PDF version of Databricks-Certified-Professional-Data-Engineer exam questions - being legible to read and remember, support customers’ printing request, and allow you to have a print and practice in papers. Software version of Databricks-Certified-Professional-Data-Engineer guide dump - supporting simulation test system, with times of setup has no restriction. Remember this version support Windows system users only. App online version of Databricks-Certified-Professional-Data-Engineer Guide dump -Being suitable to all kinds of equipment or digital devices, supportive to offline exercises on the condition that you practice it without mobile data. Bogged down in review process right now, our Databricks-Certified-Professional-Data-Engineer training materials with three versions can help you gain massive knowledge.
| Section | Objectives |
|---|---|
| Data Ingestion and Transformation | - Transform and clean datasets using Spark SQL and DataFrame APIs - Ingest data using Apache Spark and Databricks - Handle batch and streaming data pipelines |
| Production Pipelines and Orchestration | - Automate ETL pipelines and scheduling - Pipeline reliability and fault tolerance - Build and manage workflows using Databricks Jobs |
| Data Modeling and Storage | - Delta Lake table design and optimization - Design scalable data lakehouse architectures - Schema evolution and data partitioning strategies |
| Security, Governance, Monitoring, and Optimization | - Implement Unity Catalog governance and access control - Monitor and optimize Spark workloads - Cost optimization and performance tuning |
>> Downloadable Databricks-Certified-Professional-Data-Engineer PDF <<
As we all know that if you can obtain the Databricks-Certified-Professional-Data-Engineer certification, your life will change from now on. There will be various opportunities waiting for you. You take the initiative. It is up to you to make a decision. We only live once. Don’t postpone your purpose and dreams. Our Databricks-Certified-Professional-Data-Engineer Real Exam will escort your dreams. You will get better jobs as well as higher salaries to lead a better life. Come to fight for your bright future and buy our Databricks-Certified-Professional-Data-Engineer practice braindumps right now!
NEW QUESTION # 216
Which of the following is true of Delta Lake and the Lakehouse?
Answer: C
Explanation:
Explanation
https://docs.delta.io/2.0.0/table-properties.html
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters1. Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer1. By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan1. This can significantly improve the query performance and reduce the I/O cost.
The other options are false because:
Parquet compresses data column by column, not row by row2. This allows for better compression ratios, especially for repeated or similar values within a column2.
Views in the Lakehouse do not maintain a valid cache of the most recent versions of source tables at all times3. Views are logical constructs that are defined by a SQL query on one or more base tables3. Views are not materialized by default, which means they do not store any data, but only the query definition3. Therefore, views always reflect the latest state of the source tables when queried3.
However, views can be cached manually using the CACHE TABLE or CREATE TABLE AS SELECT commands.
Primary and foreign key constraints can not be leveraged to ensure duplicate values are never entered into a dimension table. Delta Lake does not support enforcing primary and foreign key constraints on tables. Constraints are logical rules that define the integrity and validity of the data in a table. Delta Lake relies on the application logic or the user to ensure the data quality and consistency.
Z-order can be applied to any values stored in Delta Lake tables, not only numeric values. Z-order is a technique to optimize the layout of the data files by sorting them on one or more columns. Z-order can improve the query performance by clustering related values together and enabling more efficient data skipping. Z-order can be applied to any column that has a defined ordering, such as numeric, string, date, or boolean values.
References: Data Skipping, Parquet Format, Views, [Caching], [Constraints], [Z-Ordering]
NEW QUESTION # 217
A data engineer has created a new cluster using shared access mode with default configurations. The data engineer needs to allow the development team access to view the driver logs if needed.
What are the minimal cluster permissions that allow the development team to accomplish this?
Answer: D
Explanation:
Databricks provides different permission levels to control access to clusters. The correct minimal permission required for viewing driver logs is CAN VIEW.
Databricks Cluster Permission Levels:
CAN ATTACH TO:
Allows users to attach notebooks to a cluster but does not allow them to view logs.
Not sufficient for viewing driver logs.
CAN MANAGE:
Grants full control over the cluster, including starting, stopping, and editing configurations.
Too broad for this requirement.
CAN VIEW (Correct Answer):
Allows users to view cluster details, logs, and status but not modify any configurations.
Minimal required permission for viewing logs.
CAN RESTART:
Grants permission to restart the cluster, but does not include log access.
Not sufficient for viewing logs.
Conclusion:
The minimal permission needed to allow the development team to view driver logs is CAN VIEW.
Reference:
Databricks Cluster Permissions Documentation
NEW QUESTION # 218
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table namedusers.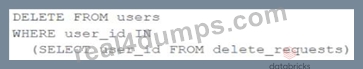
Assuming thatuser_idis a unique identifying key and that contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Answer: D
Explanation:
Explanation
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion.
The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage.
Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under "Remove files no longer referenced by a Delta table" section.
NEW QUESTION # 219
Your colleague was walking you through how a job was setup, but you noticed a warning message that said,
"Jobs running on all-purpose cluster are considered all purpose compute", the colleague was not sure why he was getting the warning message, how do you best explain this warning mes-sage?
Answer: B
Explanation:
Explanation
Warning message:
Graphical user interface, text, application, email Description automatically generated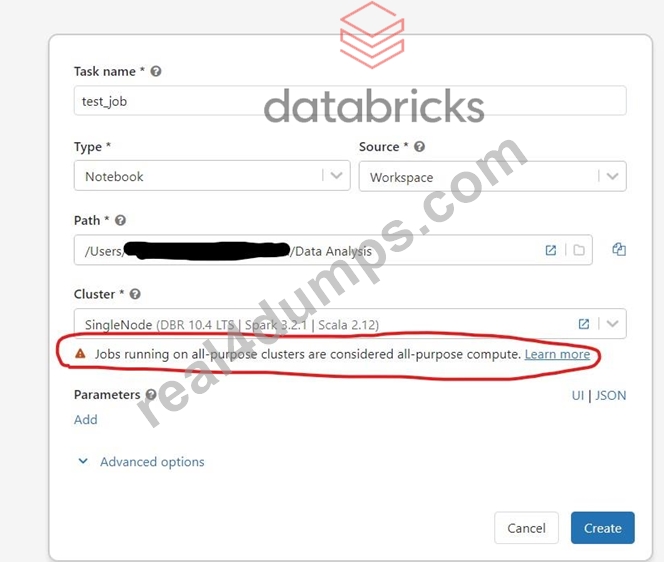
Pricing for All-purpose clusters are more expensive than the job clusters AWS pricing(Aug 15th 2022)Graphical user interface Description automatically generated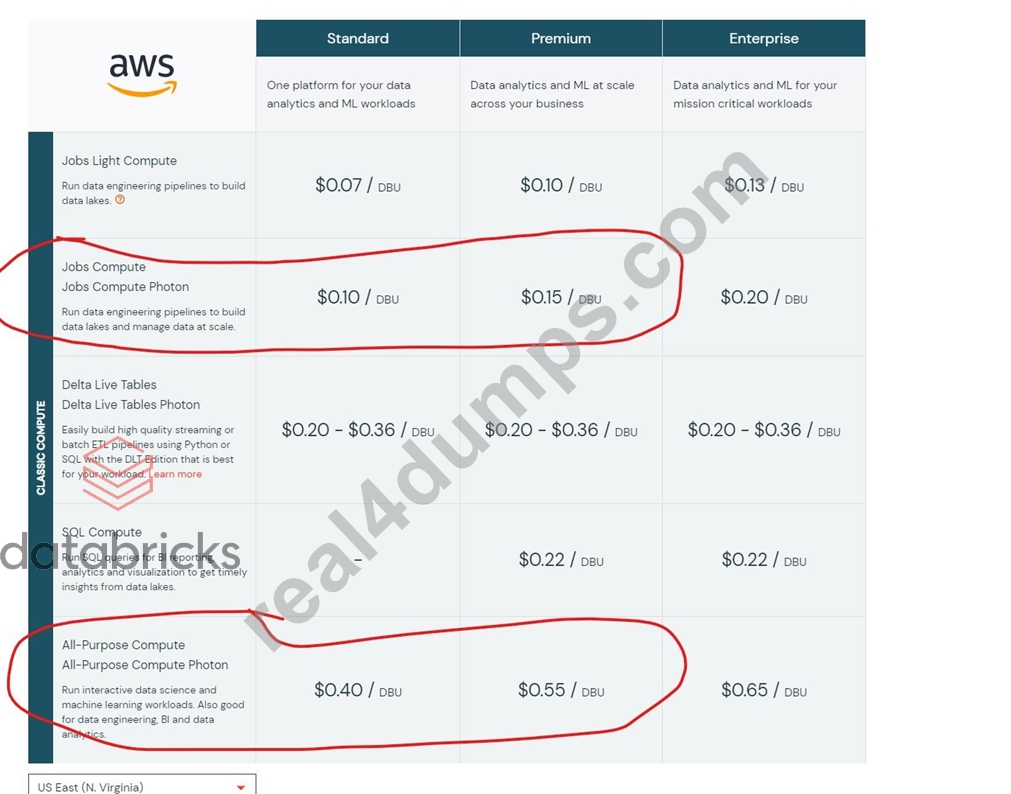
Bottom of Form
Top of Form
NEW QUESTION # 220
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is named store_saies_summary and the schema is as follows:
The table daily_store_sales contains all the information needed to update store_sales_summary . The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
If daily_store_sales is implemented as a Type 1 table and the total_sales column might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in the store_sales_summary table?
Answer: A
Explanation:
The daily_store_sales table contains all the information needed to update store_sales_summary. The schema of the table is:
store_id INT, sales_date DATE, total_sales FLOAT
The daily_store_sales table is implemented as a Type 1 table, which means that old values are overwritten by new values and no history is maintained. The total_sales column might be adjusted after manual data auditing, which means that the data in the table may change over time.
The safest approach to generate accurate reports in the store_sales_summary table is to use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update. Structured Streaming is a scalable and fault-tolerant stream processing engine built on Spark SQL. Structured Streaming allows processing data streams as if they were tables or DataFrames, using familiar operations such as select, filter, groupBy, or join. Structured Streaming also supports output modes that specify how to write the results of a streaming query to a sink, such as append, update, or complete. Structured Streaming can handle both streaming and batch data sources in a unified manner.
The change data feed is a feature of Delta Lake that provides structured streaming sources that can subscribe to changes made to a Delta Lake table. The change data feed captures both data changes and schema changes as ordered events that can be processed by downstream applications or services. The change data feed can be configured with different options, such as starting from a specific version or timestamp, filtering by operation type or partition values, or excluding no-op changes.
By using Structured Streaming to subscribe to the change data feed for daily_store_sales, one can capture and process any changes made to the total_sales column due to manual data auditing. By applying these changes to the aggregates in the store_sales_summary table with each update, one can ensure that the reports are always consistent and accurate with the latest data. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Databricks Documentation, under "Structured Streaming" section; Databricks Documentation, under "Delta Change Data Feed" section.
NEW QUESTION # 221
......
If you want to improve your career prospects, obtaining Databricks Certified Professional Data Engineer Exam, Databricks-Certified-Professional-Data-Engineer exam certificate is a great way for you. Databricks Certified Professional Data Engineer Exam certificate will help you land a job in the industry. After passing the Databricks Certified Professional Data Engineer Exam you can increase your earning potential. This is because employers are ready to pay more for candidates who have passed the Databricks Databricks-Certified-Professional-Data-Engineer Certification test. Success in the Databricks-Certified-Professional-Data-Engineer exam can impact your promotion. If you are already an employee you can promote yourself to the highest level after passing the Databricks Databricks-Certified-Professional-Data-Engineer test.
Latest Databricks-Certified-Professional-Data-Engineer Braindumps Pdf: https://www.real4dumps.com/Databricks-Certified-Professional-Data-Engineer_examcollection.html