Fast2test AIF-C01 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1AjNo21fpZbktDrhEo8SGrUbzTeQt_ywN
Amazon인증 AIF-C01 시험은 최근 제일 인기있는 인증시험입니다. IT업계에 종사하시는 분들은 자격증취득으로 자신의 가치를 업그레이드할수 있습니다. Amazon인증 AIF-C01 시험은 유용한 IT자격증을 취득할수 있는 시험중의 한과목입니다. Fast2test에서 제공해드리는Amazon인증 AIF-C01 덤프는 여러분들이 한방에 시험에서 통과하도록 도와드립니다. 덤프를 공부하는 과정은 IT지식을 더 많이 배워가는 과정입니다. 시험대비뿐만아니라 많은 지식을 배워드릴수 있는 덤프를Fast2test에서 제공해드립니다. Fast2test덤프는 선택하시면 성공을 선택한것입니다.
| Section | Weight | Objectives |
|---|---|---|
| Fundamentals of AI and ML | 20% | - Identify types of ML: supervised, unsupervised, reinforcement learning - Define artificial intelligence (AI), machine learning (ML), and deep learning - Describe common ML workflows and lifecycle - Recognize key concepts: data, models, training, inference, evaluation |
| Fundamentals of Generative AI | 24% | - Define generative AI and foundation models - Describe concepts: prompts, embeddings, fine-tuning, retrieval-augmented generation (RAG) - Explain capabilities and use cases of generative AI - Differentiate between generative AI and traditional ML |
| Security, Compliance, and Governance for AI Solutions | 14% | - Security controls for AI data and models - Governance frameworks for AI lifecycle - Compliance requirements and regulations - Data protection and privacy in AI workflows |
| Applications of Foundation Models | 28% | - Explain integration of foundation models into applications - Recognize tools for building and deploying generative AI solutions - Describe use cases for text, image, video, and code generation - Identify AWS services for generative AI: Amazon Bedrock, Amazon Titan |
| Guidelines for Responsible AI | 14% | - Identify risks and mitigation strategies for AI systems - Explain bias detection and reduction - Describe ethical and societal impacts of AI - Define responsible AI principles: fairness, transparency, privacy, safety |
다른 사이트에서도Amazon AIF-C01인증시험관련 자료를 보셨다고 믿습니다.하지만 우리 Fast2test의 자료는 차원이 다른 완벽한 자료입니다.100%통과 율은 물론Fast2test을 선택으로 여러분의 직장생활에 더 낳은 개변을 가져다 드리며 ,또한Fast2test를 선택으로 여러분은 이미 충분한 시험준비를 하였습니다.우리는 여러분이 한번에 통과하게 도와주고 또 일년무료 업데이트서비스도 드립니다.
질문 # 416
A company that streams media is selecting an Amazon Nova foundation model (FM) to process documents and images. The company is comparing Nova Micro and Nova Lite. The company wants to minimize costs.
정답:A
설명:
The correct answer is C, because Amazon Nova Micro is a smaller, lower-cost foundation model that is text- only, while Nova Lite is a more capable multimodal model that supports images, videos, and text. According to AWS Bedrock documentation, the Nova model family includes variants that differ in capability and cost.
Nova Micro is optimized for lightweight text-based tasks, including summarization, question answering, and basic reasoning. This makes it cheaper to operate and well-suited for cost-sensitive workloads. Nova Lite, on the other hand, is a multimodal FM that can analyze documents, screenshots, photographs, charts, and videos, making it ideal for media companies requiring cross-format understanding. AWS clarifies that both Micro and Lite use transformer-based architectures, and run on managed infrastructure that abstracts hardware considerations. Therefore, the main differentiator is capability-and Nova Micro being text-only is the more cost-effective option. Nova Lite is appropriate only when image or video analysis is required.
Referenced AWS Documentation:
* Amazon Bedrock - Nova Model Family Overview
* AWS Generative AI Model Selection Guide
질문 # 417
A company wants to create an application by using Amazon Bedrock. The company has a limited budget and prefers flexibility without long-term commitment.
Which Amazon Bedrock pricing model meets these requirements?
정답:A
질문 # 418
A food service company wants to develop an ML model to help decrease daily food waste and increase sales revenue. The company needs to continuously improve the model's accuracy.
Which solution meets these requirements?
정답:B
설명:
Amazon SageMaker is AWS's fully managed ML service that supports retraining and deploying models with new, recent data for continuous improvement. This directly meets the requirement to iterate and continuously improve model accuracy.
A is correct:
"Amazon SageMaker enables teams to retrain models using the most recent data, ensuring ongoing improvement in model accuracy." (Reference: Amazon SageMaker Overview)
"Amazon SageMaker enables teams to retrain models using the most recent data, ensuring ongoing improvement in model accuracy." (Reference: Amazon SageMaker Overview) B (Amazon Personalize) is for recommendations, not general ML or waste reduction.
C (CloudWatch) is for monitoring, not ML training or deployment.
D (Rekognition) is for image/video analysis.
질문 # 419
Select the correct prompt engineering technique from the following list for each description. Select each prompt engineering technique one time or not at all. (Select THREE.)
* Chain-of-thought prompting
* Few-shot prompting
* Role-based prompting
* Single-shot prompting
* Zero-shot prompting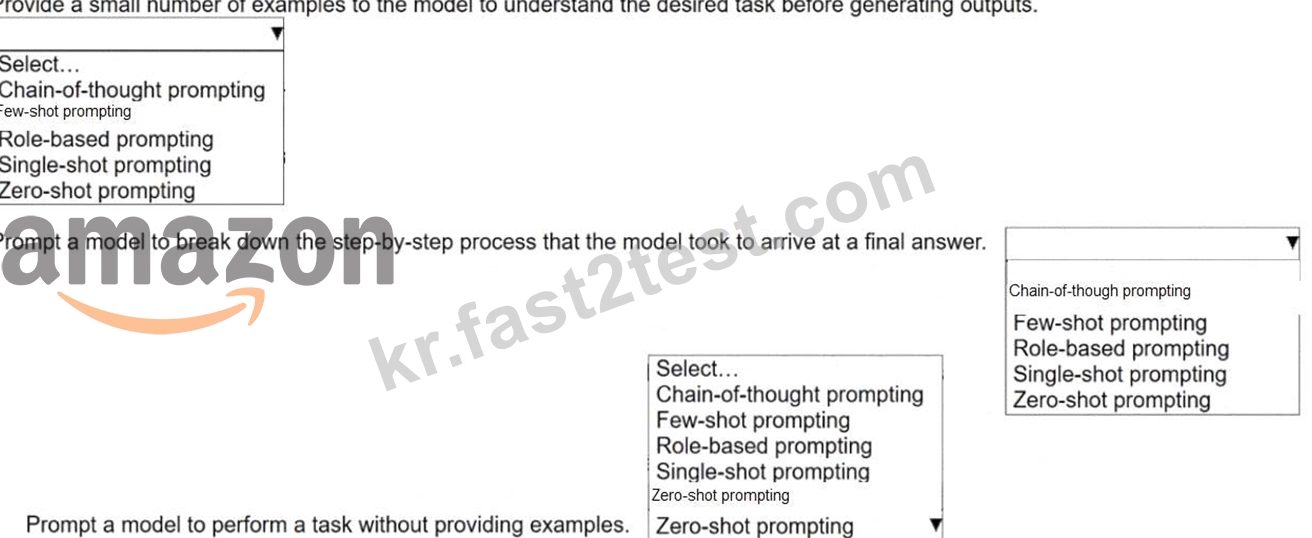
정답:
설명: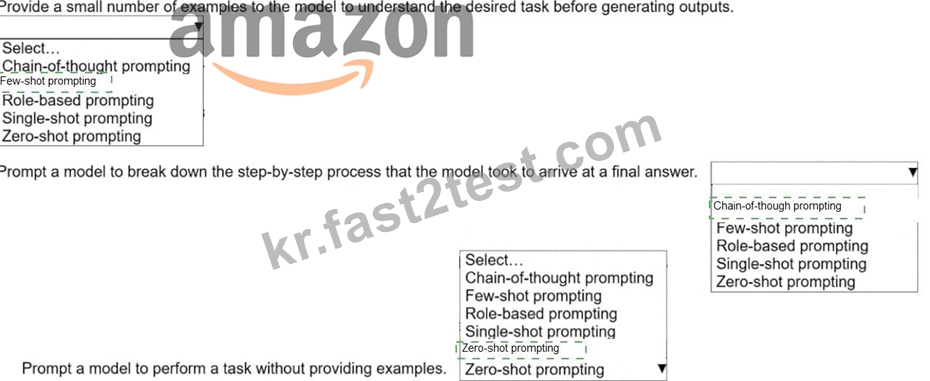
Explanation: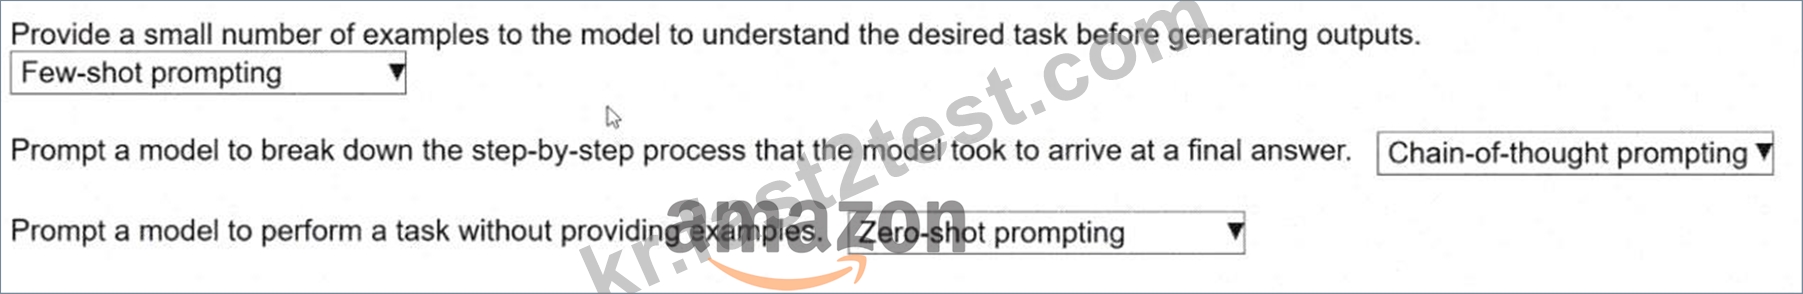
The verified selections are Few-shot prompting , Chain-of-thought prompting , and Zero-shot prompting . The first description matches few-shot prompting because AWS describes few-shot prompting as a technique that includes example outputs or demonstrations in the initial prompt so the model can understand the expected pattern before generating a response. The phrase "provide a small number of examples" is the key indicator.
A few-shot prompt gives the model limited examples of the desired task, format, or reasoning style, and the model uses those examples as context for the next output.
The second description matches chain-of-thought prompting . AWS describes chain-of-thought prompting as a technique that helps a model solve a problem by following a series of intermediate reasoning steps before reaching the final answer. The wording "break down the step-by-step process" directly points to chain-of- thought prompting. This method is commonly associated with reasoning, arithmetic, logic, planning, and multi-step problem solving because the prompt encourages the model to work through intermediate steps rather than immediately outputting a final answer.
The third description matches zero-shot prompting because AWS describes zero-shot prompting as asking the model to perform a task without providing examples in the prompt. The model relies only on the instruction and its pre-trained knowledge. The phrase "without providing examples" is the decisive clue.
Role-based prompting is not used here because none of the descriptions asks the model to act as a specific persona, job role, or domain expert, such as "Act as a financial analyst" or "You are a security engineer." Single-shot prompting is also not used because the first description says a "small number of examples," which indicates few-shot prompting, not exactly one example. Therefore, the three correct hotspot mappings are Few-shot prompting , Chain-of-thought prompting , and Zero-shot prompting .
질문 # 420
A company has fine-tuned an Amazon Bedrock foundation model (FM) to produce short document summaries. The company wants an automated metric that compares each model-generated summary with its human-written reference summary.
Which metric will meet these requirements?
정답:C
설명:
AWS documentation identifies ROUGE as a standard evaluation metric for text summarization tasks. ROUGE measures the overlap of n-grams, sequences, or word pairs between a machine-generated summary and a human-written reference summary, making it ideal for automated evaluation.
In this scenario, the company needs a metric that directly compares generated summaries with human references. ROUGE scores quantify how much of the reference content is captured by the model output, which aligns with AWS recommendations for evaluating summarization quality.
The other metrics are not appropriate. F1 score is typically used for classification tasks. Perplexity measures language model confidence but does not compare outputs to reference summaries. Frechet Inception Distance is used for image generation tasks, not text.
AWS consistently recommends ROUGE for summarization evaluation, making it the correct choice.
질문 # 421
......
Amazon AIF-C01인증시험은 현재IT인사들 중 아주 인기 잇는 인증시험입니다.Amazon AIF-C01시험패스는 여러분의 하시는 일과 생활에서 많은 도움을 줄뿐만 아니라 중요한 건 여러분의IT업계에서의 자기만의 자리를 지키실 수 잇습니다.이렇게 좋은 시험이니 많은 분들이 응시하려고 합니다,하지만 패스 율은 아주 낮습니다.
AIF-C01인증자료: https://kr.fast2test.com/AIF-C01-premium-file.html
Fast2test AIF-C01 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1AjNo21fpZbktDrhEo8SGrUbzTeQt_ywN