What's more, part of that PassExamDumps DP-750 dumps now are free: https://drive.google.com/open?id=1hsmQRt_qPqtrpL4PxVpt37oBuq--QYqx
The PassExamDumps guarantees their customers that if they have prepared with Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice test, they can pass the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification easily. If the applicants fail to do it, they can claim their payment back according to the terms and conditions. Many candidates have prepared from the actual Microsoft DP-750 Practice Questions and rated them as the best to study for the examination and pass it in a single try with the best score. The Microsoft DP-750 practice material of PassExamDumps came into existence after consultation with many professionals and getting their positive reviews.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 2: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 4: Prepare and process data | 30-35% | - Ingest and transform data
|
>> Microsoft DP-750 Materials <<
We have 24/7 Service Online Support services, and provide professional staff Remote Assistance. Besides, if you need an invoice of our DP-750 practice materials please specify the invoice information and send us an email. And you can download the trial of our DP-750 training engine for free before your purchase. This kind of service shows our self-confidence and actual strength about DP-750 Study Materials in our company. Besides, our company's website purchase process holds security guarantee, so you needn’t be anxious about download and install our DP-750 exam questions.
NEW QUESTION # 32
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales.
Sales stores transaction data and contains the following columns:
- transaction_id (string)
- transaction_date (date)
- amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
- amount must be greater than 0.
- transaction_id must never be null.
- Invalid records must be rejected when data is written to the Sales
table.
What should you do?
Answer: B
Explanation:
To enforce these table-level data quality rules and automatically reject any invalid write operations in Azure Databricks, you must configure NOT NULL and CHECK constraints on the Delta table using standard SQL commands.
In Delta Lake, these constraints are enforced instantly on write. If an incoming record violates any of them, the entire transaction fails, and the invalid records are rejected.
1. Enforce transaction_id Cannot Be Null
Add a NOT NULL constraint to the transaction_id column. This blocks any write attempt containing a null identifier.
ALTER TABLE sales_data ALTER COLUMN transaction_id SET NOT NULL;
2. Enforce amount Must Be Greater Than 0
Add a CHECK constraint to the table to validate that the amount values strictly exceed zero.
ALTER TABLE sales_data ADD CONSTRAINT check_amount_positive CHECK (amount > 0); Reference:
https://docs.databricks.com/aws/en/tables/constraints
NEW QUESTION # 33
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Sales_orders. Sales.orders stores historical sales data.
You receive a daily CSV file daily that contains new sales records only. The file does NOT contain updates to existing rows You need to load the daily data into Sales.orders. The solution must meet the following requirements:
* Preserve the existing data.
* Add only the new records.
* Minimize processing effort.
Which command should include in the loading strategy?
Answer: C
Explanation:
The correct answer is C - INSERT INTO.
The scenario is clear: the daily file contains only new records, no updates to existing rows. INSERT INTO is the right command because it appends the new rows to Sales.orders without touching the existing historical data. All three requirements are satisfied: existing data is preserved, only new records are added, and the loading strategy is as simple as it gets.
Option A (INSERT OVERWRITE) replaces the existing data with just today's file. After the first day you'd have only 24 hours of history - all prior sales records would be gone. Option B (UPDATE) modifies specific existing rows based on a match condition; it doesn't load new records at all.
Because the source file is guaranteed to contain only new records and no duplicates of existing rows, a full MERGE is unnecessary overhead. Simple INSERT INTO is both correct and the most efficient approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-insert-into
NEW QUESTION # 34
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1. Table1 stores customer data.
You need to implement a data retention solution that meets the following requirements:
Deleted data must be retained for 30 days to support audits.
Deleted data that is older than 30 days must be removed permanently.
The solution must minimize administrative effort.
Which two properties should you configure? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,E
Explanation:
The correct answers are B and D. Delta Lake's data retention behaviour is controlled by two distinct properties that work together:
delta.deletedFileRetentionDuration governs how long physically deleted data files are kept before VACUUM can remove them. Setting this to 30 days ensures deleted records remain on storage for the full audit window.
delta.logRetentionDuration controls how long the transaction log is retained. Time-travel queries (SELECT ...
VERSION AS OF or TIMESTAMP AS OF) rely on the log to reconstruct historical table states - without 30 days of log, you can't query 30-day-old snapshots even if the data files are still there.
Both properties need to be set to 30 days to fully honour the requirement. Option A (delta.timeUntilArchived) doesn't exist in Delta Lake. Option C (autoCompact) manages file sizing, not retention. Option E (enableDeletionVectors) speeds up deletes but has no bearing on how long data is kept.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/history#configure-data-retention
NEW QUESTION # 35
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed You need to configure the job alerting behavior.
What should trigger a notification?
Answer: A
Explanation:
The correct answer is B - a job failure.
The requirement draws a clear line: non-critical task failures should be logged silently; notifications should only fire when a critical failure causes the whole job to stop. Configuring the alert on ' Job Failure ' achieves this precisely - the notification triggers when the job itself reaches a Failed terminal state, which only happens when at least one critical task has failed and the job cannot complete.
Option A (task failure) would send a notification for every task-level failure, including non-critical ones. That
' s exactly the noise the question wants to avoid. Option C (job success) would never alert on failures at all.
Option D (task success) confirms completion but doesn ' t catch failures.
Setting alerting at the job level rather than the task level is also simpler to configure - you don ' t need to mark individual tasks as critical or non-critical in the notification settings.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/alerts
NEW QUESTION # 36
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
dbl sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the dbl.sales.ordets table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.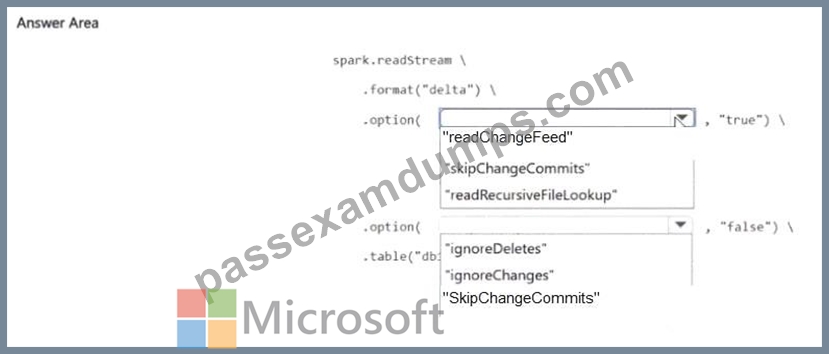
Answer:
Explanation: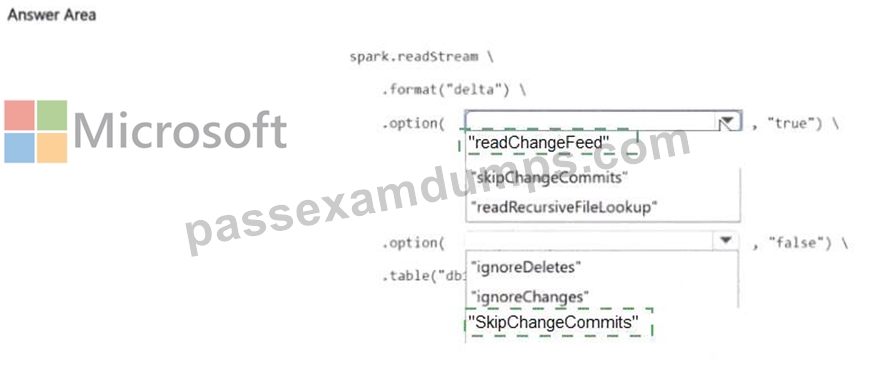
Explanation:
When Change Data Feed (CDF) is enabled on a Delta table, reading the full change stream - inserts, updates, and deletes - requires this pattern:
spark.readStream.format('delta').option('readChangeFeed', 'true').table('db1.sales_orders') The readChangeFeed option switches the reader from the default 'new rows only' mode to a mode that returns all change events. Each row in the resulting DataFrame includes a _change_type column (insert, update_preimage, update_postimage, delete) so downstream processing can distinguish what happened to each record.
Without readChangeFeed = true, streaming a Delta table only surfaces newly appended rows. Deletes and updates are invisible, making it unsuitable for true CDC pipelines. The stream also supports startingVersion or startingTimestamp options to begin from a specific point in table history rather than the current moment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-change-data-feed
NEW QUESTION # 37
......
The learning material is open in three excellent formats; Microsoft DP-750 dumps PDF, a desktop Microsoft DP-750 dumps practice test, and a web-based Microsoft DP-750 dumps practice test. Microsoft DP-750 dumps is organized by experts while saving the furthest down-the-line plan to them for the Microsoft DP-750 Exam. The sans bug plans have been given to you all to drift through the Implementing Data Engineering Solutions Using Azure Databricks certificate exam.
Latest DP-750 Braindumps Files: https://www.passexamdumps.com/DP-750-valid-exam-dumps.html
What's more, part of that PassExamDumps DP-750 dumps now are free: https://drive.google.com/open?id=1hsmQRt_qPqtrpL4PxVpt37oBuq--QYqx