Are you planning to attempt the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam of the Databricks-Certified-Professional-Data-Engineer certification? The first hurdle you face while preparing for the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam is not finding the trusted brand of accurate and updated Databricks-Certified-Professional-Data-Engineer exam questions. If you don't want to face this issue then you are at the trusted ExamDiscuss is offering actual and Latest Databricks-Certified-Professional-Data-Engineer Exam Questions that ensure your success in the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification exam on your maiden attempt.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Exam Price: | $200 USD |
| Available Languages: | English |
| Passing Score: | 70% |
| Real Exam Qty: | 60 |
| Related Certifications: | Databricks Certified Associate Developer Databricks Certified Data Analyst Associate |
| Exam Duration: | 90 minutes |
| Exam Format: | Multiple Choice, Multiple Select |
| Certificate Validity Period: | 2 years |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam (Pearson VUE) |
| Pre Condition: | Recommended: 6+ months of hands-on experience with Databricks and data engineering concepts; familiarity with Python or Scala and SQL is strongly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/professional-data-engineer |
>> Best Databricks-Certified-Professional-Data-Engineer Study Material <<
Our website experts simplify complex concepts of the Databricks-Certified-Professional-Data-Engineer exam questions and add examples, simulations, and diagrams to explain anything that might be difficult to understand. Therefore, even ordinary examiners can master all the Databricks-Certified-Professional-Data-Engineer learning materials without difficulty. And the price of our Databricks-Certified-Professional-Data-Engineer Study Guide is reasonable for even the students can afford it. At the same time, we give some discounts from time to time, you can buy our Databricks-Certified-Professional-Data-Engineer practice engine at a favorable price.
Databricks Certified Professional Data Engineer certification is globally recognized by various industries, including finance, healthcare, government, and technology. Databricks Certified Professional Data Engineer Exam certification validates the candidate's knowledge level in data engineering solutions and qualifies them to work with Databricks's technology. The certified professional can optimize and manage their organization's data in the cloud using Databricks, which results in timely and informed decisions.
NEW QUESTION # 93
A data engineer wants to reflector the following DLT code, which includes multiple definition with very similar code: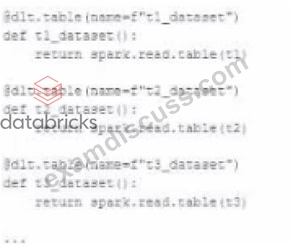
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.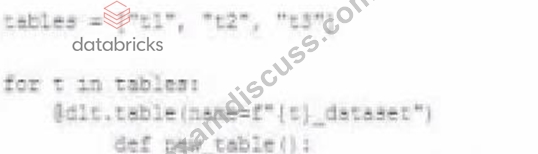
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for tables.
How can the data engineer fix this?
Answer: C
Explanation:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names. Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
NEW QUESTION # 94
A new data engineer notices that a critical field was omitted from an application that writes its Kafka source to Delta Lake. This happened even though the critical field was in the Kafka source. That field was further missing from data written to dependent, long-term storage. The retention threshold on the Kafka service is seven days. The pipeline has been in production for three months.
Which describes how Delta Lake can help to avoid data loss of this nature in the future?
Answer: E
Explanation:
Explanation
This is the correct answer because it describes how Delta Lake can help to avoid data loss of this nature in the future. By ingesting all raw data and metadata from Kafka to a bronze Delta table, Delta Lake creates a permanent, replayable history of the data state that can be used for recovery or reprocessing in case of errors or omissions in downstream applications or pipelines. Delta Lake also supports schema evolution, which allows adding new columns to existing tables without affecting existing queries or pipelines. Therefore, if a critical field was omitted from an application that writes its Kafka source to Delta Lake, it can be easily added later and the data can be reprocessed from the bronze table without losing any information. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delta Lake core features" section.
NEW QUESTION # 95
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
Answer: D
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column
NEW QUESTION # 96
You have accidentally deleted records from a table called transactions, what is the easiest way to restore the records deleted or the previous state of the table? Prior to deleting the version of the table is 3 and after delete the version of the table is 4.
Answer: A
Explanation:
Explanation
RESTORE (Databricks SQL) | Databricks on AWS
1.RESTORE [TABLE] table_name [TO] time_travel_version
Time travel supports using timestamp or version number
1.time_travel_version
2. { TIMESTAMP AS OF timestamp_expression |
3. VERSION AS OF version }
*timestamp_expression can be any one of:
*'2018-10-18T22:15:12.013Z', that is, a string that can be cast to a timestamp
*cast('2018-10-18 13:36:32 CEST' as timestamp)
*'2018-10-18', that is, a date string
*current_timestamp() - interval 12 hours
*date_sub(current_date(), 1)
*Any other expression that is or can be cast to a timestamp
NEW QUESTION # 97
A Delta Lake table with Change Data Feed (CDF) enabled in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources. The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours. Which approach would simplify the identification of these changed records?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
* Exact extract: "Change data feed (CDF) provides row-level change information for Delta tables."
* Exact extract: "Use table_changes to query the set of rows that were inserted, updated, or deleted between two versions (or timestamps)." References: Delta Lake Change Data Feed; Delta Lake MERGE INTO.
NEW QUESTION # 98
......
Databricks-Certified-Professional-Data-Engineer Official Cert Guide: https://www.examdiscuss.com/Databricks/exam/Databricks-Certified-Professional-Data-Engineer/