ActualTorrent is a reliable and professional leader in developing and delivering authorized IT exam training for all the IT candidates. We promise to give the most valid DP-750 exam dumps to all of our clients and make the Microsoft DP-750 exam training material highly beneficial for you. Before you buy our DP-750 exam torrent, you can free download the DP-750 Exam Demo to have a try. If you buy it, you will receive an email attached with DP-750 exam dumps instantly, then, you can start your study and prepare for DP-750 exam test. You will get a high score with the help of our Microsoft DP-750 practice training.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Prepare and process data | 30-35% | - Data ingestion
|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
>> DP-750 Exam Dumps Provider <<
One of the most important functions of our DP-750 preparation questions are that can support almost all electronic equipment, including the computer, mobile phone and so on. If you want to prepare for your exam by the computer, you can buy the Software and APP online versions of our DP-750 training quiz, because these two versions can work well by the computer. Moreover, the APP online version of our DP-750 learning materials can also apply the IPAD, phone, laptop and so on.
NEW QUESTION # 30
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to ensure that data lineage is captured and can be reviewed for tables accessed by Databricks notebooks and jobs. The solution must minimize administrative effort.
Which compute configuration should you use to capture the data lineage, and what should you use to review the data lineage? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.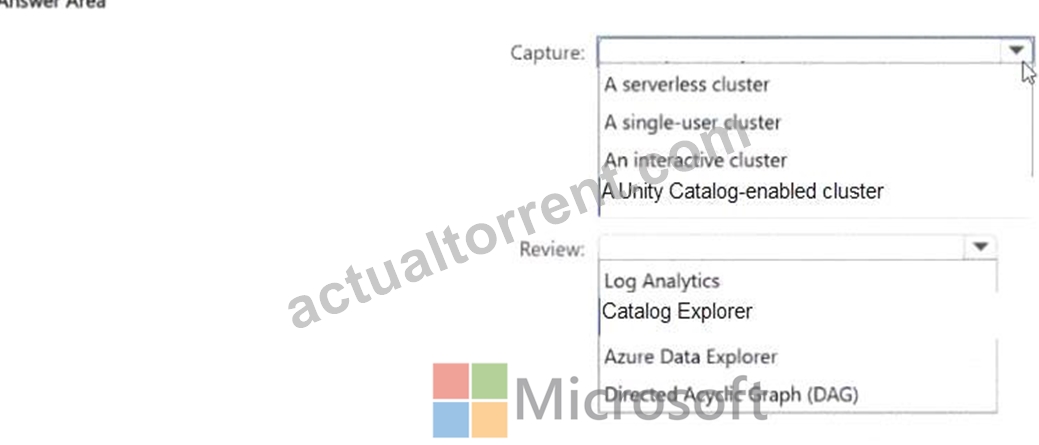
Answer:
Explanation: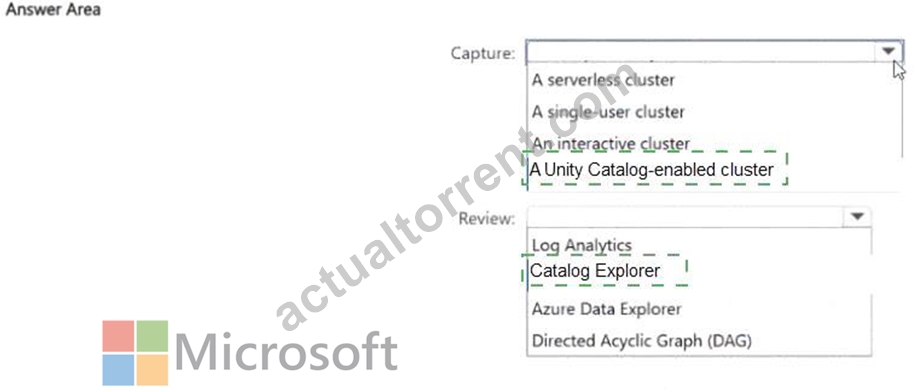
Explanation:
Data lineage in Unity Catalog is captured automatically - but only when jobs and notebooks run on clusters that are Unity Catalog-aware. Specifically, clusters must use 'Shared' or 'Single User' access mode. Clusters set to 'No Isolation Shared' or legacy 'High Concurrency' mode do not emit lineage events to the Unity Catalog lineage service.
No instrumentation, logging code, or external tools are required. The lineage service operates transparently, intercepting read and write operations at the Spark plan level and recording the table-to-table and column-to- column relationships.
To review captured lineage, open Catalog Explorer, navigate to the table, and select the Lineage tab. This shows the upstream sources that populate the table and the downstream consumers that read from it - all as an interactive graph, with no additional tooling needed. This built-in visibility is one of the core governance benefits Unity Catalog provides.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/data-lineage
NEW QUESTION # 31
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
Answer: B
Explanation:
The correct answer is D - Continuous trigger.
A Continuous trigger keeps the job running as a perpetual loop. As soon as one micro-batch or iteration completes, the next begins. New records are picked up with the shortest possible latency - as close to real- time as a Lakeflow Jobs pipeline gets.
File Arrival (Option B) is event-driven but introduces per-file trigger overhead and is best suited for file-based ingestion rather than continuous streaming workloads. Scheduled (Option C) runs at fixed clock intervals - if new data arrives between runs, it waits until the next scheduled execution. Manual (Option A) requires a human to start each run.
The question specifies serverless compute, which pairs naturally with Continuous trigger because serverless handles cluster lifecycle automatically - the job stays active without managing a persistent cluster. 'New records must be processed as soon as they become available' is the exact use case the Continuous trigger is designed for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers
NEW QUESTION # 32
You have an Azure Databricks workspace named Workspace1 that contains a cluster named Cluster1.
You need to enable a user named User1 to install a Maven package on all the nodes of Cluster1. The solution must follow the principle of least privilege.
What should you do?
Answer: D
Explanation:
Installing a Maven package on every node requires changing Cluster1's library configuration. The CAN MANAGE permission grants the cluster-level management capabilities required to add or remove libraries without giving User1 broader control over the entire workspace or Azure resource group. CAN RESTART allows a user to restart the cluster but does not provide sufficient authority to change its library configuration.
Assigning the Azure Contributor role would grant excessive control over the resource group and does not represent the appropriate Databricks object-level permission. Making User1 a workspace administrator would provide substantially more privileges than necessary. Granting CAN MANAGE directly on Cluster1 therefore satisfies the operational requirement while limiting User1's authority to the specific compute resource that must be modified.
NEW QUESTION # 33
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: C
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don't prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely.
Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 34
You have an Azure Databricks workspace that contains multiple all-purpose clusters.
You discover that some clusters remain idle for long periods after users finish their work.
You need to reduce compute costs without affecting active workloads.
What should you do?
Answer: C
Explanation:
To reduce compute costs from idle clusters without impacting active workloads, you must configure Auto-Termination and use Cluster Policies.
Core Remedies
*-> Auto-Termination: Set a strict inactivity timeout (e.g., 20-30 minutes) on all-purpose clusters to automatically shut them down when idle.
Cluster Policies: Enforce maximum auto-termination limits across the workspace so users cannot disable or set excessively long idle timeouts.
Single User Access Mode: Use this mode where possible, as it tracks idleness more accurately than Shared mode by monitoring the specific user's activity.
Reference:
https://medium.com/@sujathamudadla1213/databricks-lakehouse-platform-describe-how- clusters-are-terminated-and-the-impact-of-terminating-a-b6236689fd2e
NEW QUESTION # 35
......
In this knowledge-dominated world, the combination of the knowledge and the practical working competences has been paid high attention to is extremely important. If you want to improve your practical abilities you can attend the certificate examination. Our DP-750 exam questions are compiled by experts and approved by authorized personnel and boost varied function so that you can learn DP-750 Test Torrent conveniently and efficiently. Our passing rate is 98%-100% and there is little possibility for you to fail in the exam. But if you are unfortunately to fail in the exam we will refund you in full immediately.
DP-750 Test Cram: https://www.actualtorrent.com/DP-750-questions-answers.html