PracticeVCE Databricks-Certified-Professional-Data-Engineer exam dumps are audited by our certified subject matter experts and published authors for development. Databricks-Certified-Professional-Data-Engineer exam dumps are one of the highest quality Databricks-Certified-Professional-Data-Engineer Q&AS in the world. It covers nearly 96% real questions and answers, including the entire testing scope. PracticeVCE guarantees you Pass Databricks-Certified-Professional-Data-Engineer Exam at first attempt.
Databricks Certified Professional Data Engineer certification exam is a valuable certification for data professionals who want to demonstrate their skills in building and managing complex data solutions on the Databricks platform. Databricks-Certified-Professional-Data-Engineer Exam is designed to test the knowledge and skills required to design, implement, and manage data engineering workflows in a collaborative environment. Candidates who pass the exam will have a deep understanding of Databricks technologies and will be able to build and manage scalable and reliable data solutions.
>> Upgrade Databricks-Certified-Professional-Data-Engineer Dumps <<
You can free download part of PracticeVCE's practice questions and answers about Databricks certification Databricks-Certified-Professional-Data-Engineer exam online, as an attempt to test our quality. As long as you choose to purchase PracticeVCE's products, we will do our best to help you pass Databricks Certification Databricks-Certified-Professional-Data-Engineer Exam disposably.
Databricks is a cloud-based platform that provides data engineering, machine learning, and analytics services. The Databricks Certified Professional Data Engineer (DCPDE) exam is designed to test the skills and knowledge of data engineers who are responsible for building data pipelines, managing data infrastructure, and optimizing data processing workflows on the Databricks platform.
Databricks Certified Professional Data Engineer certification is a valuable credential for data engineers who want to demonstrate their skills and proficiency in using Databricks for data engineering tasks. Databricks Certified Professional Data Engineer Exam certification can help data engineers to advance their careers and increase their earning potential. It can also help organizations to identify and hire skilled data engineers who can design and implement data solutions using Databricks.
NEW QUESTION # 60
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame namedpredswith the schema "customer_id LONG, predictions DOUBLE, date DATE".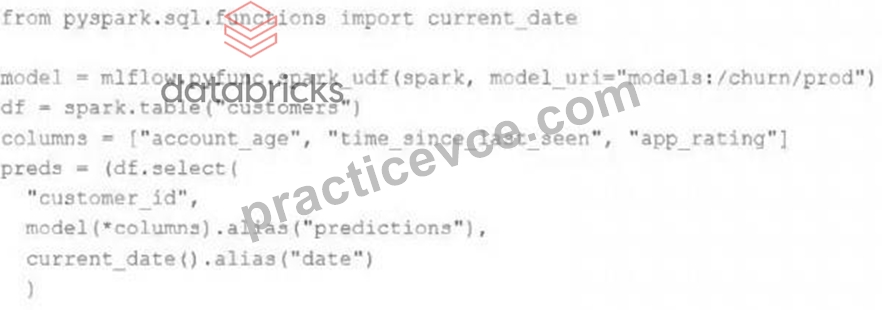
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
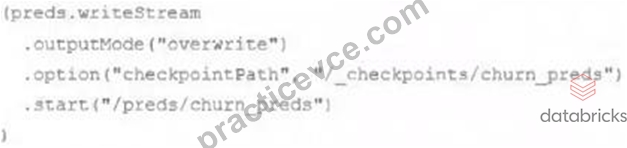
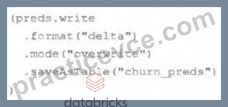
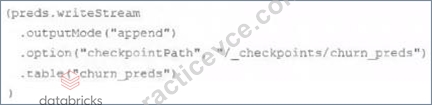
Which code block accomplishes this task while minimizing potential compute costs?
Answer: A
Explanation:
Explanation
This is the correct answer because it will save the predictions to a Delta Lake table with the ability to compare all predictions across time. The code uses the mergeInto method to perform an upsert operation, which means it will insert new records or update existing records based on the customer_id and date columns. This way, the table will always contain the latest predictions for each customer and date, and also keep the history of previous predictions. The code also uses a new job cluster to run the job, which will minimize the compute costs as it will be created and terminated for each run. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Upsert into a table using merge" section.
NEW QUESTION # 61
A junior data engineer on your team has implemented the following code block.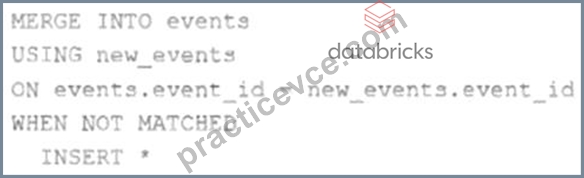
The viewnew_eventscontains a batch of records with the same schema as theeventsDelta table.
Theevent_idfield serves as a unique key for this table.
When this query is executed, what will happen with new records that have the sameevent_idas an existing record?
Answer: D
Explanation:
This is the correct answer because it describes what will happen with new records that have the same event_id as an existing record when the query is executed. The query uses the INSERT INTO command to append new records from the view new_events to the table events. However, the INSERT INTO command does not check for duplicate values in the primary key column (event_id) and does not perform any update or delete operations on existing records. Therefore, if there are new records that have the same event_id as an existing record, they will be ignored and not inserted into the table events. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Append data using INSERT INTO" section.
"If none of the WHEN MATCHED conditions evaluate to true for a source and target row pair that matches the merge_condition, then the target row is left unchanged."https://docs.databricks.com/en/sql/language-manual/delta-merge-into.html#:~:text=If%20none%20o
NEW QUESTION # 62
The data engineering team maintains the following code: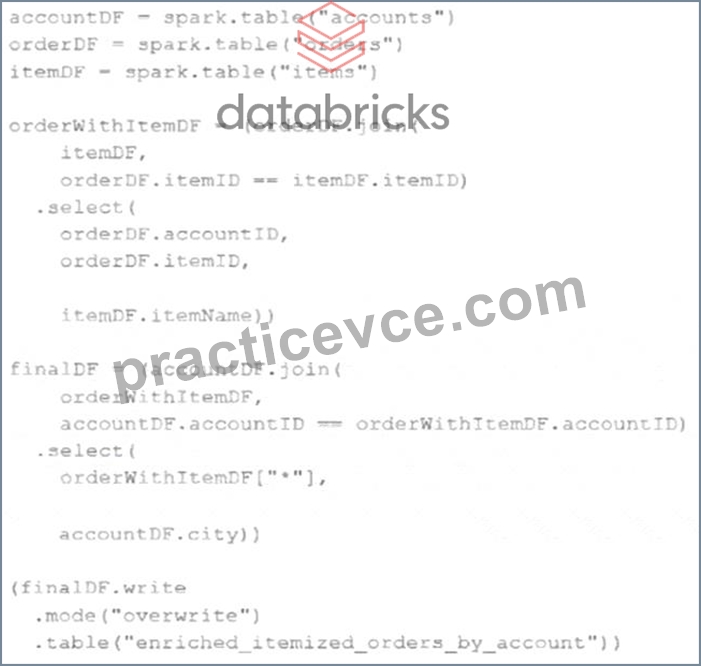
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: C
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Write to Delta tables" section.
NEW QUESTION # 63
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
Answer: C
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column
NEW QUESTION # 64
A Spark job is taking longer than expected. Using the Spark UI, a data engineer notes that the Min, Median, and Max Durations for tasks in a particular stage show the minimum and median time to complete a task as roughly the same, but the max duration for a task to be roughly 100 times as long as the minimum.
Which situation is causing increased duration of the overall job?
Answer: D
Explanation:
This is the correct answer because skew is a common situation that causes increased duration of the overall job. Skew occurs when some partitions have more data than others, resulting in uneven distribution of work among tasks and executors. Skew can be caused by various factors, such as skewed data distribution, improper partitioning strategy, or join operations with skewed keys. Skew can lead to performance issues such as long-running tasks, wasted resources, or even task failures due to memory or disk spills. Verified References:
[Databricks Certified Data Engineer Professional], under "Performance Tuning" section; Databricks Documentation, under "Skew" section.
NEW QUESTION # 65
......
Databricks-Certified-Professional-Data-Engineer Trustworthy Exam Content: https://www.practicevce.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html