Pass Guaranteed Quiz Databricks - Fantastic Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam Valid Braindumps Questions

In order to meet different needs of the candidates, three versions for Databricks-Certified-Data-Engineer-Professional exam materials are available. You can choose the one you prefer for your training. Databricks-Certified-Data-Engineer-Professional PDF version is printable, and you can print them into hard one if you like. Databricks-Certified-Data-Engineer-Professional Soft test engine can install in more than 200 personal computers, it also support MS operating system. Databricks-Certified-Data-Engineer-Professional Online Test engine can is convenient and easy to learn, it supports all web browsers, and you can have a general review of what you have learned through this version.
| Section | Objectives |
|---|
| Topic 1: Delta Lake and Data Management | - Time travel and versioning
- Schema evolution and enforcement
- Delta Lake transactions and ACID properties
|
| Topic 2: Production Pipelines and Orchestration | - Job scheduling and monitoring
- Databricks Workflows
- Error handling and recovery strategies
|
| Topic 3: Data Modeling and Transformation | - Spark SQL transformations
- Dimensional modeling concepts
- Performance optimization techniques
|
| Topic 4: Data Ingestion and Processing | - Structured Streaming fundamentals
- Batch and streaming ingestion with Auto Loader
- ETL pipeline design patterns
|
| Topic 5: Databricks Lakehouse Platform Architecture | - Data governance concepts (Unity Catalog basics)
- Workspace and cluster architecture
- Medallion architecture (Bronze, Silver, Gold)
|
>> Databricks-Certified-Data-Engineer-Professional Valid Braindumps Questions <<
Test Databricks-Certified-Data-Engineer-Professional Lab Questions - Databricks-Certified-Data-Engineer-Professional Reliable Guide Files
From the moment you decide to contact with us for the Databricks-Certified-Data-Engineer-Professional exam braindumps, you are enjoying our fast and professional service. Some of our customers may worry that we are working on certain time about our Databricks-Certified-Data-Engineer-Professional study guide. In fact, you don't need to worry at all. You can contact us at any time. The reason why our staff is online 24 hours is to be able to help you solve problems about our Databricks-Certified-Data-Engineer-Professional simulating exam at any time. We know that your time is very urgent, so we do not want you to be delayed by some unnecessary trouble.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q217-Q222):
NEW QUESTION # 217
Which of the following is true of Delta Lake and the Lakehouse?
- A. Because Parquet compresses data row by row. strings will only be compressed when a character is repeated multiple times.
- B. Delta Lake automatically collects statistics on the first 32 columns of each table which are leveraged in data skipping based on query filters.
- C. Primary and foreign key constraints can be leveraged to ensure duplicate values are never entered into a dimension table.
- D. Views in the Lakehouse maintain a valid cache of the most recent versions of source tables at all times.
- E. Z-order can only be applied to numeric values stored in Delta Lake tables
Answer: B
Explanation:
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters. Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer. By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan. This can significantly improve the query performance and reduce the I/O cost.
NEW QUESTION # 218
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is named store_saies_summary and the schema is as follows:

The table daily_store_sales contains all the information needed to update store_sales_summary.
The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
If daily_store_sales is implemented as a Type 1 table and the total_sales column might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in the store_sales_summary table?
- A. Use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update.
- B. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and append new rows nightly to the store_sales_summary table.
- C. Implement the appropriate aggregate logic as a Structured Streaming read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- D. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- E. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and overwrite the store_sales_summary table with each Update.
Answer: E
NEW QUESTION # 219
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below:
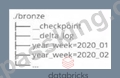
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
- A. Yes; Delta Lake supports infinite concurrent writers.
- B. No; each of the streams needs to have its own checkpoint directory.
- C. Yes; both of the streams can share a single checkpoint directory.
- D. No; only one stream can write to a Delta Lake table.
- E. No; Delta Lake manages streaming checkpoints in the transaction log.
Answer: B
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss.
NEW QUESTION # 220
A data engineer is building a Lakeflow Declarative Pipelines pipeline to process healthcare claims data. A metadata JSON file defines data quality rules for multiple tables, including:
{
"claims": [
{"name": "valid_patient_id", "constraint": "patient_id IS NOT NULL"},
{"name": "non_negative_amount", "constraint": "claim_amount >= 0"}
]
}
The pipeline must dynamically apply these rules to the claims table without hardcoding the rules.
How should the data engineer achieve this?
- A. Reference each expectation with @dlt.expect decorators in the table declaration.
- B. Load the JSON metadata, loop through its entries, and apply expectations using dlt.expect_all.
- C. Invoke an external API to validate records against the metadata rules.
- D. Use a SQL CONSTRAINT block referencing the JSON file path.
Answer: B
Explanation:
Lakeflow Declarative Pipelines provide the expect_all method for programmatically applying multiple data quality expectations at once. The documentation explains that @dlt.expect_all accepts a dictionary of expectation names mapped to SQL constraints, allowing rules to be dynamically loaded from metadata such as JSON files. This ensures that pipelines remain maintainable and scalable without needing to hardcode individual @dlt.expect decorators. The event logs will track each expectation's pass and fail counts individually, making it auditable.
NEW QUESTION # 221
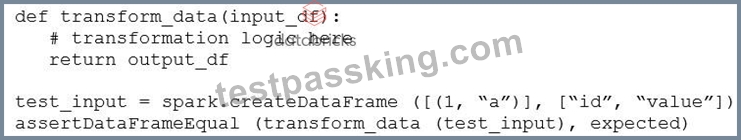
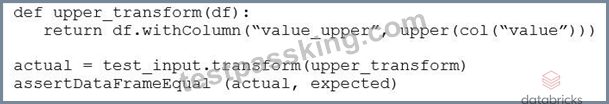
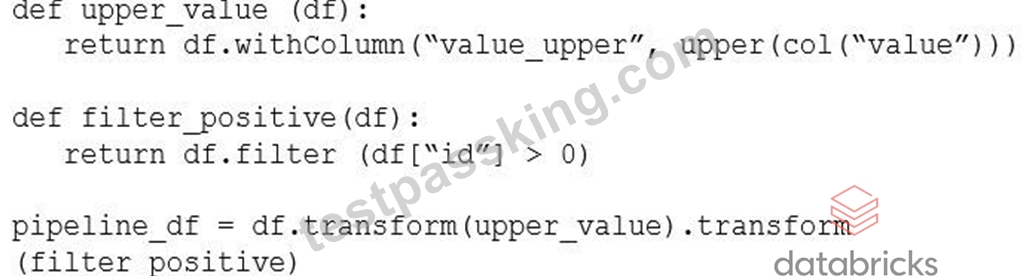
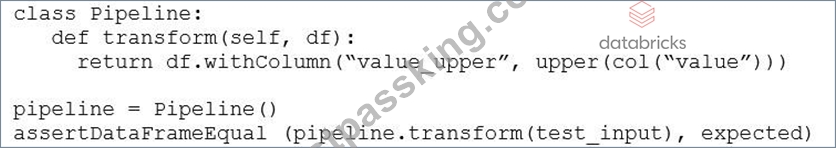
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
Answer: B
Explanation:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
NEW QUESTION # 222
......
Passing an exam requires diligent practice, and using the right study Databricks Certification Exams material is crucial for optimal performance. With this in mind, TestPassKing has introduced a range of innovative Databricks-Certified-Data-Engineer-Professional practice test formats to help candidates prepare for their Databricks-Certified-Data-Engineer-Professional. The platform offers three distinct formats, including a desktop-based Databricks Databricks-Certified-Data-Engineer-Professional practice test software, a web-based practice test, and a convenient PDF format.
Test Databricks-Certified-Data-Engineer-Professional Lab Questions: https://www.testpassking.com/Databricks-Certified-Data-Engineer-Professional-exam-testking-pass.html
- Exam Databricks-Certified-Data-Engineer-Professional Review 📑 New Databricks-Certified-Data-Engineer-Professional Exam Fee 🛶 Databricks-Certified-Data-Engineer-Professional Valid Exam Voucher 🏕 Open ▛ www.testkingpass.com ▟ enter ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ and obtain a free download 🕎Visual Databricks-Certified-Data-Engineer-Professional Cert Test
- Use Databricks Databricks-Certified-Data-Engineer-Professional Exam Dumps And Get Successful 🎢 Enter “ www.pdfvce.com ” and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ to download for free 🥏Certification Databricks-Certified-Data-Engineer-Professional Exam Dumps
- Databricks Databricks-Certified-Data-Engineer-Professional Questions [2026] 🐻 Download { Databricks-Certified-Data-Engineer-Professional } for free by simply entering { www.prepawaypdf.com } website 📋Databricks-Certified-Data-Engineer-Professional Actual Exams
- Useful Databricks-Certified-Data-Engineer-Professional Valid Braindumps Questions - Efficient Source of Databricks-Certified-Data-Engineer-Professional Exam ⚜ Download ▛ Databricks-Certified-Data-Engineer-Professional ▟ for free by simply entering ➠ www.pdfvce.com 🠰 website 🪓Visual Databricks-Certified-Data-Engineer-Professional Cert Test
- Exam Cram Databricks-Certified-Data-Engineer-Professional Pdf ↗ Databricks-Certified-Data-Engineer-Professional Clearer Explanation ⬅️ Visual Databricks-Certified-Data-Engineer-Professional Cert Test 🏡 Copy URL ✔ www.validtorrent.com ️✔️ open and search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ to download for free ◀New Databricks-Certified-Data-Engineer-Professional Exam Fee
- Reliable Databricks-Certified-Data-Engineer-Professional Dumps 🤣 Reliable Databricks-Certified-Data-Engineer-Professional Exam Testking 🎰 Databricks-Certified-Data-Engineer-Professional Valid Exam Voucher 🪑 Easily obtain ▛ Databricks-Certified-Data-Engineer-Professional ▟ for free download through ⇛ www.pdfvce.com ⇚ 🏝Exam Databricks-Certified-Data-Engineer-Professional Review
- Databricks-Certified-Data-Engineer-Professional Test Braindumps: Databricks Certified Data Engineer Professional Exam - Databricks-Certified-Data-Engineer-Professional Pass-Sure Torrent - Databricks-Certified-Data-Engineer-Professional Ttest Questions 🤴 Search on ➽ www.vceengine.com 🢪 for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ to obtain exam materials for free download 🐰Exam Cram Databricks-Certified-Data-Engineer-Professional Pdf
- Free PDF Quiz 2026 Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam – Efficient Valid Braindumps Questions 😗 The page for free download of ➥ Databricks-Certified-Data-Engineer-Professional 🡄 on 《 www.pdfvce.com 》 will open immediately 🍦Databricks-Certified-Data-Engineer-Professional Reliable Exam Camp
- Databricks Databricks-Certified-Data-Engineer-Professional Questions [2026] 🎆 Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ on ✔ www.troytecdumps.com ️✔️ immediately to obtain a free download 😘Exam Databricks-Certified-Data-Engineer-Professional Simulations
- Free PDF Quiz 2026 Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam – Efficient Valid Braindumps Questions 😛 Simply search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ for free download on ✔ www.pdfvce.com ️✔️ 📪Visual Databricks-Certified-Data-Engineer-Professional Cert Test
- Exam Cram Databricks-Certified-Data-Engineer-Professional Pdf 🏸 Visual Databricks-Certified-Data-Engineer-Professional Cert Test 👖 Databricks-Certified-Data-Engineer-Professional Real Torrent 🤸 Search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ and download exam materials for free through ➽ www.prepawayexam.com 🢪 🙀Exam Cram Databricks-Certified-Data-Engineer-Professional Pdf
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes