Newest Certified-Data-Engineer-Professional Dumps Guide Offers Candidates Correct Actual Databricks Databricks Certified Data Engineer Professional Exam Products

Now in such a Internet so developed society, choosing online training is a very common phenomenon. DumpsValid is one of many online training websites. DumpsValid's online training course has many years of experience, which can provide high quality learning material for examinee participating in Databricks Certification Certified-Data-Engineer-Professional Exam and satisfy all the needs of the students.
| Section | Objectives |
|---|
| Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 2. Create pipeline components using control flow operators such as if/else and foreach
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 5. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 6. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 7. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 8. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Apply Change Data Feed to address streaming table limitations and improve latency
|
| Monitoring and Alerting | - Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
>> Certified-Data-Engineer-Professional Dumps Guide <<
Efficient Certified-Data-Engineer-Professional Dumps Guide Supply you Fast-Download Reliable Exam Dumps for Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional to Study casually
In order to let you understand our products in detail, our Databricks Certified Data Engineer Professional test torrent has a free trail service for all customers. You can download the trail version of our Certified-Data-Engineer-Professional study torrent before you buy our products, you will develop a better understanding of our products by the trail version. In addition, the buying process of our Certified-Data-Engineer-Professional exam prep is very convenient and significant. You will receive the email from our company in 5 to 10 minutes after you pay successfully; you just need to click on the link and log in, then you can start to use our Certified-Data-Engineer-Professional study torrent for studying. Immediate download after pay successfully is a main virtue of our Databricks Certified Data Engineer Professional test torrent. At the same time, you will have the chance to enjoy the 24-hours online service if you purchase our products, so we can make sure that we will provide you with an attentive service.
Databricks Certified Data Engineer Professional Sample Questions (Q27-Q32):
NEW QUESTION # 27
What is the first line of a Databricks Python notebook when viewed in a text editor?
- A. # Databricks notebook source
- B. // Databricks notebook source
- C. -- Databricks notebook source
- D. # MAGIC %python
- E. %python
Answer: A
Explanation:
https://docs.databricks.com/en/notebooks/notebook-export-import.html#import-a-file-and-convert-it-to-a-notebook
NEW QUESTION # 28
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property "contains_pii" = true.
The following SQL DDL statement is executed to create a new table:
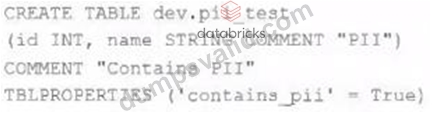
Which command allows manual confirmation that these three requirements have been met?
- A. SHOW TABLES dev
- B. SHOW TBLPROPERTIES dev.pii test
- C. DESCRIBE DETAIL dev.pii test
- D. DESCRIBE HISTORY dev.pii test
- E. DESCRIBE EXTENDED dev.pii test
Answer: E
Explanation:
This is the correct answer because it allows manual confirmation that these three requirements have been met. The requirements are that all tables containing Personal Identifiable Information (PII) must be clearly annotated, which includes adding column comments, table comments, and setting the custom table property "contains_pii" = true. The DESCRIBE EXTENDED command is used to display detailed information about a table, such as its schema, location, properties, and comments. By using this command on the dev.pii_test table, one can verify that the table has been created with the correct column comments, table comment, and custom table property as specified in the SQL DDL statement.
NEW QUESTION # 29
A data engineer is tasked with building a nightly batch ETL pipeline that processes very large volumes of raw JSON logs from a data lake into Delta tables for reporting. The data arrives in bulk once per day, and the pipeline takes several hours to complete. Cost efficiency is important, but performance and reliability of completing the pipeline are the highest priorities. Which type of Databricks cluster should the data engineer configure?
- A. An all-purpose cluster always kept running to ensure low-latency job startup times.
- B. A lightweight single-node cluster with low worker node count to reduce costs.
- C. A job cluster configured to autoscale across multiple workers during the pipeline run.
- D. A high-concurrency cluster designed for interactive SQL workloads.
Answer: C
Explanation:
Job clusters are optimized for automated production workloads. They start when a job is triggered and terminate automatically once the task completes. This ensures cost control while maintaining performance and reliability for batch ETL. Autoscaling allows Databricks to add or remove workers dynamically based on workload size, ensuring large data volumes are processed efficiently.
All-purpose clusters are intended for development or ad-hoc workloads, not scheduled ETL.
NEW QUESTION # 30
The data architect has mandated that all tables in the Lakehouse should be configured as external Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. When configuring an external data warehouse for all table storage. leverage Databricks for all ELT.
- B. When tables are created, make sure that the external keyword is used in the create table statement.
- C. When the workspace is being configured, make sure that external cloud object storage has been mounted.
- D. Whenever a database is being created, make sure that the location keyword is used
- E. Whenever a table is being created, make sure that the location keyword is used.
Answer: E
Explanation:
This is the correct answer because it ensures that this requirement is met. The requirement is that all tables in the Lakehouse should be configured as external Delta Lake tables. An external table is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created by using the location keyword to specify the path to an existing directory in a cloud storage system, such as DBFS or S3. By creating external tables, the data engineering team can avoid losing data if they drop or overwrite the table, as well as leverage existing data without moving or copying it.
NEW QUESTION # 31
A data engineer us ingesting JSON files from cloud object storage using Databricks Auto Loader.
The source folder may occasionally receive large files of data, which risks overwhelming the stream. To ensure predictable micro-batch sizes, the team wants to throttle ingestion based on the volume of data scanned at 1 GB, regardless of the number of files. Which Auto Loader configuration should the data engineer used to achieve this?
- A. Configure cloudFiles.maxBytesPerTrigger with 1 GB to place a limit.
- B. Configure cloudFiles.maxSizePerTrigger with 1 GB to place a limit.
- C. Configure cloudFiles.maxPartitionBytes with 1GB to limit data in each partition.
- D. Configure cloudFiles.maxFilesPerTrigger and estimate the average file size to approximate a size-based throttle of 1 GB.
Answer: A
Explanation:
cloudFiles.maxBytesPerTrigger limits the total volume of data scanned in each micro-batch based on size rather than file count. Setting it to 1 GB ensures predictable ingestion throughput even when large files arrive, preventing any single trigger from overwhelming the streaming job.
NEW QUESTION # 32
......
If you want to maintain your job or get a better job for making a living for your family, it is urgent for you to try your best to get the Certified-Data-Engineer-Professional certification. We are glad to help you get the certification with our best Certified-Data-Engineer-Professional study materials successfully. Our company has done the research of the study material for several years, and the experts and professors from our company have created the famous Certified-Data-Engineer-Professional learning prep for all customers.
Reliable Certified-Data-Engineer-Professional Exam Dumps: https://www.dumpsvalid.com/Certified-Data-Engineer-Professional-still-valid-exam.html
- Free PDF 2026 Databricks Fantastic Certified-Data-Engineer-Professional Dumps Guide ⚪ Easily obtain free download of ➽ Certified-Data-Engineer-Professional 🢪 by searching on ➤ www.prep4sures.top ⮘ 🦮Certified-Data-Engineer-Professional Test Dumps Pdf
- High Pass-Rate Certified-Data-Engineer-Professional Dumps Guide - Win Your Databricks Certificate with Top Score 👾 Simply search for 【 Certified-Data-Engineer-Professional 】 for free download on 【 www.pdfvce.com 】 🚉Certified-Data-Engineer-Professional Valid Real Test
- Certified-Data-Engineer-Professional test braindumps: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional testking PDF 🦆 Copy URL ▶ www.practicevce.com ◀ open and search for ✔ Certified-Data-Engineer-Professional ️✔️ to download for free 🏯Vce Certified-Data-Engineer-Professional Free
- Free PDF 2026 Databricks Fantastic Certified-Data-Engineer-Professional Dumps Guide 🏮 Open website ☀ www.pdfvce.com ️☀️ and search for ⇛ Certified-Data-Engineer-Professional ⇚ for free download 📶Braindumps Certified-Data-Engineer-Professional Downloads
- Latest Certified-Data-Engineer-Professional Mock Exam 🌌 Certified-Data-Engineer-Professional Braindumps Torrent ⛷ Certified-Data-Engineer-Professional Test Simulator 🎱 Download [ Certified-Data-Engineer-Professional ] for free by simply searching on ✔ www.vceengine.com ️✔️ 🦂Certified-Data-Engineer-Professional Valid Real Test
- Certified-Data-Engineer-Professional Test Valid 🙎 Certified-Data-Engineer-Professional Test Simulator 🏎 Exam Dumps Certified-Data-Engineer-Professional Zip 🤶 Download ➽ Certified-Data-Engineer-Professional 🢪 for free by simply searching on ▷ www.pdfvce.com ◁ 😾Certified-Data-Engineer-Professional Certification Exam Dumps
- Free PDF 2026 Databricks Fantastic Certified-Data-Engineer-Professional Dumps Guide 🎦 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and download it for free immediately on ⇛ www.dumpsmaterials.com ⇚ 🍙Latest Certified-Data-Engineer-Professional Mock Exam
- Reliable Certified-Data-Engineer-Professional Dumps Guide, Reliable Certified-Data-Engineer-Professional Exam Dumps 🥼 Easily obtain free download of ▶ Certified-Data-Engineer-Professional ◀ by searching on ⇛ www.pdfvce.com ⇚ 👛Certified-Data-Engineer-Professional Cheap Dumps
- Standard Certified-Data-Engineer-Professional Answers 🤨 Certified-Data-Engineer-Professional PDF Question 🧙 Certification Certified-Data-Engineer-Professional Questions 💾 Open website ➡ www.easy4engine.com ️⬅️ and search for ➽ Certified-Data-Engineer-Professional 🢪 for free download 🔜New Certified-Data-Engineer-Professional Dumps Questions
- 2026 Authoritative Certified-Data-Engineer-Professional Dumps Guide | 100% Free Reliable Databricks Certified Data Engineer Professional Exam Dumps ☘ Search on ▛ www.pdfvce.com ▟ for ▛ Certified-Data-Engineer-Professional ▟ to obtain exam materials for free download 🔕Certified-Data-Engineer-Professional Test Simulator
- Braindumps Certified-Data-Engineer-Professional Downloads 👔 New Certified-Data-Engineer-Professional Dumps Questions 💙 New Certified-Data-Engineer-Professional Dumps Questions 🦀 Search for ▷ Certified-Data-Engineer-Professional ◁ and obtain a free download on { www.vce4dumps.com } ✉Certified-Data-Engineer-Professional Test Simulator
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes