DOWNLOAD the newest RealExamFree AI-200 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=13IoBbtlLTJ_Aa68QnwwBaJQse8OAZm4a
After your purchase of AI-200 learning engine, our system will send a link to your email in 5 to 10 minutes. You can contact our staff anytime and anywhere during the learning process. The staff of AI-200 study materials is online 24 hours a day, seven days a week. Our staff is really serious and responsible. We just want to provide you with the best service. I hope you enjoy using AI-200 Exam Materials.
| Section | Objectives |
|---|---|
| Topic 1: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 2: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 3: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 4: Connect to and consume Azure services | - Integrate Azure services
|
With our excellent AI-200 exam questions, you can get the best chance to obtain the AI-200 certification to improve yourself, for better you and the better future. With our AI-200 training guide, you are acknowledged in your profession. The AI-200 exam braindumps can prove your ability to let more big company to attention you. Then you have more choice to get a better job and going to suitable workplace. Why not have a try on our AI-200 Exam Questions, you will be pleasantly surprised our AI-200 exam questions are the best praparation material.
NEW QUESTION # 76
An AI application retrieves configuration values from App Configuration. The application uses static configuration.
You need to implement a solution that supports dynamic configuration updates and minimizes latency for application requests.
What should you do?
Answer: B
Explanation:
You should cache configuration values with a refresh interval.
Enables Dynamic Configuration: Azure App Configuration providers natively support a cache- polling mechanism. Once the refresh interval expires, the application checks for updates and reloads configuration values automatically without requiring an application restart.
Minimizes Latency: By pulling configuration values from a local, in-memory cache for all intermediary requests, you completely bypass the network latency of making a remote API call to Azure on every single application request.
Prevents Throttling: Relying on cached values prevents your application from exhausting your App Configuration resource's request quota.
Reference:
https://learn.microsoft.com/en-us/azure/azure-app-configuration/howto-best-practices
NEW QUESTION # 77
You are developing a Python application that reads data from Azure Cosmos DB for NoSQL by using the azure-cosmos SDK.
You need to connect to an existing account and run a SQL query against an existing container.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.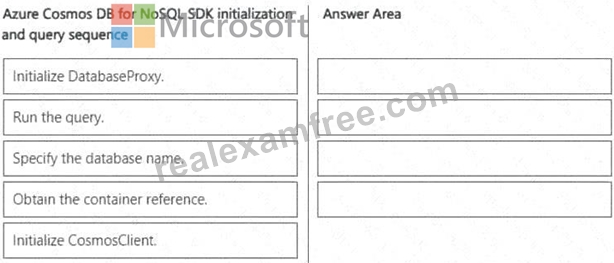
Answer:
Explanation: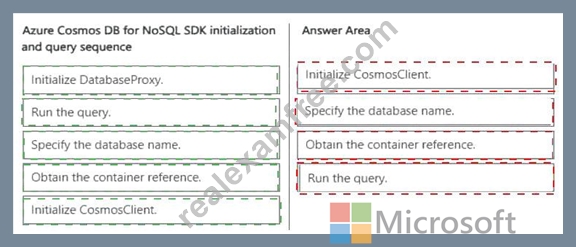
Explanation:
* Initialize CosmosClient.
* Specify the database name.
* Obtain the container reference.
* Run the query.
The Python Azure Cosmos DB SDK follows the resource hierarchy Account # Database # Container # Items . The first step is to initialize a reusable CosmosClient with the Azure Cosmos DB account endpoint and an appropriate credential. Microsoft identifies CosmosClient as the primary client for interacting with databases in an account.
Next, specify the existing database by calling client.get_database_client(database_name). This returns a DatabaseProxy representing that database. Importantly, DatabaseProxy should not be instantiated directly ; Microsoft explicitly states that it should be obtained through CosmosClient.get_database_client().
From the database reference, obtain the target container by using database.get_container_client (container_name). Microsoft documents this as the standard way to retrieve an existing container reference.
Finally, execute the SQL query through container.query_items() , which accepts the Cosmos DB for NoSQL query and optional parameters and returns an iterable result set.
Therefore, Initialize DatabaseProxy is the distractor: the SDK creates the DatabaseProxy through get_database_client; application code should not construct it directly.
Study Guide references: Azure Cosmos DB for NoSQL # Python SDK; CosmosClient; database and container clients; ContainerProxy.query_items().
NEW QUESTION # 78
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Drag and Drop Question
You need to configure event-driven scaling for the backend API services to meet the technical requirements.
Which settings should you use for each element? To answer, move the appropriate settings to the correct elements. You may use each setting once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.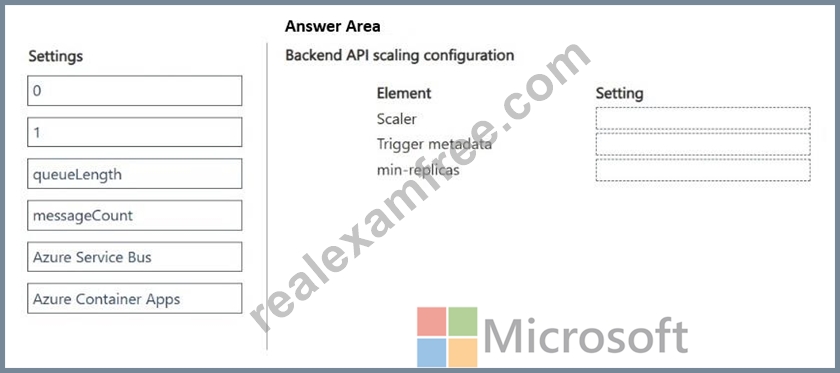
Answer:
Explanation: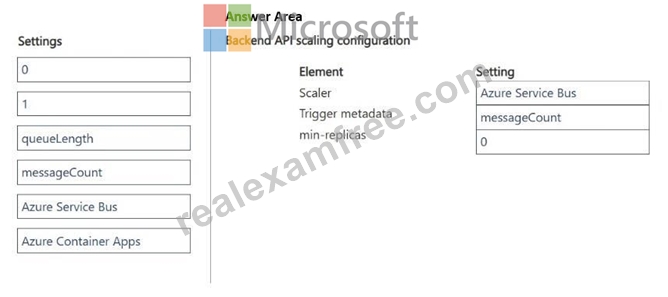
Explanation:
Scenario, technical requirements.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Box 1: Azure Service Bus
Scaler TypeType
Set the scale rule type to custom.
KEDA Scaler Name: Set the type inside the custom specification block to azure-service-bus.
Box 2: messageCount
Trigger Metadata Values
The metadata block dictates how KEDA calculates the required replica count.
Configure the following core metadata parameters:
queueName: The explicit string name of your targeted Azure Service Bus
*-> queue.messageCount: The target integer threshold of concurrent pending messages assigned per replica (e.g., 5 or 10). KEDA uses this value to scale out systematically.
activationMessageCount: Set to 1 or 0. This defines the exact metric floor required to transition the container app out of a dormant state.
namespace: The canonical name of your Service Bus namespace
Box 3: 0
Min-Replicas ConfigurationValue
Set --min-replicas to 0.
Setting this value to zero enables full serverless cost efficiency. KEDA actively handles the background polling, allowing your backend API containers to scale down completely and run zero active replicas when the Service Bus queue contains zero pending messages.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-set-up-keda-based-auto-scaling-with-queue-triggers-in-azure-container-apps/view
NEW QUESTION # 79
You are implementing semantic retrieval for a chatbot.
Embeddings are already stored in Redis. However, vector similarity queries do not return matches.
You need to resolve the vector similarity search issue.
What should you do?
Answer: B
Explanation:
Creating a FLAT vector index on your embedding field will resolve the issue and allow your Redis vector similarity queries to return matches.
In Redis (using the Redis Search and Query features), vector fields cannot be queried using Vector Similarity Search (VSS) syntax until a dedicated vector index is explicitly built over them.
No Automatic Indexing: Redis does not automatically index JSON or Hash fields containing raw binary or string embeddings.
Query Failure: Without an index, VSS queries (using the KNN operator) will fail with syntax errors or return zero results because the query engine cannot parse the unindexed field.
Reference:
https://www.louisbouchard.ai/indexing-methods/
NEW QUESTION # 80
Hotspot Question
You are developing several microservices to run on Azure Container Apps.
You need to monitor and diagnose the microservices.
Which features should you use? To answer, select the appropriate feature in the answer area.
NOTE: Each correct selection is worth one point.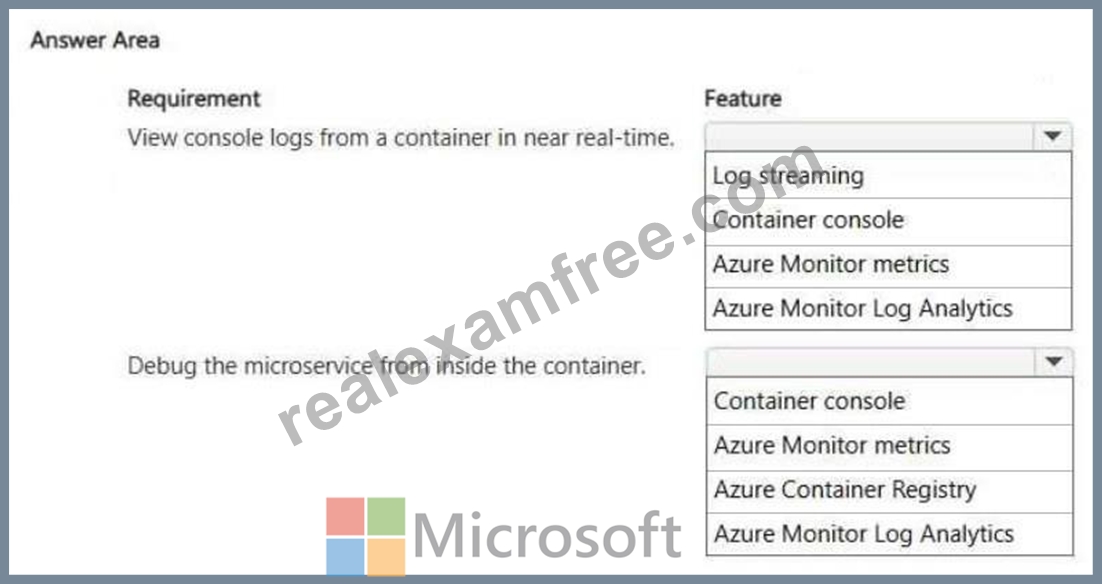
Answer:
Explanation: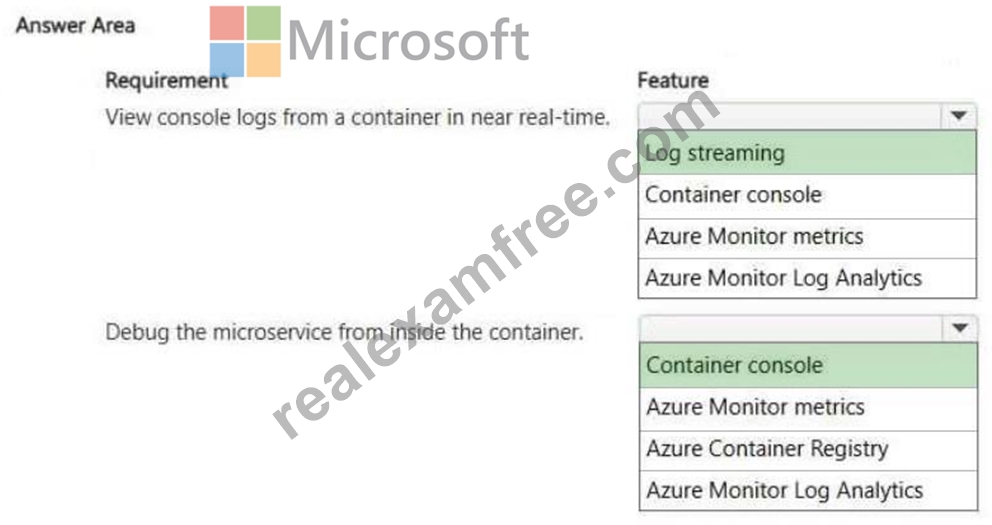
Explanation:
Box 1: Log streaming
To view console logs from an Azure Container App in near real-time, you should use the Log stream feature.
How to Access Log Stream
Navigate to your container app in the Azure portal.
Under the Monitoring section of the sidebar menu, select Log stream.
Set the log type to Console to instantly stream your application's stdout and stderr streams.
Box 2: Container console
To debug your microservice from inside the container, you should use the Container console feature.
Key Features for Debugging and Monitoring
Container console: This feature allows you to connect directly to the Linux console/shell inside your running container instance. You can use it to execute commands, inspect files, and troubleshoot the container's environment in real-time.
Log stream: This tool is used alongside the console to view streaming system and console logs from your container in near real-time.
Azure Monitor Logs: Used for querying and analyzing historical application and system logs over longer periods.
Reference:
https://learn.microsoft.com/en-us/azure/container-apps/observability
NEW QUESTION # 81
......
All formats of RealExamFree's products are immediately usable after purchase. We also offer up to 365 days of free updates so you can prepare as per the Developing AI Cloud Solutions on Azure (AI-200) latest exam content. RealExamFree offers a free demo version of the Microsoft Certification Exams so that you can assess the validity of the product before purchasing it.
AI-200 Latest Test Testking: https://www.realexamfree.com/AI-200-real-exam-dumps.html
BONUS!!! Download part of RealExamFree AI-200 dumps for free: https://drive.google.com/open?id=13IoBbtlLTJ_Aa68QnwwBaJQse8OAZm4a