We strongly recommend using our Databricks Certified-Data-Engineer-Professional exam dumps to prepare for the Databricks Certified-Data-Engineer-Professional certification. It is the best way to ensure success. With our Databricks Certified-Data-Engineer-Professional practice questions, you can get the most out of your studying and maximize your chances of passing your Databricks Certified-Data-Engineer-Professional Exam. Actual4Dumps Databricks Certified-Data-Engineer-Professional practice test software is the answer if you want to score higher in the Databricks Certified-Data-Engineer-Professional exam and achieve your academic goals.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Topic 2: Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Manage dependencies, libraries, and UDFs - Implement scalable Python/SQL code and project structures |
| Topic 3: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Topic 4: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 5: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| Topic 6: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs - Implement row-level security, column masking, and compliance |
| Topic 7: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Topic 8: CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
| Topic 9: Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
>> Exam Certified-Data-Engineer-Professional Tests <<
Actual4Dumps Databricks Certified-Data-Engineer-Professional exam training materials praised by the majority of candidates is not a recent thing. This shows Actual4Dumps Databricks Certified-Data-Engineer-Professional exam training materials can indeed help the candidates to pass the exam. Compared to other questions providers, Actual4Dumps Databricks Certified-Data-Engineer-Professional exam training materials have been far ahead. uestions broad consumer recognition and reputation, it has gained a public praise. If you want to participate in the Databricks Certified-Data-Engineer-Professional Exam, quickly into Actual4Dumps website, I believe you will get what you want. If you miss you will regret, if you want to become a professional IT expert, then quickly add it to cart.
NEW QUESTION # 226
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
MERGE INTO customers
USING (
SELECT updates.customer_id as merge_ey, updates .*
FROM updates
UNION ALL
SELECT NULL as merge_key, updates .*
FROM updates JOIN customers
ON updates.customer_id = customers.customer_id
WHERE customers.current = true AND updates.address <> customers.address ) staged_updates ON customers.customer_id = mergekey WHEN MATCHED AND customers. current = true AND customers.address <> staged_updates.address THEN UPDATE SET current = false, end_date = staged_updates.effective_date WHEN NOT MATCHED THEN INSERT (customer_id, address, current, effective_date, end_date) VALUES (staged_updates.customer_id, staged_updates.address, true, staged_updates.effective_date, null) Which statement describes this implementation?
Answer: C
Explanation:
The provided MERGE statement is a classic implementation of a Type 2 SCD in a data warehousing context. In this approach, historical data is preserved by keeping old records (marking them as not current) and adding new records for changes. Specifically, when a match is found and there's a change in the address, the existing record in the customers table is updated to mark it as no longer current (current = false), and an end date is assigned (end_date = staged_updates.effective_date). A new record for the customer is then inserted with the updated information, marked as current. This method ensures that the full history of changes to customer information is maintained in the table, allowing for time-based analysis of customer data.
NEW QUESTION # 227
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.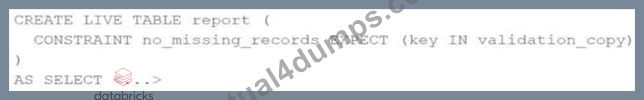
Which approach would allow using DLT expectations to validate all expected records are present in this table?
Answer: A
Explanation:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
NEW QUESTION # 228
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
Answer: A
Explanation:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = 'expectation_result' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
NEW QUESTION # 229
A data architect is designing a Databricks solution to efficiently process data for different business requirements. In which scenario should a data engineer use a materialized view compared to a streaming table?
Answer: C
Explanation:
Materialized views in Databricks are optimized for precomputing and caching results of complex SQL queries, joins, and aggregations. They store query outputs physically and automatically refresh on a schedule or incremental change basis, drastically improving BI dashboard performance and reducing compute costs.
Conversely, streaming tables are designed for real-time data ingestion and processing, enabling event-driven analytics and low-latency use cases.
Databricks documentation explicitly recommends materialized views for analytical workloads with periodic updates and streaming tables for continuously updating sources. Therefore, the correct choice is C, where complex aggregations from large tables benefit most from materialized precomputation for fast reporting.
NEW QUESTION # 230
A data engineer is designing a Lakeflow Declarative Pipeline to process streaming order data.
The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id and amount are greater than zero. Invalid records should be dropped. Which Lakeflow Declarative Pipelines configurations implement this requirement using Python?
Answer: B
Explanation:
Lakeflow Declarative Pipelines (LDP), formerly Delta Live Tables (DLT), supports enforcing data quality using expectations. Expectations can either:
Track violations (expect) -> records that do not meet conditions are flagged but still included in the pipeline.
Drop violations (expect_or_drop) -> records that do not meet conditions are excluded from downstream tables.
Fail pipeline on violations (expect_or_fail) -> records that fail conditions stop the pipeline.
In this scenario, the requirement explicitly states that invalid records (where customer_id is null or amount < 0) must be dropped. According to the official documentation, the correct method is .expect_or_drop("expectation_name", "SQL_predicate") applied on the streaming input.
Option A is correct: It uses .expect_or_drop directly within the transformation chain for both rules, ensuring records that fail are removed before writing to the silver table.
Option B incorrectly uses @dlt.expect decorators, which only track violations but do not drop invalid rows.
Option C uses .expect, which also only flags rows, not drop them.
Option D uses @dlt.expect_or_drop decorator syntax, which is not supported in Python API; expect_or_drop must be applied as a method on the DataFrame, not as a decorator.
Therefore, the correct solution is Option A, which ensures compliance by enforcing data quality and dropping invalid rows programmatically during ingestion.
NEW QUESTION # 231
......
Our test engine has been introduced for the preparation of Certified-Data-Engineer-Professional practice test and bring great convenience for most IT workers. It will make you feel the atmosphere of the Certified-Data-Engineer-Professional actual test and remark the mistakes when you practice the exam questions. We strongly recommend that you should prepare your Certified-Data-Engineer-Professional Exam PDF with our test engine before taking real exam.
Trustworthy Certified-Data-Engineer-Professional Pdf: https://www.actual4dumps.com/Certified-Data-Engineer-Professional-study-material.html