2026 Latest PDFBraindumps ARA-C01 PDF Dumps and ARA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1tXQ-Ilt35M4muU2F4y9He7-64w75zVCk
Our company always lays great emphasis on service. All of our works have good sense of service. Once you browser our website and select the ARA-C01 exam questions, we have arrange all study materials separately and logically. You will know the details if you click the ARA-C01 practice quiz. You will find that it is easy, fast and convenient. And if you have something confused on our ARA-C01 learning braindumps, then you can contact with our service online or send email to us. We will help you in the first time.
The SnowPro Advanced Architect Certification Exam is a rigorous exam that evaluates the candidate’s knowledge and expertise in various areas of Snowflake architecture, including data modeling, security, performance, scalability, and data integration. ARA-C01 Exam is designed to test the candidate’s ability to design, configure, and optimize Snowflake solutions to meet the specific needs of a business. The SnowPro Advanced Architect Certification Exam is a vendor-neutral certification program that is recognized by leading companies worldwide, making it a valuable credential for professionals who want to advance their career in the field of data warehousing and analytics.
>> Snowflake ARA-C01 Valid Exam Blueprint <<
Our users of the ARA-C01 learning guide are all over the world. Therefore, we have seen too many people who rely on our ARA-C01 exam materials to achieve counterattacks. Everyone's success is not easily obtained if without our ARA-C01 study questions. Of course, they have worked hard, but having a competent assistant is also one of the important factors. And our ARA-C01 Practice Engine is the right key to help you get the certification and lead a better life!
Snowflake ARA-C01 exam covers a wide range of topics, including data modeling, security, performance, and scalability. ARA-C01 exam also tests the candidate's knowledge of Snowflake's data warehousing capabilities, including how to design and implement a data warehouse solution using Snowflake's features. ARA-C01 Exam is designed to test a candidate's ability to design and implement complex data solutions on the Snowflake platform.
NEW QUESTION # 118
A Snowflake Architect is designing a multi-tenant application strategy for an organization in the Snowflake Data Cloud and is considering using an Account Per Tenant strategy.
Which requirements will be addressed with this approach? (Choose two.)
Answer: A,C
Explanation:
An Account Per Tenant strategy means creating a separate Snowflake account for each tenant (customer or business unit) of the multi-tenant application.
This approach has some advantages and disadvantages compared to other strategies, such as Database Per Tenant or Schema Per Tenant.
One advantage is that each tenant can have a unique data shape, meaning they can define their own tables, views, and other objects without affecting other tenants. This allows for more flexibility and customization for each tenant. Therefore, option D is correct.
Another advantage is that storage costs can be optimized, because each tenant can use their own storage credits and manage their own data retention policies. This also reduces the risk of data spillover or cross-tenant access. Therefore, option E is correct.
However, this approach also has some drawbacks, such as:
It requires more administrative overhead and complexity to manage multiple accounts and their resources.
It may not optimize compute costs, because each tenant has to provision their own warehouses and pay for their own compute credits. This may result in underutilization or overprovisioning of compute resources. Therefore, option C is incorrect.
It may not simplify security and RBAC policies, because each account has to define its own roles, users, and privileges. This may increase the risk of human errors or inconsistencies in security configurations. Therefore, option B is incorrect.
It may not reduce the number of objects per tenant, because each tenant still has to create their own databases, schemas, and other objects within their account. This may affect the performance and scalability of the application. Therefore, option A is incorrect.
NEW QUESTION # 119
A table contains five columns and it has millions of records. The cardinality distribution of the columns is shown below: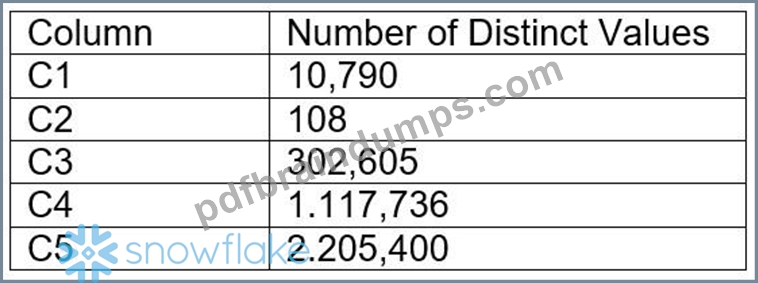
Column C4 and C5 are mostly used by SELECT queries in the GROUP BY and ORDER BY clauses. Whereas columns C1, C2 and C3 are heavily used in filter and join conditions of SELECT queries.
The Architect must design a clustering key for this table to improve the query performance.
Based on Snowflake recommendations, how should the clustering key columns be ordered while defining the multi-column clustering key?
Answer: B
Explanation:
According to the Snowflake documentation, the following are some considerations for choosing clustering for a table1:
Clustering is optimal when either:
You require the fastest possible response times, regardless of cost.
Your improved query performance offsets the credits required to cluster and maintain the table.
Clustering is most effective when the clustering key is used in the following types of query predicates:
Filter predicates (e.g. WHERE clauses)
Join predicates (e.g. ON clauses)
Grouping predicates (e.g. GROUP BY clauses)
Sorting predicates (e.g. ORDER BY clauses)
Clustering is less effective when the clustering key is not used in any of the above query predicates, or when the clustering key is used in a predicate that requires a function or expression to be applied to the key (e.g. DATE_TRUNC, TO_CHAR, etc.).
For most tables, Snowflake recommends a maximum of 3 or 4 columns (or expressions) per key. Adding more than 3-4 columns tends to increase costs more than benefits.
Based on these considerations, the best option for the clustering key columns is C. C1, C3, C2, because:
These columns are heavily used in filter and join conditions of SELECT queries, which are the most effective types of predicates for clustering.
These columns have high cardinality, which means they have many distinct values and can help reduce the clustering skew and improve the compression ratio.
These columns are likely to be correlated with each other, which means they can help co-locate similar rows in the same micro-partitions and improve the scan efficiency.
These columns do not require any functions or expressions to be applied to them, which means they can be directly used in the predicates without affecting the clustering.
NEW QUESTION # 120
When a cloned table is replicated to a secondary database, the data also gets replicated in the secondary database
Answer: B
NEW QUESTION # 121
The diagram shows the process flow for Snowpipe auto-ingest with Amazon Simple Notification Service (SNS) with the following steps:
Step 1: Data files are loaded in a stage.
Step 2: An Amazon S3 event notification, published by SNS, informs Snowpipe - by way of Amazon Simple Queue Service (SQS) - that files are ready to load. Snowpipe copies the files into a queue.
Step 3: A Snowflake-provided virtual warehouse loads data from the queued files into the target table based on parameters defined in the specified pipe.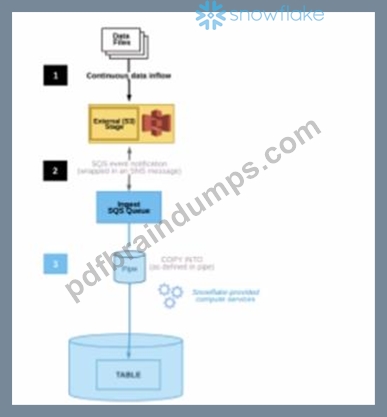
If an AWS Administrator accidentally deletes the SQS subscription to the SNS topic in Step 2, what will happen to the pipe that references the topic to receive event messages from Amazon S3?
Answer: D
NEW QUESTION # 122
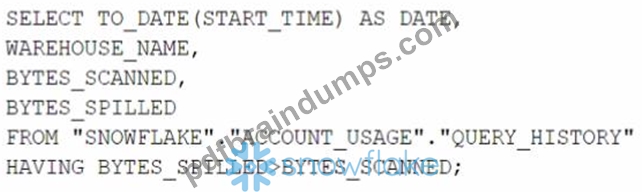
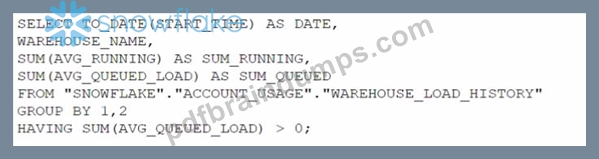
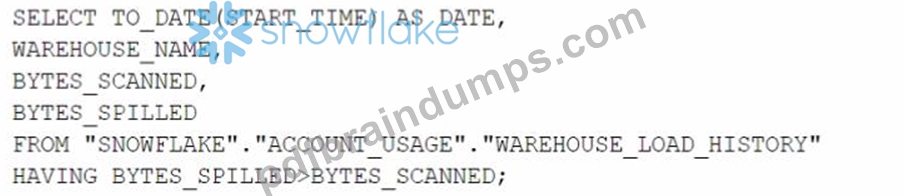
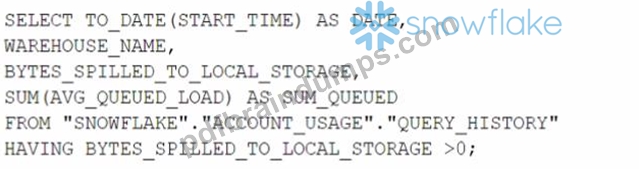
Which query will identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse to improve the performance of a particular workload?
Answer: B
Explanation:
The correct answer is option B. This query is designed to assess the need for a multi-cluster warehouse by examining the queuing time (AVG_QUEUED_LOAD) on different days and virtual warehouses. When the AVG_QUEUED_LOAD is greater than zero, it suggests that queries are waiting for resources, which can be an indicator that performance might be improved by using a multi-cluster warehouse to handle the workload more efficiently. By grouping by date and warehouse name and filtering on the sum of the average queued load being greater than zero, the query identifies specific days and warehouses where the workload exceeded the available compute resources. This information is valuable when considering scaling out warehouses to multi-cluster configurations for improved performance.
NEW QUESTION # 123
......
Detailed ARA-C01 Study Dumps: https://www.pdfbraindumps.com/ARA-C01_valid-braindumps.html
P.S. Free & New ARA-C01 dumps are available on Google Drive shared by PDFBraindumps: https://drive.google.com/open?id=1tXQ-Ilt35M4muU2F4y9He7-64w75zVCk