P.S. Free 2026 Microsoft AI-300 dumps are available on Google Drive shared by DumpStillValid: https://drive.google.com/open?id=19QTYvQNGaIUt93h45EIhQVpqR1QgYq_F
As we all know, the world does not have two identical leaves. People’s tastes also vary a lot. So we have tried our best to develop the three packages for you to choose. Now we have free demo of the AI-300 study materials, which can print on papers and make notes. Then windows software of the AI-300 Exam Questions, which needs to install on windows software. Aiso online engine of the AI-300 study materials, which is convenient because it doesn’t need to install on computers.
| Section | Weight | Objectives |
|---|---|---|
| Implement machine learning model lifecycle and operations | 25–30% | - Deploy models to production
|
| Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
>> Reliable AI-300 Exam Materials <<
The most distinguished feature of AI-300 DumpStillValid's study guides is that they provide you the most workable solution to grasp the core information of the certification syllabus in an easy to learn set of AI-300 study questions. Far more superior in quality than any online courses free, the questions and answers contain information drawn from the best available sources. They are relevant to the exam standards and are made on the format of the actual AI-300 Exam.
NEW QUESTION # 96
A team is developing a generative AI assistant. The team is experimenting with multiple prompt variants to improve the user experience.
When comparing prompt variants, the team plans to assess whether the generated responses are grammatically correct.
You need to evaluate the quality of the language from the generated responses.
Which evaluator should you use?
Answer: B
Explanation:
The best evaluator within the Microsoft ecosystem for checking the grammatical correctness of generative AI responses--especially when testing multiple prompt variants--is the Azure AI Evaluator for Fluency, available within Azure AI Foundry.
Fluency Evaluator (builtin.fluency)
Purpose: Specifically designed to measure the effectiveness and clarity of written communication.
Grammatical Focus: It assesses grammatical accuracy, sentence structure, punctuation, and vocabulary usage in AI-generated text.
Result: It provides a 1-5 Likert scale score, allowing you to compare which prompt variants produce the most grammatically correct, natural-sounding responses.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/prompt-flow/concept-model-monitoring- generative-ai-evaluation-metrics
NEW QUESTION # 97
An organization runs a customer-facing generative AI application built by using Microsoft Foundry. The application uses multiple prompts linked to multiple workflows to generate responses in production.
The application occasionally returns incomplete responses. The model call succeeds, but the final message sometimes stops early.
The issue cannot be reproduced reliably in development.
You need to identify where and why response generation is terminating early in production.
Which approach should you use?
Answer: C
Explanation:
Enabling end-to-end tracing and logging is the most effective action to isolate this issue. Because the model call succeeds, the premature termination is likely caused by token limits, downstream application logic, or network timeouts rather than a failure in the LLM itself.
Here is how to isolate and fix the issue using tracing, along with the most likely culprits.
What to Log and Trace
To find the exact point of failure, your tracing system must capture specific metadata for every step of your production workflows:
Finish Reason: Check the finish_reason string returned in the API metadata. If it says length, the model hit a token limit. If it says stop, the model thinks it finished naturally.
Token Counts: Log completion_tokens, prompt_tokens, and total_tokens for every single prompt node.
Raw Prompt vs. Output: Capture the exact, fully rendered prompt string sent to the model, not just the template.
Workflow Node Timestamps: Log the exact entry and exit times for every workflow node to detect quiet timeouts.
Reference:
https://dev.to/utibe_okodi_339fb47a13ef5/your-ai-agent-just-failed-in-production-where-do-you-even-start-debugging-268
NEW QUESTION # 98
A product team is building a customer support assistant that must respond consistently across multiple channels.
Early testing shows that small wording changes in prompts cause large differences in tone and factual accuracy.
The team needs prompts that are reliable, reusable, and adaptable across multiple use cases without retraining the underlying model.
You need to design prompts that improve response quality while remaining flexible for future changes.
Which two actions should you perform? Each correct answer presents part of the solution.
(Choose two.)
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
To achieve reliable, reusable, and adaptable prompts without retraining the model, you should implement Prompt Flow, use System Messages for tone/role definition, and enforce Output Parsing. These techniques standardize how the model behaves across all channels.
Here is the most effective approach to stabilize your customer support assistant:
[B]
1. Implement Prompt Flow
Instead of hardcoding raw prompts in your code, use Azure Machine Learning Prompt Flow.
Visual Workflows: Create executable flows that link LLMs, prompts, and Python tools.
Versioning: Easily track, iterate, and roll back prompt versions without touching application code.
Evaluation: Test prompt variants systematically against a set of baseline queries to objectively measure factual accuracy and tone before pushing to production.
[C]
2. Standardize System Messages
A well-defined system message serves as the "guardrails" for your assistant. It should dictate the persona, scope of knowledge, and safety rules.
Define the Persona: Instruct the model exactly how to behave (e.g., "You are a helpful, empathetic, and strictly technical support assistant for [Company Name].").Strict Guidelines:
Provide instructions on how to handle out-of-scope queries (e.g., "If you do not know the answer, do not guess. Apologize and route the user to [Support Email].").
Reference:
https://whitebeardstrategies.com/blog/5-best-practices-for-efficient-language-model-prompting/
NEW QUESTION # 99
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage an Azure Machine Learning workspace. The Python script named script.py reads an argument named training_data. The training_data argument specifies the path to the training data in a file named dataset1.csv.
You plan to run the script.py Python script as a command job that trains a machine learning model.
You need to provide the command to pass the path for the dataset as a parameter value when you submit the script as a training job.
Solution: python script.py --trainingdata ${{inputs.training_data}}
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* python script.py --training_data ${{inputs.training_data}}
The scipt is named script.py.
For the parameter use ${{inputs.training_data}}
Incorrect:
* python script.py --training_data dataset1.csv
* python script.py dataset1.csv
* python train.py --training_data training_data
Note: Read a TabularDataset, Example
In the Input object, specify the type as AssetTypes.MLTABLE, and mode as InputOutputModes.DIRECT:
* Details omitted*
job = command(
code="./src", # Local path where the code is stored
*-> command="python train.py --inputs ${{inputs.input_data}}",
inputs=my_job_inputs,
environment="<environment_name>:<version>",
compute="cpu-cluster",
)
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-read-write-data-v2
NEW QUESTION # 100
Hotspot Question
A machine learning model is deployed to production in Azure Machine Learning and is actively serving predictions for a business application. The model was trained by using a historical dataset that represented expected input patterns at the time of deployment.
The team working on the model must ensure the following:
- Changes in input data distribution are detected.
- Appropriate actions are triggered when predefined thresholds are
exceeded.
You need to configure monitoring to meet the requirements.
Which configuration should you use for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.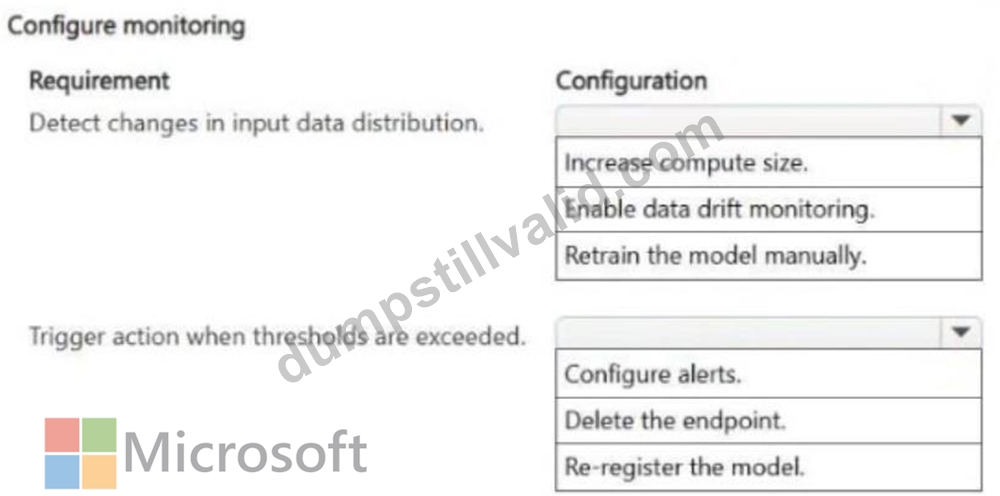
Answer:
Explanation: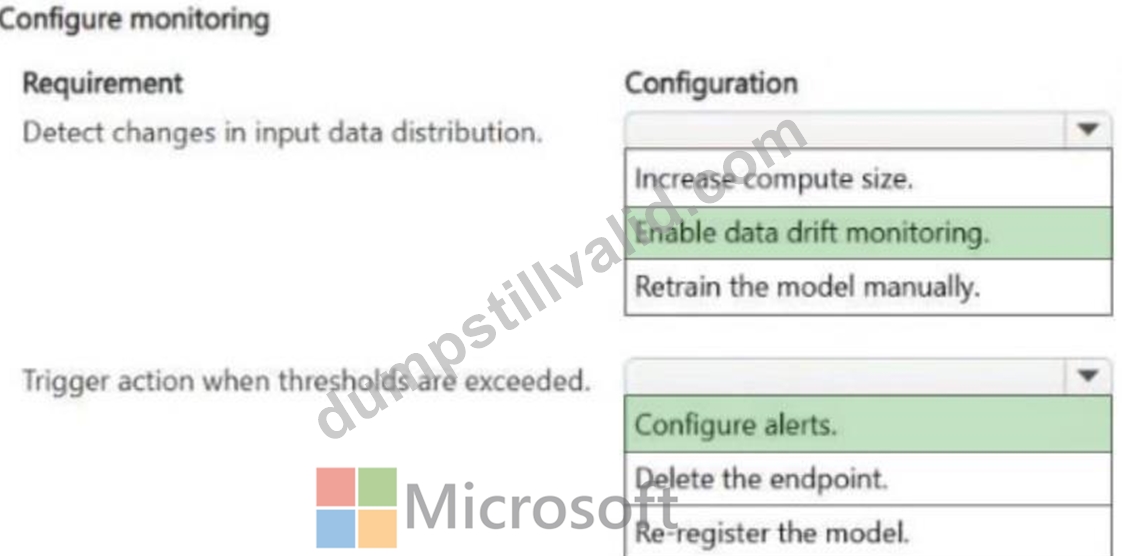
NEW QUESTION # 101
......
The Operationalizing Machine Learning and Generative AI Solutions (AI-300) questions are in use by many customers currently, and they are preparing for their best future daily. Even the students who used it in the past to prepare for the Microsoft Certification Exam have rated our practice questions as one of the best. You will receive updates till 365 days after your purchase, and there is a 24/7 support system that assists you whenever you are stuck in any problem or issues.
AI-300 Practice Exam Pdf: https://www.dumpstillvalid.com/AI-300-prep4sure-review.html
2026 Latest DumpStillValid AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=19QTYvQNGaIUt93h45EIhQVpqR1QgYq_F