P.S.JPNTestがGoogle Driveで共有している無料の2026 Microsoft DP-600ダンプ:https://drive.google.com/open?id=1U_AhYtg9JU_goiVn-wzyWuHoH1BwEMoc
世界経済の急速な発展に伴い、ますます多くの人々が社会的エリートになることを切望していることが広く受け入れられています。 DP-600最新の学習ガイド資料は、ソーシャルエリートになりたい多くの人々の近道となります。 DP-600試験の準備に最善を尽くし、短時間で関連する認定を取得すれば、私たちのような大企業の多くのリーダーから注目を集めることが容易になり、非常に簡単になります。 DP-600学習ガイドの助けを借りて、多くの人々が労働市場で適切な仕事を得ることができます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
あなたはJPNTestが提供したMicrosoftのDP-600認定試験の問題集だけ利用して合格することが問題になりません。ほかの人を超えて業界の中で最大の昇進の機会を得ます。もしあなたはJPNTestの商品がショッピング車に入れて24のインターネットオンライン顧客サービスを提供いたします。問題があったら気軽にお問いください、
質問 # 160
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a semantic model named Model1.
You discover that the following query performs slowly against Model1.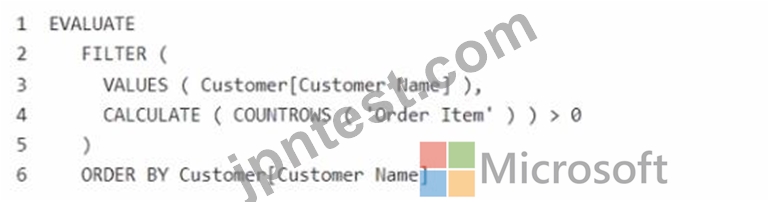
You need to reduce the execution time of the query.
Solution: You replace line 4 by using the following code:
Does this meet the goal?
正解:A
質問 # 161
You are analyzing customer purchases in a Fabric notebook by using PySpanc You have the following DataFrames:
You need to join the DataFrames on the customer_id column. The solution must minimize data shuffling. You write the following code.
Which code should you run to populate the results DataFrame?




正解:C
解説:
The correct code to populate the results DataFrame with minimal data shuffling is Option A. Using the broadcast function in PySpark is a way to minimize data movement by broadcasting the smaller DataFrame (customers) to each node in the cluster. This is ideal when one DataFrame is much smaller than the other, as in this case with customers. References = You can refer to the official Apache Spark documentation for more details on joins and the broadcast hint.
質問 # 162
You need to create a DAX measure to calculate the average overall satisfaction score.
How should you complete the DAX code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.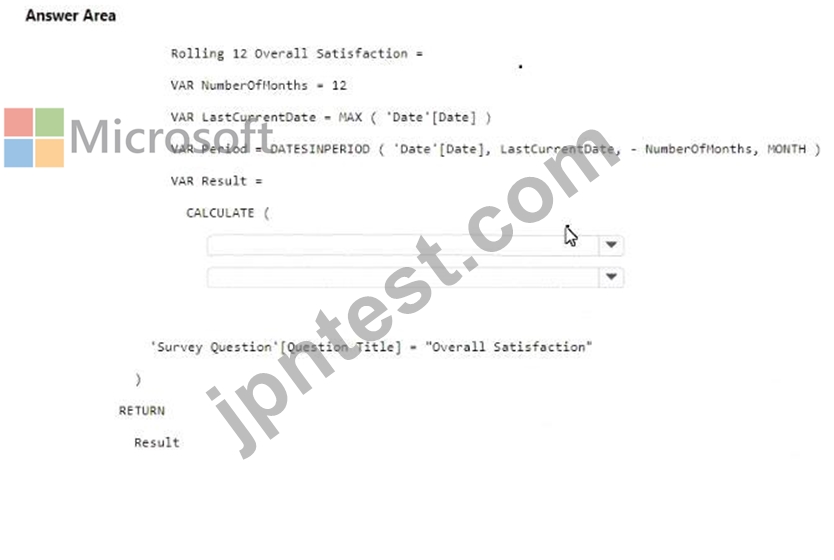
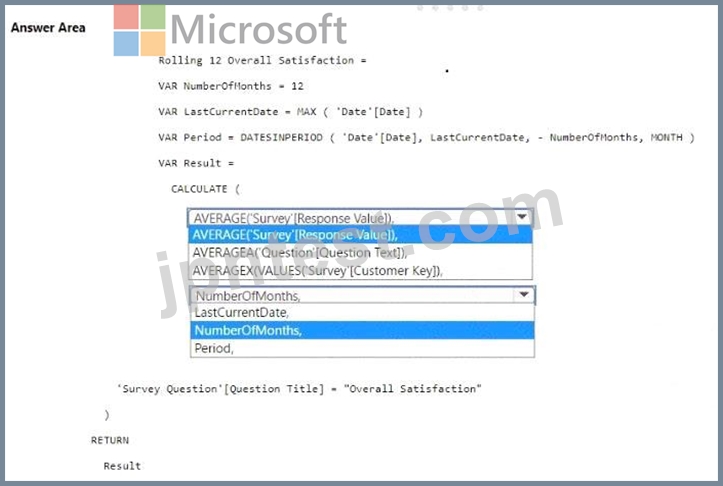
正解:
解説: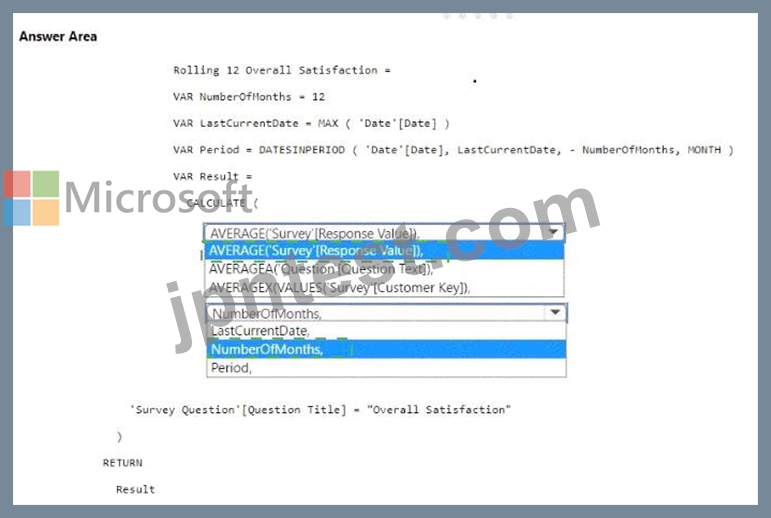
Explanation:
The measure should use the AVERAGE function to calculate the average value.
It should reference the Response Value column from the ' Survey ' table.
The ' Number of months ' should be used to define the period for the average calculation.
To calculate the average overall satisfaction score using DAX, you would need to use the AVERAGE function on the response values related to satisfaction questions. The DATESINPERIOD function will help in calculating the rolling average over the last 12 months.
Topic 2, Contoso, ltd.
Overview
Contoso, ltd. is a US-based health supplements company, Contoso has two divisions named Sales and Research. The Sales division contains two departments named Online Sales and Retail Sales. The Research division assigns internally developed product lines to individual teams of researchers and analysts.
Identity Environment
Contoso has a Microsoft Entra tenant named contoso.com. The tenant contains two groups named ResearchReviewersGroupi and ReseachReviewefsGfoup2.
Data Environment
Contoso has the following data environment
* The Sales division uses a Microsoft Power B1 Premium capacity.
* The semantic model of the Online Sales department includes a fact table named Orders that uses import mode. In the system of origin, the OrderlD value represents the sequence in which orders are created.
* The Research department uses an on-premises. third-party data warehousing product.
* Fabric is enabled for contoso.com.
* An Azure Data Lake Storage Gen2 storage account named storage1 contains Research division data for a product line named Producthne1. The data is in the delta format.
* A Data Lake Storage Gen2 storage account named storage2 contains Research division data for a product line named Productline2. The data is in the CSV format.
Planned Changes
Contoso plans to make the following changes:
* Enable support for Fabric in the Power Bl Premium capacity used by the Sales division.
* Make all the data for the Sales division and the Research division available in Fabric.
* For the Research division, create two Fabric workspaces named Producttmelws and Productline2ws.
* in Productlinelws. create a lakehouse named LakehouseV
* In Lakehouse1. create a shortcut to storage1 named ResearchProduct.
Data Analytics Requirements
Contoso identifies the following data analytics requirements:
* All the workspaces for the Sales division and the Research division must support all Fabric experiences.
* The Research division workspaces must use a dedicated, on-demand capacity that has per-minute billing.
* The Research division workspaces must be grouped together logically to support OneLake data hub filtering based on the department name.
* For the Research division workspaces, the members of ResearchRevtewersGroupl must be able to read lakehouse and warehouse data and shortcuts by using SQL endpoints.
* For the Research division workspaces, the members of ResearchReviewersGroup2 must be able to read lakehouse data by using Lakehouse explorer.
* All the semantic models and reports for the Research division must use version control that supports branching Data Preparation Requirements Contoso identifies the following data preparation requirements:
* The Research division data for Producthne2 must be retrieved from Lakehouset by using Fabric notebooks.
* All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer.
Semantic Model Requirements
Contoso identifies the following requirements for implementing and managing semantic models;
* The number of rows added to the Orders table during refreshes must be minimized.
* The semantic models in the Research division workspaces must use Direct Lake mode.
General Requirements
Contoso identifies the following high-level requirements that must be considered for all solutions:
* Follow the principle of least privilege when applicable
* Minimize implementation and maintenance effort when possible.
質問 # 163
You have a query in Microsoft Power BI Desktop that contains two columns named Order_Date and Shipping_Date.
You need to create a column that will calculate the number of days between Order_Date and Shipping_Date for each row.
Which Power Query function should you use?
正解:A
質問 # 164
You have a Microsoft Power Bl semantic model that is used by your company ' s finance and sales departments for monthly reporting. The semantic model contains two explicit measures named sales Amount and Orders and a measure named KPI Title that returns text for dynamic visual titles.
You need to implement a calculation group named Time Intelligence that contains a column named Time Calculation. The solution must meet the following requirements
* Apply time-intelligence patterns to both explicit measures by using SELECTEDMEASURE().
* Format only the yoy% calculation item as a percentage.
What should you configure ' To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point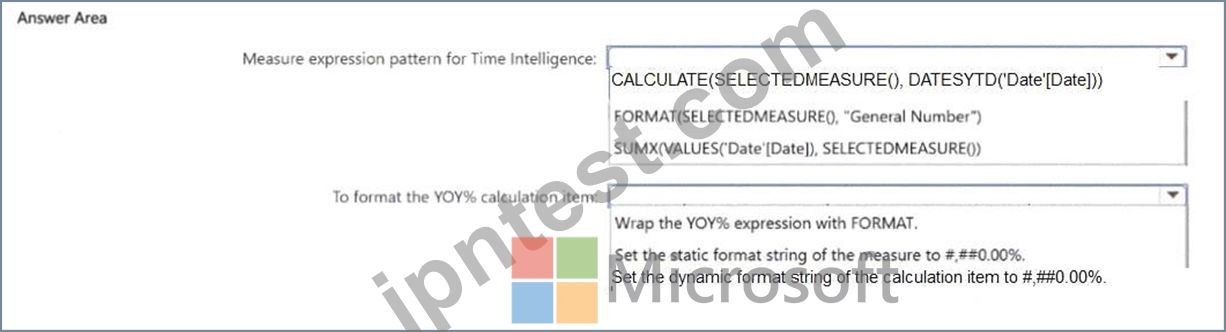
正解:
解説: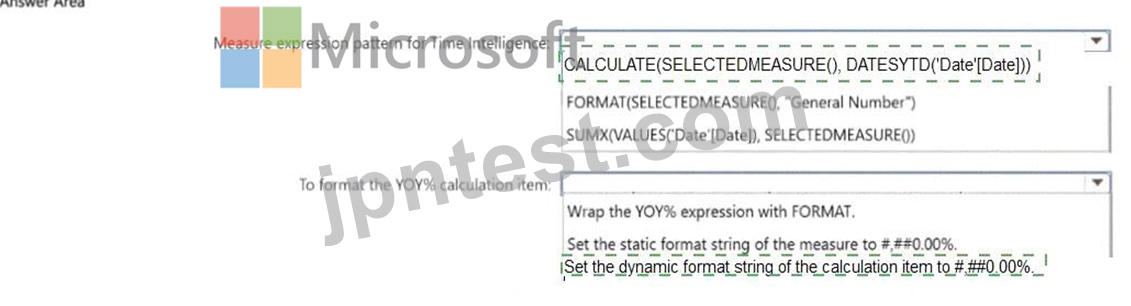
Explanation: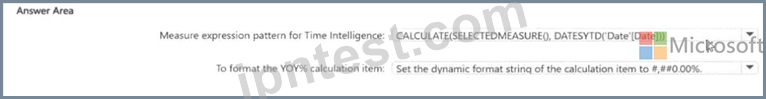
質問 # 165
......
最高のサービスを提供することを義務と考えています。 そのため、患者の同僚が24時間年中無休でサポートを提供し、DP-600実践教材に関する問題をすべて解決します。 あなたが私たちを必要とする限り、私たちは思いやりのあるサービスを提供しています。 それに、一生懸命努力しながら失敗することは不名誉ではありません。 残念ながらDP-600スタディガイドで試験に不合格になった場合、他のバージョンに切り替えるか、今回は不合格であると仮定して全額返金し、不合格書類で証明します。 あなたの能力を過小評価しないでください。DP-600の実際のテストを試みている間、私たちはあなたの最強のバックアップになります。
DP-600最新テスト: https://www.jpntest.com/shiken/DP-600-mondaishu
さらに、JPNTest DP-600ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1U_AhYtg9JU_goiVn-wzyWuHoH1BwEMoc