P.S. Free & New SPS-C01 dumps are available on Google Drive shared by VCEEngine: https://drive.google.com/open?id=1mdO_G1YhPPtQJjGi117BIqd3vbgmHnNN
In the information era, IT industry is catching more and more attention. In the society which has a galaxy of talents, there is still lack of IT talents. Many companies need IT talents, and generally, they investigate IT talents's ability in according to what IT related authentication certificate they have. So having some IT related authentication certificate is welcomed by many companies. But these authentication certificate are not very easy to get. Snowflake SPS-C01 is a quite difficult certification exams. Although a lot of people participate in Snowflake SPS-C01 exam, the pass rate is not very high.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and DataFrame Operations | 35% | - Using built-in functions - Complex data pipelines - Window functions - Persisting transformed data - Filtering, Aggregating, and Joining DataFrames |
| Snowpark API for Python | 30% | - DataFrame creation and manipulation - User-Defined Functions (UDFs) and Stored Procedures - Reading and writing data - Establishing connections and session management - Working with Semi-structured data |
| Performance Optimization and Best Practices | 20% | - Debugging and explain plans - Warehouse sizing for Snowpark - Query pushdown and optimization - Minimizing data transfer - Caching strategies - Vectorized UDFs |
| Snowpark Concepts | 15% | - Transformations vs. Actions - Client-side vs. Server-side execution - Stored procedures and conditional logic - Snowpark DataFrames and query plans - Snowpark architecture and core concepts - Snowpark Sessions and connection management |
>> SPS-C01 Exam Actual Questions <<
Our Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam dumps are useful for preparation and a complete source of knowledge. If you are a full-time job holder and facing problems finding time to prepare for the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions, you shouldn't worry more about it. One of the main unique qualities of the VCEEngine Snowflake Exam Questions is its ease of use. Our practice exam simulators are user and beginner friendly. You can use Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) PDF dumps and Web-based software without installation. Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) PDF questions work on all the devices like smartphones, Macs, tablets, Windows, etc. We know that it is hard to stay and study for the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam dumps in one place for a long time. Therefore, you have the option to use Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) PDF questions anywhere and anytime.
NEW QUESTION # 179
You have a Snowpark DataFrame named containing order data that needs to be inserted into the 'ORDERS table. However, due to a recent data ingestion issue, some records in might already exist in the 'ORDERS table based on the 'ORDER ID' column. Your goal is to insert only the new orders into the 'ORDERS table while avoiding duplicates. Which of the following approaches, combining efficiency and correctness, is most suitable for this task? Assume 'session' and required libraries are already imported.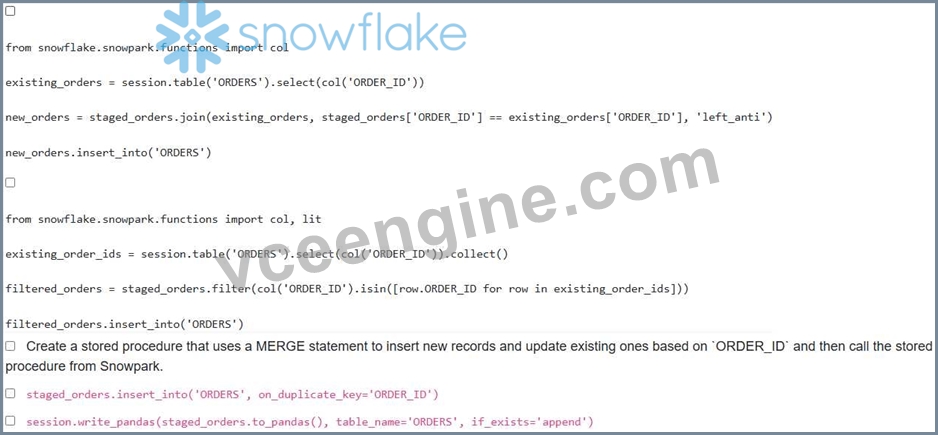
Answer: B,C
Explanation:
Options A and C are both suitable and efficient. Option A uses a 'left_anti' join to identify records in 'staged_orders' that do not exist in the 'ORDERS' table based on 'ORDER ID. This is a standard and efficient way to filter out existing records using Snowpark's DataFrame operations. Option C suggests a stored procedure with a MERGE statement, which is highly efficient for upsert operations directly within Snowflake. Option B is inefficient because it collects all the order IDs from the 'ORDERS table into the driver's memory, which could cause memory issues with large datasets. Option D is incorrect as 'on_duplicate_key' is not a valid parameter for insert_into method. Option E is using pandas dataframe to insert, which might not perform well in terms of scale.
NEW QUESTION # 180
You're working with Snowpark and have a DataFrame 'df containing a column 'json_data' with JSON strings. Some of these JSON strings are invalid. You need to parse the valid JSON strings and extract a field named 'product_id' from them. Invalid JSON strings should result in a 'NULL' value for the extracted 'product_id'. Which of the following approaches is the MOST robust and efficient way to achieve this?





Answer: E
Explanation:
Option B is the most robust and efficient. handles invalid JSON strings gracefully by returning 'NULL'. The other options have drawbacks: Option A will throw an error if the JSON is invalid. Option C involves a UDF, which can be slower than built-in functions. Option D assumes valid json and uses the native notation which will error with invalid JSON data. Option E uses Regex which is not recommended and can have perfomance impact as well as not robust
NEW QUESTION # 181
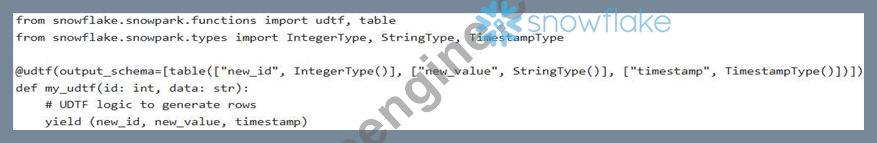
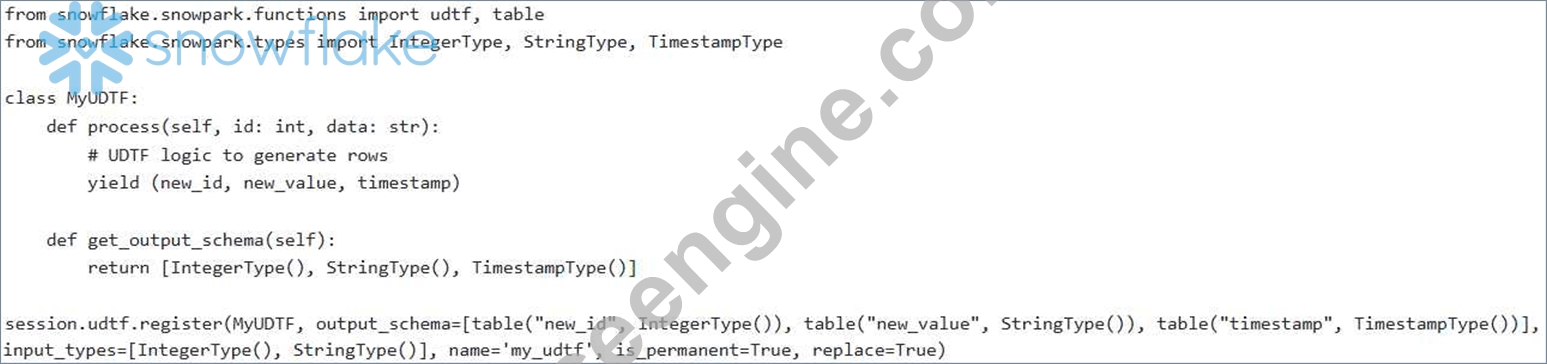
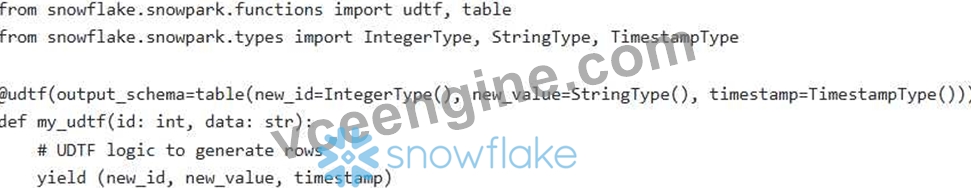
You have a Python function that performs complex data transformations, too intricate to express directly in Snowpark SQL. You want to register this as a User-Defined Table Function (UDTF) so that it can be used to expand rows in a Snowpark DataFrame. The UDTF takes two arguments: an ID (integer) and a string. It returns a table with three columns: (integer), (string), and 'timestamp' (timestamp). Which of the following code snippets correctly registers this UDTF, making it available for use within Snowpark?
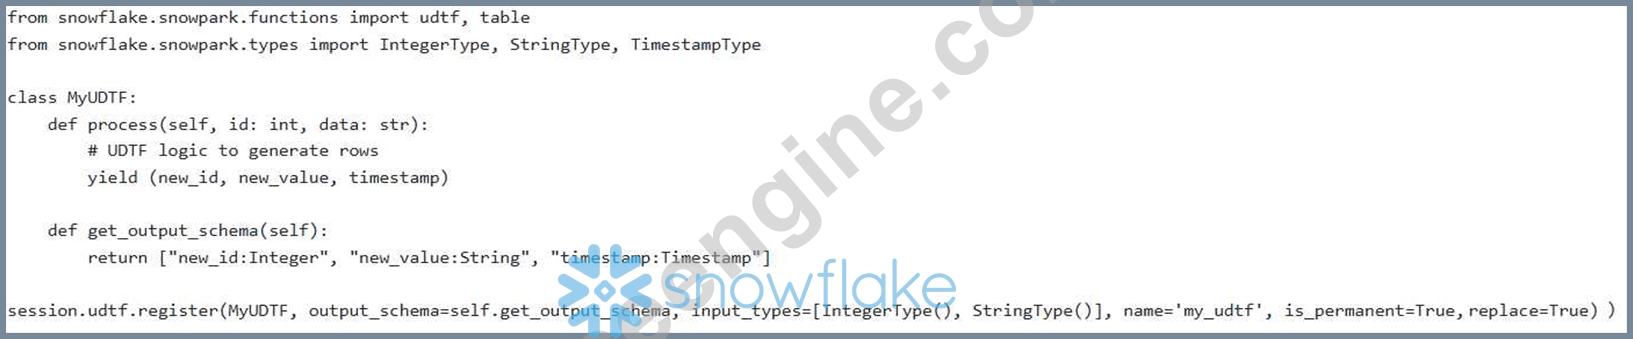
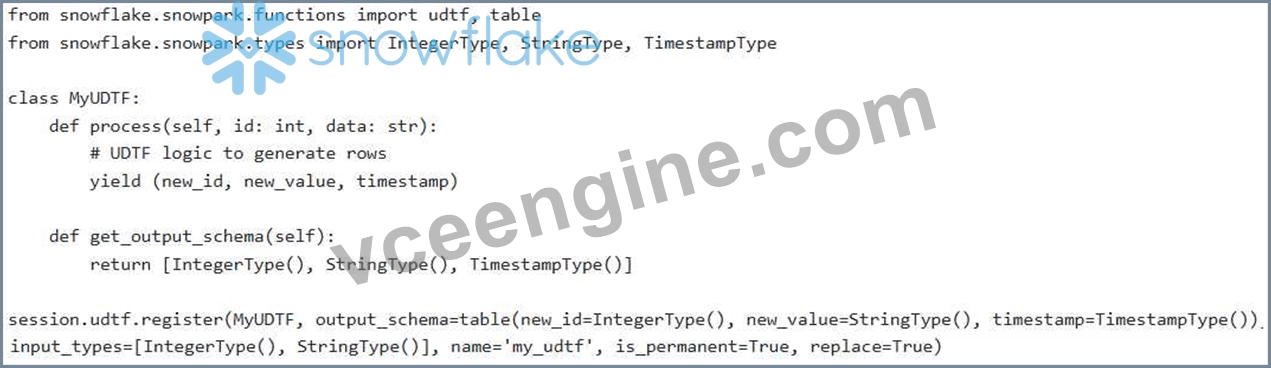
Answer: E
Explanation:
Option C provides the correct way to define and register UDTFs using the class-based approach in Snowpark. It defines the UDTF class with 'process' and methods. returns the schema using 'table' function correctly. Options A and B use the decorator approach, which is valid for simple UDTFs, but it's less flexible than the class-based approach, especially for managing complex state or schema. Option D uses the class-based approach but incorrectly defines the 'output_schema' when registering. Option E has an incorrect definition of return type.
NEW QUESTION # 182
You have a Snowpark application that processes sensor data from a large number of devices. You've implemented a scalar UDF in Python to calculate a complex statistical metric for each sensor reading. Initial tests show poor performance. Which of the following strategies would be MOST effective in improving the performance of this application, considering the nature of the computation and the data volume?
Answer: D
Explanation:
Vectorized UDFs process data in batches (vectors), significantly reducing the overhead associated with individual row processing, which is the primary bottleneck of scalar UDFs. While increasing warehouse size (C) might provide some improvement, it doesn't address the fundamental inefficiency of scalar processing. Java might be faster (A), but the biggest gain comes from vectorization. Caching (D) is useful for repeated calculations, but doesn't address the inherent UDF overhead if computations are unique. SQL (E) is good, but might not be possible due to the complexity.
NEW QUESTION # 183
You have developed a Snowpark application that processes a large volume of customer interaction data'. The application uses a vectorized UDF to classify the sentiment of text-based interactions. Initial tests show the application is performing slowly. Which of the following strategies would be MOST effective for optimizing the performance of sentiment analysis using a vectorized UDF?
Answer: C
Explanation:
Optimizing the vectorized UDF code itself offers the most direct and significant performance gains for sentiment analysis. By streamlining computations, reducing memory allocations, and avoiding unnecessary function calls within the UDF's vectorized function, the processing time for each batch of data can be substantially reduced. Mini-batching (B) is already implicit with vectorization with pandas series/dataframe. Increaseing Number of cores allocated to the virtual warehouse can provide some help but it depends on other factor also. Other oprions may not have impact
NEW QUESTION # 184
......
As far as our SPS-C01 study guide is concerned, the PDF version brings you much convenience with regard to the following advantage. The PDF version of our SPS-C01 learning materials contain demo where a part of questions selected from the entire version of our SPS-C01 Exam Quiz is contained. In this way, you have a general understanding of our SPS-C01 actual prep exam, which must be beneficial for your choice of your suitable exam files.
Reliable Exam SPS-C01 Pass4sure: https://www.vceengine.com/SPS-C01-vce-test-engine.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by VCEEngine: https://drive.google.com/open?id=1mdO_G1YhPPtQJjGi117BIqd3vbgmHnNN