What's more, part of that DumpsActual Databricks-Certified-Professional-Data-Engineer dumps now are free: https://drive.google.com/open?id=1TS486Dcdz7Itron9jH9c_5ict7f2z7WU
Will you feel that the product you have brought is not suitable for you? One trait of our Databricks-Certified-Professional-Data-Engineer exam prepare is that you can freely download a demo to have a try. Because there are excellent free trial services provided by our Databricks-Certified-Professional-Data-Engineer exam guides, our products will provide three demos that specially designed to help you pick the one you are satisfied. On the one hand, by the free trial services you can get close contact with our products, learn about the detailed information of our Databricks-Certified-Professional-Data-Engineer Study Materials, and know how to choose the different versions before you buy our products. On the other hand, using free trial downloading before purchasing, I can promise that you will have a good command of the function of our Databricks-Certified-Professional-Data-Engineer exam prepare. According to free trial downloading, you will know which version is more suitable for you in advance and have a better user experience.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Topic 2: Delta Lake | 20-25% | - Delta Lake fundamentals
|
| Topic 3: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Topic 4: Data Processing with Spark | 25-30% | - Python and SQL for data engineering
|
| Topic 5: Data Ingestion | 15-20% | - Streaming ingestion
|
>> Latest Databricks-Certified-Professional-Data-Engineer Exam Objectives <<
You will be able to experience the real exam scenario by practicing with Databricks Databricks-Certified-Professional-Data-Engineer practice test questions. As a result, you should be able to pass your Databricks Databricks-Certified-Professional-Data-Engineer Exam on the first try. Databricks Databricks-Certified-Professional-Data-Engineer desktop software can be installed on Windows-based PCs only. There is no requirement for an active internet connection.
NEW QUESTION # 175
A nightly job ingests data into a Delta Lake table using the following code: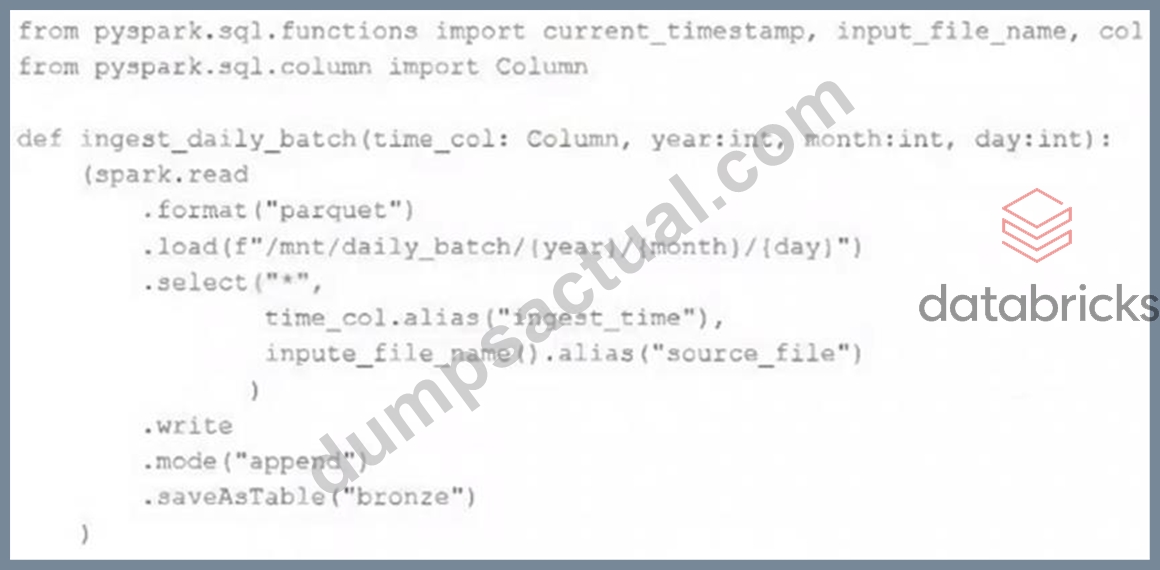
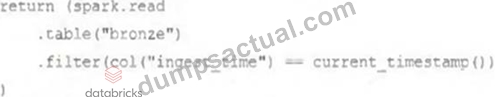
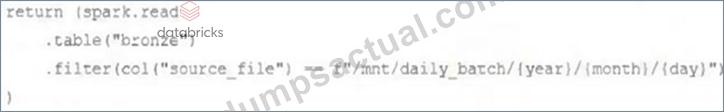
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
Answer: C
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 176
A Delta Lake table representing metadata about content from user has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE Based on the above schema, which column is a good candidate for partitioning the Delta Table?
Answer: D
Explanation:
Partitioning a Delta Lake table improves query performance by organizing data into partitions based on the values of a column. In the given schema, thedatecolumn is a good candidate for partitioning for several reasons:
* Time-Based Queries: If queries frequently filter or group by date, partitioning by thedatecolumn can significantly improve performance by limiting the amount of data scanned.
* Granularity: Thedatecolumn likely has a granularity that leads to a reasonable number of partitions (not too many and not too few). This balance is important for optimizing both read and write performance.
* Data Skew: Other columns likepost_idoruser_idmight lead to uneven partition sizes (data skew), which can negatively impact performance.
Partitioning bypost_timecould also be considered, but typicallydateis preferred due to its more manageable granularity.
References:
* Delta Lake Documentation on Table Partitioning: Optimizing Layout with Partitioning
NEW QUESTION # 177
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.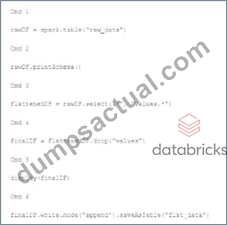
Which command should be removed from the notebook before scheduling it as a job?
Answer: B
Explanation:
Cmd 6 is the command that should be removed from the notebook before scheduling it as a job. This command is selecting all the columns from the finalDF dataframe and displaying them in the notebook. This is not necessary for the job, as the finalDF dataframe is already written to a table in Cmd 7. Displaying the dataframe in the notebook will only consume resources and time, and it will not affect the output of the job.
Therefore, Cmd 6 is redundant and should be removed.
The other commands are essential for the job, as they perform the following tasks:
* Cmd 1: Reads the raw_data table into a Spark dataframe called rawDF.
* Cmd 2: Prints the schema of the rawDF dataframe, which is useful for debugging and understanding the data structure.
* Cmd 3: Selects all the columns from the rawDF dataframe, as well as the nested columns from the values struct column, and creates a new dataframe called flattenedDF.
* Cmd 4: Drops the values column from the flattenedDF dataframe, as it is no longer needed after flattening, and creates a new dataframe called finalDF.
* Cmd 5: Explains the physical plan of the finalDF dataframe, which is useful for optimizing and tuning the performance of the job.
* Cmd 7: Writes the finalDF dataframe to a table called flat_data, using the append mode to add new data to the existing table.
NEW QUESTION # 178
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver) . The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
Answer: C
Explanation:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 179
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable.
Which approach will solve the problem with minimum overhead while preserving data integrity?
Answer: C
Explanation:
The Databricks documentation recommends applyInPandas() for complex per-group operations where maintaining internal state within each group is necessary. When using applyInPandas(), Spark provides all records for each grouping key as a Pandas DataFrame to the function, allowing efficient vectorized operations with local state management. This approach ensures high performance and scalability while maintaining logical isolation between groups. In contrast, SCALAR and SCALAR_ITER UDFs operate on individual rows or batches and cannot maintain inter-row state effectively. grouped_agg UDFs are limited to computing aggregates and do not support complex multi-row transformations. Therefore, applyInPandas() is the correct and Databricks-recommended solution for stateful per-group time-series computations.
NEW QUESTION # 180
......
There are totally three versions of Databricks-Certified-Professional-Data-Engineer practice materials which are the most suitable versions for you: PDF, Software and APP online versions. We promise ourselves and exam candidates to make these Databricks-Certified-Professional-Data-Engineer learning materials top notch. So if you are in a dark space, our Databricks-Certified-Professional-Data-Engineer Exam Questions can inspire you make great improvements. Just believe in our Databricks-Certified-Professional-Data-Engineer training guide and let us lead you to a brighter future!
Databricks-Certified-Professional-Data-Engineer Reliable Test Objectives: https://www.dumpsactual.com/Databricks-Certified-Professional-Data-Engineer-actualtests-dumps.html
BTW, DOWNLOAD part of DumpsActual Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1TS486Dcdz7Itron9jH9c_5ict7f2z7WU