Databricks-Certified-Data-Engineer-Professional certification has great effect in this field and may affect your career even future. Databricks-Certified-Data-Engineer-Professional real questions files are professional and high passing rate so that users can pass the exam at the first attempt. High quality and pass rate make us famous and growing faster and faster. Many candidates compliment that Databricks-Certified-Data-Engineer-Professional Study Guide materials are best assistant and useful for qualification exams, they have no need to purchase other training courses or books to study, and only by practicing our Databricks-Certified-Data-Engineer-Professional Databricks Certification exam braindumps several times before exam, they can pass exam in short time easily.
| Section | Weight | Objectives |
|---|---|---|
| Data Quality and Governance | 12% | - Data Lineage - Governance - Data Quality |
| Data Modeling and Storage | 20% | - File Formats - Data Modeling - Storage Optimization |
| Data Processing | 28% | - Structured Streaming - ETL Pipelines - Data Transformation - Spark SQL |
| Monitoring and Troubleshooting | 16% | - Performance Optimization - Monitoring - Troubleshooting |
| Databricks Lakehouse Platform | 24% | - Data Management - Delta Lake - Unity Catalog - Lakehouse Architecture |
>> Databricks-Certified-Data-Engineer-Professional Valid Dumps Files <<
Do you want to double your salary in a short time? Yes, it is not a dream. Our Databricks-Certified-Data-Engineer-Professional latest study guide can help you. IT field is becoming competitive; a Databricks certification can help you do that. If you get a certification with our Databricks-Certified-Data-Engineer-Professional latest study guide, maybe your career will change. A useful certification will bring you much outstanding advantage when you apply for any jobs about Databricks company or products. Just only dozens of money on Databricks-Certified-Data-Engineer-Professional Latest Study Guide will assist you 100% pass exam and 24-hours worm aid service.
NEW QUESTION # 104
A departing platform owner currently holds ownership of multiple catalogs and controls storage credentials and external locations. A data engineer has been asked to ensure continuity: transfer catalog ownership to the platform team group, delegate ongoing privilege management, and retain the ability to receive and share data via Delta Sharing. Which role must be in place to perform these actions across the metastore?
Answer: D
Explanation:
Metastore Admins have the highest administrative privileges within a Unity Catalog metastore.
They can transfer ownership of any Unity Catalog object, including catalogs, schemas, tables, storage credentials, and external locations. Metastore Admins are also required to manage Delta Sharing configurations such as creating or transferring shares and recipients.
Account Admins, by contrast, only create metastores and cannot change ownership or manage Delta Sharing objects. Workspace Admins have privileges limited to workspace-level management, not cross-metastore access.
NEW QUESTION # 105
Which Python variable contains a list of directories to be searched when trying to locate required modules?
Answer: C
Explanation:
sys. path is a built-in variable within the sys module. It contains a list of directories that the interpreter will search in for the required module.
NEW QUESTION # 106
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.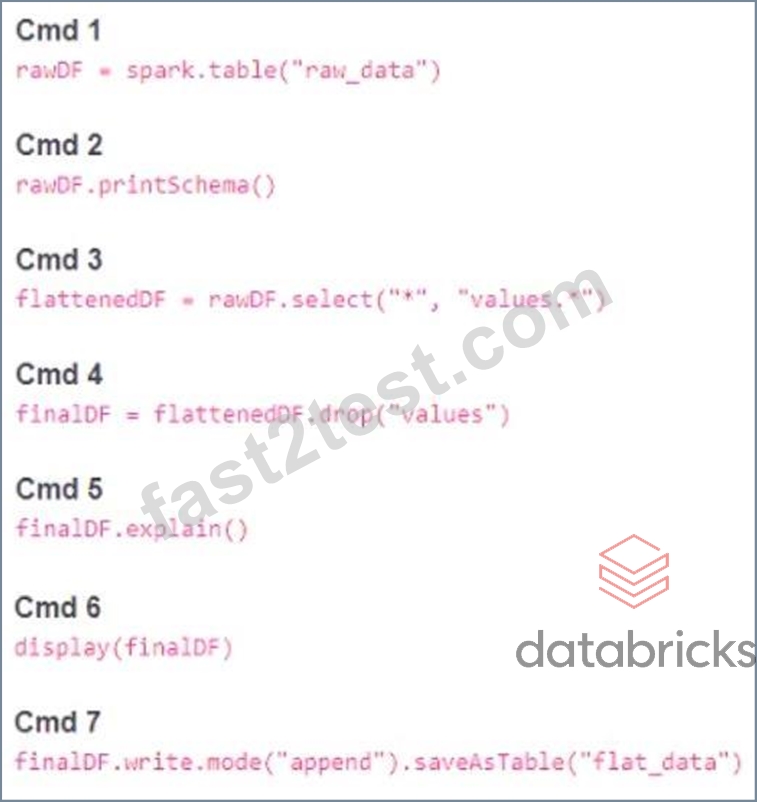
Which command should be removed from the notebook before scheduling it as a job?
Answer: C
Explanation:
When scheduling a Databricks notebook as a job, it's generally recommended to remove or modify commands that involve displaying output, such as using the display() function. Displaying data using display() is an interactive feature designed for exploration and visualization within the notebook interface and may not work well in a production job context.
The finalDF.explain() command, which provides the execution plan of the DataFrame transformations and actions, is often useful for debugging and optimizing queries. While it doesn't display interactive visualizations like display(), it can still be informative for understanding how Spark is executing the operations on your DataFrame.
NEW QUESTION # 107
A Delta Lake table was created with the below query: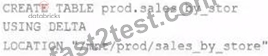
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
Answer: B
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly.
NEW QUESTION # 108
A data engineer is designing a Lakeflow Declarative Pipeline to process streaming order data.
The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id and amount are greater than zero. Invalid records should be dropped. Which Lakeflow Declarative Pipelines configurations implement this requirement using Python?
Answer: D
Explanation:
Lakeflow Declarative Pipelines (LDP), formerly Delta Live Tables (DLT), supports enforcing data quality using expectations. Expectations can either:
Track violations (expect) -> records that do not meet conditions are flagged but still included in the pipeline.
Drop violations (expect_or_drop) -> records that do not meet conditions are excluded from downstream tables.
Fail pipeline on violations (expect_or_fail) -> records that fail conditions stop the pipeline.
In this scenario, the requirement explicitly states that invalid records (where customer_id is null or amount < 0) must be dropped. According to the official documentation, the correct method is .expect_or_drop("expectation_name", "SQL_predicate") applied on the streaming input.
Option A is correct: It uses .expect_or_drop directly within the transformation chain for both rules, ensuring records that fail are removed before writing to the silver table.
Option B incorrectly uses @dlt.expect decorators, which only track violations but do not drop invalid rows.
Option C uses .expect, which also only flags rows, not drop them.
Option D uses @dlt.expect_or_drop decorator syntax, which is not supported in Python API; expect_or_drop must be applied as a method on the DataFrame, not as a decorator.
Therefore, the correct solution is Option A, which ensures compliance by enforcing data quality and dropping invalid rows programmatically during ingestion.
NEW QUESTION # 109
......
Three versions for Databricks-Certified-Data-Engineer-Professional test materials are available, and you can choose the most suitable one according to your own needs. Databricks-Certified-Data-Engineer-Professional PDF version is printable, and if you prefer to practice on paper, this version must be your taste. Databricks-Certified-Data-Engineer-Professional Soft test engine can stimulate the real exam environment, and you can know the procedures for the exam, and your confidence will be strengthened. Databricks-Certified-Data-Engineer-Professional Online Test engine supports all web browsers and it also supports Android and iOS etc. This version can give you a general review of what you have leant last time.
Databricks-Certified-Data-Engineer-Professional Practice Exam Online: https://www.fast2test.com/Databricks-Certified-Data-Engineer-Professional-premium-file.html