Außerdem sind jetzt einige Teile dieser Pass4Test Data-Engineer-Associate Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1w_Wv9Iioe27ZHwaLAmOJQopcsgHW6HMz
Vorm Kauf der Dumps zur Data-Engineer-Associate Zertifizierungsprüfung von Pass4Test können Sie unsere Demo kostenlos als Probe herunterladen.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion and Transformation | 34% | - Perform data ingestion
|
| Data Operations and Support | 22% | - Monitor data pipelines
|
| Data Security and Governance | 18% | - Ensure data encryption
|
| Data Store Management | 26% | - Manage data lifecycle
|
>> Data-Engineer-Associate Unterlage <<
Wenn Sie die Amazon Data-Engineer-Associate Zertifizierungsprüfung bestehen wollen, ist es ganz notwendig, die Schulungsunterlagen von Pass4Test zu wählen. Durch die Amazon Data-Engineer-Associate Zertifizierungsprüfung wird Ihr Job besser garantiert. In Ihrem späten Berufsleben, werden Ihre Fertigkeiten und Kenntnisse wenigstens international akzeptiert. Das ist der Grund dafür, warum viele Menschen Amazon Data-Engineer-Associate Zertifizierungsprüfung wählen. So ist diese Prüfung immer wichtiger geworden. Die Schulungsunterlagen zur Amazon Data-Engineer-Associate Zertifizierungsprüfung von Pass4Test, die von den erfahrungsreichen IT-Experten bearbeitet, wird Ihnen helfen, Ihren Wunsch zu erfüllen. Sie enthalten Prüfungsfragen und Antworten. Keine anderen Schulungsunterlagen sind Pass4Test vergleichbar. Sie brauchen auch nicht am Kurs teilzunehmen. Sie brauchen nur die Schulungsunterlagen zur Amazon Data-Engineer-Associate Zertifizierungsprüfung von Pass4Test in den Warenkorb hinzufügen, dann können Sie mit Hilfe von Pass4Test die Prüfung ganz einfach bestehen.
109. Frage
A company stores petabytes of data in thousands of Amazon S3 buckets in the S3 Standard storage class. The data supports analytics workloads that have unpredictable and variable data access patterns.
The company does not access some data for months. However, the company must be able to retrieve all data within milliseconds. The company needs to optimize S3 storage costs.
Which solution will meet these requirements with the LEAST operational overhead?
Antwort: D
Begründung:
S3 Intelligent-Tiering is a storage class that automatically moves objects between four access tiers based on the changing access patterns. The default access tier consists of two tiers: Frequent Access and Infrequent Access. Objects in the Frequent Access tier have the same performance and availability as S3 Standard, while objects in the Infrequent Access tier have the same performance and availability as S3 Standard-IA. S3 Intelligent-Tiering monitors the access patterns of each object and moves them between the tiers accordingly, without any operational overhead or retrieval fees. This solution can optimize S3 storage costs for data with unpredictable and variable access patterns, while ensuring millisecond latency for data retrieval. The other solutions are not optimal or relevant for this requirement. Using S3 Storage Lens standard metrics and activity metrics can provide insights into the storage usage and access patterns, but they do not automate the data movement between storage classes. Creating S3 Lifecycle policies for the S3 buckets can move objects to more cost-optimized storage classes, but they require manual configuration and maintenance, and they may incur retrieval fees for data that is accessed unexpectedly. Activating the Deep Archive Access tier for S3 Intelligent-Tiering can further reduce the storage costs for data that is rarely accessed, but it also increases the retrieval time to 12 hours, which does not meet the requirement of millisecond latency. References:
S3 Intelligent-Tiering
S3 Storage Lens
S3 Lifecycle policies
[AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide]
110. Frage
A company has a production AWS account that runs company workloads. The company's security team created a security AWS account to store and analyze security logs from the production AWS account. The security logs in the production AWS account are stored in Amazon CloudWatch Logs.
The company needs to use Amazon Kinesis Data Streams to deliver the security logs to the security AWS account.
Which solution will meet these requirements?
Antwort: D
Begründung:
Amazon Kinesis Data Streams is a service that enables you to collect, process, and analyze real-time streaming data. You can use Kinesis Data Streams to ingest data from various sources, such as Amazon CloudWatch Logs, and deliver it to different destinations, such as Amazon S3 or Amazon Redshift. To use Kinesis Data Streams to deliver the security logs from the production AWS account to the security AWS account, you need to create a destination data stream in the security AWS account. This data stream will receive the log data from the CloudWatch Logs service in the production AWS account. To enable this cross- account data delivery, you need to create an IAM role and a trust policy in the security AWS account. The IAM role defines the permissions that the CloudWatch Logs service needs to put data into the destination data stream. The trust policy allows the production AWS account to assume the IAM role. Finally, you need to create a subscription filter in the production AWS account. A subscription filter defines the pattern to match log events and the destination to send the matching events. In this case, the destination is the destination data stream in the security AWS account. This solution meets the requirements of using Kinesis Data Streams to deliver the security logs to the security AWS account. The other options are either not possible or not optimal.
You cannot create a destination data stream in the production AWS account, as this would not deliver the data to the security AWS account. You cannot create a subscription filter in the security AWS account, as this would not capture the log events from the production AWS account. References:
* Using Amazon Kinesis Data Streams with Amazon CloudWatch Logs
* AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 3: Data Ingestion and Transformation, Section 3.3: Amazon Kinesis Data Streams
111. Frage
A company receives call logs as Amazon S3 objects that contain sensitive customer information. The company must protect the S3 objects by using encryption. The company must also use encryption keys that only specific employees can access.
Which solution will meet these requirements with the LEAST effort?
Antwort: D
Begründung:
Option C is the best solution to meet the requirements with the least effort because server-side encryption with AWS KMS keys (SSE-KMS) is a feature that allows you to encrypt data at rest in Amazon S3 using keys managed by AWS Key Management Service (AWS KMS). AWS KMS is a fully managed service that enables you to create and manage encryption keys for your AWS services and applications. AWS KMS also allows you to define granular access policies for your keys, such as who can use them to encrypt and decrypt data, and under what conditions. By using SSE-KMS, you canprotect your S3 objects by using encryption keys that only specific employees can access, without having to manage the encryption and decryption process yourself.
Option A is not a good solution because it involves using AWS CloudHSM, which is a service that provides hardware security modules (HSMs) in the AWS Cloud. AWS CloudHSM allows you to generate and use your own encryption keys on dedicated hardware that is compliant with various standards and regulations.
However, AWS CloudHSM is not a fully managed service and requires more effort to set up and maintain than AWS KMS. Moreover, AWS CloudHSM does not integrate with Amazon S3, so you have to configure the process that writes to S3 to make calls to CloudHSM to encrypt and decrypt the objects, which adds complexity and latency to the data protection process.
Option B is not a good solution because it involves using server-side encryption with customer-provided keys (SSE-C), which is a feature that allows you to encrypt data at rest in Amazon S3 using keys that you provide and manage yourself. SSE-C requires you to send your encryption key along with each request to upload or retrieve an object. However, SSE-C does not provide any mechanism to restrict access to the keys that encrypt the objects, so you have to implement your own key management and access control system, which adds more effort and risk to the data protection process.
Option D is not a good solution because it involves using server-side encryption with Amazon S3 managed keys (SSE-S3), which is a feature that allows you to encrypt data at rest in Amazon S3 using keys that are managed by Amazon S3. SSE-S3 automatically encrypts and decrypts your objects as they are uploaded and downloaded from S3. However, SSE-S3 does not allow you to control who can access the encryption keys or under what conditions. SSE-S3 uses a single encryption key for each S3 bucket, which is shared by all users who have access to the bucket. This means that you cannot restrict access to the keys that encrypt the objects by specific employees, which does not meet the requirements.
References:
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide
Protecting Data Using Server-Side Encryption with AWS KMS-Managed Encryption Keys (SSE-KMS)
- Amazon Simple Storage Service
What is AWS Key Management Service? - AWS Key Management Service
What is AWS CloudHSM? - AWS CloudHSM
Protecting Data Using Server-Side Encryption with Customer-Provided Encryption Keys (SSE-C) - Amazon Simple Storage Service Protecting Data Using Server-Side Encryption with Amazon S3-Managed Encryption Keys (SSE-S3) - Amazon Simple Storage Service
112. Frage
A data engineer is implementing model governance for machine learning (ML) workflows on AWS. The data engineer needs a solution that can track the complete lifecycle of the ML models, including data preparation, model training, and deployment stages. The solution must ensure reproducibility and audit compliance.
Antwort: B
Begründung:
Amazon SageMaker ML Lineage Tracking provides a unified mechanism to automatically capture and track the lineage of ML artifacts (datasets, jobs, and models). It supports auditability, reproducibility, and compliance by maintaining metadata for every stage of the ML lifecycle.
"Use Amazon SageMaker Lineage Tracking to automatically record and track the lineage of data, training jobs, models, and endpoints to ensure auditability and reproducibility."
- Ace the AWS Certified Data Engineer - Associate Certification - version 2 - apple.pdf
113. Frage
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?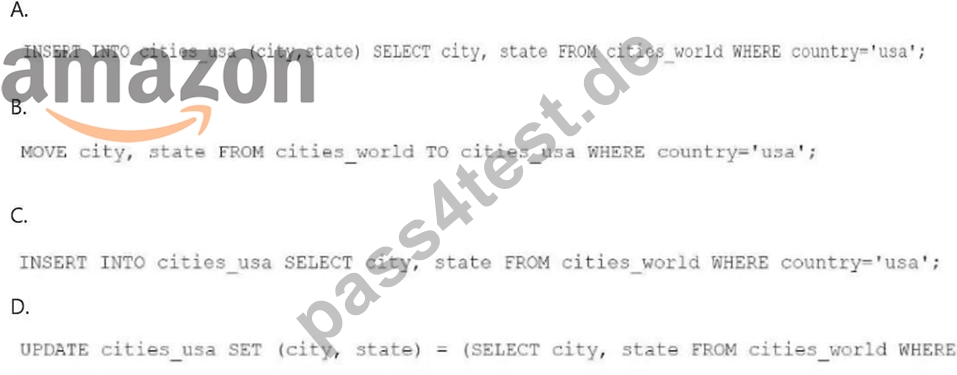
Antwort: D
Begründung:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is 'usa'. The correct SQL syntax would be:
Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country='usa';This statement inserts only the cities and states where the country column has a value of 'usa' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
References:
Amazon Athena SQL Reference
Creating Tables in Athena
114. Frage
......
Um Sie beim Kauf der Amazon Data-Engineer-Associate Prüfungssoftware beruhigt zu lassen, wenden wir die gesicherteste Zahlungsmittel an. Paypal ist das größte internationale Zahlungssystem. Und wir bewahren sorgfältig Ihre persönliche Informationen. Wenn Sie Fragen über die Amazon Data-Engineer-Associate Prüfungsunterlagen oder Interesse an anderen Prüfungssoftwaren haben, könnten Sie diret mit uns online kontaktieren oder uns E-Mail schicken. Wir tun unser Bestes, um Ihnen bei der Amazon Data-Engineer-Associate Prüfung zu helfen.
Data-Engineer-Associate Lerntipps: https://www.pass4test.de/Data-Engineer-Associate.html
P.S. Kostenlose und neue Data-Engineer-Associate Prüfungsfragen sind auf Google Drive freigegeben von Pass4Test verfügbar: https://drive.google.com/open?id=1w_Wv9Iioe27ZHwaLAmOJQopcsgHW6HMz