Latest Certified-Data-Engineer-Professional Study Guide, Certified-Data-Engineer-Professional Prep Guide

BTW, DOWNLOAD part of PracticeTorrent Certified-Data-Engineer-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1Szv-WKIbZ5aeI3KDCkJOWmqloAx5yaQv
Taking practice tests is particularly helpful for those who have exam anxiety. Our practice tests are user-friendly and customizable. Windows support the desktop practice test software. Our web-based practice test is compatible with all browsers and operating systems. The web-based Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice test is similar to the desktop-based exam and can be taken on any browser without needing to download separate software.
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 2: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
| Topic 3: Cost & Performance Optimisation | - Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
|
| Topic 4: Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
|
| Topic 5: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 6: Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 7: Ensuring Data Security and Compliance | - Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Apply anonymization and pseudonymization techniques
- 3. Use ACLs to secure workspace objects and enforce least privilege
- Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
|
| Topic 8: Data Modelling | - Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Optimize data layout using Liquid Clustering
- 3. Design and implement scalable data models using Delta Lake
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 9: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Use control flow operators in pipeline components
- 2. Develop unit and integration tests for data processing code
- 3. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 4. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 5. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 6. Compare streaming tables and materialized views
- 7. Use APPLY CHANGES APIs for change data capture
- 8. Configure environments, dependencies, memory, and retry behavior
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
| Topic 10: Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Query Profiler and Spark UI to monitor workloads
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
|
>> Latest Certified-Data-Engineer-Professional Study Guide <<
Latest Certified-Data-Engineer-Professional Study Guide | Amazing Pass Rate For Databricks Certified-Data-Engineer-Professional | Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional
PracticeTorrent are supposed to help you pass the Certified-Data-Engineer-Professional exam smoothly. Don't worry about channels to the best Certified-Data-Engineer-Professional study materials so many exam candidates admire our generosity of offering help for them. Up to now, no one has ever challenged our leading position of this area. The existence of our Certified-Data-Engineer-Professional learning guide is regarded as in favor of your efficiency of passing the exam. Over time, our company is becoming increasingly obvious degree of helping the exam candidates with passing rate up to 98 to 100 percent. All our behaviors are aiming squarely at improving your chance of success on Certified-Data-Engineer-Professional Exam.
Databricks Certified Data Engineer Professional Sample Questions (Q50-Q55):
NEW QUESTION # 50
Two of the most common data locations on Databricks are the DBFS root storage and external object storage mounted with dbutils.fs.mount().
Which of the following statements is correct?
- A. Neither the DBFS root nor mounted storage can be accessed when using %sh in a Databricks notebook.
- B. The DBFS root is the most secure location to store data, because mounted storage volumes must have full public read and write permissions.
- C. DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems.
- D. By default, both the DBFS root and mounted data sources are only accessible to workspace administrators.
- E. The DBFS root stores files in ephemeral block volumes attached to the driver, while mounted directories will always persist saved data to external storage between sessions.
Answer: C
Explanation:
DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems. DBFS is not a physical file system, but a layer over the object storage that provides a unified view of data across different data sources. By default, the DBFS root is accessible to all users in the workspace, and the access to mounted data sources depends on the permissions of the storage account or container. Mounted storage volumes do not need to have full public read and write permissions, but they do require a valid connection string or access key to be provided when mounting. Both the DBFS root and mounted storage can be accessed when using %sh in a Databricks notebook, as long as the cluster has FUSE enabled. The DBFS root does not store files in ephemeral block volumes attached to the driver, but in the object storage associated with the workspace. Mounted directories will persist saved data to external storage between sessions, unless they are unmounted or deleted.
NEW QUESTION # 51
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
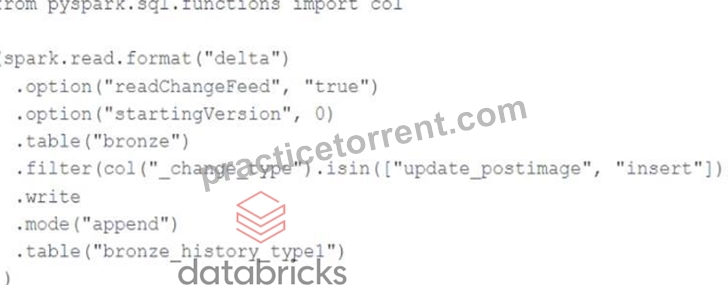
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
- B. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- C. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
- D. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- E. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
Answer: E
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 52
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame named preds with the schema "customer_id LONG, predictions DOUBLE, date DATE".
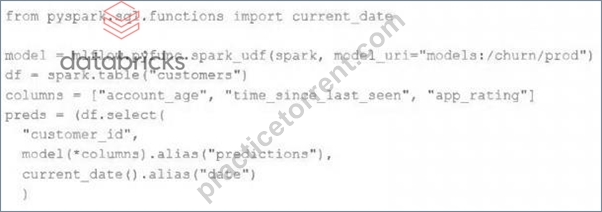
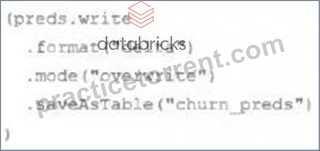
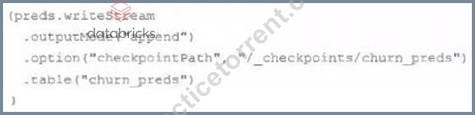
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
- A.
- B. preds.write.format("delta").save("/preds/churn_preds")
- C.
- D. preds.write.mode("append").saveAsTable("churn_preds")
- E.
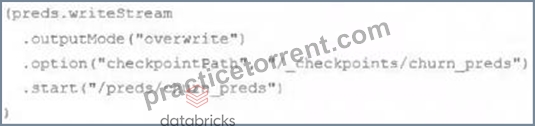
Answer: D
NEW QUESTION # 53
A data engineer is brining an existing production Databricks job under asset bundle management and wants to ensure that:
- The job's current configuration is captured as YAML, and all
referenced files are included in their bundle project.
- Future changes to the bundle's YAML will update the existing job in-
place (not create a new job)
How should the data engineer successfully move the production job under asset bundle management?
- A. Run databricks bundle generate job --existing-job-id to generate the YAML and download referenced files. Then, run Databricks bundle deployment, bind to link the bundle's job resource to the existing job in Databricks.
- B. Export the job definition as JSON, convert it to YAML, and place it in your bundle. Then, run Databricks bundle deploy to update the existing job.
- C. Run Databricks bundle generate job --existing-job-id to generate the YAML and download referenced files. Then, run Databricks bundle deploy to deploy the bundle, which will always update the existing job automatically.
- D. Manually create the YAML configuration for the job in your bundle project, ensuring all settings match the existing job. Then, run Databricks bundle deploy the bundle, which will update the existing job in your workspace.
Answer: A
Explanation:
Generating the bundle from the existing job captures the full job configuration as YAML and pulls in all referenced files into the bundle project. Binding the generated job resource to the existing Databricks job establishes a persistent link, ensuring that future bundle deployments update the same production job in place rather than creating a new one.
NEW QUESTION # 54
A data engineer is using the AUTO CDC API in Lakeflow Spark Declarative Pipeline to propagate deletions from a source table (orders_source) to a target table (orders_target). The source has Change Data Feed (CDF) enabled, but some delete events arrive out of order due to upstream delays. How does the AUTO CDC API internally ensure deletions are applied correctly despite out-of-order events?
- A. It runs VACUUM on the target table to purge conflicting records.
- B. It ignores deletions if they arrive after updates for the same key.
- C. It uses sequence_by to order events and retains tombstones for deleted rows until older sequences are processed.
- D. It manually sorts incoming events by timestamp before applying changes.
Answer: C
Explanation:
AUTO CDC uses the sequence_by column to deterministically order change events for each key.
Delete operations create tombstones that are retained until all earlier sequence values have been processed, ensuring that out-of-order delete events are still applied correctly and consistently in the target table.
NEW QUESTION # 55
......
PracticeTorrent have the obligation to ensure your comfortable learning if you have spent money on our Certified-Data-Engineer-Professional study materials. We do not have hot lines. The pass rate of our Certified-Data-Engineer-Professional is as high as more then 98%. And you can enjoy our considerable service on Certified-Data-Engineer-Professional exam questions. So you are advised to send your emails to our email address. In case you send it to others' email inbox, please check the address carefully before. The after-sales service of website can stand the test of practice. Once you trust our Certified-Data-Engineer-Professional Exam Torrent, you also can enjoy such good service.
Certified-Data-Engineer-Professional Prep Guide: https://www.practicetorrent.com/Certified-Data-Engineer-Professional-practice-exam-torrent.html
- Certified-Data-Engineer-Professional Test Answers 🛹 Latest Certified-Data-Engineer-Professional Braindumps Sheet 🛃 Dump Certified-Data-Engineer-Professional Collection 🕕 Simply search for ➠ Certified-Data-Engineer-Professional 🠰 for free download on ✔ www.examcollectionpass.com ️✔️ 👇Practice Certified-Data-Engineer-Professional Mock
- Certified-Data-Engineer-Professional Pass4sure Dumps Pdf ✊ Certified-Data-Engineer-Professional Exam Study Guide 🪐 Latest Certified-Data-Engineer-Professional Braindumps Sheet 📓 ▷ www.pdfvce.com ◁ is best website to obtain ⏩ Certified-Data-Engineer-Professional ⏪ for free download ⏰New Certified-Data-Engineer-Professional Test Materials
- Certified-Data-Engineer-Professional Certification Questions 🟢 Sample Certified-Data-Engineer-Professional Test Online 🧓 New Certified-Data-Engineer-Professional Test Materials 🏍 Download [ Certified-Data-Engineer-Professional ] for free by simply searching on ➥ www.verifieddumps.com 🡄 🧟Certified-Data-Engineer-Professional Lead2pass Review
- Certified-Data-Engineer-Professional valid training questions - Certified-Data-Engineer-Professional updated practice vce - Certified-Data-Engineer-Professional exam cram test ✊ Easily obtain free download of ( Certified-Data-Engineer-Professional ) by searching on ⏩ www.pdfvce.com ⏪ 🧼Certified-Data-Engineer-Professional Exam Study Guide
- Exam Certified-Data-Engineer-Professional Prep 📽 New Soft Certified-Data-Engineer-Professional Simulations 🥏 Valid Exam Certified-Data-Engineer-Professional Blueprint 🚨 Search for ➥ Certified-Data-Engineer-Professional 🡄 and download exam materials for free through 《 www.vce4dumps.com 》 🖌Exam Certified-Data-Engineer-Professional Prep
- Free PDF 2026 Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Newest Latest Study Guide 🤒 Download ➤ Certified-Data-Engineer-Professional ⮘ for free by simply entering ➥ www.pdfvce.com 🡄 website 😬Certified-Data-Engineer-Professional Reliable Test Materials
- 2026 Databricks Professional Certified-Data-Engineer-Professional: Latest Databricks Certified Data Engineer Professional Study Guide ↩ Simply search for ➠ Certified-Data-Engineer-Professional 🠰 for free download on ▶ www.prepawayexam.com ◀ 🐏Certified-Data-Engineer-Professional Exam Study Guide
- Free PDF 2026 Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Newest Latest Study Guide 😅 Open website ▷ www.pdfvce.com ◁ and search for “ Certified-Data-Engineer-Professional ” for free download 🧅New Soft Certified-Data-Engineer-Professional Simulations
- Get Updated Latest Certified-Data-Engineer-Professional Study Guide - All in www.verifieddumps.com 🖖 Copy URL ⮆ www.verifieddumps.com ⮄ open and search for 「 Certified-Data-Engineer-Professional 」 to download for free ⛷Certified-Data-Engineer-Professional Practice Online
- Want to Get Databricks Certified-Data-Engineer-Professional Certified? Polish Your Abilities and Make it Easy 🐞 Search on ➥ www.pdfvce.com 🡄 for ⇛ Certified-Data-Engineer-Professional ⇚ to obtain exam materials for free download 🌳New Certified-Data-Engineer-Professional Test Materials
- Certified-Data-Engineer-Professional Practice Exam Online 🚀 Excellect Certified-Data-Engineer-Professional Pass Rate 🤧 Certified-Data-Engineer-Professional Exam Study Guide 🔖 Easily obtain free download of ⏩ Certified-Data-Engineer-Professional ⏪ by searching on [ www.vce4dumps.com ] 🍜Certified-Data-Engineer-Professional Practice Online
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free & New Certified-Data-Engineer-Professional dumps are available on Google Drive shared by PracticeTorrent: https://drive.google.com/open?id=1Szv-WKIbZ5aeI3KDCkJOWmqloAx5yaQv