さらに、Jpshiken SPS-C01ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1S4NDvMNjaTp5_TuJc5l-QDor04O3qJap
常々、時間とお金ばかり効果がないです。正しい方法は大切です。我々Jpshikenは一番効果的な方法を探してあなたにSnowflakeのSPS-C01試験に合格させます。弊社のSnowflakeのSPS-C01ソフトを購入するのを決めるとき、我々は各方面であなたに保障を提供します。購入した前の無料の試み、購入するときのお支払いへの保障、購入した一年間の無料更新SnowflakeのSPS-C01試験に失敗した全額での返金…これらは我々のお客様への承諾です。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformations and Operations | 35% | - User-defined logic
|
| Topic 2: Snowpark API and Development | 30% | - Multi-language support
|
| Topic 3: Performance and Best Practices | 10% | - Security and governance
|
| Topic 4: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
IT職員のあなたは毎月毎月のあまり少ない給料を持っていますが、暇の時間でひたすら楽しむんでいいですか。Snowflake SPS-C01試験認定書はIT職員野給料増加と仕事の昇進にとって、大切なものです。それで、我々社の無料のSnowflake SPS-C01デモを参考して、あなたに相応しい問題集を入手します。暇の時間を利用して勉強します。努力すれば報われますなので、Snowflake SPS-C01資格認定を取得して自分の生活状況を改善できます。
質問 # 111
You have a Snowpark Python application that reads data from a Snowflake table named 'SALES DATA', performs several transformations using DataFrames, and then writes the results back to a new table named 'AGGREGATED SALES'. The application runs successfully, but you notice that the write operation to 'AGGREGATED SALES' is consistently slow. After examining the query profile, you observe significant skew in the data being written, causing some worker nodes to be overloaded. Which of the following techniques could you use within your Snowpark application to mitigate the data skew and improve the write performance to 'AGGREGATED SALES'?
正解:B、C
解説:
Both options B and D address data skew directly. Option B, , attempts to redistribute data evenly, which can alleviate skew if the repartitioning strategy is effective (e.g., using a hash function). Option D, using a UDF and 'repartitionByRange' , allows for more sophisticated custom partitioning based on the skew key, potentially achieving a more balanced distribution. Increasing warehouse size (A) might provide more resources, but it doesn't directly address the skew. Sorting (C) can exacerbate skew by concentrating similar values on single nodes. Clustering (E) improves read performance after the data is written, but does not improve the write performance itself. Therefore, B and D are the best choices to reduce skew during the write operation.
質問 # 112
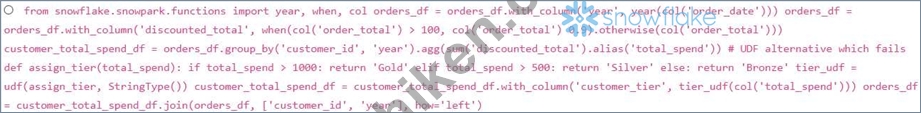
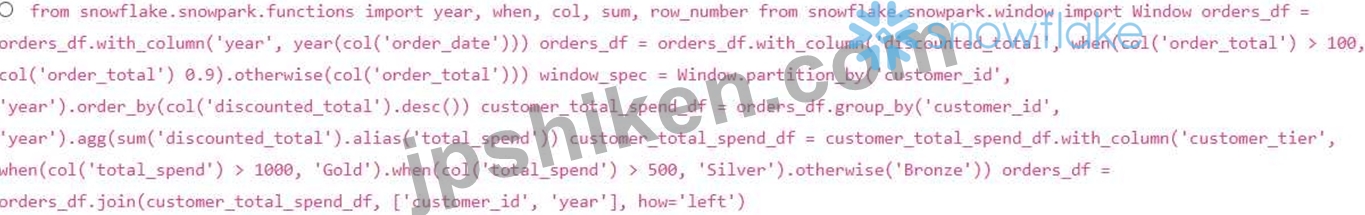
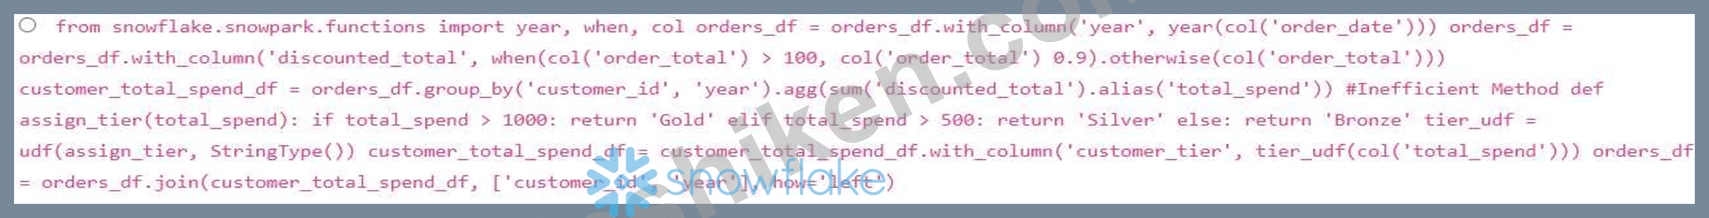
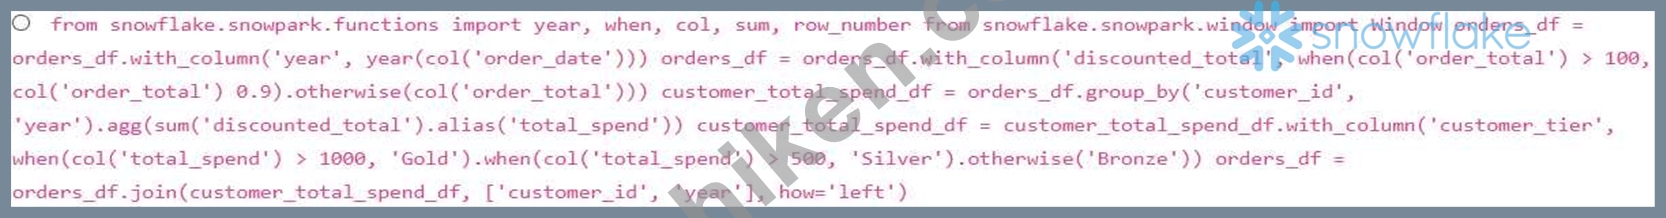
You have a Snowpark DataFrame named 'orders_df with columns 'order_id', 'customer_id', 'order_date', and 'order_total'. You need to perform the following data enrichment steps using Snowpark for Python: 1. Calculate the 'year' from the 'order_date' column. 2. Calculate the 'discounted_total' by applying a discount of 10% if the 'order_total' is greater than $100, otherwise, no discount. 3. Create a new column 'customer_tier' based on the total spend per customer for each year. Customers with total spend greater than $1000 are 'Gold', between $500 and $1000 are 'Silver', and below $500 are 'Bronze'. Which of the following code snippets correctly implements these data enrichment steps using Snowpark (Assume the existence of a customer total spend df DataFrame).

正解:E
解説:
Option B is the most efficient and correct. It calculates 'year' and 'discounted_total' using built-in functions. It then groups by 'customer_id' and 'year' to calculate 'total_spend'. Critically, it then assigns the 'customer_tier' using a series of 'when' statements directly within Snowpark, avoiding the performance overhead of a UDE Finally, it joins the customer tier information back to the original 'orders df. Option A implements Customer Tier calculation using UDF, Option C introduces Windowing without need. Options D, E are incomplete.
質問 # 113
You have a CSV file stored in a Snowflake stage named 'my_stage/data.csv'. The file contains customer data, including 'customer id' (INT), 'first_name' (VARCHAR), 'last_name' (VARCHAR), and 'email' (VARCHAR). You want to create a Snowpark DataFrame representing this data, explicitly defining the schema for improved type safety and performance. Which of the following code snippets is the MOST efficient and correct way to create the DataFrame with the specified schema, assuming you have a valid Snowpark session object named 'session'?





正解:E
解説:
Option A is the most efficient and correct. It defines the schema using 'StructType' and and applies it during the DataFrame creation using 'session.read.schema(schema).csv(...)'. This avoids unnecessary type casting after DataFrame creation. Option B performs type casting after DataFrame creation, which is less efficient. Option C is similar to A, and can be accepted, but defining nullable is not important. Option D uses the option argument in wrong way. Option E assumes column names are uppercase which might not be correct.
質問 # 114
A data engineering team wants to create a Snowpark stored procedure that takes a VARIANT column from a Snowflake table, parses a specific JSON element within each row, and returns a new DataFrame with the extracted data as a STRING column. The JSON structure is consistent across all rows. What is the MOST efficient and type-safe way to implement this, considering the need for performance and maintainability?
正解:B
解説:
The most efficient and type-safe approach is Option E. Using 'get' function on the VARIANT column to extract the JSON element, use the 'as_varchar' function to cast the VARIANT value to a String value, and register the stored procedure with explicit 'return_type' and schema definition for enhanced type safety. Snowpark's 'get' function provides optimized JSON parsing capabilities. Explicit casting using 'as_varchar' ensures that the extracted data is properly converted to a string. Registering the stored procedure with and a schema definition enforces data type safety at the interface level, preventing potential runtime errors and improving maintainability. Options A and D are less efficient or may lead to runtime errors. Option B is less explicit and more error prone.
質問 # 115
A Snowpark developer is using to create a Snowpark session. They want to ensure that the session uses a specific role and warehouse, but only if those parameters are not already defined in the Snowflake CLI configuration. Which of the following code snippets correctly implements this behavior?





正解:A
解説:
Option D offers a concise method where role and warehouse specified in the 'Session.builder' are only used if they aren't already defined in the environment or Snowflake CLI configurations. Snowflake gives precedence to the environment over the code when using the session builder. Options A does not take into account how Session.builder.configs would work in order to read the current CLI configurations. Option B overwrites even though the question state that if these parameters are already defined in Snowflake CLI configurations they should NOT be changed. Option C does not have complete Code. Option E is overly complicated.
質問 # 116
......
私たちのSPS-C01試験参考書を利用し、SPS-C01試験に合格できます。おそらくあなたは私たちのSPS-C01試験参考書を信じられないでしょう。でも、あなたはSPS-C01試験参考書を買ったお客様のコメントを見ると、すぐ信じるようになります。あなたは心配する必要がないです。早くSPS-C01試験参考書を買いましょう!
SPS-C01オンライン試験: https://www.jpshiken.com/SPS-C01_shiken.html
ちなみに、Jpshiken SPS-C01の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1S4NDvMNjaTp5_TuJc5l-QDor04O3qJap