BTW, DOWNLOAD part of Dumpleader Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=11pfEZS88vSPOs1ut_qE-VB05B5CHH-1j
Dumpleader is a specialized IT certification exam training website which provide you the targeted exercises and current exams. We focus on the popular Databricks Certification Databricks-Certified-Professional-Data-Engineer Exam and has studied out the latest training programs about Databricks certification Databricks-Certified-Professional-Data-Engineer exam, which can meet the needs of many people. Databricks Databricks-Certified-Professional-Data-Engineer certification is a reference of many well-known IT companies to hire IT employee. So this certification exam is very popular now. Dumpleader is also recognized and relied by many people. Dumpleader can help a lot of people achieve their dream. If you choose Dumpleader, but you do not successfully pass the examination, Dumpleader will give you a full refund.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion | 15-20% | - Batch ingestion methods
|
| Topic 2: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Topic 3: Delta Lake | 20-25% | - Delta Lake operations
|
| Topic 4: Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
|
| Topic 5: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
>> Valid Databricks-Certified-Professional-Data-Engineer Braindumps <<
There are three different versions of our Databricks-Certified-Professional-Data-Engineer exam questions to meet customers' needs you can choose the version that is suitable for you to study. If you buy our Databricks-Certified-Professional-Data-Engineer test torrent, you will have the opportunity to make good use of your scattered time to learn. If you choose our Databricks-Certified-Professional-Data-Engineer study torrent, you can make the most of your free time. So using our Databricks-Certified-Professional-Data-Engineer Exam Prep will help customers make good use of their fragmentation time to study and improve their efficiency of learning. It will be easier for you to pass your Databricks-Certified-Professional-Data-Engineer exam and get your certification in a short time.
NEW QUESTION # 45
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on Task A.
If task A fails during a scheduled run, which statement describes the results of this run?
Answer: C
Explanation:
When a Databricks job runs multiple tasks with dependencies, the tasks are executed in a dependency graph.
If a task fails, the downstream tasks that depend on it are skipped and marked as Upstream failed. However, the failed task may have already committed some changes to the Lakehouse before the failure occurred, and those changes are not rolled back automatically. Therefore, the job run may result in a partial update of the Lakehouse. To avoid this, you can use the transactional writes feature of Delta Lake to ensure that the changes are only committed when the entire job run succeeds. Alternatively, you can use the Run if condition to configure tasks to run even when some or all of their dependencies have failed, allowing your job to recover from failures and continue running. References:
* transactional writes: https://docs.databricks.com/delta/delta-intro.html#transactional-writes
* Run if: https://docs.databricks.com/en/workflows/jobs/conditional-tasks.html
NEW QUESTION # 46
A data engineer has configured their Databricks Asset Bundle with multiple targets in databricks.yml and deployed it to the production workspace. Now, to validate the deployment, they need to invoke a job named my_project_job specifically within the prod target context. Assuming the job is already deployed, they need to trigger its execution while ensuring the target-specific configuration is respected.
Which command will trigger the job execution?
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks Asset Bundles (DABs) enable declarative configuration and deployment of Databricks resources such as jobs, pipelines, and dashboards across multiple environments.
Once deployed, jobs can be executed in a specific target context using the databricks bundle run command, which ensures all environment-specific configurations from the bundle definition (such as parameters, cluster settings, and workspace URLs) are respected.
The -t flag specifies the target environment (e.g., dev, staging, or prod). This ensures that the execution runs with the correct configuration defined under that target in databricks.yml.
Other options (A, B, and C) are invalid because they reference deprecated or incorrect command syntax that doesn't integrate with bundle targets. Therefore, D is the correct and verified answer.
NEW QUESTION # 47
A data engineer is designing an append-only pipeline that needs to handle both batch and streaming data in Delta Lake. The team wants to ensure that the streaming component can efficiently track which data has already been processed.
Which configuration should be set to enable this?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
When working with Delta Lake streaming ingestion, checkpointing is critical for maintaining fault tolerance and ensuring exactly-once data processing semantics.
The checkpointLocation parameter defines the directory where Spark Structured Streaming stores progress information, offsets, and metadata. This allows the engine to resume processing from the last committed offset without reprocessing previously ingested data.
Without checkpointing, each stream restart would reprocess all data, leading to duplicates. Parameters like partitionBy or schema options (mergeSchema / overwriteSchema) affect table structure, not data lineage tracking. Therefore, the correct and required configuration for efficient streaming state management is checkpointLocation.
NEW QUESTION # 48
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should havefive workers,one driverof type i3.xlarge, and should use the '14.3.x-scala2.12' runtime.
Which command should the data engineer use?
Answer: C
Explanation:
Comprehensive and Detailed In-Depth Explanation:
TheDatabricks CLIallows users to manage clusters using command-line commands. The correct command for creating a cluster follows a specific format.
Key Components in the Command:
* Command Type:databricks compute create is the correct syntax for creating a new compute resource (cluster).
* Runtime Version:'14.3.x-scala2.12' specifies the Databricks runtime to use.
* Workers:--num-workers 5 sets the number of worker nodes to 5.
* Node Type:--node-type-id i3.xlarge defines the hardware configuration.
* Cluster Name:--cluster-name DataEngineer_cluster assigns a recognizable name to the cluster.
Evaluation of Options:
* Option A (databricks clusters create ...)
* Incorrect:databricks clusters createis not a valid commandin the Databricks CLI v0.205.
* The correct CLI command for cluster creation is databricks compute create.
* Option B (databricks clusters add ...)
* Incorrect:databricks clusters addis not a valid CLI command.
* Option C (databricks compute add ...)
* Incorrect:databricks compute addis not a valid CLI command.
* Option D (databricks compute create ...)
* Correct:databricks compute create is the correct command for creating a cluster.
Conclusion:
The correct command to create a cluster with five workers, an i3.xlarge node type, and Databricks runtime
14.3.x-scala2.12 is:
databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster Thus, the correct answer isD.
References:
* Databricks CLI Documentation
NEW QUESTION # 49
In order to facilitate near real-time workloads, a data engineer is creating a helper function to leverage the schema detection and evolution functionality of Databricks Auto Loader. The desired function will automatically detect the schema of the source directly, incrementally process JSON files as they arrive in a source directory, and automatically evolve the schema of the table when new fields are detected.
The function is displayed below with a blank: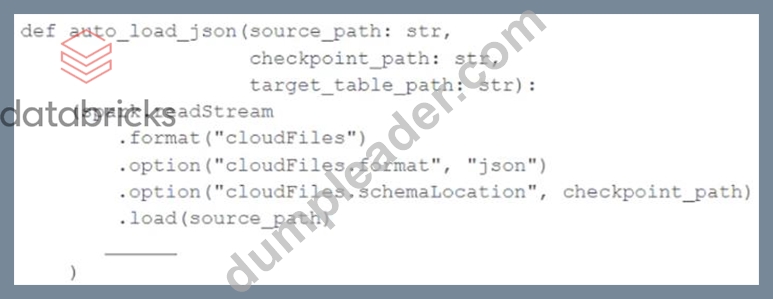
Which response correctly fills in the blank to meet the specified requirements?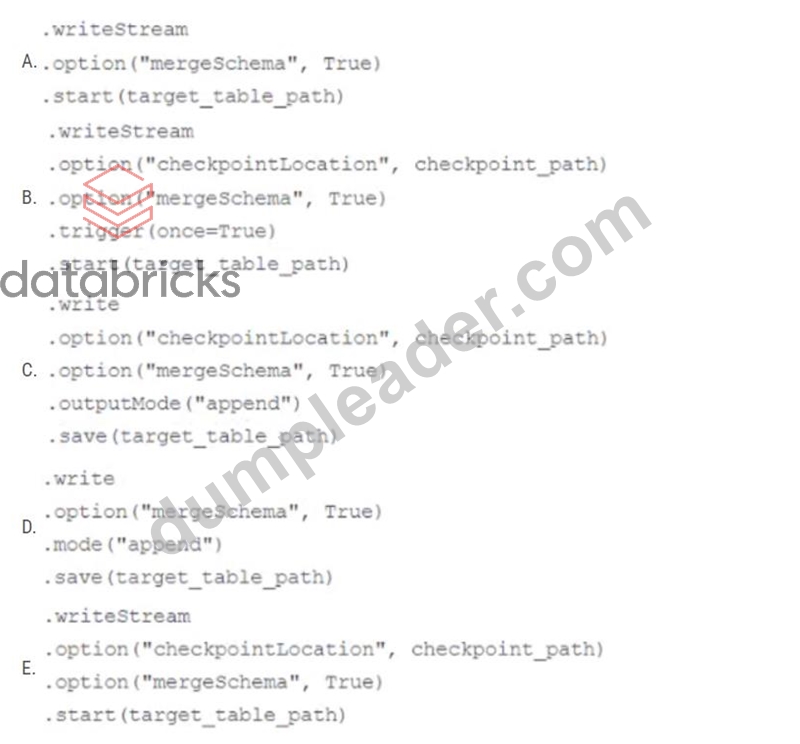
Answer: B
Explanation:
Option B correctly fills in the blank to meet the specified requirements. Option B uses the "cloudFiles.schemaLocation" option, which is required for the schema detection and evolution functionality of Databricks Auto Loader. Additionally, option B uses the "mergeSchema" option, which is required for the schema evolution functionality of Databricks Auto Loader. Finally, option B uses the "writeStream" method, which is required for the incremental processing of JSON files as they arrive in a source directory. The other options are incorrect because they either omit the required options, use the wrong method, or use the wrong format. Reference:
Configure schema inference and evolution in Auto Loader: https://docs.databricks.com/en/ingestion/auto-loader/schema.html Write streaming data: https://docs.databricks.com/spark/latest/structured-streaming/writing-streaming-data.html
NEW QUESTION # 50
......
The Databricks Databricks-Certified-Professional-Data-Engineer certification exam is a valuable credential that often comes with certain personal and professional benefits. For many Databricks professionals, the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification exam is not just a valuable way to boost their skills but also Databricks Certified Professional Data Engineer Exam certification exam gives them an edge in the job market or the corporate ladder. There are other several advantages that successful Databricks Databricks-Certified-Professional-Data-Engineer Exam candidates can gain after passing the Databricks Databricks-Certified-Professional-Data-Engineer exam.
Databricks-Certified-Professional-Data-Engineer Valid Dumps Sheet: https://www.dumpleader.com/Databricks-Certified-Professional-Data-Engineer_exam.html
P.S. Free 2026 Databricks Databricks-Certified-Professional-Data-Engineer dumps are available on Google Drive shared by Dumpleader: https://drive.google.com/open?id=11pfEZS88vSPOs1ut_qE-VB05B5CHH-1j