P.S. Free & New SPS-C01 dumps are available on Google Drive shared by DumpsFree: https://drive.google.com/open?id=1QLWJkHrAdWlaVhGeuxSM-Flg3zTtDZzI
If you are confusing while preparing for your test, you can choose to trust our information resource and experienced experts rather than waste a lot of time on learning aimlessly. Our Snowflake SPS-C01 exam guide materials are edited by professional experts based on latest and exact information about the real test. Generally the passing rate is high up to 99.79%. If you want to pass exam as soon as possible, our SPS-C01 Exam Guide Materials will be most useful product for you.
| Section | Objectives |
|---|---|
| Topic 1: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 2: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 3: Data Engineering with Snowpark | - Pipeline development
|
| Topic 4: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 5: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 6: Snowpark Fundamentals | - Snowpark architecture and concepts
|
Our SPS-C01 prepare questions are suitable for people of any culture level. According to different audience groups, our SPS-C01 preparation materials for the examination of the teaching content of a careful division, so that every user can find a suitable degree of learning materials. More and more candidates choose our SPS-C01 Quiz guide, they are constantly improving, so what are you hesitating about? As long as users buy our products online, our SPS-C01 practice materials will be shared in five minutes, so hold now, but review it! This may be the best chance to climb the top of your life.
NEW QUESTION # 182
Consider the following Snowpark Python code snippet for creating a stored procedure: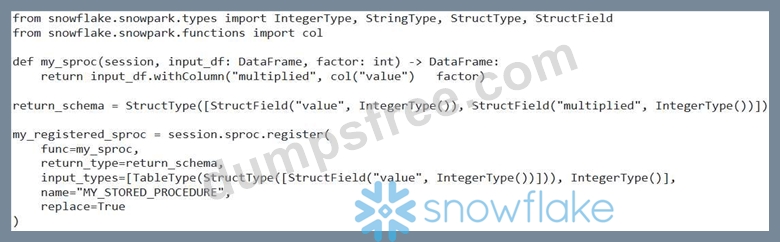
What is the PRIMARY reason for explicitly defining 'input_types' and during the stored procedure registration?
Answer: E
Explanation:
The primary reason for explicitly defining and 'return_type' during stored procedure registration is to enforce data type safety and schema validation. Snowflake uses these definitions to verify that the data passed to the stored procedure and the data returned by the stored procedure conform to the expected types. This helps prevent unexpected runtime errors that can occur due to type mismatches between the stored procedure's code and the calling environment. Without explicit type definitions, Snowpark would rely on runtime inference, which can be less reliable and harder to debug in production scenarios.
NEW QUESTION # 183
You have a Snowflake table 'PRODUCT REVIEWS' with columns 'product_id', 'review_text', 'review_date', and 'sentiment_score'. You are using Snowpark to build a data pipeline that analyzes these reviews and identifies potentially malicious or spam reviews. Based on a machine learning model deployed as a Snowflake UDF, you have identified a set of 'product_id' values that are associated with malicious reviews, and are stored in a python list called 'malicious_product_ids'. You need to delete all rows from the 'PRODUCT REVIEWS' table where the 'product_id' is present in the list. Assume 'malicious_product_ids' contains thousands of product IDs. Which of the following approaches is the MOST efficient and scalable for deleting these records using Snowpark?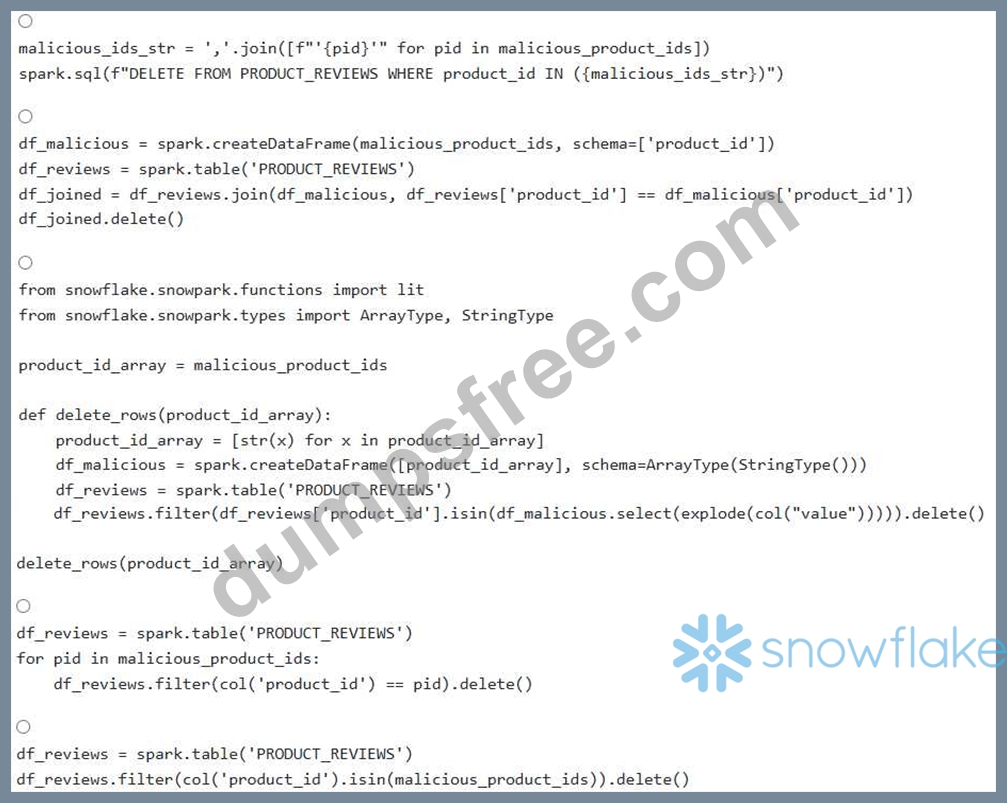
Answer: E
Explanation:
Option E is the most efficient and scalable. Using operator allows Snowpark to leverage Snowflake's internal optimizations for filtering based on a list of values. Option A is limited by the maximum length of SQL statement and also uses SQL directly. Option B has a subtle problem, DataFrame.delete() cannot use join condition. Option C has incorrect schema definition. Option D iterates through each , which is highly inefficient for a large list of IDs.
NEW QUESTION # 184
You have created a Python UDTF in Snowpark to process large volumes of image data'. This UDTF resizes each image and extracts certain features from it. The process is memory-intensive and sometimes fails due to Python process exceeding memory limits. You need to optimize this UDTF for memory usage. Which of the following strategies would be MOST effective? (Select TWO)
Answer: A,E
Explanation:
Lazy evaluation (B) and iterators allow processing data in smaller chunks, reducing memory consumption. Utilizing image compression techniques (D) reduces the memory footprint of each image, allowing more images to be processed within the available memory. Using scalar UDFs would not help and might perform worse. Decreasing the warehouse size would not solve the underlying problem and may make it worse. MAX_BATCH_SIZE determines how many records are sent over to UDF for each batch. It can help increasing performance but decreasing batch sizes might help with memory management, however its dependent on each case.
NEW QUESTION # 185
You are building a Snowpark application to process sensitive data'. To enhance security, you want to leverage ephemeral sessions. Which configurations, passed to 'snowpark.Session.builder.configS , are required and sufficient to create an ephemeral session? Assume your Snowflake environment is properly configured to allow ephemeral sessions.
Answer: A
Explanation:
Ephemeral sessions in Snowflake require that you specify a 'role', 'database', 'schema', and 'warehouse'. These parameters define the context within which the session will operate. Without these parameters, the session cannot be properly established. Although option A set role which is important for setting the context but it is insufficient. Ephemeral sessions are not automatic and require proper configuration.
NEW QUESTION # 186
You need to perform a set difference operation between two DataFrames in Snowpark Python. 'dfl' contains customer IDs from a marketing campaign, and 'df2 contains customer IDs from a recent purchase event. You want to identify customers who were targeted in the campaign but did not make a recent purchase. Both DataFrames have a column named 'customer id'. Which of the following approaches provides the most efficient way to accomplish this task in Snowpark?





Answer: B
Explanation:
Option C, using a 'left_anti' join, is the most efficient way to perform a set difference operation between two DataFrames in Snowpark. A join returns only the rows from the left DataFrame Cdfl s) where the join condition is not met in the right DataFrame Cdf2). This leverages Snowflake's query optimizer for optimal performance. Option A, 'subtract(df2)' , is equivalent to 'exceptAll(df2)' (Option B) and removes duplicate rows. While functionally correct, join is often more performant, especially for larger datasets. Option D is highly inefficient as it collects the 'customer_id' from 'df2 to the driver, it should be avoided. Option E calculates intersection, not difference.
NEW QUESTION # 187
......
If you attend Snowflake certification SPS-C01 Exams, your choosing DumpsFree is to choose success! I wish you good luck.
SPS-C01 Training Material: https://www.dumpsfree.com/SPS-C01-valid-exam.html
BONUS!!! Download part of DumpsFree SPS-C01 dumps for free: https://drive.google.com/open?id=1QLWJkHrAdWlaVhGeuxSM-Flg3zTtDZzI