DOWNLOAD the newest Prep4King AI-103 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=11EVjZ9ONF4Rh0aWti6tdfiPG5yC4g_Ag
The third and last format is the AI-103 desktop practice exam software form that can be used without an active internet connection. This software works offline on the Windows operating system. The practice exams benefit your preparation because you can attempt them multiple times to improve yourself for the Developing AI Apps and Agents on Azure Professional-Cloud-Developercertification test. Our AI-103 Exam Dumps are customizable, so you can set the time and questions according to your needs.
| Section | Weight | Objectives |
|---|---|---|
| Implement computer vision solutions | 10-15% | - Analyze visual content
|
| Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
| Plan and manage Azure AI solutions | 25-30% | - Plan Azure AI resources
|
| Implement generative AI solutions | 25-30% | - Optimize and evaluate models
|
| Implement agentic solutions | 20-25% | - Manage agent operations
|
When dealing with any kind of exams, the most important thing is to find a scientific way to review effectively. Our AI-103 practice materials compiled by the most professional experts. Till now, we have over tens of thousands of customers around the world supporting our AI-103 exam torrent. If you are unfamiliar with our AI-103 Study Materials, please download the free demos for your reference. To some unlearned exam candidates, you can master necessities by our AI-103 practice materials quickly So our materials are elemental materials you cannot miss.
NEW QUESTION # 110
You have a Microsoft Foundry project that contains an agent.
You need to process mixed-format documents that contain scanned text, tables, and multicolumn layouts. The extracted content must preserve the document structure and be converted into the Markdown format for downstream reasoning.
What should you configure first?
Answer: C
Explanation:
The first step should be an Azure Content Understanding analyzer within Microsoft Foundry Tools.
This specific tool is designed to handle the complexities in this scenario--scanned text, complex tables, and multi-column layouts--by converting unstructured documents into a structured Markdown format. This preserves the document's original hierarchy and structural relationships, which is critical for accurate downstream reasoning by an agent.
Incorrect:
[Not A]
Azure Language is designed for text-based natural language processing (NLP) like sentiment analysis or PII redaction on raw text strings. It cannot parse scanned images, optical character recognition (OCR), tables, or complex multi-column visual layouts.
[Not C]
The first step in this specific Microsoft Foundry agent configuration should not be an Azure OpenAI Responses API call.While multimodal models can read images, they frequently hallucinate data, fail to capture complex multi-column reading orders, and degrade table structures when processing dense, mixed-format documents.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/content-understanding/document/elements
NEW QUESTION # 111
You have a Microsoft Foundry project that contains an agent.
You need to enable long-term memory to ensure that the agent can recall user preferences across separate conversations. Stored memories must be isolated per authenticated user without the client application manually generating user IDs.
How should you complete the Python code? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all.
NOTE: Each correct selection is worth one point.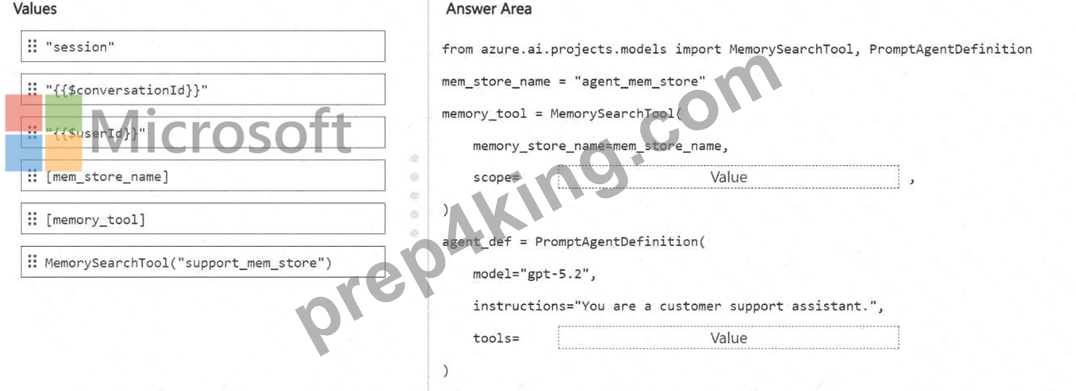
Answer:
Explanation: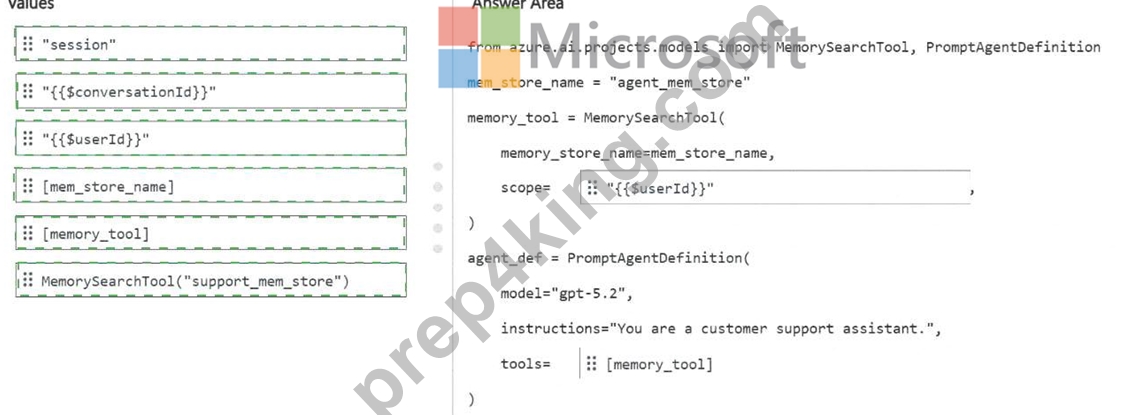
Explanation:
scope = " {{userId}} "
tools = [memory_tool]
The correct scope value is {{userId}} because the requirement is per-authenticated-user memory isolation without the client application manually generating user identifiers. In Microsoft Foundry Agent Service memory, the scope parameter partitions memory items inside the memory store. The official guidance states that when the memory search tool is attached to an agent, setting scope to the user identity template enables per-user memory isolation; the service resolves the end-user identity from the request header when provided, or falls back to the Microsoft Entra tenant ID and object ID of the caller. This matches the requirement to isolate stored preferences by authenticated user automatically.
The tools property must be [memory_tool] because the MemorySearchTool instance is created earlier and must be attached to the PromptAgentDefinition. Foundry guidance shows the memory search tool being passed in the agent definition as tools=[tool] , allowing the agent to read from and write to the configured memory store during conversations.
" session " and {{conversationId}} would limit continuity to a session or conversation instead of enabling long-term recall across separate conversations. [mem_store_name] is a list containing the store name, not a tool definition. Reference topics: Foundry Agent Service memory, memory stores, memory search tools, scope, and per-user isolation.
NEW QUESTION # 112
You are developing prompts for a Micosoft Foundry project that classifies incoming support tickets by category.
You need to improve accuracy by showing the model how correct classifications look, without retaining the model or storing knowledge permanently.
Which prompt engineering approach should you use?
Answer: B
Explanation:
Few-shot prompting is the best approach for this project. This technique improves classification accuracy by including a few high-quality examples directly inside the prompt, giving the model a clear pattern to follow without modifying its weights or storing data permanently.
Zero retraining: Works entirely through in-context learning during the API call.
No permanent storage: The knowledge disappears as soon as the inference request is completed.
Immediate accuracy boost: Demonstrates formatting, nuances, and edge cases directly to the model.
Reference:
https://www.linkedin.com/pulse/top-interview-questions-answers-prompt-engineering-nitin-sharma-ka4fc
NEW QUESTION # 113
You have an invoice-processing application named App1 that uses Azure Content Understanding in Foundry Tools. You are building a new Content Understanding pipeline named Pipeline1 that must meet the following requirements:
* Compare an invoice to its related purchase order.
* Validate the invoice against static vendor contract documents.
* Return a single structured output that includes discrepancy findings.
You need to configure Pipeline1 and expose the pipeline as a single analyzer endpoint. What should you configure?
Answer: D
Explanation:
Configure a multi-file task in pro mode . At analysis time, provide the invoice and its related purchase order as the input documents. During analyzer creation, add the static vendor contracts as reference data . Pro mode can reason across multiple input documents and use reference documents as contextual knowledge for validation, enrichment, and discrepancy detection. Microsoft specifically documents the scenario of supplying an invoice and purchase order as inputs while using contract files as reference data to identify inconsistencies.
Define a field schema containing the required invoice information and generated discrepancy findings.
Building the task creates an analyzer ID that applications invoke through one analyzer API endpoint, producing a unified structured result governed by that schema.
Standard mode is optimized for straightforward processing of individual files. It does not support cross-file analysis, reference-dataset integration, or the multi-step reasoning required to compare invoices, purchase orders, and contractual conditions. A "multi-file task in standard mode" is therefore not a supported configuration. Confidence scores do not address document comparison and, notably, are not available in pro mode.
Study Guide alignment: configure Content Understanding analyzers, design structured schemas, process multiple documents, integrate reference data, and implement document validation workflows .
NEW QUESTION # 114
You have a Python application that uses Azure OpenAt structured outputs to extract fields from unstructured receipt text and support ticket text. The application uses the following schema.
Answer:
Explanation: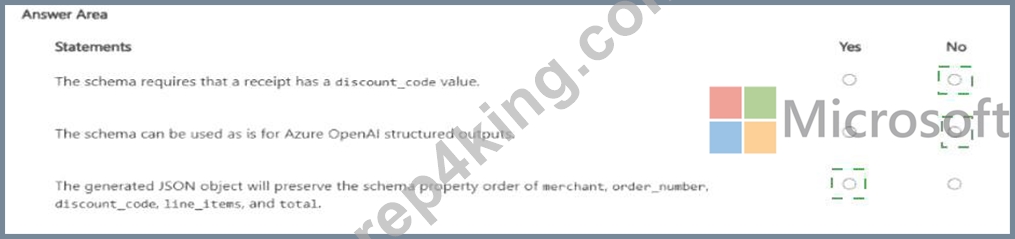
Explanation:
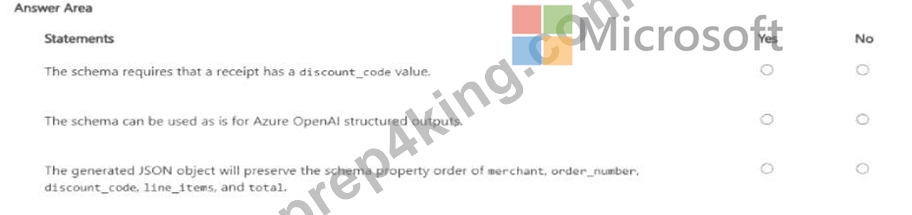
* The schema requires that a receipt has a discount_code value - No
* The schema can be used as is for Azure OpenAI structured outputs - No
* The generated JSON object will preserve the property order merchant, order_number, discount_code, line_items, and total - Yes The discount_code definition permits a nullable result. Consequently, the output can contain " discount_code
" : null when the source receipt contains no discount code. The property can be structurally present without containing a substantive discount-code value; therefore, the first statement is No .
The schema cannot be submitted unchanged. Azure OpenAI structured outputs support only a defined subset of JSON Schema. Every property declared in an object must be included in that object's required array.
Optional information must instead be represented as a required property whose type includes null. Each object must also specify " additionalProperties " : false. Furthermore, although nested anyOf constructs are supported, an anyOf construct cannot be used as the root schema. A schema that violates any of these restrictions must be revised before use, making the second statement No .
The third statement is Yes . Azure OpenAI structured outputs preserve keys in the order in which the properties are defined in the supplied schema. Therefore, the receipt object will emit merchant, order_number, discount_code, line_items, and total in that sequence. This behavior supports predictable parsing and downstream integration. The relevant curriculum area is Use Azure OpenAI in Foundry Models to generate content , including application integration and structured model responses.
NEW QUESTION # 115
......
Prep4King's experts have simplified the complex concepts and have added examples, simulations and graphs to explain whatever could be difficult for you to understand. Therefore even the average exam candidates can grasp all study questions without any difficulty. Additionally, the AI-103 Exam takers can benefit themselves by using our testing engine and get numerous real exam like practice questions and answers. They will help them revising the entire syllabus within no time.
AI-103 Latest Test Question: https://www.prep4king.com/AI-103-exam-prep-material.html
P.S. Free 2026 Microsoft AI-103 dumps are available on Google Drive shared by Prep4King: https://drive.google.com/open?id=11EVjZ9ONF4Rh0aWti6tdfiPG5yC4g_Ag