NVIDIA NCP-AIO Online Exam - NCP-AIO Valid Exam Answers

P.S. Free & New NCP-AIO dumps are available on Google Drive shared by Lead2Passed: https://drive.google.com/open?id=1pk0FHpl5dsyQBfX_PUuKG_L1Sy1_R-qm
Don't let the NVIDIA AI Operations (NCP-AIO) certification exam stress you out! Prepare with our NVIDIA NCP-AIO exam dumps and boost your confidence in the NVIDIA NCP-AIO exam. We guarantee your road toward success by helping you prepare for the NCP-AIO Certification Exam. Use the best NVIDIA NCP-AIO practice questions to pass your NVIDIA NCP-AIO exam with flying colors!
| Topic | Details |
|---|
| Topic 1 | - Troubleshooting and Optimization: NVIThis section of the exam measures the skills of AI infrastructure engineers and focuses on diagnosing and resolving technical issues that arise in advanced AI systems. Topics include troubleshooting Docker, the Fabric Manager service for NVIDIA NVlink and NVSwitch systems, Base Command Manager, and Magnum IO components. Candidates must also demonstrate the ability to identify and solve storage performance issues, ensuring optimized performance across AI workloads.
|
| Topic 2 | - Workload Management: This section of the exam measures the skills of AI infrastructure engineers and focuses on managing workloads effectively in AI environments. It evaluates the ability to administer Kubernetes clusters, maintain workload efficiency, and apply system management tools to troubleshoot operational issues. Emphasis is placed on ensuring that workloads run smoothly across different environments in alignment with NVIDIA technologies.
|
| Topic 3 | - Administration: This section of the exam measures the skills of system administrators and covers essential tasks in managing AI workloads within data centers. Candidates are expected to understand fleet command, Slurm cluster management, and overall data center architecture specific to AI environments. It also includes knowledge of Base Command Manager (BCM), cluster provisioning, Run.ai administration, and configuration of Multi-Instance GPU (MIG) for both AI and high-performance computing applications.
|
| Topic 4 | - Installation and Deployment: This section of the exam measures the skills of system administrators and addresses core practices for installing and deploying infrastructure. Candidates are tested on installing and configuring Base Command Manager, initializing Kubernetes on NVIDIA hosts, and deploying containers from NVIDIA NGC as well as cloud VMI containers. The section also covers understanding storage requirements in AI data centers and deploying DOCA services on DPU Arm processors, ensuring robust setup of AI-driven environments.
|
>> NVIDIA NCP-AIO Online Exam <<
NVIDIA NCP-AIO Valid Exam Answers | Real NCP-AIO Exam Dumps
In the PDF version, the NVIDIA AI Operations (NCP-AIO) exam questions are printable and portable. You can take these NVIDIA NCP-AIO pdf dumps anywhere and even take a printout of NVIDIA AI Operations (NCP-AIO) exam questions. The PDF version is mainly composed of real NVIDIA NCP-AIO Exam Dumps. Lead2Passed updates regularly to improve its NVIDIA AI Operations (NCP-AIO) pdf questions and also makes changes when required.
NVIDIA AI Operations Sample Questions (Q86-Q91):
NEW QUESTION # 86
A DGX H100 system in a cluster is showing performance issues when running jobs.
Which command should be run to generate system logs related to the health report?
- A. nvsm get logs
- B. nvsm show logs --save
- C. nvsm health --dump-log
- D. nvsm dump health
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
For troubleshooting and performance optimization on NVIDIA DGX systems such as DGX H100, the NVIDIA System Management (nvsm)tool is used to gather system health and diagnostic data. The command nvsm dump health is the correct command to generate and export detailed system logs related to the health report of the DGX system.
* nvsm show logs --save is not a recognized command format.
* nvsm get logs retrieves logs but does not specifically dump the health report logs.
* nvsm health --dump-log is not a standard documented nvsm command.
Therefore, nvsm dump health is the valid and documented command used to generate system logs focused on health reporting, useful for diagnosing performance issues in DGX H100 systems.
This usage aligns with NVIDIA's system management tools guidance for DGX platforms as described in NVIDIA AI Operations documentation for troubleshooting and performance optimization.
NEW QUESTION # 87
A user submits a Slurm job script with the following options:
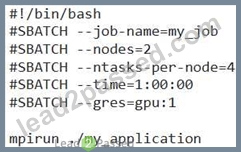
Assuming each node has 4 GPUs, how many GPU resources will be allocated to this job across the entire cluster?
Answer: B
Explanation:
The job requests 2 nodes (nodes=2) and one GPU per node Therefore, a total of 2 GPUs (2 nodes 1 GPU/node) will be allocated to the job.
NEW QUESTION # 88
You are designing a data center network to support distributed deep learning training across multiple servers. The training job uses NCCL (NVIDIA Collective Communications Library) for inter-GPU communication. Which of the following network configurations will maximize the performance of NCCL?
- A. A VLAN-based network with no QOS (Quality of Service) configured.
- B. A Clos network topology with non-blocking links between all servers, utilizing RoCEv2 or InfiniBand.
- C. A traditional three-tier network architecture with oversubscribed links at each layer.
- D. A network using only TCP/IP without RDMA support.
- E. A single network switch connecting all servers, with each server connected via a single IOGbE link.
Answer: B
Explanation:
NCCL benefits greatly from low-latency, high-bandwidth communication. A Clos network with non-blocking links, RoCEv2, or InfiniBand ensures that GPUs can communicate efficiently without bottlenecks. A single switch with limited bandwidth, a three-tier network with oversubscription, or lack of RDMA will significantly hinder NCCL performance. VLANs without QOS do not guarantee low latency.
NEW QUESTION # 89
You are managing a fleet of edge devices using NVIDIA Fleet Command. After deploying a new AI model, you observe that the model is consuming excessive resources on several devices, leading to performance degradation. What steps can you take within Fleet Command to address this issue?
- A. Increase the overall resource allocation for the entire fleet.
- B. Redeploy the same model to see if the issue resolves itself.
- C. Use Fleet Command's monitoring tools to identify the specific resources being overutilized and then reconfigure the model deployment with resource limits.
- D. Roll back the deployment to the previous model version.
- E. Remotely reboot the affected edge devices.
Answer: C
Explanation:
Fleet Command's monitoring allows precise identification of resource bottlenecks. Resource limits prevent excessive consumption. Rolling back (A) is a reactive measure. Rebooting (B) is temporary. Increasing overall resources (D) is inefficient. Redeploying (E) is unlikely to solve the problem without investigation.
NEW QUESTION # 90
A data scientist submits a Run.ai job requesting 4 GPUs. However, due to resource constraints, only 2 GPUs are immediately available. You want the job to automatically start running as soon as the remaining 2 GPUs become available, without manual intervention. How do you configure Run.ai to achieve this?
- A. Enable gang scheduling for the job.
- B. Set a higher quota for the team.
- C. Configure a lower priority for the job.
- D. Set the job's 'restartPolicy' to 'Always'.
- E. Use Run.ai's 'suspend' and 'resume' commands manually.
Answer: A
Explanation:
Gang scheduling ensures that all requested resources (in this case, all 4 GPUs) are allocated before the job starts. The job will remain in a pending state until all resources are available, and then it will automatically start. 'restartPolicy only applies if a job fails after it has already started. Lower priority would make it less likely to start. Manually suspending and resuming requires intervention. A quota impacts how much you can submit overall, not the allocation of the complete resources requested by a single job.
NEW QUESTION # 91
......
Every detail of our NCP-AIO exam guide is going through professional evaluation and test. Other workers are also dedicated to their jobs. Even the proofreading works of the NCP-AIO study materials are complex and difficult. They still attentively accomplish their tasks. Please have a try and give us an opportunity. Our NCP-AIO Preparation quide will totally amaze you and bring you good luck. And it deserves you to have a try!
NCP-AIO Valid Exam Answers: https://www.lead2passed.com/NVIDIA/NCP-AIO-practice-exam-dumps.html
- Latest NCP-AIO Test Objectives 🎒 Exam Dumps NCP-AIO Demo 🅱 NCP-AIO Test Lab Questions 🦯 Search for ( NCP-AIO ) and obtain a free download on [ www.dumpsmaterials.com ] 🚤NCP-AIO Accurate Study Material
- Exam Dumps NCP-AIO Demo 🎴 NCP-AIO Clear Exam 🕘 NCP-AIO Guaranteed Questions Answers 🧃 Search for ⇛ NCP-AIO ⇚ and download it for free immediately on ▛ www.pdfvce.com ▟ 🟩NCP-AIO Real Torrent
- Free PDF 2026 Latest NVIDIA NCP-AIO Online Exam 👺 Open 【 www.practicevce.com 】 enter ➡ NCP-AIO ️⬅️ and obtain a free download ↕Exam NCP-AIO Cram
- Hot NCP-AIO Online Exam Free PDF | Latest NCP-AIO Valid Exam Answers: NVIDIA AI Operations 🍖 Immediately open ➡ www.pdfvce.com ️⬅️ and search for ▷ NCP-AIO ◁ to obtain a free download 🤾NCP-AIO Guaranteed Questions Answers
- Why Should You Start Preparation With NVIDIA NCP-AIO Exam Dumps? 🖊 Search for 《 NCP-AIO 》 and download exam materials for free through ▛ www.practicevce.com ▟ 👐Certification NCP-AIO Torrent
- NCP-AIO Valid Test Objectives 📂 Valid NCP-AIO Exam Camp 🔔 Examcollection NCP-AIO Dumps Torrent 😊 Go to website ▶ www.pdfvce.com ◀ open and search for [ NCP-AIO ] to download for free 🏉Valid NCP-AIO Exam Dumps
- Hot NCP-AIO Online Exam Free PDF | Latest NCP-AIO Valid Exam Answers: NVIDIA AI Operations 🏜 Download “ NCP-AIO ” for free by simply searching on [ www.examcollectionpass.com ] 🔴Valid NCP-AIO Exam Camp
- Latest NCP-AIO Test Objectives 🔒 Valid NCP-AIO Exam Dumps 🌰 NCP-AIO Free Vce Dumps 🕋 Download 【 NCP-AIO 】 for free by simply entering ( www.pdfvce.com ) website 🔯Latest NCP-AIO Test Sample
- NCP-AIO Online Exam - NVIDIA NCP-AIO Valid Exam Answers: NVIDIA AI Operations Pass Success 🚝 Search for 【 NCP-AIO 】 on ▶ www.examdiscuss.com ◀ immediately to obtain a free download ⚜Examcollection NCP-AIO Dumps Torrent
- NCP-AIO Clear Exam ♿ NCP-AIO Latest Dumps Pdf 🔚 Certification NCP-AIO Torrent 😚 Enter ⏩ www.pdfvce.com ⏪ and search for ✔ NCP-AIO ️✔️ to download for free 🏯NCP-AIO Real Torrent
- Useful 100% Free NCP-AIO – 100% Free Online Exam | NCP-AIO Valid Exam Answers 🐴 The page for free download of ▶ NCP-AIO ◀ on { www.vce4dumps.com } will open immediately 🤗Valid NCP-AIO Exam Dumps
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
What's more, part of that Lead2Passed NCP-AIO dumps now are free: https://drive.google.com/open?id=1pk0FHpl5dsyQBfX_PUuKG_L1Sy1_R-qm