AI-200試験問題はグローバルなものであるとMicrosoft誇らしく言えます。 したがって、どんな種類のAI-200テストトレントを求めても、当社のアフターサービスサービススタッフは、最も専門的な方法でAI-200練習問題の問題を解決するお手伝いをします。 AI-200のDeveloping AI Cloud Solutions on Azure学習ツールを目指しているお客様は世界中のさまざまな国から来ており、間違いなく時間差があるため、AI-200トレーニングガイドで1日24時間、7日間、思いやりのあるXhs1991オンラインアフターサービスを提供します 週に数日、いつでもどこでも気軽にご連絡ください。
| Section | Objectives |
|---|---|
| Implement Azure AI solutions | - Implement natural language processing solutions - Implement generative AI solutions using Azure OpenAI - Implement computer vision solutions - Implement knowledge mining with Azure AI Search |
| Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
| Plan and manage Azure AI solutions | - Plan security and compliance requirements - Monitor and optimize AI solutions - Select appropriate Azure AI services |
Microsoft AI-200テスト質問の回答を注文する予定です。 クレジットカードが必要です。 ほとんどの場合、クレジットカードをサポートしています。 デビットカードをお持ちの場合は、クレジットカードを申請するか、他の友人にAI-200テスト質問の回答の支払いを手伝ってもらってください。 通常、候補者はPayPalで支払うことをお勧めします。ここでは、PayPalアカウントを持っている必要はありません。 [PayPal]をクリックすると、クレジットカード支払いに振り替えられます。 AI-200テストの質問の回答にSWREG支払いを選択した場合、一部の国では追加の税金がかかります。
質問 # 79
You are reviewing an Azure Function app that processes incoming order requests for a company. The function must:
* Accept order submissions from an external client application.
* Require controlled access for security
* Return a response containing the processed request payload.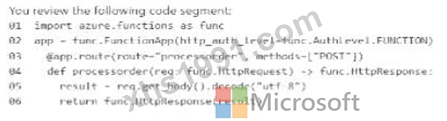
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.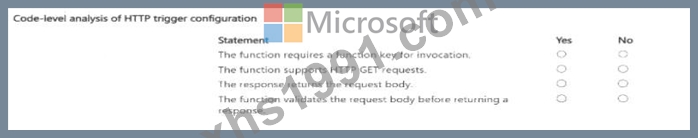
正解:
解説: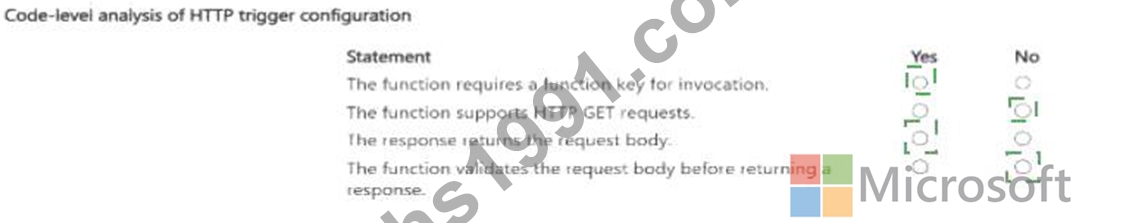
Explanation: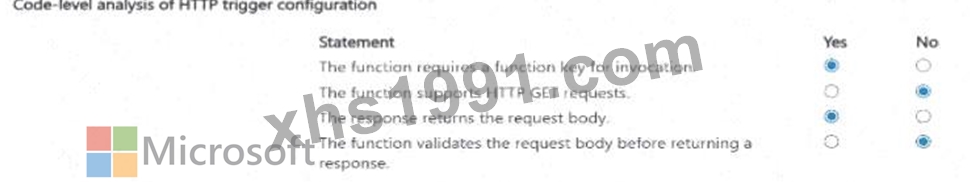
Verified answer: Yes; No; Yes; No.
Detailed Explanation: `auth_level=FUNCTION` means invocation requires a function key unless a stronger platform authentication layer is configured, so the first statement is true. The route explicitly permits POST, not GET. The function reads `req.get_body()` and returns that value in the HttpResponse, so the response contains the request body. No schema, type, required-field, or other payload validation is performed before the response is constructed, making the final statement false.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Azure Functions HTTP trigger
質問 # 80
You need to configure a connection string for the partner-facing service according to the technical requirements.
What should you use?
正解:C
解説:
Detailed Explanation: Azure Key Vault references in App Service settings satisfy the requirement to keep secrets out of container images, source control, and directly stored application configuration. App Service resolves the referenced secret at runtime by using the app identity, so the application can consume the value as a normal setting without embedding credentials in the image. GitHub secrets are build/deployment secrets rather than a runtime App Service secret-delivery mechanism. Dockerfile ENV instructions would place secret material in the image configuration and violate the case requirements.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Use Key Vault references for App Service and Functions | Managed identities for Azure resources
Topic 2, Fabrikam Inc
Background - Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure. The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security. The solution must meet strict performance, scalability, and security requirements. Current environment - Application architecture - The Recommendation engine is a customer- facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA). Embeddings are stored in Azure Database for PostgreSQL by using pgvector. Semantic retrieval uses metadata filtering combined with vector similarity search. Azure Managed Redis is used as a caching layer. Front-end and API workloads are deployed to Azure Container Apps (ACA). Batch model retraining workloads run in Azure Kubernetes Service (AKS). Container and CI/CD - Container images are stored in Azure Container Registry (ACR). CI/CD uses ACR Tasks to build images on commit. ACA environments support revision management. AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring - Logs are collected in Azure Monitor. Teams inspect container logs and Kubernetes events when troubleshooting. Developers write KQL queries to analyze latency spikes. Business requirements - Customer experience: Maintain a seamless, low-latency recommendation experience for end-users, even during unpredictable seasonal traffic spikes. Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs. Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction. Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets. Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers. Technical requirements - Performance: Semantic search latency must remain under 200 milliseconds at peak load. Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput.
Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints. Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization. Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates. Identity: Use managed identities for all service-to-service and service-to-database authentication. Plain-text credentials in configuration files are strictly prohibited. Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy. Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero. CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits. Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
質問 # 81
You have an Azure Service Bus namespace with a partitioned queue named queue1.
You plan to send a large number of messages through queue1 over the next few weeks. The order of messages will be random. You must minimize the possibility of message transmission interruption by transient failures of individual partitions.
You need to use the optimal configuration of the partition key in the messages.
Which configuration should you use?
正解:C
質問 # 82
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are using Azure Monitor Application Insights to investigate a production API. You open the Logs blade and set the time range to Last 24 hours.
An engineer recommends the following query to count requests by result code and sort the results from most frequent to least frequent:
requests
| summarize request_count = count() by resultCode
| order by request_count desc
You need to determine whether the query returns the number of requests grouped by result code and sorted from most to least frequent.
Solution: The query returns one row per unique resultCode value with the number of requests in each group.
Does the solution meet the goal?
正解:A
解説:
Correct:
* The query returns one row per unique resultCode value with the number of requests in each group.
The Kusto Query Language (KQL) query uses the summarize operator, which acts as a grouping and aggregation mechanism.
summarize request_count = count() by resultCode
This groups all the individual rows in the requests table by their unique resultCode. It then counts the total number of logs within each group and places that value into a new column called request_count.
order by request_count desc: This sorts those aggregated rows so that the resultCode with the highest number of requests appears at the top.
Incorrect:
* The result codes are sorted alphabetically.
* The query lists every individual request along with its result code.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/reference/tables/apprequests
質問 # 83
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals.
You are using Azure Monitor Application Insights to investigate a production API. You open the Logs blade and set the time range to Last 24 hours.
An engineer recommends the following query to count requests by result code and sort the results from most frequent to least frequent:
requests
| summarize request_count = count() by resultCode
| order by request_count desc
You need to determine whether the query returns the number of requests grouped by result code and sorted from most to least frequent.
Solution: The result codes are sorted alphabetically.
Does the solution meet the goal?
正解:B
解説:
The solution does not meet the goal because the query does not sort by resultCode. The summarize operator groups request records by each distinct resultCode value and calculates the number of requests in each group by using count().
The resulting table contains a resultCode column and a calculated request_count column. The next statement:
| order by request_count desc
sorts the output by request_count in descending order , which places the most frequently occurring result code first and the least frequent last.
Therefore, the output is sorted by frequency , not alphabetically or numerically by the resultCode field.
If alphabetical sorting by result code were required, the query would instead use a statement such as:
| order by resultCode asc
That is not what the provided query does.
Because the Logs blade is already scoped to the Last 24 hours , the query operates over that selected time range unless additional time filtering is explicitly added.
Study Guide references: Azure Monitor Logs; Application Insights requests table; KQL summarize; count() aggregation; order by; descending sort semantics.
質問 # 84
......
Xhs1991は君の試験に合格させるだけでなく本当の知識を学ばれます。Xhs1991はあなたが100% でAI-200試験に合格させるの保証することができてまたあなたのために一年の無料の試験の練習問題と解答の更新サービス提供して、もし試験に失敗したら、弊社はすぐ全額で返金を保証いたします。
AI-200試験勉強過去問: https://www.xhs1991.com/AI-200.html