With rapid development of IT industry, more and more requirements have been taken on those who are working in IT industry. So if you don't want to be eliminated in the competition, to pass DP-750 exam is a necessary for you. If you worry that you will not get the satisfied results after you have taken too much time and energy to prepare the DP-750 Exam. Now let our BraindumpStudy help you! Countless DP-750 exam software users of our BraindumpStudy let us have the confidence to tell you that using our test software, you will have the most reliable guarantee to pass DP-750 exam.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
>> Reliable Test Microsoft DP-750 Test <<
The Microsoft DP-750 PDF format is printable which enables you to do paper study. It contains pool of actual and updated Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions. You can carry this portable file of Microsoft DP-750 Real Questions to any place via smartphones, laptops, and tablets. This simple and convenient format of BraindumpStudy's Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice material is being updated regularly.
NEW QUESTION # 60
You have an Azure Databricks workspace named Workspace1.
You create a compute cluster named Cluser1 that will be used to ingest data.
You need to install the required libraries on Cluster1. The solution must use Unity Catalog for access control.
What should you do?
Answer: D
Explanation:
A Unity Catalog volume is the appropriate location because it provides governed file storage with permissions managed through Unity Catalog. After uploading the library package to the volume, it can be configured as a cluster library on Cluster1. This approach permits centralized access control, auditing, and lifecycle management. Option A installs the library without placing its source under Unity Catalog governance. Option B provides notebook-scoped dependency management but does not, by itself, satisfy the requirement that Unity Catalog control access to the library artifact. A schema is a logical container for tables, views, functions, models, and volumes; a library file cannot be uploaded directly to the schema itself, eliminating option D. Unity Catalog volumes explicitly support storing cluster libraries and job dependencies. Microsoft Learn
NEW QUESTION # 61
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.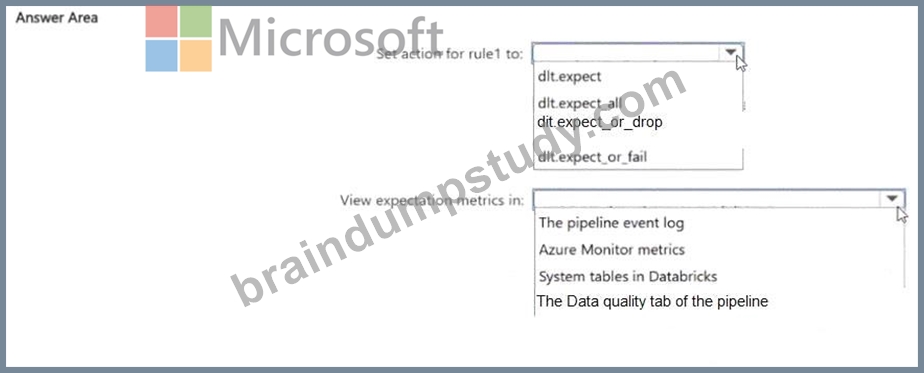
Answer:
Explanation: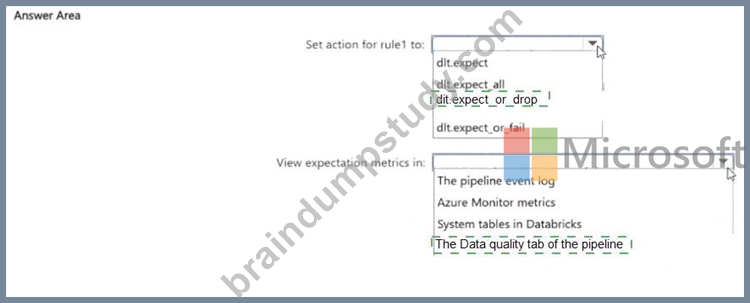
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 62
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
* asset.id
* asset, type
* asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.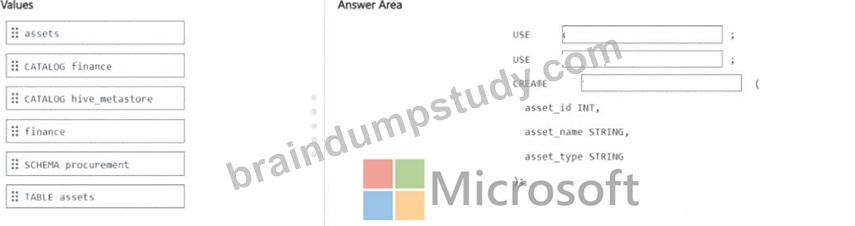
Answer:
Explanation: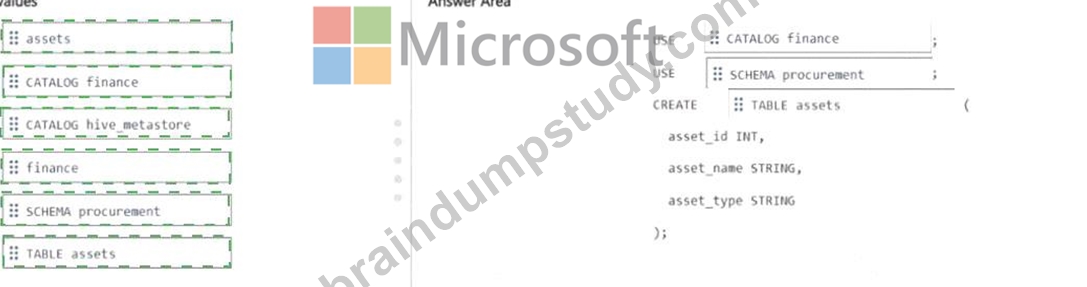
Explanation:
The correct SQL statement uses the full three-part namespace finance.procurement.assets with the three specified columns.
In Unity Catalog, every object lives in a three-tier hierarchy: catalog # schema # table. Using the full path finance.procurement.assets guarantees the table lands in the right schema regardless of the session's current catalog or schema context. Omitting the catalog or schema name relies on the session default, which may not be finance.procurement - a silent mistake that's hard to catch.
The column names asset_id, asset_type, and asset_name must match the spec exactly. Unity Catalog applies access controls, lineage tracking, and tagging at the column level, so the names are meaningful beyond just the schema. Once created, any GRANT statements can target specific columns for fine-grained access control.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- table-using
NEW QUESTION # 63
You need to recommend a compute type for the production ingestion workloads and BI workloads. The solution must meet the environment and compute requirements.
What should you recommend for each type of workload? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.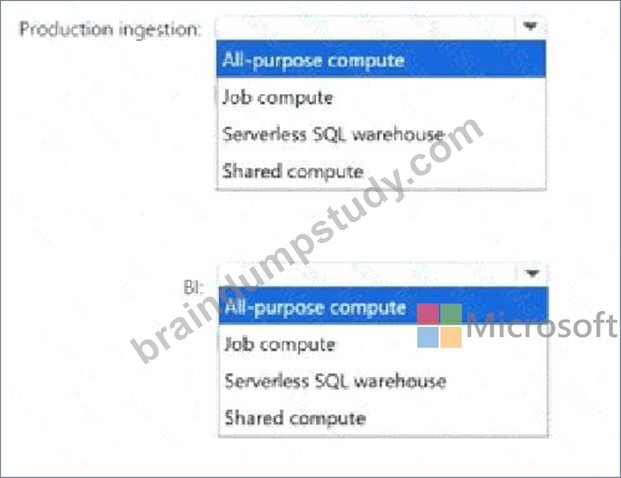
Answer:
Explanation: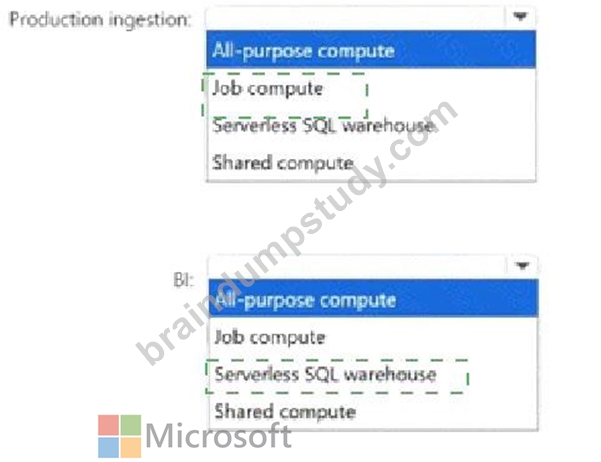
Explanation:
Production ingestion: Job compute
BI: Serverless SQL warehouse
Job compute is designed for automated production workloads executed through Lakeflow Jobs. Its lifecycle can be tied to the job run, providing workload isolation and avoiding the cost of maintaining an interactive all- purpose cluster continuously. It is therefore appropriate for scheduled ingestion and transformation processing. A serverless SQL warehouse is designed for BI and Databricks SQL workloads. It provides rapid startup, automatic infrastructure management, scaling, and optimized SQL-query execution for dashboards and reporting tools. All-purpose compute is intended primarily for interactive notebook development and exploration, while shared compute does not provide the same job-specific isolation or SQL-serving experience. Consequently, job compute should support production ingestion, and a serverless SQL warehouse should serve the BI workload.
NEW QUESTION # 64
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
- Ensure that authentication does NOT require storing credentials in
Databricks.
- Ensure that users can access the files, but NOT modify the files.
- Follow the principle of least privilege.
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.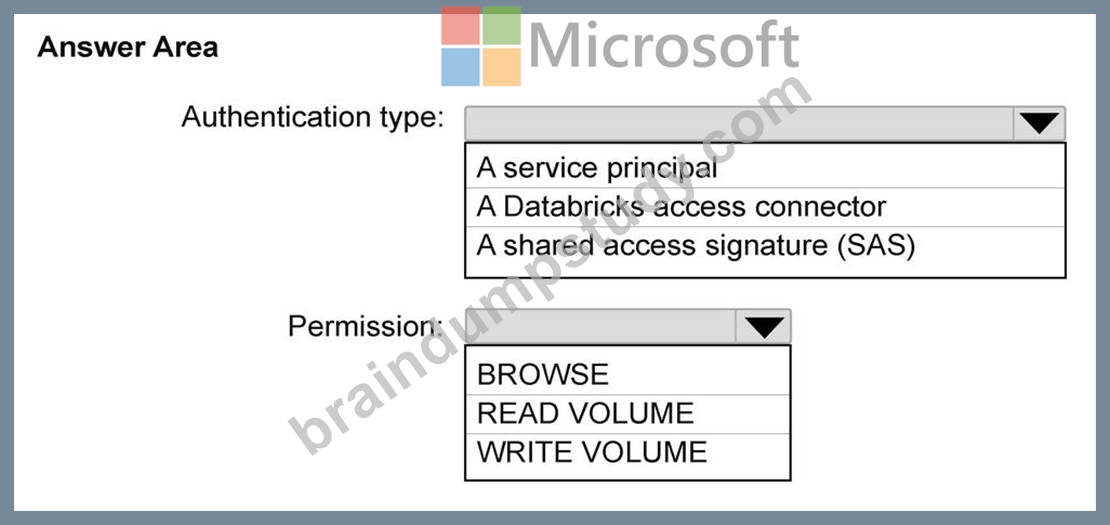
Answer:
Explanation: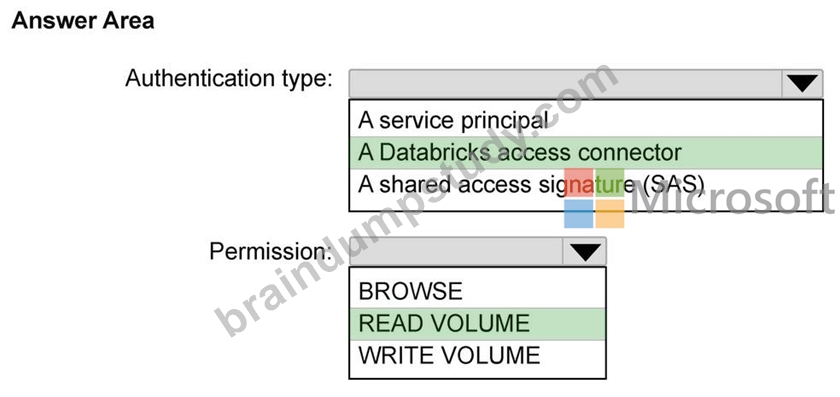
NEW QUESTION # 65
......
In comparison to others, Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam dumps are priced at a reasonable price. It is possible to prepare using DP-750 exam using a pdf file anytime according to the hectic routines. If you are confused regarding its quality DP-750 exam dumps, download the free trial to assist you make a final decision prior to purchasing. All exam dumps and patterns are made to follow the style of actual exam dumps. Therefore, it increases your chances of success in the Real DP-750 Exam.
DP-750 Valid Test Camp: https://www.braindumpstudy.com/DP-750_braindumps.html