PDFバージョン、ソフトバージョン、APPバージョンの3つのバージョンのNCP-BC-7.5練習問題を選択できます。 NCP-BC-7.5トレーニング資料のPDFバージョンは読みやすく、覚えやすく、印刷リクエストをサポートしているため、紙で印刷して練習することができます。 NCP-BC-7.5実践教材のソフトウェアバージョンは、シミュレーションテストシステムをサポートし、セットアップの時間を与えることには制限がありません。 このバージョンはWindowsシステムユーザーのみをサポートすることに注意してください。 NCP-BC-7.5試験問題のオンライン版は、あらゆる種類の機器やデジタルデバイスに適しています。モバイルデータなしで練習することを条件に、オフラインでの運動をサポートします。
| Section | Objectives |
|---|---|
| Topic 1: Nutanix Disaster Recovery Architecture | - Replication Types (Sync/Async) - Nutanix Leap Overview - Protection Domains |
| Topic 2: Recovery Operations | - Test Recovery Workflows - Recovery Plans and Orchestration - Failover and Failback Procedures |
| Topic 3: Disaster Recovery Fundamentals | - Business Continuity Principles - DR Concepts (RPO, RTO, SLAs) |
| Topic 4: Prism Central Management | - DR Monitoring and Operations - Cluster and Site Management |
| Topic 5: Data Protection and Backup Integration | - Snapshot Management - Backup Solutions Integration |
逆境は人をテストすることができます。困難に直面するとき、勇敢な人だけはのんびりできます。あなたは勇敢な人ですか。もしIT認証の準備をしなかったら、あなたはのんびりできますか。もちろんです。 MogiExamのNutanixのNCP-BC-7.5試験トレーニング資料を持っていますから、どんなに難しい試験でも成功することができます。
質問 # 86
An organization requires a maximum data loss of 15 minutes for a Tier-1 application running on Nutanix AHV. Which configuration best meets this requirement?
正解:D
解説:
This question evaluates the administrator ' s ability to map business RPO (Recovery Point Objective) requirements to the appropriate Nutanix technology. A requirement for " maximum 15 minutes of data loss " means the system must replicate data at least every 15 minutes. Nutanix offers two primary ways to achieve this: traditional Asynchronous replication and Nearsync replication. While Async (Option D) can technically be configured for a 15-minute interval, it relies on standard, full snapshots which can be heavy and resource- intensive, potentially leading to performance lag if the data churn is high. Nearsync Replication (Option B) is specifically designed for these low-RPO scenarios (from 20 seconds up to 15 minutes) by using " Lightweight Snapshots " (LWS). LWS minimize the storage and I/O overhead compared to traditional snapshots, making Nearsync the more reliable and robust choice for Tier-1 applications. Furthermore, Nearsync is built to handle the constant, high-frequency data transfers required to maintain a strict 15-minute window without impacting application performance. Therefore, Nearsync with a 15-minute RPO is the " best " configuration because it is the purpose-built solution for the stated performance and data protection goals.
質問 # 87
An administrator is troubleshooting a hung replication. When checking the replication status, the complete percent and bytes completed do not increase. The administrator checks the Stargate logs on the destination cluster and confirms the writes are failing with " nfs status 28 " . Checking the container info on the destination cluster, free space on the container is 0. The administrator confirms that there is sufficient space available in the storage pool. What could be the reason for free space on the container to be 0?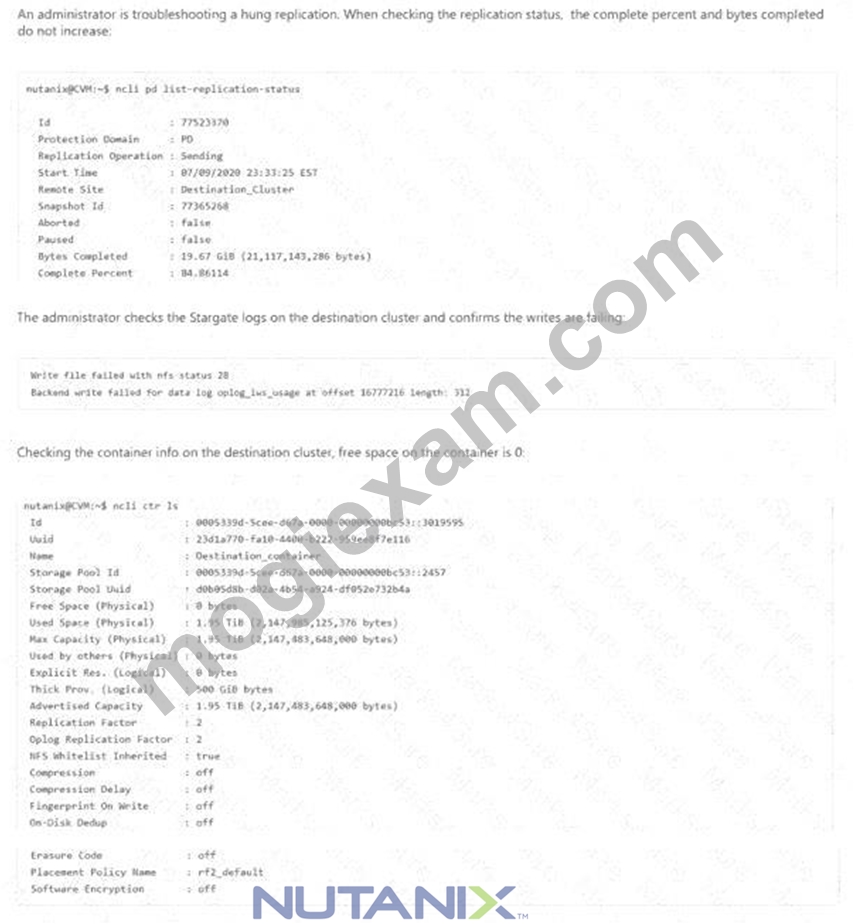
正解:D
解説:
In a Nutanix environment, " Advertised Capacity " is a logical limit (a quota) that an administrator can set on a specific storage container. Even if the physical storage pool has terabytes of free space, if a container ' s advertised capacity is reached, the hypervisor and the Nutanix services will perceive the container as being
100% full.
In this troubleshooting scenario, the " nfs status 28 " error code is a standard indicator for " No space left on device " . Since the administrator confirmed the pool is healthy, the logical limit on the container is the only remaining bottleneck. Replication jobs will " hang " because the destination Stargate service cannot write the incoming data blocks to a container that reports zero free space. To resolve this, the administrator must either increase the advertised capacity value in Prism or remove the limit entirely to allow the container to consume the available physical space in the pool. This highlights a common configuration " trap " where logical quotas-intended for multi-tenant management-can inadvertently block critical BCDR processes like replication if not monitored or sized correctly according to the protected VM growth.
質問 # 88
An administrator is creating a recovery plan between two availability zones. The production VMs use a subnet that does not exist at the recovery AZ. To ensure the VMs can successfully connect after a failover, what must be configured?
正解:C
解説:
When failing over a virtual machine between different physical locations or availability zones, it is common for the network topology at the recovery site to differ from the primary site. If a VM is recovered into a site where its original subnet is unavailable, it will lose connectivity.
To resolve this, Nutanix Recovery Plans include a " Network Mapping " section. The administrator must configure these mappings to explicitly define which production subnet at the source site corresponds to which valid subnet at the recovery site. During the failover process, the orchestrator uses this mapping to automatically re-configure the VM ' s virtual network interface (vNIC) to connect to the correct local VLAN or overlay network at the destination. While " matching subnet names " (Option D) can simplify management, it is not a requirement if the mapping is correctly defined. Synchronous replication (Option B) does not address the networking layer, as it is a storage-level feature. Network mapping is therefore the essential task for ensuring that workloads are not only recovered but also accessible following a failover.
質問 # 89
An administrator finds replications for Marketing VMs are failing to replicate. After doing some digging the administrator was able to find the following:
* Connectivity was confirmed on ports 2020 and 2009 between the clusters
* All other VMs are replicating successfully
* Cluster wide storage has plenty of remaining space
* No firewall exists between the sites
* Marketing VMs are running Windows, successful VMs are running Linux
What could be causing the Marketing VMs to fail replications?
正解:C
解説:
In a complex BCDR environment, replication failures that affect only a specific subset of virtual machines- while others on the same cluster succeed-usually point to a configuration mismatch rather than a general network or storage issue. Since the ports (2009 and 2020) are confirmed open and storage is available, the transport layer is functional. The fact that Linux VMs are succeeding while Windows (Marketing) VMs are failing suggests that the two groups may be mapped to different destination storage containers. In Nutanix replication, if a container mapping is explicitly set for one set of entities (the Linux VMs) but not for another (the Marketing VMs), the second group might be defaulting to a destination container that is either missing, misconfigured, or has restricted permissions. This specific scenario implies that the successful Linux VMs are benefiting from a correctly configured container mapping on the remote site, whereas the Marketing VMs are likely attempting to replicate to a location where mapping is invalid or non-existent. Troubleshooting this requires an administrator to verify the Prism Central container mapping settings to ensure that the storage targets for all protected categories are reachable and correctly associated with the destination storage pool.
質問 # 90
A Nutanix protection policy is configured with:
* RPO: 1 hour,
* Retention period: 5 days,
* Retention type: Roll-up.
After six days of continuous operation, approximately how many hourly recovery points will still be available for restores for the most recent 24-hour period?
正解:A
解説:
Nutanix uses a " Roll-up " retention strategy to optimize storage while maintaining a range of recovery options. This strategy keeps all high-frequency recovery points for the most recent period and then consolidates (rolls up) older snapshots into daily or weekly points as they age.
For a policy with a 1-hour RPO and 5-day retention, the system is designed to provide granular recovery for the immediate past. By default, Nutanix retention logic maintains the hourly snapshots for the current 24-hour window. As snapshots move past the 24-hour mark, they are " rolled up " into a single daily snapshot to save space while still providing a 5-day historical view. Therefore, after six days of operation, the administrator will find approximately 24 hourly recovery points for the most recent 24 hours, followed by several daily recovery points representing the previous four days. This approach balances the need for surgical " point-in- time " recovery (to combat recent data corruption or ransomware) with the need for long-term historical data, ensuring that the BCDR solution is both effective and storage-efficient.
質問 # 91
......
NCP-BC-7.5試験のMogiExam教材は専門家によって編集され、経験豊富な専門家によって承認されています。これらは、合格試験の論文と業界で人気の傾向に従って改訂および更新されます。 NCP-BC-7.5試験トレントの言語は理解しやすいものであり、NCP-BC-7.5試験問題はどの学習者にも適しています。 NCP-BC-7.5学習教材の内容は習得しやすく、重要な情報を簡素化しました。 NCP-BC-7.5テストの質問は、最新かつ有効な質問と回答を伝えるため、Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5学習がリラックスして効率的になります。
NCP-BC-7.5最新資料: https://www.mogiexam.com/NCP-BC-7.5-exam.html