2026年CertJukenの最新Professional-Machine-Learning-Engineer PDFダンプおよびProfessional-Machine-Learning-Engineer試験エンジンの無料共有:https://drive.google.com/open?id=1iKt4JDqlqdf9Lwc625-oARW7Ta8v8rbB
多くの人は結果が大丈夫で過程だけ重要ですって言いますが。GoogleのProfessional-Machine-Learning-Engineer試験にとってはそうではない。GoogleのProfessional-Machine-Learning-Engineer試験に合格するのはIT業界で働いているあなたに利益をもらわせることができます。もしあなたが試験に合格する決心があったら、我々のGoogleのProfessional-Machine-Learning-Engineerソフトを利用するのはあなたの試験に成功する有効な保障です。我々のGoogleのProfessional-Machine-Learning-Engineerソフトのデモをダウンロードしてみて我々CertJukenのあなたに合格させる自信を感じられます。
| Section | Objectives |
|---|---|
| Topic 1: Designing ML solutions | - ML architecture design
|
| Topic 2: Data preparation and processing | - Feature engineering
|
| Topic 3: ML model development | - Evaluation
|
| Topic 4: ML pipeline automation and orchestration | - Pipeline design
|
| Topic 5: Deployment and operations | - Monitoring and maintenance
|
>> Professional-Machine-Learning-Engineer復習時間 <<
Professional-Machine-Learning-Engineer認定試験問題には、高品質と効率に加えて、非常に高品質のサービスがあります。 Professional-Machine-Learning-Engineerテスト準備を使用すると、能力を向上させながら非常に楽しい経験をすることができます。私たちは常に最初に顧客を提唱しています。あなたの目標を達成するためにProfessional-Machine-Learning-Engineer学習教材を使用する場合、私たちは光栄に思います。また、Professional-Machine-Learning-Engineer pdfファイルにより、学習効率が向上し、限られた時間で最高の結果を得ることができます。 Professional-Machine-Learning-Engineer pdfファイルは、選択する必要がある最高の試験ツールです。
質問 # 144
You are developing a Kubeflow pipeline on Google Kubernetes Engine. The first step in the pipeline is to issue a query against BigQuery. You plan to use the results of thatquery as the input to the next step in your pipeline. You want to achieve this in the easiest way possible. What should you do?
正解:B
解説:
Kubeflow is an open source platform for developing, orchestrating, deploying, and running scalable and portable machine learning workflows on Kubernetes. Kubeflow Pipelines is a component of Kubeflow that allows you to build and manage end-to-end machine learning pipelines using a graphical user interface or a Python-based domain-specific language (DSL). Kubeflow Pipelines can help you automate and orchestrate your machine learning workflows, and integrate with various Google Cloud services and tools1 One of the Google Cloud services that you can use with Kubeflow Pipelines is BigQuery, which is a serverless, scalable, and cost-effective data warehouse that allows you to run fast and complex queries on large-scale data. BigQuery can help you analyze and prepare your data for machine learning, and store and manage your machine learning models2 To execute a query against BigQuery as the first step in your Kubeflow pipeline, and use the results of that query as the input to the next step in your pipeline, the easiest way to do that is to use the BigQuery Query Component, which is a pre-built component that you can find in the Kubeflow Pipelines repository on GitHub.
The BigQuery Query Component allows you to run a SQL query on BigQuery, and output the results as a table or a file. You can use the component's URL to load the component into your pipeline, and specify the query and the output parameters. You can then use the output of the component as the input to the next step in your pipeline, such as a data processing or a model training step3 The other options are not as easy or feasible. Using the BigQuery console to execute your query and then save the query results into a new BigQuery table is not a good idea, as it does not integrate with your Kubeflow pipeline, and requires manual intervention and duplication of data. Writing a Python script that uses the BigQuery API to execute queries against BigQuery is not ideal, as it requires writing custom code and handling authentication and error handling. Using the Kubeflow Pipelines DSL to create a custom component that uses the Python BigQuery client library to execute queries is not optimal, as it requires creating and packaging a Docker container image for the component, and testing and debugging the component.
References: 1: Kubeflow Pipelines overview 2: BigQuery overview 3: BigQuery Query Component
質問 # 145
A machine learning (ML) specialist wants to secure calls to the Amazon SageMaker Service API. The specialist has configured Amazon VPC with a VPC interface endpoint for the Amazon SageMaker Service API and is attempting to secure traffic from specific sets of instances and IAM users. The VPC is configured with a single public subnet.
Which combination of steps should the ML specialist take to secure the traffic? (Choose two.)
正解:A、E
解説:
Explanation/Reference: https://aws.amazon.com/blogs/machine-learning/private-package-installation-in-amazon- sagemaker-running-in-internet-free-mode/
質問 # 146
You work for a bank. You have created a custom model to predict whether a loan application should be flagged for human review. The input features are stored in a BigQuery table. The model is performing well and you plan to deploy it to production. Due to compliance requirements the model must provide explanations for each prediction. You want to add this functionality to your model code with minimal effort and provide explanations that are as accurate as possible What should you do?
正解:D
質問 # 147
You deployed an ML model into production a year ago. Every month, you collect all raw requests that were sent to your model prediction service during the previous month. You send a subset of these requests to a human labeling service to evaluate your model'sperformance. After a year, you notice that your model's performance sometimes degrades significantly after a month, while other times it takes several months to notice any decrease in performance. The labeling service is costly, but you also need to avoid large performance degradations. You want to determine how often you should retrain your model to maintain a high level of performance while minimizing cost. What should you do?
正解:D
解説:
The best option for determining how often to retrain your model to maintain a high level of performance while minimizing cost is to run training-serving skew detection batch jobs every few days. Training-serving skew refers to the discrepancy between the distributions of the features in the training dataset and the serving data. This can cause the model to perform poorly on the new data, as it is not representative of the data that the model was trained on. By running training-serving skew detection batch jobs, you can monitor the changes in the feature distributions over time, and identify when the skew becomes significant enough to affect the model performance. If skew is detected, you can send the most recent serving data to the labeling service, and use the labeled data to retrain your model. This option has the following benefits:
* It allows you to retrain your model only when necessary, based on the actual data changes, rather than on a fixed schedule or a heuristic. This can save you the cost of the labeling service and the retraining process, and also avoid overfitting or underfitting your model.
* It leverages the existing tools and frameworks for training-serving skew detection, such as TensorFlow
* Data Validation (TFDV) and Vertex Data Labeling. TFDV is a library that can compute and visualize descriptive statistics for your datasets, and compare the statistics across different datasets. Vertex Data Labeling is a service that can label your data with high quality and low latency, using either human labelers or automated labelers.
* It integrates well with the MLOps practices, such as continuous integration and continuous delivery (CI/CD), which can automate the workflow of running the skew detection jobs, sending the data to the labeling service, retraining the model, and deploying the new model version.
The other options are less optimal for the following reasons:
* Option A: Training an anomaly detection model on the training dataset, and running all incoming requests through this model, introduces additional complexity and overhead. This option requires building and maintaining a separate model for anomaly detection, which can be challenging and time-consuming. Moreover, this option requires running the anomaly detection model on every request, which can increase the latency and resource consumption of the prediction service. Additionally, this option may not capture the subtle changes in the feature distributions that can affect the model performance, as anomalies are usually defined as rare or extreme events.
* Option B: Identifying temporal patterns in your model's performance over the previous year, and creating a schedule for sending serving data to the labeling service for the next year, introduces additional assumptions and risks. This option requires analyzing the historical data and model performance, and finding the patterns that can explain the variations in the model performance over time. However, this can be difficult and unreliable, as the patterns may not be consistent or predictable, and may depend on various factors that are not captured by the data. Moreover, this option requires creating a schedule based on the past patterns, which may not reflect the future changes in the data or the environment. This can lead to either sending too much or too little data to the labeling service, resulting in either wasted cost or degraded performance.
* Option C: Comparing the cost of the labeling service with the lost revenue due to model performance degradation over the past year, and adjusting the frequency of model retraining accordingly, introduces additional challenges and trade-offs. This option requires estimating the cost of the labeling service and the lost revenue due to model performance degradation, which can be difficult and inaccurate, as they may depend on various factors that are not easily quantifiable or measurable. Moreover, this option requires finding the optimal balance between the cost and the performance, which can be subjective and variable, as different stakeholders may have different preferences and expectations. Furthermore, this option may not account for the potential impact of the model performance degradation on other aspects of the business, such as customer satisfaction, retention, or loyalty.
質問 # 148
You are training an LSTM-based model on Al Platform to summarize text using the following job submission script: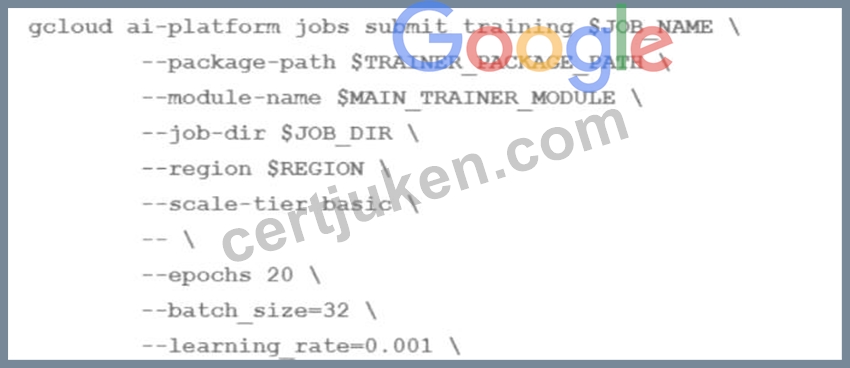
You want to ensure that training time is minimized without significantly compromising the accuracy of your model. What should you do?
正解:A
解説:
The training time of a machine learning model depends on several factors, such as the complexity of the model, the size of the data, the hardware resources, and the hyperparameters. To minimize the training time without significantly compromising the accuracy of the model, one should optimize these factors as much as possible.
One of the factors that can have a significant impact on the training time is the scale-tier parameter, which specifies the type and number of machines to use for the training job on AI Platform. The scale-tier parameter can be one of the predefined values, such as BASIC, STANDARD_1, PREMIUM_1, or BASIC_GPU, or a custom value that allows you to configure the machine type, the number of workers, and the number of parameter servers1 To speed up the training of an LSTM-based model on AI Platform, one should modify the scale-tier parameter to use a higher tier or a custom configuration that provides more computational resources, such as more CPUs, GPUs, or TPUs. This can reduce the training time by increasing the parallelism and throughput of the model training. However, one should also consider the trade-off between the training time and the cost, as higher tiers or custom configurations may incur higher charges2 The other options are not as effective or may have adverse effects on the model accuracy. Modifying the epochs parameter, which specifies the number of times the model sees the entire dataset, may reduce the training time, but also affect the model's convergence and performance. Modifying the batch size parameter, which specifies the number of examples per batch, may affect the model's stability and generalization ability, as well as the memory usage and the gradient update frequency. Modifying the learning rate parameter, which specifies the step size of the gradient descent optimization, may affect the model's convergence and performance, as well as the risk of overshooting or getting stuck in local minima3 References: 1: Using predefined machine types 2: Distributed training 3: Hyperparameter tuning overview
質問 # 149
......
CertJukenお客様が問題を解決できるように、当社は常に問題を最優先し、価値あるサービスを提供することを強く求めています。 Professional-Machine-Learning-Engineer質問トレントは、短時間で試験に合格し、認定資格を取得するのに役立つと確信しています。 Professional-Machine-Learning-Engineerガイドの質問を理解するのが待ち遠しいかもしれません。他の教材と比較した場合、当社の製品の品質がより高いことをお約束します。現時点では、Professional-Machine-Learning-Engineerガイドトレントのデモを無料でダウンロードできます。Professional-Machine-Learning-Engineer試験問題をご存知の場合は、ぜひお試しください。
Professional-Machine-Learning-Engineerテスト内容: https://www.certjuken.com/Professional-Machine-Learning-Engineer-exam.html
2026年CertJukenの最新Professional-Machine-Learning-Engineer PDFダンプおよびProfessional-Machine-Learning-Engineer試験エンジンの無料共有:https://drive.google.com/open?id=1iKt4JDqlqdf9Lwc625-oARW7Ta8v8rbB