Neueste Databricks Certified Data Engineer Professional Prüfung pdf & Certified-Data-Engineer-Professional Prüfung Torrent

Databricks Certified-Data-Engineer-Professional dumps von EchteFrage sind die unentbehrliche Prüfungsunterlagen, mit denen Sie sich auf Databricks Certified-Data-Engineer-Professional Zertifizierung vorbereiten. Der Wert dieser Unterlagen ist gleich wie die anderen Nachschlagsbücher. Diese Meinung ist nicht übertrieben. Wenn Sie diese Schulungsunterlagen zur Databricks Certified-Data-Engineer-Professional Zertifizierung benutzen, finden Sie es wirklich.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 2: Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use system tables for resource, cost, audit, and workload monitoring
|
| Topic 3: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
|
| Topic 4: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Topic 5: Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
| Topic 6: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Configure Databricks-to-Databricks Sharing
- 3. Share live Lakehouse data with external computing platforms
|
| Topic 7: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Analyze errors and remediate failed job runs
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
| Topic 8: Cost & Performance Optimisation | - Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Understand deletion vectors and liquid clustering
- 3. Apply data skipping and file pruning techniques
|
| Topic 9: Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
|
| Topic 10: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Develop User-Defined Functions using Pandas/Python UDFs
- Building and Testing ETL Pipelines
- 1. Use control flow operators in pipeline components
- 2. Compare streaming tables and materialized views
- 3. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 4. Use APPLY CHANGES APIs for change data capture
- 5. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 6. Develop unit and integration tests for data processing code
- 7. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 8. Configure environments, dependencies, memory, and retry behavior
|
>> Certified-Data-Engineer-Professional Zertifizierung <<
Certified-Data-Engineer-Professional Examsfragen, Certified-Data-Engineer-Professional Online Tests
Seit langem bieten wir EchteFrage vielfältige neueste Prüfungsunterlagen zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung. Zum Beispiel sind Databricks Certified-Data-Engineer-Professional Dumps von EchteFrage laut der neuesten IT-Zertifizierungsprüfung geschaffen. Wir können Ihnen die neusten Informationen über die Databricks Certified-Data-Engineer-Professional Prüfungen anbieten. Die Unterlagen beinhalten die veränderten Informationen und die neue Prüfungsfragensformen. So wenn Sie IT-Zertifizierungsprüfung ablegen wollen, sollen Sie am besten die Unterlagen von EchteFrage. Damit können Sie sich besser auf die Databricks Certified-Data-Engineer-Professional Prüfungen vorbereiten.
Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Prüfungsfragen mit Lösungen (Q119-Q124):
119. Frage
Which REST API call can be used to review the notebooks configured to run as tasks in a multi- task job?
- A. /jobs/runs/get
- B. /jobs/get
- C. /jobs/runs/get-output
- D. /jobs/list
- E. /jobs/runs/list
Antwort: B
Begründung:
https://docs.databricks.com/api/workspace/jobs/getresponses/settings/tasks/notebook_task/noteb ook_path
120. Frage
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs UI. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.
What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
- A. Can Manage
- B. Can Edit
- C. Can Read
- D. No permissions
- E. Can Run
Antwort: C
121. Frage
A data engineer is masking a column containing email addresses. The goal is to produce output strings of identical length for all rows, while generating different outputs for different email values.
Which SQL function should be used to achieve this?
- A. hash(email)
- B. sha2(email, 0)
- C. sha1(email)
- D. mask(email, '?')
Antwort: A
Begründung:
The hash() function in Databricks SQL returns a deterministic fixed-length integer (or hexadecimal string) derived from the input. When applied to sensitive identifiers like email addresses, it produces a unique value for each distinct input while ensuring uniform output size, making it suitable for anonymization where referential consistency is required.
Functions like mask() perform pattern-based substitutions that change string lengths, and sha1() or sha2() produce long hexadecimal strings of varying lengths (depending on hash size), which may not match requirements for fixed-length masking.
Therefore, the correct choice for fixed-length, deterministic pseudonymization of email addresses is hash(email), as it maintains analytical usability while anonymizing sensitive data.
122. Frage
A nightly job ingests data into a Delta Lake table using the following code:
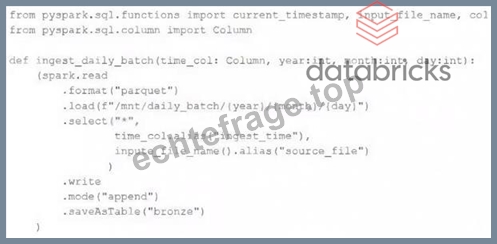
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
- A. return spark.read.option("readChangeFeed", "true").table ("bronze")
- B. return spark.readStream.table("bronze")
- C. return spark.readStream.load("bronze")
- D.
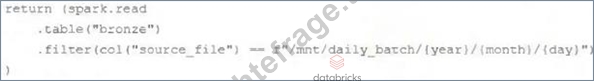
- E.
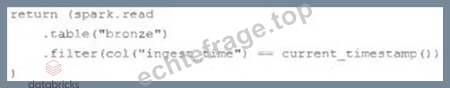
Antwort: D
Begründung:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
123. Frage
While reviewing a query's execution in the Databricks Query Profiler, a data engineer observes that the Top Operators panel shows a Sort operator with high Time Spent and Memory Peak metrics. The Spark UI also reports frequent data spilling. How should the data engineer address this issue?
- A. Increase the number of shuffle partitions to better distribute data.
- B. Switch to a broadcast join to reduce memory usage.
- C. Convert the sort operation to a filter operation.
- D. Repartition the DataFrame to a single partition before sorting.
Antwort: A
Begründung:
Increasing the number of shuffle partitions distributes the data across more tasks, reducing per- task memory pressure during the sort operation. This helps mitigate spilling by lowering memory peak usage per task and improves overall sort performance in large-scale distributed queries.
124. Frage
......
Die Ausbildungsmaterialien zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung aus EchteFrage sind nicht nur der Grundstein auf dem Weg zu Ihrem Erfolg, sie können Ihnen auch dabei helfen, Ihre Fähigkeiten in der IT-Branche effektiver zu entfalten. Nach mehrjährigen Bemühungen beträgt die Hit-Rate von Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung von EchteFrage bereits 100%. Wenn Sie die Zertifizierungsprüfung nicht bestehen, nachdem Sie unsere Fragenpool gekauft haben, werden wir alle Ihre bezahlten Summe zurückgeben.
Certified-Data-Engineer-Professional Examsfragen: https://www.echtefrage.top/Certified-Data-Engineer-Professional-deutsch-pruefungen.html
- Certified-Data-Engineer-Professional Online Test 💽 Certified-Data-Engineer-Professional Fragen&Antworten 🔇 Certified-Data-Engineer-Professional Fragen Antworten 🐎 Suchen Sie einfach auf 【 www.zertpruefung.ch 】 nach kostenloser Download von ( Certified-Data-Engineer-Professional ) 🏈Certified-Data-Engineer-Professional Prüfungsfragen
- Certified-Data-Engineer-Professional Prüfungs 🐤 Certified-Data-Engineer-Professional Praxisprüfung ⛑ Certified-Data-Engineer-Professional PDF 🤼 Suchen Sie auf ➡ www.itzert.com ️⬅️ nach ➡ Certified-Data-Engineer-Professional ️⬅️ und erhalten Sie den kostenlosen Download mühelos 👺Certified-Data-Engineer-Professional Online Test
- Certified-Data-Engineer-Professional Übungsmaterialien - Certified-Data-Engineer-Professional Lernführung: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Lernguide 😑 Öffnen Sie ▛ www.echtefrage.top ▟ geben Sie “ Certified-Data-Engineer-Professional ” ein und erhalten Sie den kostenlosen Download 🅰Certified-Data-Engineer-Professional Ausbildungsressourcen
- Certified-Data-Engineer-Professional Zertifizierungsantworten 🐽 Certified-Data-Engineer-Professional Fragenkatalog 🧲 Certified-Data-Engineer-Professional Fragen Antworten 🎎 Sie müssen nur zu 【 www.itzert.com 】 gehen um nach kostenloser Download von { Certified-Data-Engineer-Professional } zu suchen 🤳Certified-Data-Engineer-Professional Fragen&Antworten
- Certified-Data-Engineer-Professional Prüfungsfragen 🦟 Certified-Data-Engineer-Professional Zertifikatsfragen 💞 Certified-Data-Engineer-Professional Online Praxisprüfung 🐘 Suchen Sie jetzt auf 【 www.zertfragen.com 】 nach ➽ Certified-Data-Engineer-Professional 🢪 um den kostenlosen Download zu erhalten 🕕Certified-Data-Engineer-Professional Testfagen
- Certified-Data-Engineer-Professional Zertifizierungsantworten 🔓 Certified-Data-Engineer-Professional Ausbildungsressourcen 👜 Certified-Data-Engineer-Professional Zertifizierungsantworten 🌕 Suchen Sie auf der Webseite ➽ www.itzert.com 🢪 nach { Certified-Data-Engineer-Professional } und laden Sie es kostenlos herunter 👗Certified-Data-Engineer-Professional Prüfungs
- Certified-Data-Engineer-Professional Ausbildungsressourcen 🌖 Certified-Data-Engineer-Professional Ausbildungsressourcen 🏋 Certified-Data-Engineer-Professional Ausbildungsressourcen 🏬 Suchen Sie einfach auf 《 www.deutschpruefung.com 》 nach kostenloser Download von ⏩ Certified-Data-Engineer-Professional ⏪ ☔Certified-Data-Engineer-Professional Testfagen
- Certified-Data-Engineer-Professional Deutsche Prüfungsfragen 🌐 Certified-Data-Engineer-Professional Deutsche 💙 Certified-Data-Engineer-Professional Ausbildungsressourcen 🗓 Öffnen Sie die Webseite ✔ www.itzert.com ️✔️ und suchen Sie nach kostenloser Download von ➥ Certified-Data-Engineer-Professional 🡄 💦Certified-Data-Engineer-Professional Fragen&Antworten
- Certified-Data-Engineer-Professional Testengine 🐤 Certified-Data-Engineer-Professional PDF 🌺 Certified-Data-Engineer-Professional Demotesten 🎶 Öffnen Sie die Webseite ✔ de.fast2test.com ️✔️ und suchen Sie nach kostenloser Download von { Certified-Data-Engineer-Professional } 🕚Certified-Data-Engineer-Professional Fragenpool
- Certified-Data-Engineer-Professional Prüfungsfragen 🌝 Certified-Data-Engineer-Professional Prüfungs 🤲 Certified-Data-Engineer-Professional Zertifikatsfragen 🥶 URL kopieren 【 www.itzert.com 】 Öffnen und suchen Sie ➤ Certified-Data-Engineer-Professional ⮘ Kostenloser Download 🦀Certified-Data-Engineer-Professional Deutsche
- Certified-Data-Engineer-Professional Testengine 🔰 Certified-Data-Engineer-Professional PDF ↘ Certified-Data-Engineer-Professional Prüfungs 🍑 Geben Sie ➽ www.pass4test.de 🢪 ein und suchen Sie nach kostenloser Download von ➤ Certified-Data-Engineer-Professional ⮘ ⛰Certified-Data-Engineer-Professional Fragenpool
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, pastebin.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes