Es ist nicht unmöglich, die Nutanix NCP-BC-7.5 Prüfung leicht zu bestehen. Dieses Gefühl haben schon viele Benutzer der Nutanix NCP-BC-7.5 Prüfungssoftware von unserer ZertSoft empfunden. Dieses Gefühl können Sie auch empfinden, solange Sie unsere kostenlose Demo probieren. Wir sind verantwortlich für jeder Kunde, der unsere Produkte wählt, und garantieren, dass unsere Kunden immer die neueste Version von Nutanix NCP-BC-7.5 Prüfungssoftware benutzen.
| Section | Objectives |
|---|---|
| Topic 1: Recovery Operations | - Recovery Plans and Orchestration - Failover and Failback Procedures - Test Recovery Workflows |
| Topic 2: Prism Central Management | - DR Monitoring and Operations - Cluster and Site Management |
| Topic 3: Disaster Recovery Fundamentals | - DR Concepts (RPO, RTO, SLAs) - Business Continuity Principles |
| Topic 4: Nutanix Disaster Recovery Architecture | - Replication Types (Sync/Async) - Nutanix Leap Overview - Protection Domains |
| Topic 5: Data Protection and Backup Integration | - Snapshot Management - Backup Solutions Integration |
>> Nutanix NCP-BC-7.5 Prüfungsmaterialien <<
Wenn Sie die Fragen und Antworten zur Nutanix NCP-BC-7.5 Zertifizierungsprüfung kaufen, können Sie nicht nur die Nutanix NCP-BC-7.5 Zertifizierungsprüfung erfolgreich bestehen, sonder einen einjährigen kostenlosen Update-Service genießen. Falls Sie in der Prüfung durchfallen, zahlen wir Ihnen die gesammte Summe zurück. Sie können im Internet teilweise die Fragen und Antworten zur Nutanix NCP-BC-7.5 Zertifizierungsprüfung kostenlos als Probe herunterladen, um die Zuverlässigkeit unserer Produkte zu prüfen.
77. Frage
An administrator needs to provide the QA team with a VM state from four days ago to test an older browser version. However, the current production VM contains new application code and security patches that must not be deleted or overwritten. Which restore operation should the administrator perform to meet this requirement?
Antwort: A
Begründung:
Nutanix offers several ways to recover data, ranging from full VM reverts to granular file-level access. In this scenario, the key requirement is to access historical data (from four days ago) without modifying or destroying the current production VM ' s state. Self-Service Restore (SSR) is the most efficient and least disruptive method to achieve this. SSR, which requires Nutanix Guest Tools (NGT) to be installed, allows an administrator or user to mount a historical snapshot disk directly to the existing VM as a new, temporary volume. This allows the QA team to browse the file system of the " four-day-old " state and copy the specific older browser version they need while the production application continues to run undisturbed with its new code and patches. An " In-place Restore " (Option C) would be disastrous here because it would roll back the entire VM, overwriting the new patches. A " Clone " (Option D) would work but is less efficient as it consumes additional vCPU, RAM, and full storage overhead for an entirely new VM. SSR provides the surgical precision needed for file-level testing while maintaining the integrity of the live production environment.
78. Frage
What is the bandwidth limit of a single Nutanix Cloud Gateway for IPSec traffic?
Antwort: D
Begründung:
The Nutanix Cloud Gateway serves as a critical bridge between on-premises Nutanix clusters and the Nutanix Cloud Availability Zone (AZ). Its primary role is to provide a secure, encrypted tunnel for replicating recovery points and managing disaster recovery orchestration metadata. When utilizing standard IPSec for this traffic, the system architecture imposes certain throughput limitations based on the processing capabilities of the gateway instance. For a single Nutanix Cloud Gateway, the maximum supported bandwidth for IPSec- encrypted traffic is 1 Gbps.
This 1 Gbps limit is an important consideration for BCDR planning, as it defines the maximum " Snapshot-on- wire " throughput available for a given protection policy. If an organization has a high data change rate (churn) that exceeds 1 Gbps of sustained replication traffic, the Recovery Point Objective (RPO) may be at risk of lag. While the physical network link might be 10 Gbps or higher, the encryption overhead of the IPSec protocol within the gateway VM is the limiting factor. To achieve higher aggregate throughput, administrators would need to deploy multiple gateways or consider high-performance direct connectivity options if available.
Understanding this 1 Gbps threshold ensures that administrators can accurately size their replication windows and manage expectations for initial seed transfers and ongoing delta synchronization to the cloud AZ.
79. Frage
An administrator has recently completed the initial configuration of Nutanix Disaster Recovery for a production environment. Protection Policies and Recovery Plans have been configured and validated by the senior infrastructure team.
The administrator has confirmed that the expected categories are correctly associated with both the Protection Policies and Recovery Plans. During a scheduled test failover, the administrator notices that several VMs are missing from the recovery.
The administrator reviews the environment and notes the following:
* The Protection Summary tab does not show any warnings or errors
* No replication tasks are currently ongoing
* The missing VMs were all deployed within the last two weeks as part of a new application rollout
* The missing VMs are running on the same cluster as other VMs that recovered successfully during the test failover
* The application team followed the standard VM deployment checklist but did not coordinate with the infrastructure team during provisioning Given this information, what is the most likely cause of the missing VMs?
Antwort: C
Begründung:
Modern Nutanix Disaster Recovery (Leap) relies on " Categories " to automate the inclusion of virtual machines into Protection Policies and Recovery Plans. When a Protection Policy is created, it is typically applied to a category (e.g., AppType:SQL) rather than individual VM names.
In this scenario, the newly deployed VMs were missed during a test failover despite other VMs on the same cluster recovering successfully. The most likely root cause is that the application team, working independently, failed to assign the required categories to the new VMs during the provisioning process.
Because the VMs lacked the correct category tags, the Nutanix Protection Policy did not " see " them, and consequently, no recovery points were ever created for them. This is a common operational failure in environments where " infrastructure as code " or strict provisioning standards are not enforced. Recovery Plans (Option A) do not need manual re-synchronization for new VMs if the categories are correctly mapped.
While an initial sync is required (Option D), it would typically show a task or progress rather than just leaving the VMs " missing " from the entire protection summary. Therefore, verifying category assignment is the primary troubleshooting step.
80. Frage
An administrator is troubleshooting a hung replication. When checking the replication status, the complete percent and bytes completed do not increase. The administrator checks the Stargate logs on the destination cluster and confirms the writes are failing with " nfs status 28 " . Checking the container info on the destination cluster, free space on the container is 0. The administrator confirms that there is sufficient space available in the storage pool. What could be the reason for free space on the container to be 0?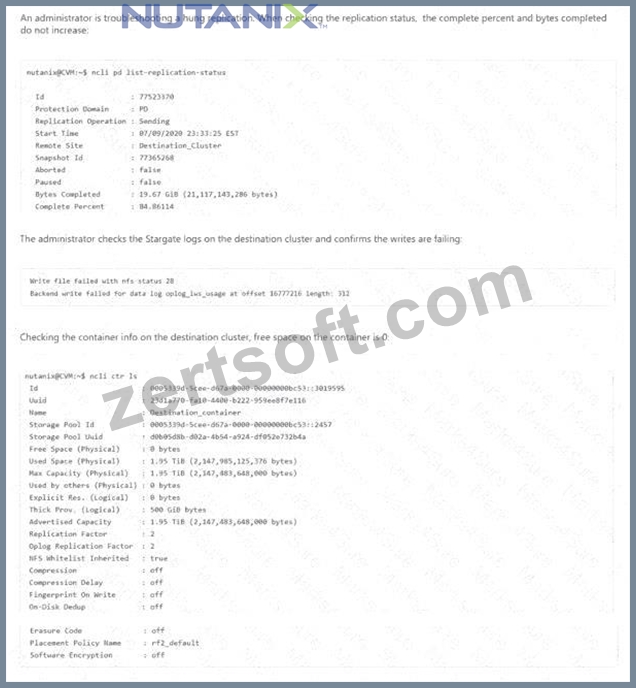
Antwort: C
Begründung:
In a Nutanix environment, " Advertised Capacity " is a logical limit (a quota) that an administrator can set on a specific storage container. Even if the physical storage pool has terabytes of free space, if a container ' s advertised capacity is reached, the hypervisor and the Nutanix services will perceive the container as being
100% full.
In this troubleshooting scenario, the " nfs status 28 " error code is a standard indicator for " No space left on device " . Since the administrator confirmed the pool is healthy, the logical limit on the container is the only remaining bottleneck. Replication jobs will " hang " because the destination Stargate service cannot write the incoming data blocks to a container that reports zero free space. To resolve this, the administrator must either increase the advertised capacity value in Prism or remove the limit entirely to allow the container to consume the available physical space in the pool. This highlights a common configuration " trap " where logical quotas-intended for multi-tenant management-can inadvertently block critical BCDR processes like replication if not monitored or sized correctly according to the protected VM growth.
81. Frage
Which two Data Protection technologies are compatible with Self-Service Restore? (Choose two.)
Antwort: B
Begründung:
Self-Service Restore (SSR) is a Nutanix guest-level feature that empowers users to mount snapshots as local drives to recover individual files without administrative intervention. For SSR to function, the underlying data protection mechanism must support the specific metadata and disk-attachment hooks required by Nutanix Guest Tools (NGT). Asynchronous (Async) replication schedules are a primary supported technology for SSR because they create standard, persistent recovery points that are easily indexed by the SSR agent within the guest OS. While the question asks to " Choose two, " it is important to note that Nutanix also generally supports SSR for Synchronous replication (Option C), as both methods produce the point-in-time vDisk snapshots necessary for the mounting process.
Conversely, certain high-frequency technologies like NearSync (at very low RPOs) or complex storage entities like Volume Groups (VGs) have historically faced limitations with the SSR mounting workflow due to the way metadata is handled or how disks are presented to the hypervisor. In a production environment, an administrator must ensure that NGT is fully functional on the VM and that the VM is part of a compatible Protection Policy to enable the SSR " snapshot-to-drive " mapping. This capability is essential for balancing operational efficiency with user-led data recovery, as it offloads simple " deleted file " requests from the infrastructure team while leveraging the existing BCDR snapshot architecture.
82. Frage
......
Die Zertifizierungsantworten zur Nutanix NCP-BC-7.5 Zertifizierungsprüfun von ZertSoft werden von IT-Eliten seit mehr als 10 Jahre durch ihre Forschung und Praxis gesammelt. ZertSoft hat viele neueste und genaueste Prüfungsunterlagen. ZertSoft ist für Ihren Erfolg vorhanden. Es bedeutet, dass Sie Erfolg wählen, wenn Sie ZertSoft wählen. Wenn Sie Nutanix NCP-BC-7.5 Zertifizierungsprüfungen leicht bestehen wollen, ist ZertSoft die einzige Wahl für Sie.
NCP-BC-7.5 Vorbereitungsfragen: https://www.zertsoft.com/NCP-BC-7.5-pruefungsfragen.html