P.S. Free & New DP-750 dumps are available on Google Drive shared by PracticeDump: https://drive.google.com/open?id=1w_HhfnTUMVxiMXTnaUCiLxmcKELo63SC
Our DP-750 exam guide has high quality of service. We provide 24-hour online service. If you have any questions in the course of using the DP-750 exam questions, you can contact us by email. We will provide you with excellent after-sales service with the utmost patience and attitude. And we will give you detailed solutions to any problems that arise during the course of using the DP-750 practice torrent. And our DP-750 study materials welcome your supervision and criticism. With the company of our DP-750 study materials, you will find the direction of success.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Data quality and validation
|
| Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
DP-750 practice materials can expedite your review process, inculcate your knowledge of the exam and last but not the least, speed up your pace of review dramatically. The finicky points can be solved effectively by using our DP-750 practice materials. Some practice materials keep droning on the useless points of knowledge. In contrast, being venerated for high quality and accuracy rate, our DP-750 practice materials received high reputation for their efficiency and accuracy rate originating from your interests, and the whole review process may cushier than you have imagined before.
NEW QUESTION # 48
You have an Azure Databricks workspace that contains a Git folder and uses Azure Repos as the Git provider.
From the main branch, you create a branch named Branch1. You commit changes to Branch1.
You need to incorporate the changes from Branch1 into main The solution must preserve the commit history in the repository. Which command should you run?
Answer: D
Explanation:
The correct answer is A - merge.
A Git merge combines the histories of two branches by creating a merge commit that joins them. Every individual commit from Branch1 remains visible in the repository log - the full development history is preserved. This is the requirement: 'the solution must preserve the commit history in the repository.' Option C (rebase) moves Branch1's commits on top of main by replaying them as new commits with new hashes. The end result looks like a linear history, but the original commit hashes are rewritten - the prior history is not preserved in its original form. For a shared repository, rebase rewrites public history, which is considered problematic.
Option B (pull) fetches remote changes and merges or rebases them into the current branch - it's used to sync with a remote, not to incorporate a feature branch. Option D (push) sends local commits to the remote but doesn't incorporate any branch into another.
Reference: https://learn.microsoft.com/en-us/azure/databricks/repos/git-operations-with-repos
NEW QUESTION # 49
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1.
Table1 is written by batch jobs every hour and is queried frequently by filtering two columns named Customerid and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.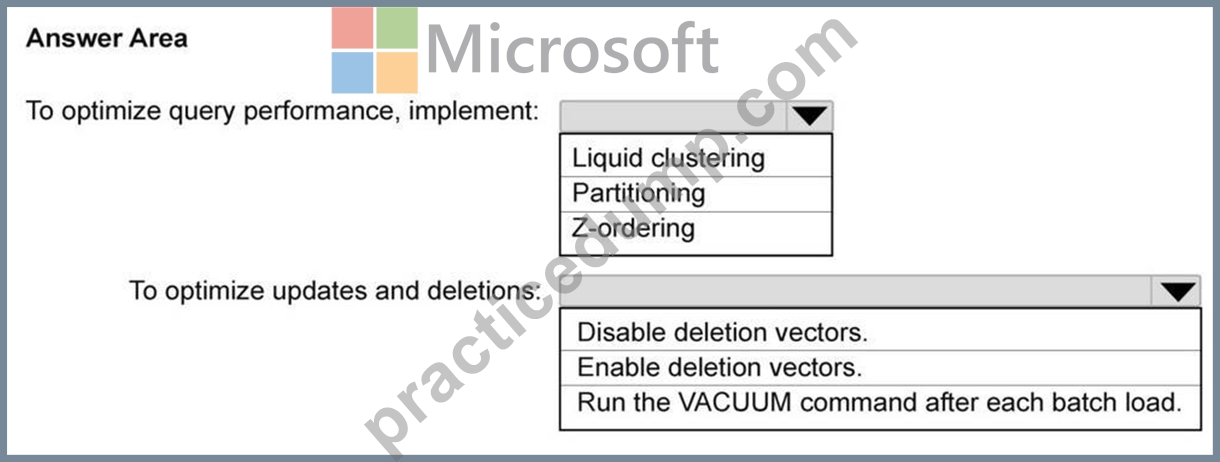
Answer:
Explanation: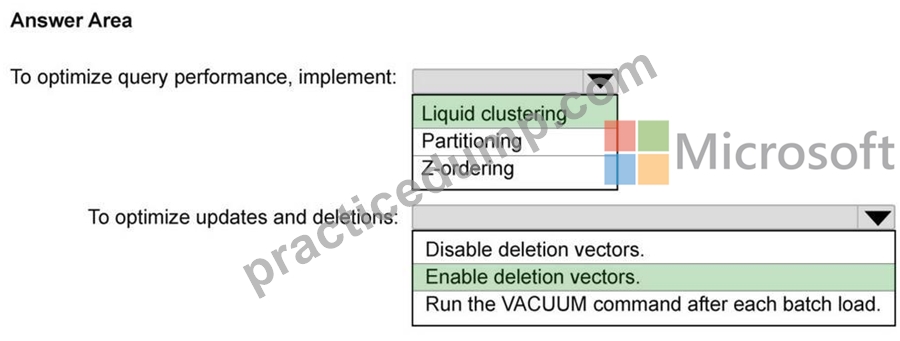
NEW QUESTION # 50
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
- Ensure that amount is always greater than 0.
- Prevent an update to Table1 from being committed when data that
violates rule1 is detected.
Which statement should you execute?
Answer: D
Explanation:
To ensure the data validation rule forces the pipeline update to abort and roll back transactions when data violates the condition, you must use a "fail" expectation operator. In Databricks Lakeflow Spark Declarative Pipelines (SDP), the command/syntax depends on whether your pipeline is written in Python or SQL.
Python Implementation
If your pipeline uses Python, apply the @dp.expect_or_fail decorator above your table definition (note: dp is the standard alias for the databricks.pipelines module in Lakeflow SDP):
dp.expect_or_fail("amount_greater_than_zero", "amount > 0")
Reference:
https://docs.databricks.com/aws/en/ldp/expectations
NEW QUESTION # 51
You have an Azure Databricks workspace.
Users report that a Databricks notebook that runs each day takes longer than expected to run.
When reading the Directed Acyclic Graph (DAG), you discover the following issues concerning the Apache Spark stage:
* Most tasks in the stage finish quickly.
* A few tasks in the stage run more slowly.
* The CPU is underutilized at the end of the stage.
* The slow tasks process many more input records.
* The stage is blocked while it waits for the few slow tasks.
What is the root cause of the issues?
Answer: C
NEW QUESTION # 52
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.dropna(subset=["order_amount"])
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 53
......
Our company has taken a lot of measures to ensure the quality of DP-750 preparation materials. It is really difficult for yourself to hire a professional team, regularly investigate market conditions, and constantly update our DP-750 exam questions. But we have all of them done for you. And our DP-750 study braindumps have the advantage of high-effective. Just look at our pass rate of our loyal customers, with the help of our DP-750 learning guide, 98% of them passed the exam successfully.
Reliable DP-750 Test Labs: https://www.practicedump.com/DP-750_actualtests.html
2026 Latest PracticeDump DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=1w_HhfnTUMVxiMXTnaUCiLxmcKELo63SC