What's more, part of that PDFDumps Databricks-Certified-Data-Analyst-Associate dumps now are free: https://drive.google.com/open?id=1bo4g4gQcpeE1NyG1HD1_2zqrIdbgUQJP
You may find that there are a lot of buttons on the website which are the links to the information that you want to know about our Databricks-Certified-Data-Analyst-Associate exam braindumps. Also the useful small buttons can give you a lot of help on our Databricks-Certified-Data-Analyst-Associate study guide. Some buttons are used for hide or display answers. What is more, there are extra place for you to make notes below every question of the Databricks-Certified-Data-Analyst-Associate practice quiz. Don't you think it is quite amazing? Just come and have a try!
| Section | Weight | Objectives |
|---|---|---|
| Creating Dashboards and Visualizations in Databricks | 16% | - Filtering and interactivity - Visualization types and best practices - Scheduling and sharing dashboards - Dashboard creation and layout |
| Analyzing Queries | 15% | - Performance optimization - Query history and auditing - Execution plans and analysis - Liquid clustering and indexing |
| Securing Data | 8% | - Data governance policies - Access control and permissions - Secure storage and compliance |
| Understanding of Databricks Data Intelligence Platform | 11% | - Lakehouse platform fundamentals - Workspace navigation and interface - Core architecture and components |
| Data Modeling with Databricks SQL | 5% | - Schema design principles - Delta table structure - Performance-oriented modeling |
| Importing Data | 5% | - S3 and cloud storage integration - UI-based data ingestion - Delta Sharing - API and Auto Loader - Databricks Marketplace |
| Developing, Sharing, and Maintaining AI/BI Genie Spaces | 12% | - Maintenance and improvement - Natural language query setup - Genie space setup and configuration - Access control and sharing |
| Executing Queries using Databricks SQL and Databricks SQL Warehouses | 20% | - Aggregations and grouping - Creating and managing views - Joining and combining datasets - Warehouse configuration and performance - ANSI SQL syntax and functions |
| Managing Data | 8% | - Discovering and registering datasets - Dataset versioning and management - Data cleaning and preparation - Unity Catalog usage |
>> Databricks Databricks-Certified-Data-Analyst-Associate Latest Dumps Free <<
Our company is a professional exam dumps material providers, with occupying in this field for years, and we are quite familiar with compiling the Databricks-Certified-Data-Analyst-Associate exam materialls. If you choose us, we will give you free update for one year after purchasing. Besides, the quality of Databricks-Certified-Data-Analyst-Associate Exam Dumps is high, they contain both questions and answers, and you can practice first before seeing the answers. Choosing us means you choose to pass the exam successfully.
NEW QUESTION # 68
A data analyst has a series of queries in a SQL program. The data analyst wants this program to run every day. They only want the final query in the program to run on Sundays. They ask for help from the data engineering team to complete this task.
Which of the following approaches could be used by the data engineering team to complete this task?
Answer: A
Explanation:
Option B is correct. The program can be scheduled to run daily as a Databricks job, and Python control flow can determine whether the final query runs only when the current day is Sunday. Databricks jobs support scheduled execution, and PySpark notebooks can run SQL through Spark while using Python logic around those commands. Official Databricks extract: jobs can be configured "to run it on a time-based schedule," and spark.sql/Spark DataFrame operations allow Python-based workflows to interact with SQL data.
NEW QUESTION # 69
A data engineering team has created a Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables. The microbatches are triggered every minute.
A data analyst has created a dashboard based on this gold-level data. The project stakeholders want to see the results in the dashboard updated within one minute or less of new data becoming available within the gold-level tables.
Which of the following cautions should the data analyst share prior to setting up the dashboard to complete this task?
Answer: D
Explanation:
A Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables every minute requires a high level of compute resources to handle the frequent data ingestion, processing, and writing. This could result in a significant cost for the organization, especially if the data volume and velocity are large. Therefore, the data analyst should share this caution with the project stakeholders before setting up the dashboard and evaluate the trade-offs between the desired refresh rate and the available budget. The other options are not valid cautions because:
B) The gold-level tables are assumed to be appropriately clean for business reporting, as they are the final output of the data engineering pipeline. If the data quality is not satisfactory, the issue should be addressed at the source or silver level, not at the gold level.
C) The streaming data is an appropriate data source for a dashboard, as it can provide near real-time insights and analytics for the business users. Structured Streaming supports various sources and sinks for streaming data, including Delta Lake, which can enable both batch and streaming queries on the same data.
D) The streaming cluster is fault tolerant, as Structured Streaming provides end-to-end exactly-once fault-tolerance guarantees through checkpointing and write-ahead logs. If a query fails, it can be restarted from the last checkpoint and resume processing.
E) The dashboard can be refreshed within one minute or less of new data becoming available in the gold-level tables, as Structured Streaming can trigger micro-batches as fast as possible (every few seconds) and update the results incrementally. However, this may not be necessary or optimal for the business use case, as it could cause frequent changes in the dashboard and consume more resources. Reference: Streaming on Databricks, Monitoring Structured Streaming queries on Databricks, A look at the new Structured Streaming UI in Apache Spark 3.0, Run your first Structured Streaming workload
NEW QUESTION # 70
A data analyst has a managed table table_name in database database_name. They would now like to remove the table from the database and all of the data files associated with the table. The rest of the tables in the database must continue to exist.
Which of the following commands can the analyst use to complete the task without producing an error?
Answer: C
Explanation:
The DROP TABLE command removes a table from the metastore and deletes the associated data files. The syntax for this command is DROP TABLE [IF EXISTS] [database_name.]table_name;. The optional IF EXISTS clause prevents an error if the table does not exist. The optional database_name. prefix specifies the database where the table resides. If not specified, the current database is used. Therefore, the correct command to remove the table table_name from the database database_name and all of the data files associated with it is DROP TABLE database_name.table_name;. The other commands are either invalid syntax or would produce undesired results. Reference: Databricks - DROP TABLE
NEW QUESTION # 71
A data analyst runs the following command:
SELECT age, country
FROM my_table
WHERE age > = 75 AND country = ' canada ' ;
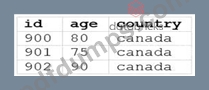
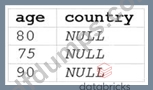
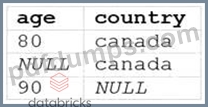
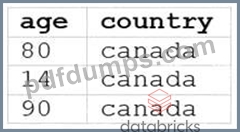
Which of the following tables represents the output of the above command?
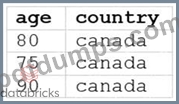
Answer: E
Explanation:
The SQL query provided is designed to filter out records from "my_table" where the age is 75 or above and the country is Canada. Since I can't view the content of the links provided directly, I need to rely on the image attached to this question for context. Based on that, Option E (the image attached) represents a table with columns "age" and "country", showing records where age is 75 or above and country is Canada. References:
The answer can be inferred from understanding SQL queries and their outputs as per Databricks documentation: Databricks SQL
NEW QUESTION # 72
After running DESCRIBE EXTENDED accounts.customers;, the following was returned: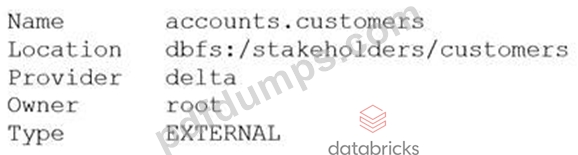
Now, a data analyst runs the following command:
DROP accounts.customers;
Which of the following describes the result of running this command?
Answer: E
Explanation:
the accounts.customers table is an EXTERNAL table, which means that it is stored outside the default warehouse directory and is not managed by Databricks. Therefore, when you run the DROP command on this table, it only removes the metadata information from the metastore, but does not delete the actual data files from the file system. This means that you can still access the data using the location path (dbfs:/stakeholders
/customers) or create another table pointing to the same location. However, if you try to query the table using its name (accounts.customers), you will get an error because the table no longer exists in the metastore. References: DROP TABLE | Databricks on AWS, Best practices for dropping a managed Delta Lake table - Databricks
NEW QUESTION # 73
......
The Databricks Databricks-Certified-Data-Analyst-Associate certification exam is one of the valuable credentials designed to demonstrate a candidate's technical expertise in information technology. They can remain current and competitive in the highly competitive market with the Databricks-Certified-Data-Analyst-Associate certificate. For novices as well as seasoned professionals, the Databricks Certified Data Analyst Associate Exam Questions provide an excellent opportunity to not only validate their skills but also advance their careers.
Databricks-Certified-Data-Analyst-Associate Actual Dump: https://www.pdfdumps.com/Databricks-Certified-Data-Analyst-Associate-valid-exam.html
P.S. Free & New Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by PDFDumps: https://drive.google.com/open?id=1bo4g4gQcpeE1NyG1HD1_2zqrIdbgUQJP