HPE7-S02試験の参考資料のユーザーは、専門家、学生、高度な文化の学生など、幅広い分野をカバーしています。これは、HPE7-S02学習教材の言語形式が理解しやすいためです。どんな情報を勉強しても、初心者であることやデータを読んでいないことを心配する必要はありません。そして、HPE7-S02テストの質問は多くの専門家によって準備されています。 HPE7-S02学習ガイドの内容は、すべてのレベルの候補者にとって非常に簡単に理解できます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: AI Workshops and HPE AI Essentials Platform | 15% | - Customer engagement and assessment - Platform capabilities and deployment |
| Topic 2: Solution Optimization and Security | 5% | - Security best practices - Efficiency and resilience |
| Topic 3: NVIDIA AI Enterprise and Model Serving | 10% | - Model serving architecture and optimization - Software deployment and management |
| Topic 4: Integration with Third-Party Platforms | 15% | - VMware integration - Red Hat OpenShift and Kubernetes integration |
| Topic 5: High Performance Computing (HPC) Design and Management | 10% | - Management and monitoring - Architecture and scaling |
| Topic 6: HPE ProLiant Gen12 for AI | 20% | - AI-optimized compute design - Server architecture and components - GPU integration and configuration |
| Topic 7: HPE AI Essentials: Data Analytics and Data Science | 15% | - Data pipelines and processing - Analytics and machine learning tools |
| Topic 8: Troubleshooting HPE Private Cloud AI | 10% | - Performance tuning and optimization - Issue diagnosis and resolution |
あなたはすぐHPE7-S02試験に参加したいかもしれません。そうすれば、自分の能力を有る分野で証明できます。しかし、HPE7-S02試験のために、どんな資料がいいですか。もちろん、HPE7-S02問題集は一番いいです。HPE7-S02問題集の内容は精確で、全面的です。HPE7-S02問題集について、私たちはあなたのお問い合わせをお待ちします。
質問 # 26
What is one action that an HPE Private Cloud AI Administrator can perform from the Alerts view in HPE AI Essentials?
正解:A
解説:
C is correct. The Alerts view in HPE AI Essentials is designed to move an administrator from a detected condition to the evidence needed for diagnosis. From an alert, the administrator can open the logs for the pod associated with that alert. That is materially different from taking a remediation action such as restarting a pod: the Alerts interface provides observability and troubleshooting context, while restart or recovery actions are performed through the appropriate Kubernetes or platform-management workflow. Alert forwarding is separately configured in the platform's observability settings rather than as a per-alert action, and HPE GreenLake does not provide an alert-correlation function from this local Alerts view.
This is an important operational distinction for the exam. HPE Private Cloud AI troubleshooting follows an evidence-first workflow: identify the alert, inspect the affected workload and its logs, and then determine the corrective action. Pod logs can expose image-pull failures, scheduling problems, resource exhaustion, application exceptions, or service communication errors without immediately changing system state.
References/topics: Advanced HPE Compute Solutions, Rev. 26.21, Module 7 "Troubleshooting HPE Private Cloud AI," especially alerts and solution-provided tools; HPE AI Essentials Software documentation,
"Viewing Alerts and Notifications."
質問 # 27
Which correctly describes an aspect of the AI software stack for HPE Cray XD systems?
正解:C
解説:
D is correct. HPE Cray XD systems use a conventional layered management model: platform firmware is managed through standards-based interfaces such as Redfish, while the host operating environment is Linux- based. This separation is appropriate for HPC because firmware lifecycle, hardware telemetry, node provisioning, and operating-system management are distinct administrative functions even when they are coordinated by cluster-management tooling.
Option A overstates the role of HPE GreenLake. HPE Cray XD environments are not fundamentally managed as a multi-system HPC control plane through GreenLake. Option B misnames and mischaracterizes HPE Performance Cluster Manager (HPCM); HPCM is cluster provisioning and management software, not the AI development environment itself. Option C is false because HPE does not provide a single combined firmware- and-OS image that replaces the normal platform firmware and Linux software stack.
An integrator should understand both layers: Redfish/BMC interfaces expose node hardware management and telemetry, while Linux and HPC software provide the runtime environment for schedulers, MPI, accelerators, storage clients, and applications.
References/topics: Advanced HPE Compute Solutions, Rev. 26.21, Module 9 "HPE Cray management" and
"HPE Cray firmware and software"; HPE Cray XD management documentation.
質問 # 28
A customer has HPE Cray XD systems, an HPE Slingshot network that includes HPE Slingshot Fabric Manager, HPE Performance Cluster Manager (HPCM), HPE Slingshot AIOps Software, and SchedMD Slurm.
Which tool provides heatmaps and interactive topologies that help you find trouble spots in the network performance?
正解:D
解説:
A is correct. HPE Slingshot AIOps Software is the analytics and visualization layer designed to expose network performance behavior across a Slingshot fabric. It provides topology-oriented views and telemetry heatmaps that allow an administrator to identify regions with abnormal bandwidth use, congestion, or other performance hot spots. Those visualizations are particularly useful when correlating network behavior with application or job activity.
HPE Slingshot Fabric Manager has a different primary role: fabric configuration, management, discovery, and operational control. SchedMD Slurm schedules jobs and allocates compute resources; although job information can be correlated with infrastructure telemetry, Slurm does not provide the Slingshot network heatmap interface described. HPE Performance Cluster Manager manages cluster provisioning and lifecycle operations rather than serving as the specialized Slingshot performance-analytics application.
The tools are complementary. Fabric Manager controls the network, HPCM manages the cluster, Slurm manages workload scheduling, and Slingshot AIOps helps diagnose how traffic is behaving on the fabric.
References/topics: Advanced HPE Compute Solutions, Rev. 26.21, Modules 9 and 10, HPE Cray management and HPC networking; HPE Slingshot AIOps Software User Guide, system-wide and telemetry heatmap views.
質問 # 29
You are planning to demonstrate how you can use KServe to run NIMs on HPE Private Cloud AI. You have downloaded the CodeLlama-70B-Instruct model to a volume in your namespace named demo-model.
The objects that you are planning to deploy are shown below: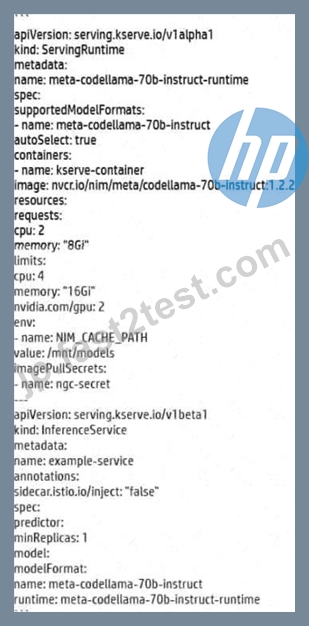
What change should you make to the objects?
正解:A
解説:
D is correct after correcting the YAML location to spec.predictor.model.storageUri. The ServingRuntime describes the runtime container capable of serving the model; the InferenceService describes the particular model instance to deploy. Because the CodeLlama model files already reside on a persistent volume claim named demo-model, the InferenceService must tell KServe where those model artifacts are stored. A PVC URI is therefore supplied through the model's storageUri field, for example pvc://demo-model.
Option A is structurally wrong because modelFormat.name identifies the model format understood by the ServingRuntime; it is not a storage location. Option B incorrectly assigns model storage to the ServingRuntime specification. Option C changes the NIM cache directory inside the container but does not tell KServe to mount and initialize the requested model from the PVC. KServe's v1beta1 schema places storageUri alongside modelFormat and runtime under the predictor's model block.
This distinction is fundamental to reusable KServe design: a runtime can serve multiple compatible models, while each InferenceService supplies the model-specific location and deployment parameters.
References/topics: Advanced HPE Compute Solutions, Rev. 26.21, Module 5 "Other options for serving models on HPE Private Cloud AI"; HPE AI Essentials KServe documentation; KServe InferenceService v1beta1 schema.
質問 # 30
An HPE Private Cloud AI customer has a model deployed with HPE Machine Learning Inference Software (MLIS). You have helped the customer further fine-tune that model. Now the customer would like to test the new model by directing 10% of traffic to it. What should you do?
正解:D
解説:
MLIS supports canary rollout for a new model version by assigning a traffic percentage, such as
10%, to the canary while the existing model continues receiving the remaining traffic.
質問 # 31
......
日常から離れて理想的な生活を求めるには、職場で高い得点を獲得し、試合に勝つために余分なスキルを習得する必要があります。同時に、社会的競争は現代の科学、技術、ビジネスの発展を刺激し、HPE7-S02試験に対する社会の認識に革命をもたらし、人々の生活の質に影響を与えます。 HPE7-S02試験問題は、あなたの夢をかなえるのに役立ちます。さらに、HPE7-S02ガイドトレントに関する詳細情報を提供する当社のWebサイトにアクセスできます。
HPE7-S02模擬対策問題: https://jp.fast2test.com/HPE7-S02-premium-file.html