P.S. Free 2026 Microsoft DP-600 dumps are available on Google Drive shared by ActualTorrent: https://drive.google.com/open?id=1H_QlaferLRwcZ6w-3zLt-4AkwiibGmIj
You have an option to try the DP-600 exam dumps demo version and understand the full features before purchasing. You can download the full features of DP-600 PDF Questions and practice test software right after the payment. ActualTorrent has created the three best formats of DP-600 practice questions. These Formats will help you to prepare for and pass the Microsoft DP-600 Exam. DP-600 pdf dumps format is the best way to quickly prepare for the DP-600 exam. You can open and use the Implementing Analytics Solutions Using Microsoft Fabric pdf questions file at any place. You don't need to install any software.
| Section | Objectives |
|---|---|
| Implement data engineering solutions | - Lakehouse architecture
|
| Real-time analytics | - Streaming and event processing
|
| Manage and secure Microsoft Fabric | - Governance and administration
|
| Get data into Microsoft Fabric | - Data ingestion and integration
|
| Implement analytics solutions | - Data warehousing and modeling
|
>> DP-600 Free Study Material <<
You will get real questions and accurate answers from DP-600 exam pdf torrent for your preparation of DP-600 certification. When you choose ActualTorrent DP-600 exam dumps, you will enjoy instant access to the DP-600 practice papers. Moreover, free updates for DP-600 latest dumps are available for 1 year after the purchase. With the help of the DP-600 Test Engine, you can not only revisit the mistakes you made, but also can retake tests until you are satisfied. With the practice and DP-600 valid study material, you will get your Microsoft DP-600 certification with ease.
NEW QUESTION # 190
You have a Fabric tenant that contains a semantic model. The model contains data about retail stores.
You need to write a DAX query that will be executed by using the XMLA endpoint. The query must return the total amount of sales from the same period last year.
How should you complete the DAX expression? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.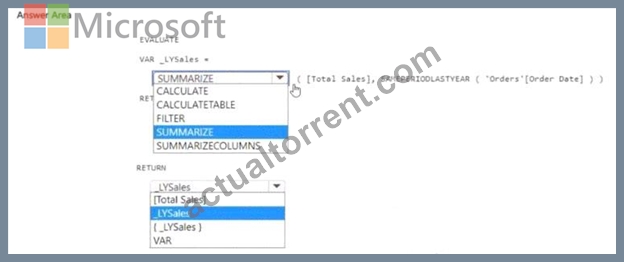
Answer:
Explanation: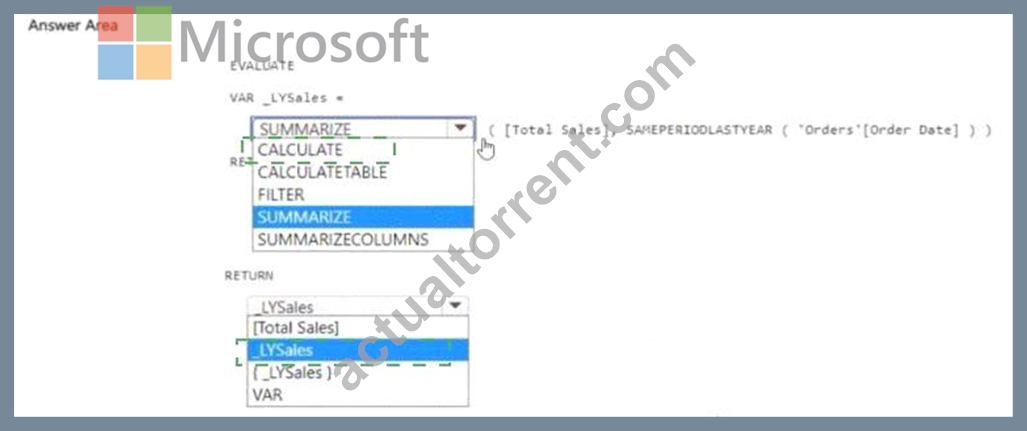
Explanation:
First blank: CALCULATE
Second blank: _LYSales
Step 1 - Defining the variable
We want to calculate sales for the same period in the prior year. The correct function here is CALCULATE, because it allows applying a filter context modification (with SAMEPERIODLASTYEAR).
So:
VAR _LYSales =
CALCULATE ( [Total Sales], SAMEPERIODLASTYEAR ( ' Orders ' [Order Date] ) ) Step 2 - Returning the value We then need to RETURN the value of the variable. From the dropdown options, we select _LYSales.
So:
EVALUATE
VAR _LYSales =
CALCULATE ( [Total Sales], SAMEPERIODLASTYEAR ( ' Orders ' [Order Date] ) ) RETURN ROW ( " LastYearSales " , _LYSales ) Note: In XMLA DAX queries, you usually need a table expression, so wrapping with ROW or SELECTCOLUMNS is common, but based on the provided answer box, just returning _LYSales is sufficient here.
Final Answer:
First blank: CALCULATE
Second blank: _LYSales
NEW QUESTION # 191
You have a Fabric tenant that contains a lakehouse.
You are using a Fabric notebook to save a large DataFrame by using the following code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.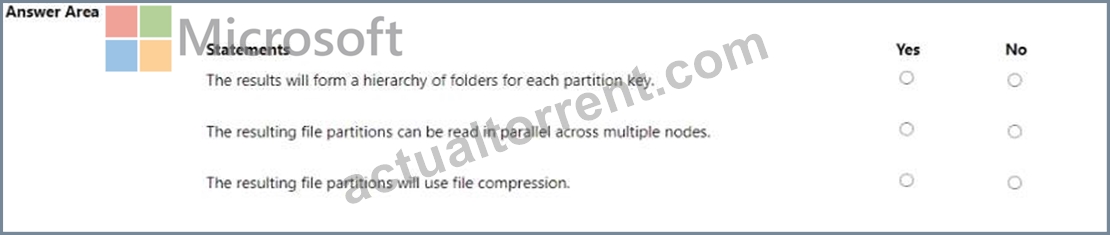
Answer:
Explanation: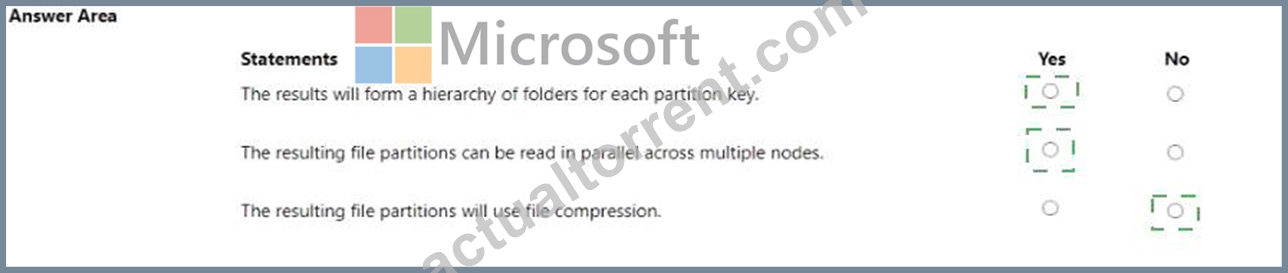
Explanation:
* The results will form a hierarchy of folders for each partition key. - Yes
* The resulting file partitions can be read in parallel across multiple nodes. - Yes
* The resulting file partitions will use file compression. - No
Partitioning data by columns such as year, month, and day, as shown in the DataFrame write operation, organizes the output into a directory hierarchy that reflects the partitioning structure. This organization can improve the performance of read operations, as queries that filter by the partitioned columns can scan only the relevant directories. Moreover, partitioning facilitates parallelism because each partition can be processed independently across different nodes in a distributed system like Spark. However, the code snippet provided does not explicitly specify that file compression should be used, so we cannot assume that the output will be compressed without additional context.
References =
* DataFrame write partitionBy
* Apache Spark optimization with partitioning
NEW QUESTION # 192
You have a Fabric semantic model named Model1 that contains a table named Sales.
You need to enable incremental refresh for the Sales table.
What should you do first?
Answer: B
Explanation:
To configure incremental refresh for a table in a Microsoft Fabric semantic model, you must first create two Power Query parameters with specific, case-sensitive names: RangeStart and RangeEnd.
These parameters act as placeholders that the Fabric service will later use to automatically partition your data based on date ranges.
Mandatory Setup Steps
Before you can enable the incremental refresh toggle in the table settings, you must complete these three tasks in Power Query Editor:
1. Create Reserved Parameters
Names: Must be exactly RangeStart and RangeEnd (case-sensitive).
Data Type: Must be set to Date/Time.
Values: Assign temporary default values (e.g., a one-day range) to filter the data you work with in the desktop environment.
2. Filter the Table Column
3. Ensure Query Folding
Reference:
https://learn.microsoft.com/en-us/power-bi/connect-data/incremental-refresh-configure
NEW QUESTION # 193
You have a Fabric warehouse that contains two tables named DimDate and Trips.
DimDate contains the following fields.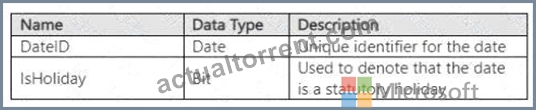
Trips contains the following fields.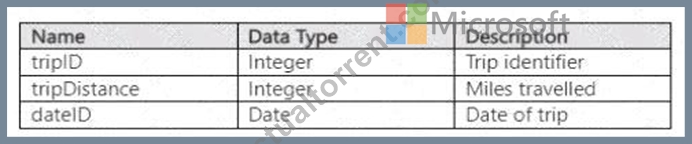
You need to compare the average miles per trip for statutory holidays versus non-statutory holidays.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.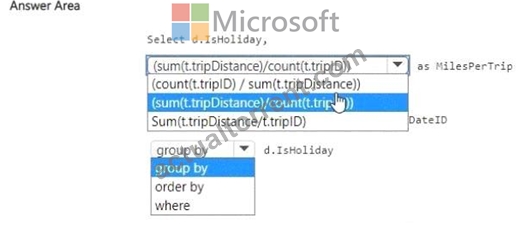
Answer:
Explanation: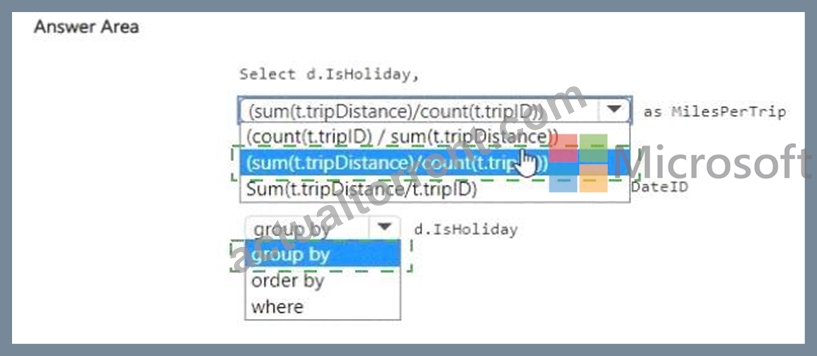
Explanation: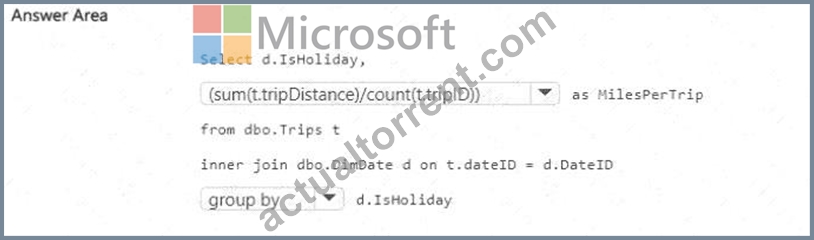
Comprehensive Detailed Explanation
Step 1: Requirement
We need to compare the average miles per trip for:
Statutory holidays (when IsHoliday = 1)
Non-statutory holidays (when IsHoliday = 0)
Step 2: Formula for average miles per trip
Average miles per trip = total miles ÷ number of trips
Total miles # SUM(t.tripDistance)
Number of trips # COUNT(t.tripID)
So the calculation is:
(SUM(t.tripDistance) / COUNT(t.tripID)) AS MilesPerTrip
Step 3: Grouping
We need a comparison by holiday status.
So we must group the results by:
GROUP BY d.IsHoliday
This ensures we get two rows: one for IsHoliday = 1 and one for IsHoliday = 0.
Step 4: Final Query
SELECT
d.IsHoliday,
(SUM(t.tripDistance) / COUNT(t.tripID)) AS MilesPerTrip
FROM DimDate d
INNER JOIN Trips t ON d.DateID = t.DateID
GROUP BY d.IsHoliday;
Why This is Correct
The formula ensures average miles per trip.
Grouping ensures comparison between holidays vs non-holidays.
Efficient aggregation, minimal computation.
References
Aggregate functions in T-SQL
GROUP BY clause
NEW QUESTION # 194
You are analyzing customer purchases in a Fabric notebook by using PySpanc You have the following DataFrames:
You need to join the DataFrames on the customer_id column. The solution must minimize data shuffling. You write the following code.
Which code should you run to populate the results DataFrame?




Answer: D
Explanation:
The correct code to populate the results DataFrame with minimal data shuffling is Option A. Using the broadcast function in PySpark is a way to minimize data movement by broadcasting the smaller DataFrame ( customers) to each node in the cluster. This is ideal when one DataFrame is much smaller than the other, as in this case with customers. References = You can refer to the official Apache Spark documentation for more details on joins and the broadcast hint.
NEW QUESTION # 195
......
Our DP-600 practice materials from our company are invulnerable. And we are consigned as the most responsible company in this area. So many competitors concede our superior position in the market. Besides, we offer some promotional benefits for you. The more times you choose our DP-600 Training Materials, the more benefits you can get, such as free demos of our DP-600 exam dumps, three-version options, rights of updates and so on. So customer orientation is the beliefs we honor.
Valid Exam DP-600 Blueprint: https://www.actualtorrent.com/DP-600-questions-answers.html
2026 Latest ActualTorrent DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=1H_QlaferLRwcZ6w-3zLt-4AkwiibGmIj