What's more, part of that Prep4pass HPE7-J01 dumps now are free: https://drive.google.com/open?id=1BMvO96hPoypqMs5QUX2oIjEb5yNyqA_e
You have Prep4pass HP HPE7-J01 certification exam training materials, the same as having a bright future. Prep4pass HP HPE7-J01 exam certification training is not only the cornerstone to success, and can help you to play a greater capacity in the IT industry. The training materials covering a wide range, not only to improve your knowledge of the culture, the more you can improve the operation level. If you are still waiting, still hesitating, or you are very depressed how through HP HPE7-J01 Certification Exam. Do not worry, the Prep4pass HP HPE7-J01 exam certification training materials will help you solve these problems.
| Section | Weight | Objectives |
|---|---|---|
| Storage Architecture and Design | 30% | - Design principles for enterprise storage
|
| Deployment and Integration | 20% | - Networking and connectivity
|
| Emerging Technologies and Solutions | 10% | - Hybrid cloud and multi-cloud storage
|
| Management and Optimization | 15% | - Troubleshooting and problem resolution
|
| Data Protection and Availability | 25% | - High availability solutions
|
Cease to struggle and you cease to live. Only by continuous learning can we not be surpassed by others. Many people do not like to study and think that learning is a very vexing thing. This kind of cognition makes their careers stagnate. HPE7-J01 test question will change your perception. HPE7-J01 learning dumps aim to help students learn easily and effectively that has been developed over many years by many industry experts. With HPE7-J01 study tool, you no longer need to look at a drowsy textbook. You do not need to study day and night. With HPE7-J01 learning dumps, you only need to spend 20-30 hours on studying, and then you can easily pass the exam. At the same time, the language in HPE7-J01 test question is very simple and easy to understand. Even if you are a newcomer who has just entered the industry, you can learn all the knowledge points without any obstacles. We believe that HPE7-J01 study tool will make you fall in love with learning. Come and buy it now.
NEW QUESTION # 24
Order the steps for a write data path and a successful write IO in HPE GreenLake for File Storage using NAS.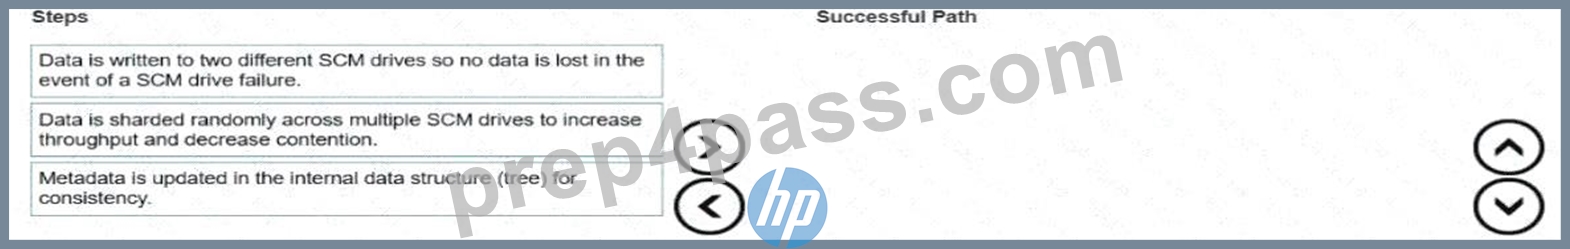
Answer:
Explanation: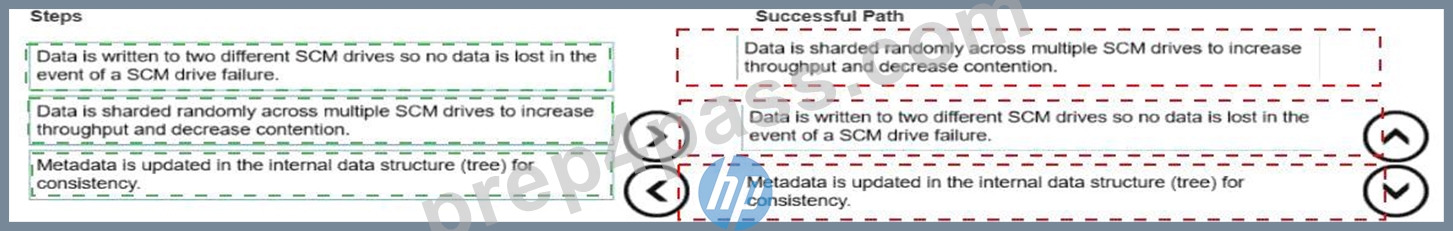
Explanation:
* Data is sharded randomly across multiple SCM drives to increase throughput and decrease contention.
* Data is written to two different SCM drives so no data is lost in the event of a SCM drive failure.
* Metadata is updated in the internal data structure (tree) for consistency.
Comprehensive and Detailed 250 to 300 words of Explanation From Advanced Storage Solutions Architect documents and knowledge guide:
The write data path in HPE GreenLake for File Storage (powered by Alletra MP X10000 hardware and VAST Data software) follows a unique Disaggregated Shared-Everything (DASE) architecture. Unlike legacy NAS systems that use front-end caching or complex controller-to-controller talk, this solution leverages Storage Class Memory (SCM) as a persistent write buffer to provide high-sustained performance without the need for traditional data movement between tiers.
The process begins with sharding. When a NAS write request arrives, the system immediately shards the data randomly across multiple SCM drives in the cluster. This sharding is critical because it eliminates hot spots and contention by ensuring that no single drive or node becomes a bottleneck, effectively parallelizing the IO load across the entire storage fabric.
Once the sharding logic is determined, the data is physically written to the SCM tier. To ensure mission- critical resilience, every write is mirrored (written to two different SCM drives). Because SCM is non-volatile random-access memory (NVRAM), the write is persistent the moment it hits the media. This allows the system to send an immediate acknowledgement back to the client while protecting against a drive or node failure.
Finally, the metadata is updated in the internal data structure (the V-Tree). This step ensures the "View" of the file system remains consistent and that the global namespace reflects the newly written data. After this point, the data is asynchronously moved from SCM to high-capacity NVMe SSDs using wide-stripe erasure coding for long-term, efficient storage. This disaggregated flow allows the Alletra MP X10000 to scale performance and capacity independently while maintaining strict data integrity and consistency at AI-scale.
NEW QUESTION # 25
What is a prerequisite for a successful Fibre Channel storage array Peer Motion migration?
Answer: A
Explanation:
The HPE Peer Motion Utility (PMU) and its integrated counterpart in HPE GreenLake and SSMC are designed for the non-disruptive migration of data between storage systems, such as from an HPE 3PAR to an HPE Alletra 9000 or Primera. A core requirement for the "Online" (non-disruptive) version of this migration is that the storage fabric must support and have N-Port ID Virtualization (NPIV) enabled.
Architecturally, Peer Motion relies on the destination array's ability to "masquerade" as the source array during the transition. When a volume is migrated, the destination array creates virtual ports using NPIV to inherit the identity (WWNs) of the source array's ports. This allows the host's multipathing software to see the new storage paths as if they were additional paths to the original volume, enabling a seamless transition without a server reboot or I/O interruption. According to the HPE Peer Motion Utility User Guide, if the SAN fabric (the switches) does not support NPIV or if NPIV is disabled on the specific ports, the migration utility will default to a Minimally Disruptive Migration (MDM) or an offline migration, both of which involve host-side downtime.
Furthermore, the fabric must be zoned such that the source and destination arrays can "see" each other to establish the Peer Motion relationship and handle the data orchestration. Option B is incorrect because while the management station (running the PMU) requires IP connectivity to send commands, the actual data movement and host-transparent pathing are strictly dependent on the FC fabric's NPIV capability. Option C is incorrect as fabric connections (via switches) are required; direct point-to-point connections between array FC ports are typically not supported for Peer Motion federations.
NEW QUESTION # 26
Hotspot Question
An administrator needs to verify that the HPE plug-in was installed in VMware vCenter to correctly integrate with the HPE Alletra storage array. Use your cursor to place a + where the administrator can click to verify the plug-in installation.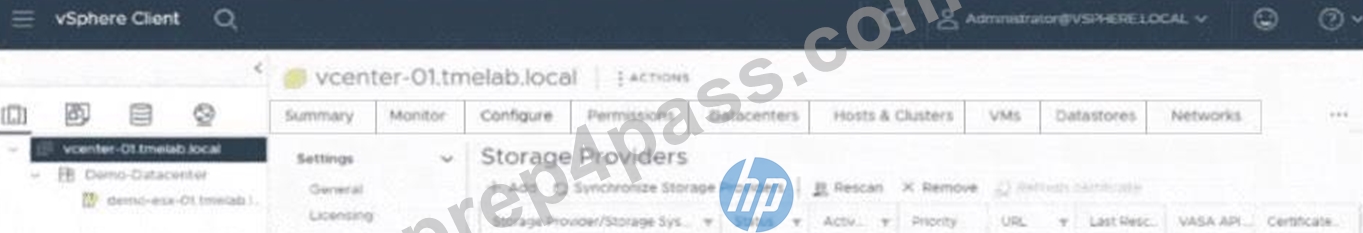
Answer:
Explanation: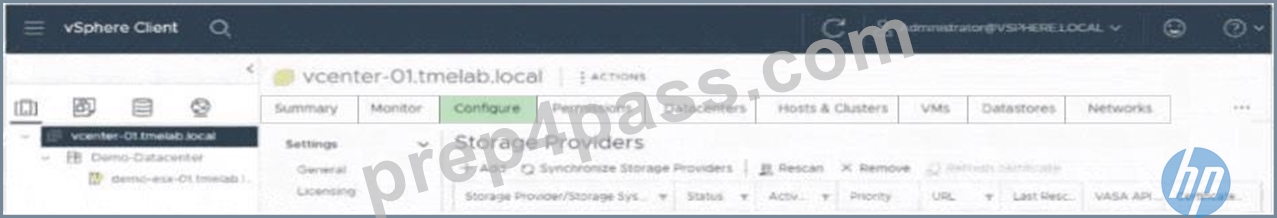
NEW QUESTION # 27
An HPE Partner is using HPE CloudPhysics to size a new storage solution for a customer that currently has a non-HPE storage array. When looking at the graphs and statistics in CloudPhysics, what is the only summary statistic that has time-correlated values?
Answer: A
Explanation:
HPE CloudPhysics is a SaaS-based analytics platform that collects high-resolution metadata (at 20-second intervals) from a customer's virtualized infrastructure to drive data-led procurement and optimization decisions. In the context of performance analysis and sizing, it is critical to understand not just the average utilization, but how different resource demands interact over time.
The Peak Details statistic is unique within the CloudPhysics analytics framework because it provides time- correlated values across different resource dimensions (CPU, RAM, and Disk I/O). While standard "Storage Metrics" or "Hardware Performance" summaries often present aggregated averages or 95th percentile figures that lose their temporal context, Peak Details allows an architect to see exactly when a spike occurred.
This correlation is essential for determining if a storage bottleneck is being driven by a simultaneous compute peak or if a specific "noisy neighbor" VM is impacting the entire datastore during a backup or batch processing window. By aligning disk latency peaks with IOPS and throughput peaks on the same timeline, CloudPhysics enables the architect to validate if the existing third-party array is truly under-provisioned or simply misconfigured. This time-correlated insight ensures that the new HPE storage solution is sized not just for total capacity, but for the actual performance "burstiness" observed in the customer's production cycle.
Other metrics, while useful for high-level summaries, do not provide the granular, synchronized timeline required to perform a deep-dive root cause analysis or precision sizing for mission-critical workloads.
NEW QUESTION # 28
A customer currently has an HPE Alletra 9000 with data reduction on all volumes and plans to migrate to an HPE Alletra MP B10000. Which formula should be used to size the new solution?
Answer: A
Explanation:
When sizing a migration from a highly efficient array like the HPE Alletra 9000 (or Primera) to the next-generation HPE Alletra MP B10000, storage architects must account for the difference between the "Written Capacity" (what the host thinks it has stored) and the "Consumed Capacity" (the physical space used after data reduction).
The standard best practice for an HPE Master ASE when performing these migrations is to Size to consumption multiplied by 1.25. This "1.25 factor" (representing a 25% overhead) is the recommended safety margin used in sizing tools like HPE NinjaStars and the HPE Cloud Physics assessment reports. This 25% buffer is designed to cover several critical architectural requirements:
System Metadata and Overhead: Both the Alletra 9000 and Alletra MP require physical capacity to store internal metadata, map tables, and the structures required for their respective data reduction engines. Snapshot Reserve: While snapshots are thin and pointer-based, they still consume physical space as data changes over time. The 1.25 multiplier ensures there is enough
"headroom" for typical snapshot retention policies.
Data Reduction Parity: Data reduction ratios (deduplication and compression) can fluctuate based on the specific workload. Sizing exactly to current consumption without a buffer risks an out-of- space condition if the new array's reduction engine handles a specific block pattern slightly differently during the initial ingest.
Operational Performance: SSD-based arrays perform best when they are not "packed" to 100% capacity, as the garbage collection and wear-leveling processes require free blocks to operate efficiently.
NEW QUESTION # 29
......
It takes a lot of effort and hard work to get the results. The first step is to download real Advanced HPE Storage Architect Solutions Written Exam (HPE7-J01) Exam Questions of Prep4pass. These Advanced HPE Storage Architect Solutions Written Exam (HPE7-J01) exam questions are available in PDF, desktop practice test software, and web-based practice exam. If you are already an employee or busy in your routine, you can prepare HPE7-J01 Exam quickly with Prep4pass pdf questions. HPE7-J01 pdf exam questions help applicants study for the Advanced HPE Storage Architect Solutions Written Exam (HPE7-J01) exam at any time from any location. With the pdf questions, it will be easy for you to complete the Advanced HPE Storage Architect Solutions Written Exam (HPE7-J01) exam preparation in a short time.
Valid HPE7-J01 Test Objectives: https://www.prep4pass.com/HPE7-J01_exam-braindumps.html
P.S. Free & New HPE7-J01 dumps are available on Google Drive shared by Prep4pass: https://drive.google.com/open?id=1BMvO96hPoypqMs5QUX2oIjEb5yNyqA_e