It is inescapable choice to make why don't you choose our DP-750 practice materials with passing rate up to 98-100 percent. You can have a sweeping through of our DP-750 practice materials with intelligibly and under-stable contents. It is time to take the plunge and you will not feel depressed. All incomprehensible issues will be small problems and all contents will be printed on your minds. So even trifling mistakes can be solved by using our DP-750 practice materials, as well as all careless mistakes you may make.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 2: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 3: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 4: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
The Implementing Data Engineering Solutions Using Azure Databricks (DP-750) is one of the popular exams of Microsoft DP-750. It is designed for Microsoft aspirants who want to earn the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification and validate their skills. The DP-750 test is not an easy exam to crack. It requires dedication and a lot of hard work. You need to prepare well to clear the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) test on the first attempt. One of the best ways to prepare successfully for the DP-750 examination in a short time is using real DP-750 Exam Dumps.
NEW QUESTION # 29
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: B
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don't prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely.
Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 30
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: C
Explanation:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
NEW QUESTION # 31
You have an Azure Databricks workspace
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically. You need to configure compute for the pipeline. The solution must minimize operational costs and effort. What should you use?
Answer: B
Explanation:
The correct answer is C - a job cluster that uses autoscaling.
Job clusters (also called pipeline clusters in the SDP context) are created exclusively for a pipeline run and terminated when the pipeline stops. You pay only for what the pipeline uses, and there's no idle cost between runs. Autoscaling on a job cluster lets the pipeline expand during heavy processing and contract during lighter stages - the combination of on-demand lifecycle and elastic scaling gives the lowest operational cost.
Option A (all-purpose cluster) runs at a higher DBU rate and persists beyond the pipeline's lifecycle, meaning you're paying for it even when the pipeline isn't running. Option B (SQL warehouse) is optimised for interactive BI and ad-hoc queries, not for the batch/streaming workloads SDP pipelines run. Option D (single- node all-purpose) has no scaling, runs at the all-purpose DBU rate, and is capped at one node - unsuitable for any production pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/configure-pipeline
NEW QUESTION # 32
You have an Azure Databricks workspace that is attached to a Unity Catalog metastore named metastore1.
Metastore1 contains a catalog named catalog 1.
You need to create a new schema named schema2 that meets the following requirements:
* Is contained in catalog1
* Uses abfss://containergstorageaccount.dfs.core.windows.net/data as the Managed location Which SQL statement should you execute?
Answer: B
Explanation:
The correct answer is A. The Unity Catalog DDL for creating a schema inside a specific catalog and setting a custom managed storage path uses the three-part name (catalog.schema) and the MANAGED LOCATION clause:
CREATE SCHEMA catalog1.schema2 MANAGED LOCATION ' abfss://... ' ;
The three-part name explicitly places the schema inside catalog1. MANAGED LOCATION tells Unity Catalog where to store managed tables and volumes created under this schema - any managed table without its own explicit location will inherit this path.
Option B uses CREATE CATALOG, which creates an entirely new catalog rather than a schema. Option C uses the LOCATION keyword without MANAGED - that syntax is for external locations, not for overriding the managed storage path of a schema. Option D uses WITH DBPROPERTIES, which stores arbitrary key- value metadata but has no effect on where Unity Catalog physically stores data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- schema
NEW QUESTION # 33
You have an Azure Databricks workspace.
You have a streaming table named sales_order that is populated by using a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
You need to create a new streaming table named sales_order_by_city that summarizes sales by city and calculates the total sales per city.
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.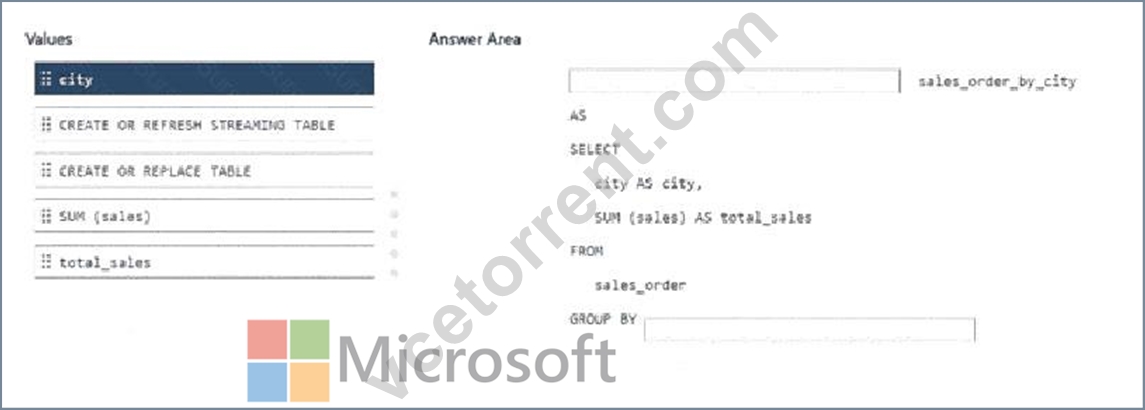
Answer:
Explanation: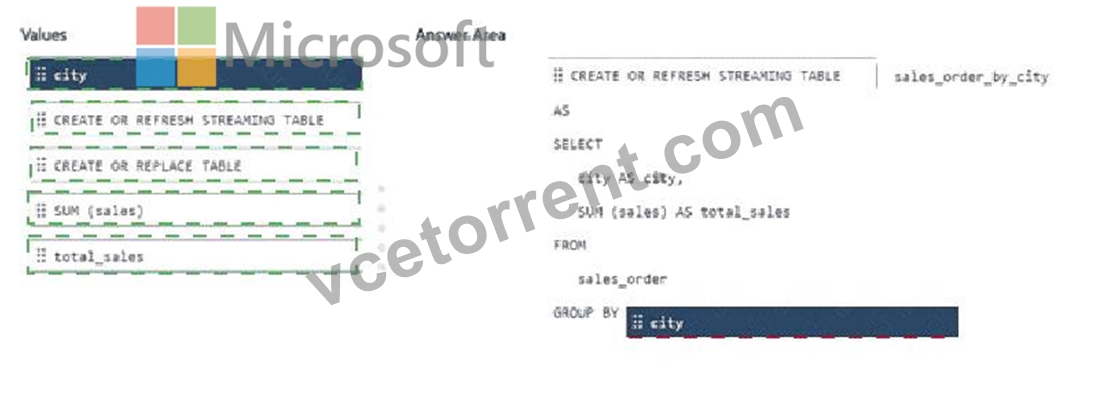
Explanation:
CREATE OR REFRESH STREAMING TABLE
city
CREATE OR REFRESH STREAMING TABLE defines a streaming table managed by Lakeflow Spark Declarative Pipelines. When the pipeline refreshes, Databricks incrementally processes newly available source data and maintains the resulting table. CREATE OR REPLACE TABLE would create a conventional table and does not provide the required streaming-table semantics. The query selects city AS city and calculates SUM(sales) AS total_sales. Because the aggregation must produce one result for each city, the GROUP BY expression must be city. Neither SUM(sales) nor total_sales belongs in the grouping clause: the former is the aggregate calculation, while the latter is only the alias assigned to its result. This produces continuously maintained city-level sales totals from the sales_order source table.
NEW QUESTION # 34
......
It is a common sense that in terms of a kind of Implementing Data Engineering Solutions Using Azure Databricks test torrent, the pass rate would be the best advertisement, since only the pass rate can be the most powerful evidence to show whether the DP-750 guide torrent is effective and useful or not. We are so proud to tell you that according to the statistics from the feedback of all of our customers, the pass rate among our customers who prepared for the exam under the guidance of our Implementing Data Engineering Solutions Using Azure Databricks test torrent has reached as high as 98%to 100%, which definitely marks the highest pass rate in the field. Therefore, the DP-750 Guide Torrent compiled by our company is definitely will be the most sensible choice for you.
DP-750 Reliable Exam Pattern: https://www.vcetorrent.com/DP-750-valid-vce-torrent.html