DP-600 Study Materials & Reliable DP-600 Braindumps Questions

2026 Latest Exam4PDF DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=18lM9j3Bjp1cn2swGIoE6xwQjrbKjw_q2
Most of the DP-600 exam dumps on the platform are out of reach for most users due to their high price. Visit the Microsoft DP-600 exam dumps if you want to buy real Microsoft DP-600 Exam Questions at a good price. Start your Microsoft DP-600 exam preparation with our exam practice questions.
| Topic | Details |
|---|
| Topic 1 | - Implement and manage semantic models: This section of the exam measures the skills of architects and focuses on designing and optimizing semantic models to support enterprise-scale analytics. It evaluates understanding of storage modes and implementing star schemas and complex relationships, such as bridge tables and many-to-many joins. Architects must write DAX-based calculations using variables, iterators, and filtering techniques. The use of calculation groups, dynamic format strings, and field parameters is included. The section also includes configuring large semantic models and designing composite models. For optimization, candidates are expected to improve report visual and DAX performance, configure Direct Lake behaviors, and implement incremental refresh strategies effectively.
|
| Topic 2 | - Maintain a data analytics solution: This section of the exam measures the skills of administrators and covers tasks related to enforcing security and managing the Power BI environment. It involves setting up access controls at both workspace and item levels, ensuring appropriate permissions for users and groups. Row-level, column-level, object-level, and file-level access controls are also included, alongside the application of sensitivity labels to classify data securely. This section also tests the ability to endorse Power BI items for organizational use and oversee the complete development lifecycle of analytics assets by configuring version control, managing Power BI Desktop projects, setting up deployment pipelines, assessing downstream impacts from various data assets, and handling semantic model deployments using XMLA endpoint. Reusable asset management is also a part of this domain.
|
| Topic 3 | - Prepare data: This section of the exam measures the skills of engineers and covers essential data preparation tasks. It includes establishing data connections and discovering sources through tools like the OneLake data hub and the real-time hub. Candidates must demonstrate knowledge of selecting the appropriate storage type—lakehouse, warehouse, or eventhouse—depending on the use case. It also includes implementing OneLake integrations with Eventhouse and semantic models. The transformation part involves creating views, stored procedures, and functions, as well as enriching, merging, denormalizing, and aggregating data. Engineers are also expected to handle data quality issues like duplicates, missing values, and nulls, along with converting data types and filtering. Furthermore, querying and analyzing data using tools like SQL, KQL, and the Visual Query Editor is tested in this domain.
|
>> DP-600 Study Materials <<
Reliable DP-600 Braindumps Questions - DP-600 Discount
Exam4PDF was established in 2008, now we are the leading position in this field as we have good reputation of high-pass-rate DP-600 guide torrent materials. Our DP-600 exam questions are followed by many peers many years but never surpassed. We build a mature and complete DP-600 learning guide R&D system, customers' information safety system & customer service system since past 10 years. Every candidate who purchases our valid DP-600 Preparation materials will enjoy our high-quality guide torrent, information safety and golden customer service.
Microsoft Implementing Analytics Solutions Using Microsoft Fabric Sample Questions (Q158-Q163):
NEW QUESTION # 158
You have source data in a folder on a local computer.
You need to create a solution that will use Fabric to populate a data store. The solution must meet the following requirements:
* Support the use of dataflows to load and append data to the data store.
* Ensure that Delta tables are V-Order optimized and compacted automatically.
Which type of data store should you use?
- A. a lakehouse
- B. an Azure SQL database
- C. a KQL database
- D. a warehouse
Answer: B,D
Explanation:
A lakehouse (A) is the type of data store you should use. It supports dataflows to load and append data and ensures that Delta tables are Z-Order optimized and compacted automatically. Reference = The capabilities of a lakehouse and its support for Delta tables are described in the lakehouse and Delta table documentation.
NEW QUESTION # 159
You have a Fabric warehouse that contains a table named Sales.Orders. Sales.Orders contains the following columns.
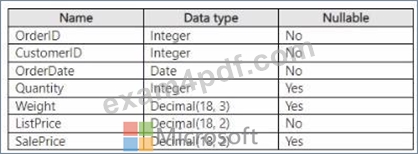
You need to write a T-SQL query that will return the following columns.
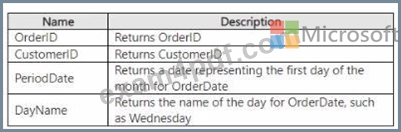
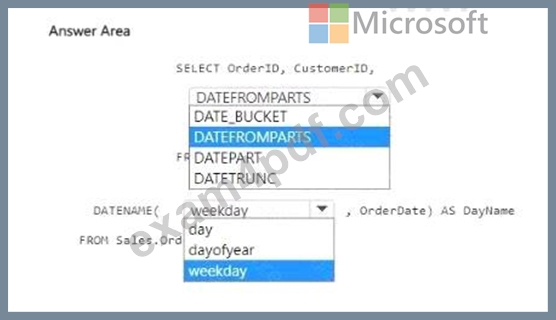
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
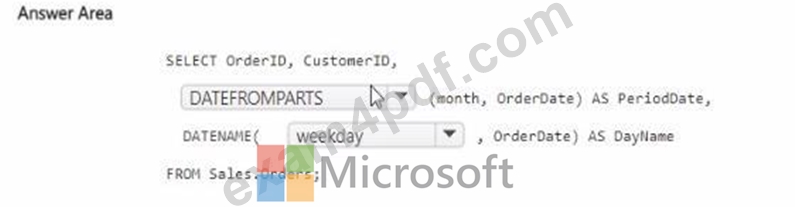
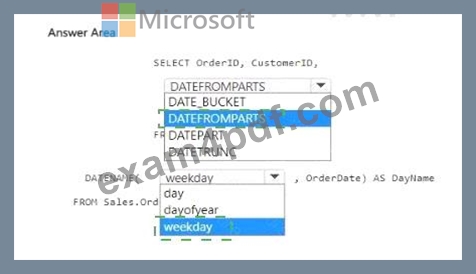
For the PeriodDate that returns the first day of the month for OrderDate, you should use DATEFROMPARTS as it allows you to construct a date from its individual components (year, month, day).
For the DayName that returns the name of the day for OrderDate, you should use DATENAME with the weekday date part to get the full name of the weekday.
The complete SQL query should look like this:
SELECT OrderID, CustomerID,
DATEFROMPARTS(YEAR(OrderDate), MONTH(OrderDate), 1) AS PeriodDate,
DATENAME(weekday, OrderDate) AS DayName
FROM Sales.Orders
Select DATEFROMPARTS for the PeriodDate and weekday for the DayName in the answer area.
NEW QUESTION # 160
You have a Fabric workspace named Workspace1 and an Azure SQL database.
You plan to create a dataflow that will read data from the database, and then transform the data by performing an inner join. You need to ignore spaces in the values when performing the inner join The solution must minimize development effort. What should you do?
- A. Merge the queries by using fuzzy matching.
- B. Append the queries by using a lookup table.
- C. Merge the queries by using a lookup table.
- D. Append the queries by using fuzzy matching.
Answer: A
Explanation:
You need to perform an inner join and ignore spaces in the values.
In Power Query, to handle joins where values may contain spaces or minor mismatches, you use fuzzy matching in the Merge Queries operation.
Append queries combines rows, not columns, so it does not apply here.
Lookup table is not required since the transformation can be handled natively in Power Query with fuzzy matching.
Correct solution: Merge the queries by using fuzzy matching.
Reference: Fuzzy merge in Power Query
NEW QUESTION # 161
You have a Microsoft Power Bl report named Report1 that uses a Fabric semantic model.
Users discover that Report1 renders slowly.
You open Performance analyzer and identify that a visual named Orders By Date is the slowest to render. The duration breakdown for Orders By Date is shown in the following table.
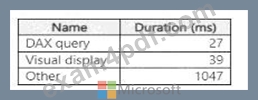
What will provide the greatest reduction in the rendering duration of Report1?
- A. Optimize the DAX query of Orders By Date by using DAX Studio.
- B. Change the visual type of Orders By Dale.
- C. Reduce the number of visuals in Report1.
- D. Enable automatic page refresh.
Answer: C
Explanation:
Based on the duration breakdown provided, the major contributor to the rendering duration is categorized as " Other, " which is significantly higher than DAX Query and Visual display times. This suggests that the issue is less likely with the DAX calculation or visual rendering times and more likely related to model performance or the complexity of the visual. However, of the options provided, optimizing the DAX query can be a crucial step, even if " Other " factors are dominant. Using DAX Studio, you can analyze and optimize the DAX queries that power your visuals for performance improvements. Here's how you might proceed:
Open DAX Studio and connect it to your Power BI report.
Capture the DAX query generated by the Orders By Date visual.
Use the Performance Analyzer feature within DAX Studio to analyze the query.
Look for inefficiencies or long-running operations.
Optimize the DAX query by simplifying measures, removing unnecessary calculations, or improving iterator functions.
Test the optimized query to ensure it reduces the overall duration.
References: The use of DAX Studio for query optimization is a common best practice for improving Power BI report performance as outlined in the Power BI documentation.
NEW QUESTION # 162
You have a Fabric tenant that contains a workspace named Workspace1.
You plan to deploy a semantic model named Model1 by using the XMLA endpoint.
You need to optimize the deployment of Model1. The solution must minimize how long it takes to deploy Model1.
What should you do in Workspace1?
- A. Select Users can edit data models in the Power BI service.
- B. Select Small semantic model storage format.
- C. Select Large semantic model storage format.
- D. Set Enable Cache for Shortcuts to On.
Answer: B
Explanation:
When using XMLA endpoint for deployment or processing , the semantic model storage format impacts deployment times.
Small storage format allows faster metadata operations and shorter deployment times.
Large semantic model storage format is only needed for extremely large models ( > 10 GB dataset limit), and it increases deployment overhead.
The other options (B: service editing, C: cache for shortcuts) are unrelated to XMLA endpoint deployment performance.
Reference:
Power BI semantic model storage format
NEW QUESTION # 163
......
Dear, hurry up to get the 100% pass DP-600 exam study dumps for your preparation. You will get original questions and verified answers for the Microsoft certification. After purchase of the DP-600 exam dumps, you can instant download the DP-600 practice torrent and start your study with no time wasted. The validity and useful DP-600 will clear your doubts which will be in the actual test. When you prepare well with our DP-600 pdf cram, the 100% pass will be easy thing.
Reliable DP-600 Braindumps Questions: https://www.exam4pdf.com/DP-600-dumps-torrent.html
- New DP-600 Test Topics 🌰 Latest DP-600 Exam Bootcamp 👽 Pass4sure DP-600 Exam Prep 🐊 Open ➡ www.validtorrent.com ️⬅️ enter ⏩ DP-600 ⏪ and obtain a free download 🕚Exam DP-600 Flashcards
- 2026 DP-600 Study Materials 100% Pass | High-quality Reliable Implementing Analytics Solutions Using Microsoft Fabric Braindumps Questions Pass for sure 🏃 Easily obtain ▶ DP-600 ◀ for free download through ⏩ www.pdfvce.com ⏪ 💼Latest DP-600 Exam Bootcamp
- Pass4sure DP-600 Exam Prep 😋 Latest DP-600 Test Camp 🏋 Exam DP-600 Flashcards 🖕 Simply search for “ DP-600 ” for free download on [ www.prepawaypdf.com ] 🏂DP-600 Exam Price
- DP-600 Study Materials - Free PDF 2026 First-grade DP-600: Reliable Implementing Analytics Solutions Using Microsoft Fabric Braindumps Questions ⌨ Search on 【 www.pdfvce.com 】 for 《 DP-600 》 to obtain exam materials for free download 🧥New DP-600 Test Topics
- Get Certified in One Go with www.testkingpass.com's Reliable Microsoft DP-600 Questions 🦋 Search on ⏩ www.testkingpass.com ⏪ for ▶ DP-600 ◀ to obtain exam materials for free download 🔳DP-600 Authorized Certification
- Microsoft DP-600 Exam is Easy with Our Trustable DP-600 Study Materials: Implementing Analytics Solutions Using Microsoft Fabric Effectively 🐋 Enter ➤ www.pdfvce.com ⮘ and search for 「 DP-600 」 to download for free 🛺New DP-600 Exam Preparation
- DP-600 Pass Test Guide 🍞 Pass DP-600 Exam 🛥 Pass DP-600 Exam 🏂 Open ➥ www.troytecdumps.com 🡄 and search for ⇛ DP-600 ⇚ to download exam materials for free 💝DP-600 Certification Materials
- 2026 DP-600 Study Materials 100% Pass | High-quality Reliable Implementing Analytics Solutions Using Microsoft Fabric Braindumps Questions Pass for sure 🚀 Open 《 www.pdfvce.com 》 and search for { DP-600 } to download exam materials for free 🐄Exam DP-600 Course
- DP-600 Certification Materials ✒ DP-600 Pass Test Guide 💎 DP-600 Authorized Certification 🚝 Open ➥ www.troytecdumps.com 🡄 enter ☀ DP-600 ️☀️ and obtain a free download 🐥DP-600 Mock Test
- Pass4sure DP-600 Exam Prep 🥮 Actual DP-600 Test Pdf 🟥 Exam DP-600 Course ⛹ Search for 「 DP-600 」 and download it for free immediately on { www.pdfvce.com } 🐊Latest DP-600 Exam Bootcamp
- Get Certified in One Go with www.examcollectionpass.com's Reliable Microsoft DP-600 Questions ⚽ Search for ▶ DP-600 ◀ and obtain a free download on 《 www.examcollectionpass.com 》 🐁DP-600 Exam Price
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, schoolido.lu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free & New DP-600 dumps are available on Google Drive shared by Exam4PDF: https://drive.google.com/open?id=18lM9j3Bjp1cn2swGIoE6xwQjrbKjw_q2