P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by ExamcollectionPass: https://drive.google.com/open?id=1hwSJ8xauOg8QmyRRP_yA7jM6Rr1trzHC
For the convenience of the Exams candidates, the difficult portions of the syllabus have been explained with the help of experts to be simplified. One remarkable feature of SPS-C01 actual dumps questions and answers is their similarity with the real exam scenario. They not only give you understanding of the SPS-C01 Exams but also impart you an opportunity to master it. To enhance further your exam ability and strengthen your learning, you can benefit yourself getting practice Snowflake real dumps.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and Operations | 35% | - Advanced operations
|
| Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
| Performance and Best Practices | 10% | - Security and governance
|
| Snowpark API and Development | 30% | - Python API fundamentals
|
ExamcollectionPass team of professionals made this product after working day and night so that users can prepare from it for the Snowflake SPS-C01 certification test successfully. ExamcollectionPass even guarantees that you will pass the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) test on the first try by preparing with real questions. If you fail to pass the certification exam, despite all your efforts, you could get a full refund from ExamcollectionPass according to terms and conditions.
NEW QUESTION # 190
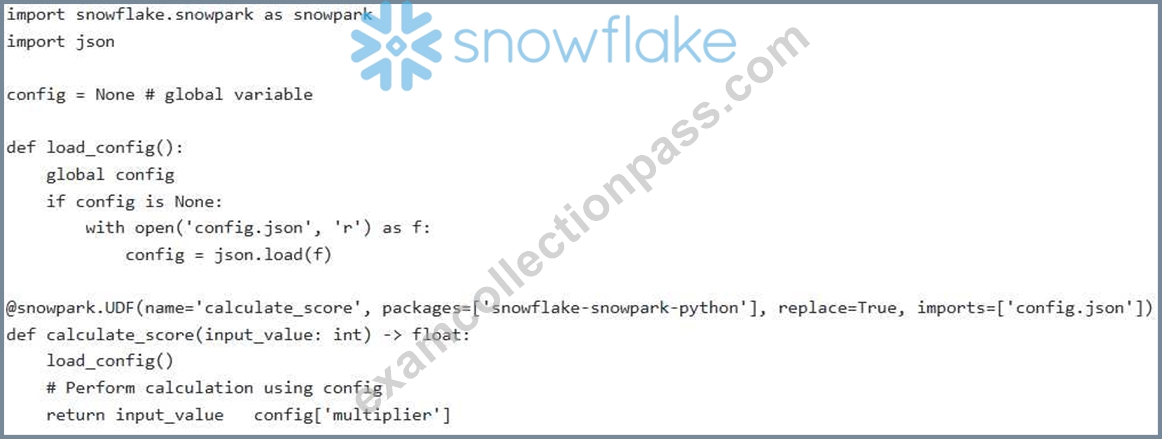
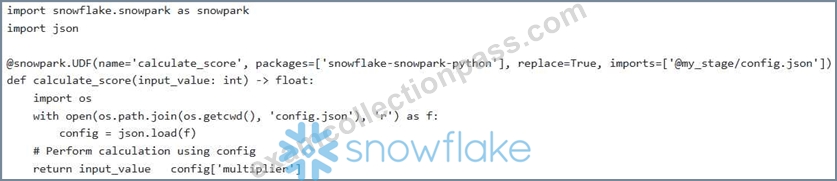
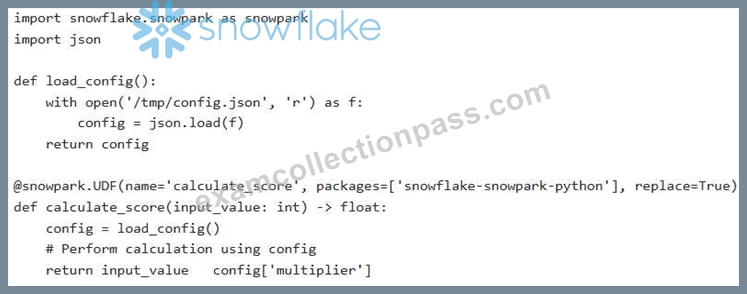
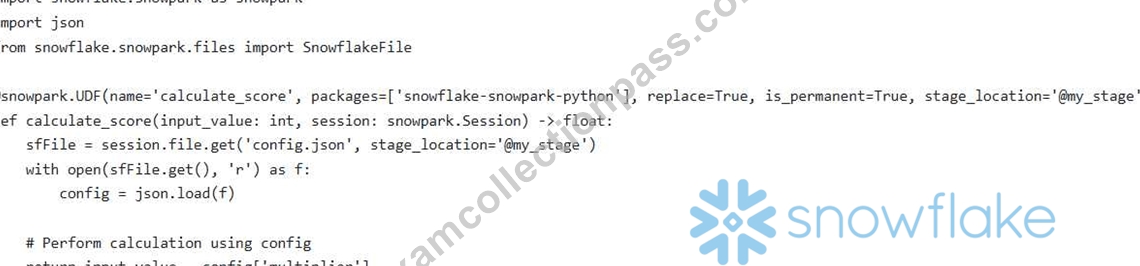
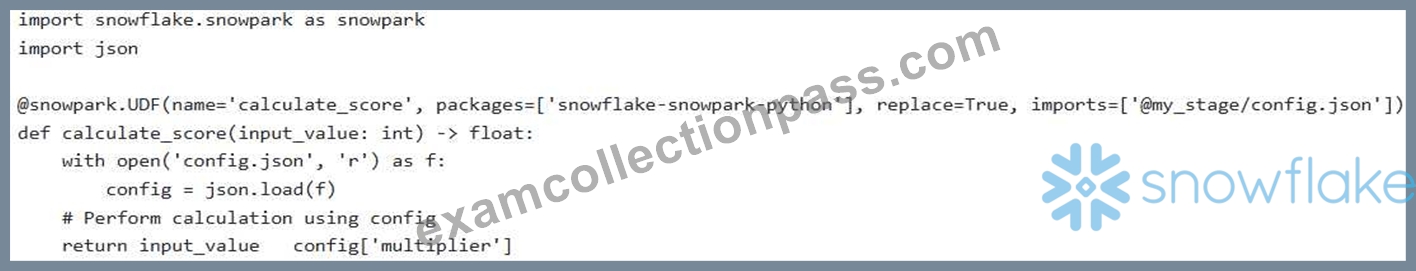
Consider the following Snowpark Python code snippet designed to read data from a Snowflake table, apply a user-defined function (UDF) for data transformation, and then write the transformed data to another table. The UDF, 'calculate_score' , requires a configuration file ('config.json') to be loaded. Which of the following code snippets demonstrates the CORRECT and MOST efficient way to load and access the "config.json' file within the UDF, ensuring that it's available to all UDF invocations without requiring network access?
Answer: E
Explanation:
Option E is the most correct answer, leveraging the 'imports' parameter to efficiently load the 'config.json' file from the specified stage into the UDF's environment. The file is then accessed using a relative path ('config.json'), which is the location where Snowflake places the imported file. Option A is incorrect because it attempts to load from '/tmp/config.json' , which is not accessible within the UDF's environment. Option B is incorrect due to it being Permanent UDF and trying to access the session which are mutually exclusive. In addition , the stage location must be at the time of registration rather than in the UDF definitition, which isn't right. Option C is almost right but incorrect because it accesses file with 'os.path.join(os.getcwd(), 'config.json'Y which is unecessary and wrong. Option D is incorrect because files specified in the 'imports' parameter are available in the current working directory directly, no need to import and declare a global variable
NEW QUESTION # 191
A data engineering team is building a Snowpark application in Python to perform advanced time series analysis on sensor data stored in Snowflake. They need to leverage a specific, but older, version of the 'pandas' library (version 1.1.5) that is not available in the default Snowflake Anaconda channel. Which of the following approaches is the MOST efficient and recommended way to ensure this specific version of 'pandas' is available to their Snowpark application, while minimizing security risks and operational overhead?
Answer: A
Explanation:
Creating a new Snowflake Anaconda environment is the most efficient and secure way to manage specific package versions. It leverages Snowflake's built-in dependency management capabilities and avoids external dependencies or manual package management within the application code. Options A and D introduce potential security risks and maintenance overhead. Option B is inefficient for dependency management. Option E will not work, as it tries to install dependencies at runtime, which isn't supported in Snowpark.
NEW QUESTION # 192
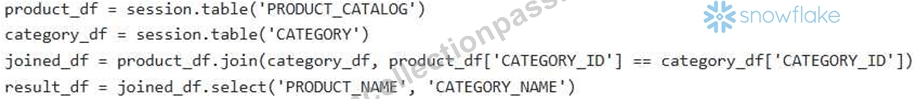
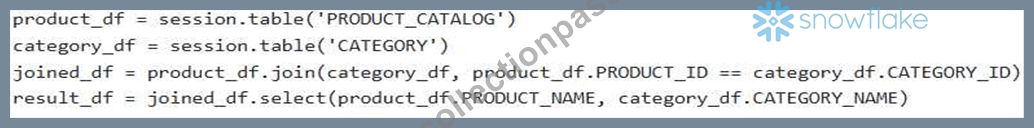
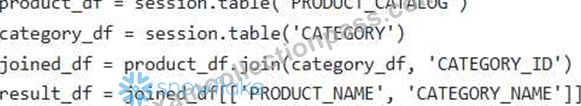
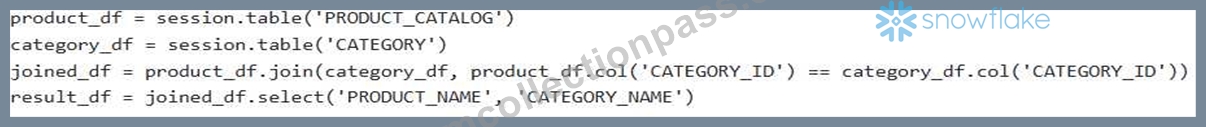
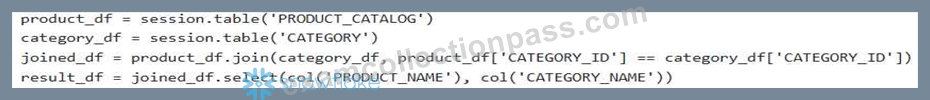
You have a Snowflake table 'PRODUCT CATALOG' with columns 'PRODUCT ID, 'PRODUCT NAME, and 'CATEGORY ID. You also have a table 'CATEGORY' with 'CATEGORY ID' and 'CATEGORY NAME. You need to create a Snowpark DataFrame that joins these two tables and includes only 'PRODUCT NAME and 'CATEGORY NAME. Assume a Snowpark Session object named 'session' is available. Which code snippet demonstrates creating the DataFrame using Snowpark's join functionality and column selection while using the 'table' method?
Answer: E
Explanation:
Option D correctly joins the tables using the 'join' method with a column expression specifying the join condition. It also correctly selects only the desired columns using and option A incorrectly uses 'PRODUCT_ID instead of for the join and needs 'col()' to reference columns. option B selects 'PRODUCT_NAME', 'CATEGORY_NAME' without using 'col(Y which will cause an error since the join brings duplicate column names from product_df and category_df. Option C uses Pythonic '[['PRODUCT_NAME', 'CATEGORY_NAME'I]' which only works on Pandas dataframes. option E attempts to use col() to reference the columns in the join condition which is incorrect as it is a column expression needs to use fully qualified table name for the same named column in two dataframes; moreover selection is missing col().
NEW QUESTION # 193
You are working with a data science team that needs to create Snowpark DataFrames from various file types (CSV, JSON, Parquet, and XML) stored in different locations (internal stages, external stages on AWS S3, and Azure Blob Storage). The team wants a unified and reusable function to create DataFrames, abstracting away the specific file format and location details. Which of the following approaches using Snowpark Python API will provide the MOST flexible and maintainable solution?
Answer: E
Explanation:
Option C provides the best balance of flexibility, maintainability, and conciseness. Using 'getattr(session.read, file_format)' allows dynamically calling the appropriate 'session.read' method (e.g., 'session.read.csv', 'session.read.json') based on a string parameter. Passing additional configuration through a dictionary allows customizing the read operation without modifying the core function. Options A, B, D, and E are less flexible, more verbose, or less efficient.
NEW QUESTION # 194
You have a Snowpark Python application that reads data from a Snowflake table, performs a complex transformation using a User- Defined Table Function (UDTF), and then writes the transformed data back to a new Snowflake table. The UDTF is defined as follows: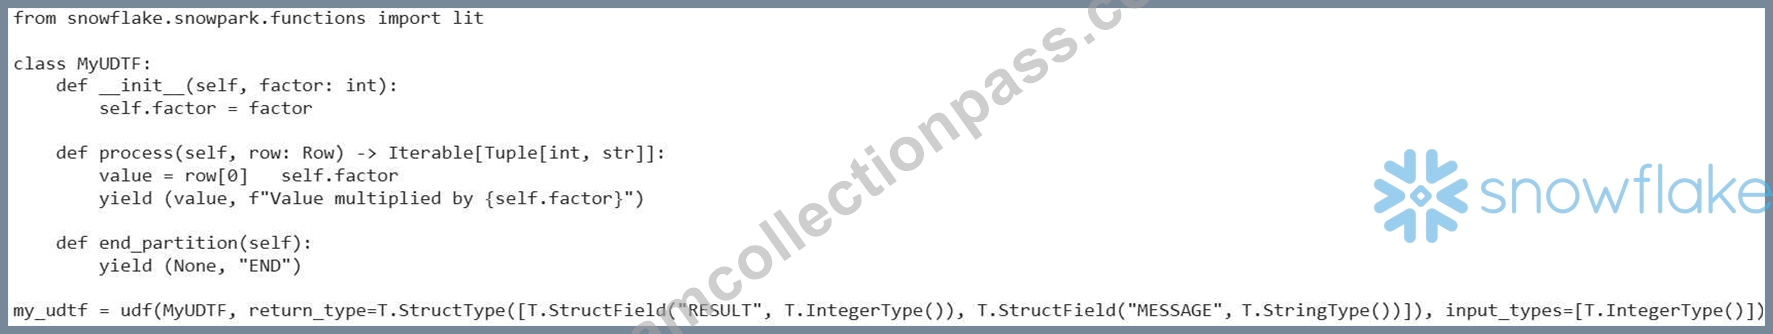
You need to optimize the performance of this application. Which of the following strategies would be MOST effective in reducing the execution time of the UDTF?
Answer: B
Explanation:
Vectorized UDTFs process data in batches, which can significantly improve performance compared to processing each row individually. This is especially true for complex transformations. Increasing warehouse size (A) can help but might not be as efficient as vectorization. Reducing input data (B) is always a good practice, but vectorization provides a more direct performance boost to the UDTF execution. Standard UDFs (D) are not generally faster than UDTFs, especially when dealing with table transformations. Caching (E) can help if the DataFrame is reused multiple times, but it doesn't directly optimize the UDTF's performance.
NEW QUESTION # 195
......
There are a lot of experts and professors in our company. All SPS-C01 study torrent of our company are designed by these excellent experts and professors in different area. We can make sure that our SPS-C01 test torrent has a higher quality than other study materials. The aim of our design is to improving your learning and helping you gains your certification in the shortest time. If you long to gain the certification, our Snowflake Certified SnowPro Specialty - Snowpark guide torrent will be your best choice. Many experts and professors consist of our design team, you do not need to be worried about the high quality of our SPS-C01 Test Torrent. If you decide to buy our study materials, you will have the opportunity to enjoy the best service.
Free SPS-C01 Study Material: https://www.examcollectionpass.com/Snowflake/SPS-C01-practice-exam-dumps.html
BONUS!!! Download part of ExamcollectionPass SPS-C01 dumps for free: https://drive.google.com/open?id=1hwSJ8xauOg8QmyRRP_yA7jM6Rr1trzHC