順便提一下,可以從雲存儲中下載VCESoft SPS-C01考試題庫的完整版:https://drive.google.com/open?id=122ibdhEubsmTCilzGB2Y1DojRCKaag5V
目前是經濟衰退的時期,找一份工作不容易,考取 SPS-C01 認證的證書肯定是有用的,能夠幫助你穩定你的位置,增加求職的成功率。VCESoft SPS-C01 認證考題已經幫助很多考生通過 SPS-C01 考試。并被很多考生視為首選的 SPS-C01 證照參考資料,是考生一直稱贊和信得過的考題。想獲取 Snowflake 的證照考生需要參加SPS-C01 考試。
| Section | Weight | Objectives |
|---|---|---|
| Snowpark Concepts | 15% | - Stored procedures and conditional logic - Snowpark Sessions and connection management - Snowpark DataFrames and query plans - Snowpark architecture and core concepts - Transformations vs. Actions - Client-side vs. Server-side execution |
| Performance Optimization and Best Practices | 20% | - Debugging and explain plans - Query pushdown and optimization - Vectorized UDFs - Minimizing data transfer - Warehouse sizing for Snowpark - Caching strategies |
| Snowpark API for Python | 30% | - Establishing connections and session management - User-Defined Functions (UDFs) and Stored Procedures - DataFrame creation and manipulation - Working with Semi-structured data - Reading and writing data |
| Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Persisting transformed data - Filtering, Aggregating, and Joining DataFrames - Using built-in functions - Window functions |
獲得SPS-C01認證已經成為大多數IT員工獲得更好工作的一種選擇,然而,許多考生一直在努力嘗試卻失敗了。如果你選擇使用我們的Snowflake SPS-C01題庫產品,幫您最大程度保證取得成功。充分利用SPS-C01題庫你將得到不一樣的效果,這是一個針對性強,覆蓋面廣,更新快,最完整的學習資料,保證您一次通過SPS-C01考試。如果您想要真實的考試模擬,就選擇我們軟件版本的Snowflake SPS-C01題庫,安裝在電腦上進行模擬,簡單易操作。
問題 #87
You are developing a Snowpark Python application that needs to process large datasets. You want to optimize performance by leveraging user-defined functions (UDFs) to perform complex calculations in parallel across the Snowflake data warehouse. Which of the following statements regarding Snowpark UDFs are TRUE?
答案:A,E
解題說明:
Snowpark UDFs can be either scalar or vectorized, offering different performance tradeoffs. Vectorized UDFs are generally more efficient for large datasets as they process batches of rows. Snowpark UDFs do distribute the data and computation across multiple nodes automatically; however, the distribution strategy, while not directly controlled, is influenced by how the UDF is applied to the data and the inherent distribution of the underlying data itself. Python is the primary UDF language. Option A is false because UDFs are designed for parallel processing. Option C is not always true; custom channels might be necessary for specific dependencies. Option E is partially correct in the older releases but Python is used primarily now.
問題 #88
You have a Snowpark Python application that performs several data transformations on a DataFrame representing customer transactions. The application is experiencing performance issues, and you suspect that some transformations are unnecessarily expensive. Which of the following techniques can MOST effectively optimize the performance of your Snowpark application, specifically focusing on minimizing data movement and leveraging Snowflake's query optimization capabilities?
答案:D
解題說明:
Snowpark is designed to push down computations to Snowflake, allowing Snowflake's query optimizer to handle the execution. Using Snowpark's built-in DataFrame transformations allows Snowflake to understand the intent and optimize the query accordingly. Materializing intermediate results using .cache()' (A) can lead to unnecessary data movement. Python UDFs (B) can be useful for complex logic but should be avoided for simple transformations as they bypass Snowflake's optimization capabilities and are generally slower than native SQL functions. Warehouse size (E) is a factor, but optimizing the query logic is more crucial. Using Pandas dataframe is also costly and performance heavy.
問題 #89
Consider the following Snowpark Python code snippet that defines and registers a User-Defined Table Function (UDTF):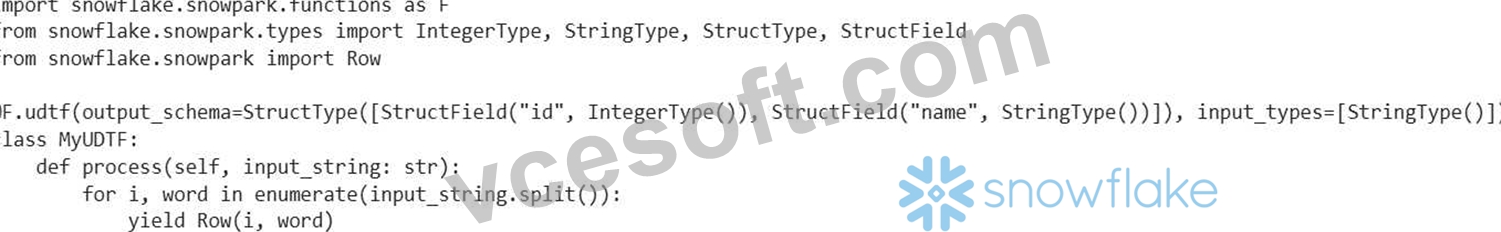
Which of the following statements is MOST accurate regarding the behavior and limitations of this UDTF when used in a Snowpark DataFrame transformation?
答案:D
解題說明:
Option E is the most accurate. When a Snowpark UDTF receives NULL as input, it's passed as 'None' in Python. The provided code defines the 'output_schema' which describes the structure and types of the rows that the UDTF will return. Option A is incorrect because, while Snowflake distributes UDTF processing, the code itself doesn't guarantee parallelism within a single input string. Option B is incorrect; UDTFs can be used with any DataFrame, regardless of whether it's backed by a persistent table. Option C is incorrect because NULL values in the input DataFrame will be passed as 'None' to the 'process' method. Option D is incorrect; Snowpark distributes UDTF execution across worker nodes, not within the driver process.
問題 #90
You are developing a Snowpark application to process customer reviews. You need to use a third-party sentiment analysis library, 'SentimentAnalyzer', which is NOT available in the Anaconda repository. You have the library JAR file stored in an internal artifact repository accessible via HTTP. Which of the following steps are necessary to make this library available to your Snowpark session?
答案:B
解題說明:
The correct approach involves uploading the JAR file to a Snowflake stage and then using 'session.add_import' (or its Scala equivalent) to make it available within the Snowpark session's environment. Creating a UDF directly (A) isn't the correct way to use it within Snowpark DataFrame operations. 'session.add_dependency' (B) is incorrect. is generally used for Python packages, not arbitrary JAR files accessed via HTTP. Using conda and deploying is not required for simple cases (E).
問題 #91
You're developing a Snowpark application that reads data from a Snowflake table, performs several transformations, and then writes the results back to a different table. You want to ensure that the entire process is executed as a single atomic transaction, even if it involves multiple Snowpark DataFrames and operations. Which of the following actions are required to achieve this transactional behavior?
答案:E
解題說明:
Snowflake inherently provides transactional consistency. All operations within a single Snowpark session are automatically executed as a single atomic transaction by default. This is a core feature of Snowflake and doesn't require explicit transaction management in most common scenarios. Options A, B and C are incorrect as Snowflake handles transaction automatically. E describes a possible solution, however, it isn't required.
問題 #92
......
我們都很清楚 Snowflake SPS-C01 認證考試在IT行業中的地位是駐足輕重的地位,但關鍵的問題是能夠拿到Snowflake SPS-C01的認證證書不是那麼簡單的。我們很清楚地知道網上缺乏有高品質的準確性高的相關考試資料。VCESoft的考試練習題和答案可以為一切參加IT行業相關認證考試的人提供一切所急需的資料。它能時時刻刻地提供你們想要的資料,購買我們所有的資料能保證你通過你的第一次Snowflake SPS-C01認證考試。
最新SPS-C01考題: https://www.vcesoft.com/SPS-C01-pdf.html
從Google Drive中免費下載最新的VCESoft SPS-C01 PDF版考試題庫:https://drive.google.com/open?id=122ibdhEubsmTCilzGB2Y1DojRCKaag5V