AI-200 exam dumps have a higher pass rate than products in the same industry. If you want to pass AI-200 certification, then it is necessary to choose a product with a high pass rate. Our study materials guarantee the pass rate from professional knowledge, services, and flexible plan settings. According to user needs, AI-200 exam prep provides everything possible to ensure their success. The 99% pass rate is the proud result of our study materials. If you join, you will become one of the 99%. I believe that pass rate is also a big criterion for your choice of products, because your ultimate goal is to obtain AI-200 Certification. In AI-200 exam dumps, you can do it.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Topic 2: Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Topic 3: Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
| Topic 4: Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
The iPassleader AI-200 Practice Questions are designed and verified by experienced and renowned AI-200 exam trainers. They work collectively and strive hard to ensure the top quality of AI-200 exam practice questions all the time. The AI-200 Exam Questions are real, updated, and error-free that helps you in Microsoft AI-200 exam preparation and boost your confidence to crack the upcoming AI-200 exam easily.
NEW QUESTION # 105
Drag and Drop Question
You are designing Azure Functions for three different backend workloads.
Each workload requires one of the following dispatching models:
- Return an immediate response to a client.
- Process background work from a queue.
- Run code on a fixed schedule.
You need to select the trigger for each requirement.
Which triggers should you select? To answer, move the appropriate triggers to the correct requirements. You may use each trigger once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.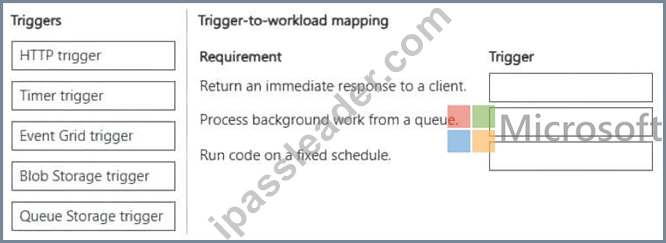
Answer:
Explanation: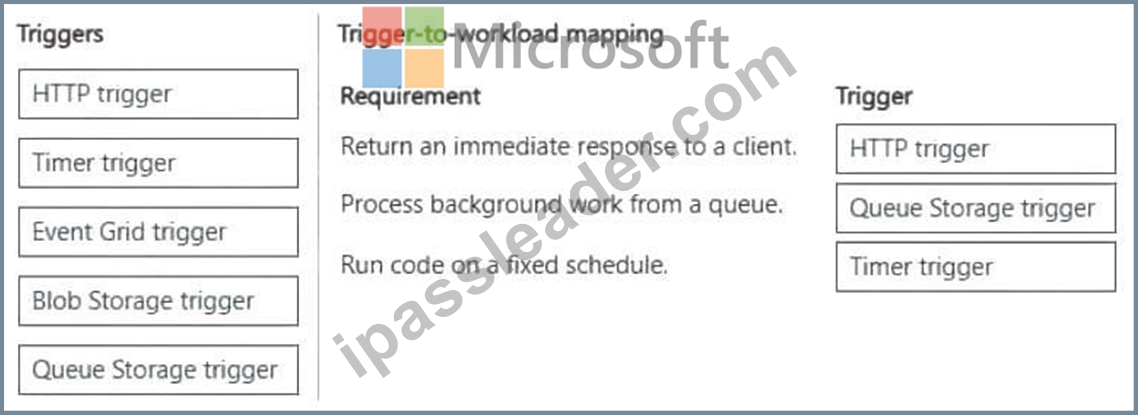
Explanation:
Box 1: HTTP trigger
An HTTP trigger is the best choice for returning an immediate response to a client.
Direct connection: The client makes a standard web request and waits on the same connection.
Low latency: It avoids the delays introduced by routing messages through queues or storage.
Two-way communication: It natively supports returning payload data and HTTP status codes (e.g., 200 OK).
Box 2: Queue Storage Trigger
Azure Queue Storage Trigger or Azure Service Bus Queue Trigger is the best choice to process background work from a queue.
Azure Queue Storage Trigger:
Best for simple, low-cost message queues with high throughput and straightforward FIFO (first-in, first-out) processing needs.
Automatic Scaling: Scales out instances dynamically based on the number of messages waiting in the queue.
Reliability: Automatically handles poison messages and retries failed executions if configured correctly.
Cost Efficiency: Consumes zero compute resources when the queue is empty (especially under the Consumption plan).
Box 3: Timer trigger
An Azure Function with a timer trigger is the standard and ideal choice for running code on a fixed schedule. It acts as a serverless cron job that automatically manages execution intervals, scales automatically, and includes built-in locking mechanisms to prevent duplicate executions across multiple instances.
Reference:
https://levelup.gitconnected.com/request-driven-service-vs-event-driven-service-4bf04d642843?gi=c0bdcb16db5a
https://codilime.com/blog/enabling-first-in-first-out-pattern-microsoft-azure-service-bus-queues-topics/
NEW QUESTION # 106
An application deployed to AKS depends on an internal API hosted in the same cluster. All pods are healthy and report Ready status, but requests between the services time out.
You need to determine whether the issue is related to Kubernetes service configuration or application code.
What should you do first?
Answer: B
NEW QUESTION # 107
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to deploy a batch embedding workload according to the planned application architecture.
What should you use?
Answer: D
Explanation:
Scenario, application architecture
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
YAML-formatted files should be used for this deployment.
In a production-grade Kubernetes architecture, declarative management using configuration files provides the predictability, version control, and automation required for complex microservices.
Declarative Configuration: Kubernetes relies natively on YAML to define the desired state of resources like Deployments, KEDA ScaledObjects (for event-driven Azure Function scaling), and Secrets.
Complex Deployments: Your workload requires setting up multiple components, environmental variables, and scaling rules that cannot be efficiently managed via single-line commands.
GitOps Readiness: Storing configurations in YAML allows you to track changes in source control and deploy updates automatically through CI/CD pipelines.
Reference:
https://developer.okta.com/blog/2022/05/05/kubernetes-microservices-azure
NEW QUESTION # 108
Hotspot Question
You are developing an AI application that retrieves database credentials from Key Vault by using the Azure SDK for Python.
The application must use managed identity for authentication.
You review the following code segment that retrieves a secret from Key Vault.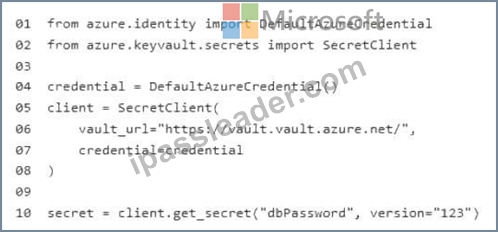
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.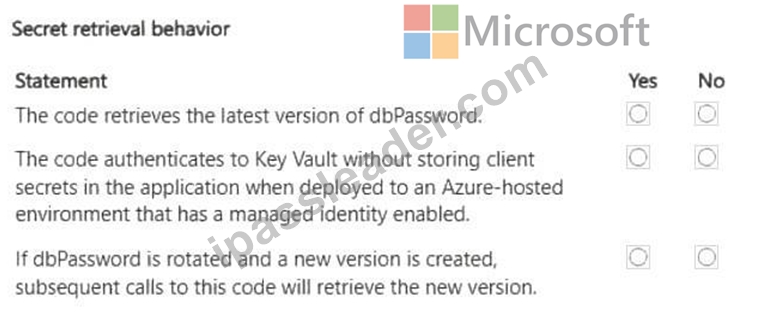
Answer:
Explanation: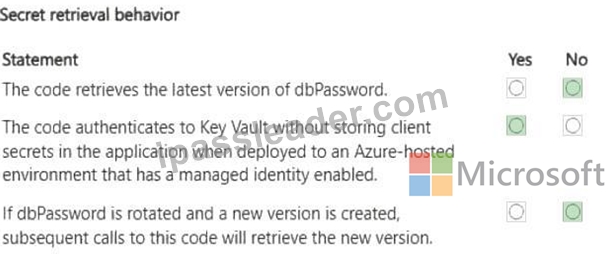
Explanation:
Box 1: No
No, this code will not retrieve the latest version of dbPassword.
Instead, it explicitly retrieves the specific version designated by the string "123".
To pull the latest active version of a secret, omit the version parameter entirely from the get_secret function.python# Change this line:
secret = client.get_secret("dbPassword", version="123")
# To this line:
secret = client.get_secret("dbPassword")
Box 2: Yes
Yes, the code will successfully authenticate to Azure Key Vault without storing client secrets when deployed to an Azure-hosted environment with a managed identity enabled.
DefaultAzureCredential Behavior: This class is a sequential chaining credential mechanism.
When deployed to Azure (such as Azure App Service, Azure VMs, or Azure Functions), it automatically looks for an active Managed Identity environment endpoint to fetch an access token.
Zero Secret Storage: Because the platform relies on the underlying Azure host infrastructure to handle identity token generation, you do not need to hardcode client secrets, passwords, or certificates anywhere inside your application code or configuration settings.
Box 3: No
No, subsequent calls to this code will not retrieve the new version.
By explicitly including version="123" in the get_secret method, you are requesting a specific immutable version of the secret.
Reference:
https://learn.microsoft.com/en-us/azure/key-vault/secrets/quick-create-python
NEW QUESTION # 109
You are reviewing the Python tracing configuration for an application that must send distributed traces to Azure Monitor.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.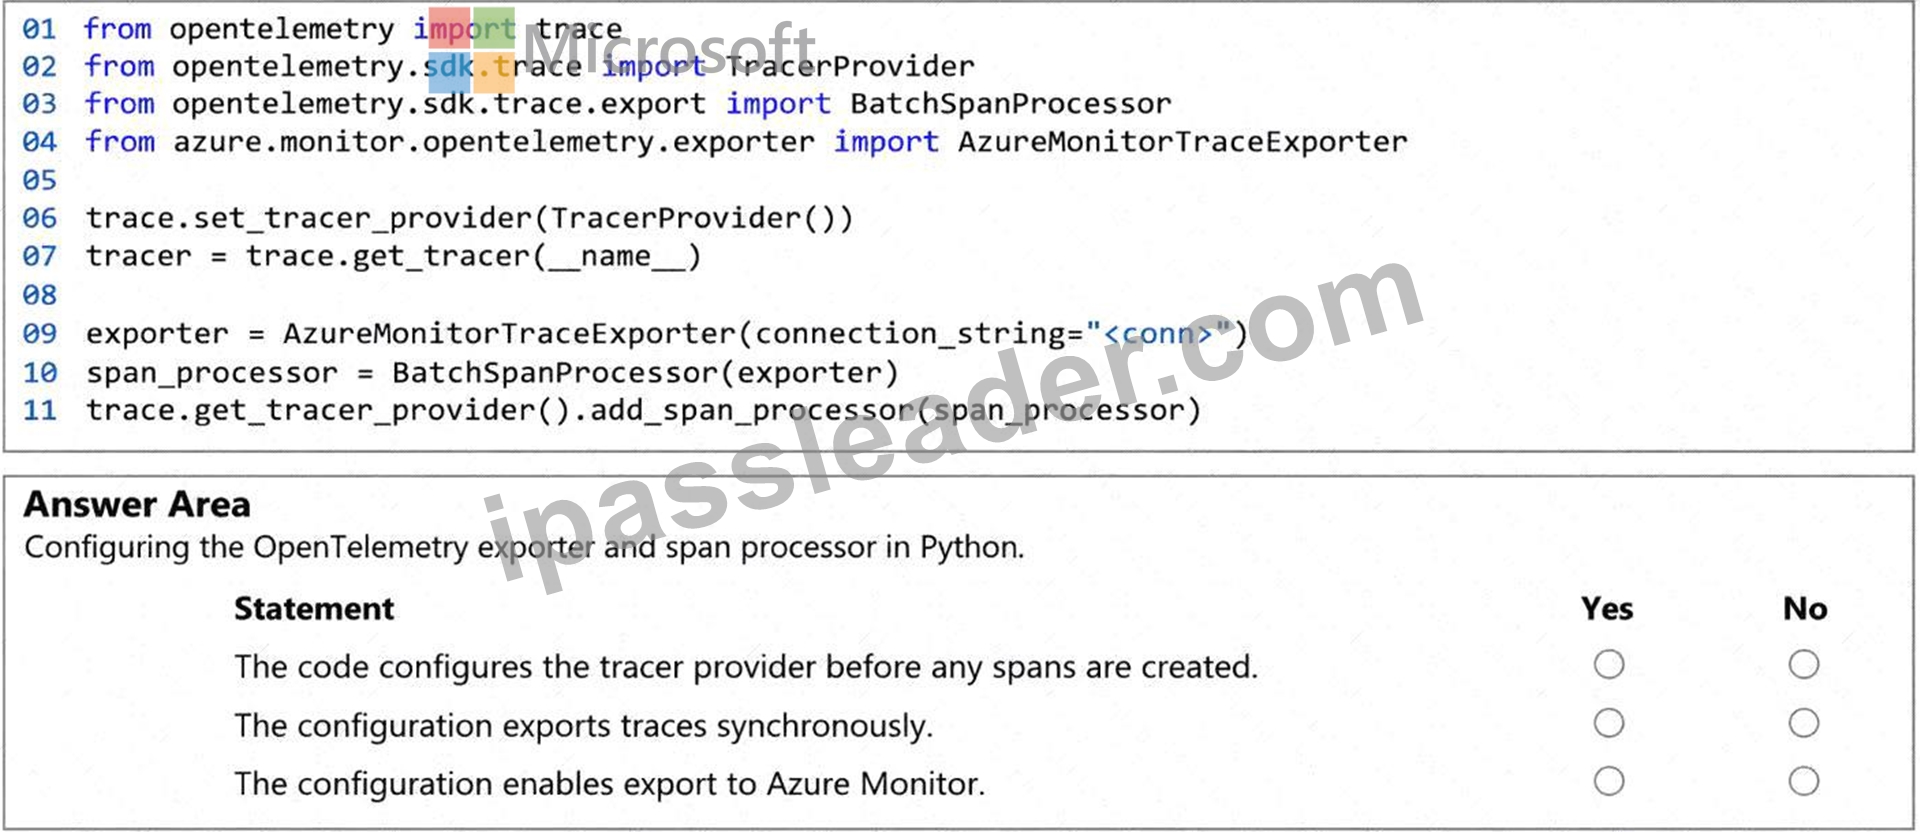
Answer:
Explanation: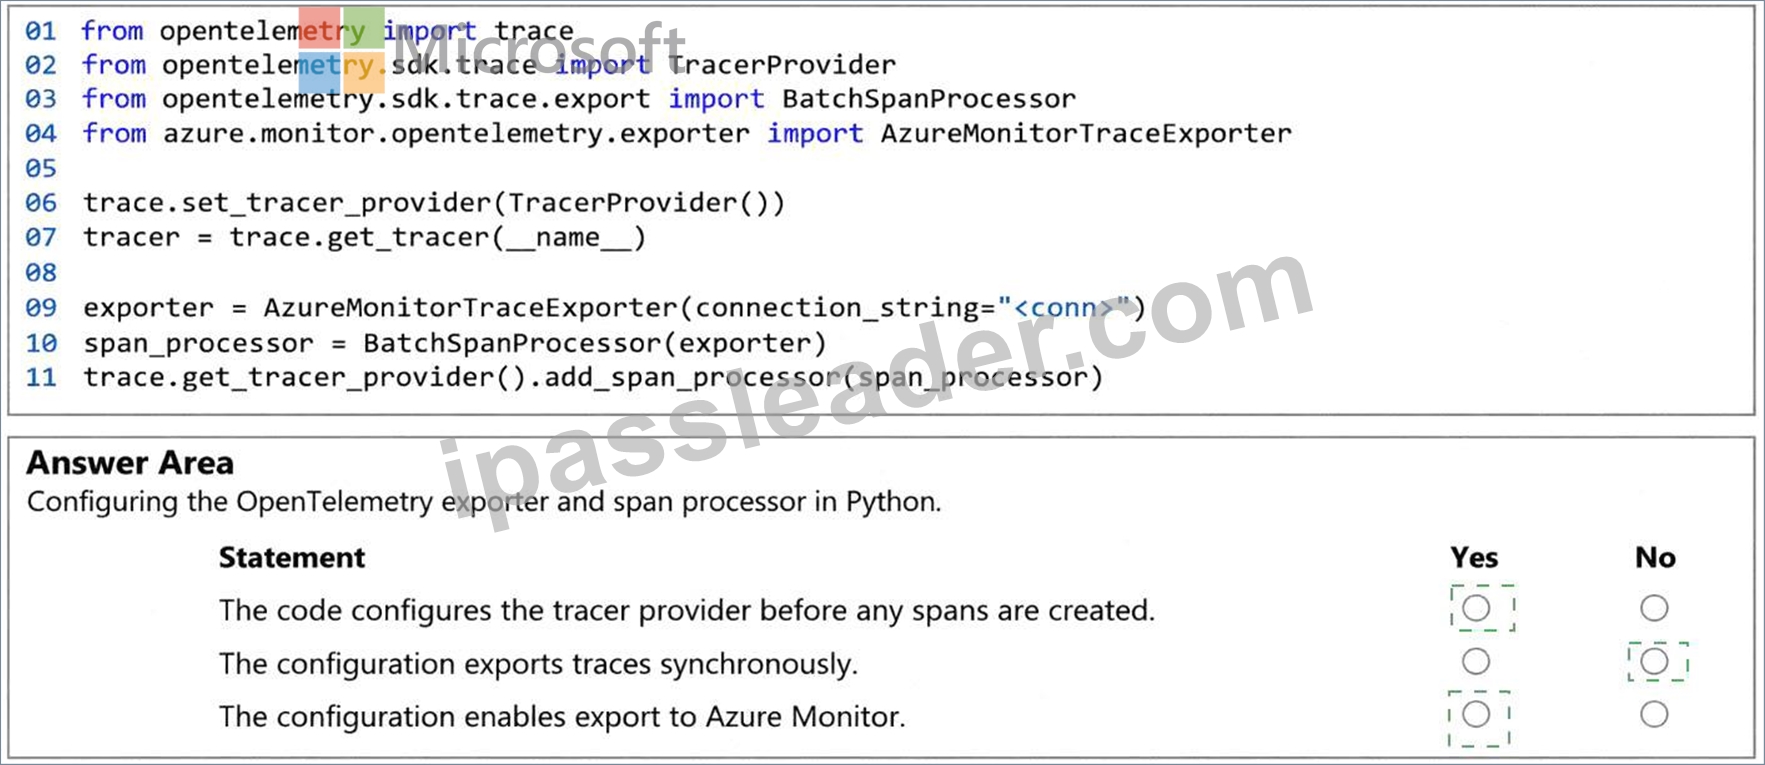
Explanation:
* The code configures the tracer provider before any spans are created: Yes
* The configuration exports traces synchronously: No
* The configuration enables export to Azure Monitor: Yes
The first statement is Yes. The code calls trace.set_tracer_provider(TracerProvider()) before obtaining the tracer and before any span-creation operation occurs. In OpenTelemetry, retrieving a tracer by using trace.
get_tracer() does not itself create a span; spans are created later through methods such as start_span() or start_as_current_span().
The second statement is No. The code uses BatchSpanProcessor, which batches completed spans and exports them through a background processing mechanism rather than exporting every span synchronously on the application ' s execution path. OpenTelemetry documentation states that BatchSpanProcessor batches ended spans before sending them to the configured exporter, and the Python implementation uses a background thread for export processing.
The third statement is Yes. AzureMonitorTraceExporter is instantiated with an Azure Monitor/Application Insights connection string and passed to BatchSpanProcessor. That processor is then registered with the tracer provider. Microsoft provides this same pattern specifically for exporting OpenTelemetry traces to Azure Monitor/Application Insights.
Study Guide references: Azure Monitor OpenTelemetry; TracerProvider; BatchSpanProcessor; AzureMonitorTraceExporter; distributed tracing.
NEW QUESTION # 110
......
All of our considerate designs have a strong practicability. We are still researching on adding more useful buttons on our AI-200 test answers. The aim of our design is to improve your learning and all of the functions of our products are completely real. Then the learning plan of the AI-200 Exam Torrent can be arranged reasonably. You need to pay great attention to the questions that you make lots of mistakes. If you are interested in our products, click to purchase and all of the functions. Try to believe us and give our AI-200 exam guides a chance to certify.
AI-200 Test Pdf: https://www.ipassleader.com/Microsoft/AI-200-practice-exam-dumps.html