To be the best global supplier of electronic DP-750 study materials for our customers through innovation and enhancement of our customers' satisfaction has always been our common pursuit. The advantages of our DP-750 study guide are more than you can count. As the most important factor that our worthy customers will consider-the pass rate, we are proud to tell you that we have a pass rate high as 98% to 100% on our DP-750 training engine, which is also unique in the market. And our price of the DP-750 practice guide is also reasonable.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
Our web-based practice exam software is an online version of the Microsoft DP-750 practice test. It is also quite useful for instances when you have internet access and spare time for study. To study and pass the Microsoft DP-750 Exam on the first attempt, our web-based Microsoft DP-750 practice test software is your best option. You will go through Implementing Data Engineering Solutions Using Azure Databricks mock exams and will see for yourself the difference in your preparation.
NEW QUESTION # 27
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table1 is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table1.
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: B
Explanation:
Schema evolution allows the target Delta table to incorporate compatible new source columns instead of failing when the incoming schema changes. This is the appropriate response to additive schema drift and avoids manually rebuilding tables whenever the source evolves. Creating a separate table for every schema version would fragment the dataset and increase operational effort. Disabling schema enforcement removes valuable protection against incompatible or corrupt data rather than handling legitimate evolution safely. Row filters operate on records and cannot remove an unexpected column from the incoming schema. With schema evolution enabled, the pipeline can detect new fields, update the target schema, and continue processing while retaining Delta Lake's transactional guarantees. The solution therefore supports changing source data without sacrificing the managed-table architecture.
NEW QUESTION # 28
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
* asset.id
* asset, type
* asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.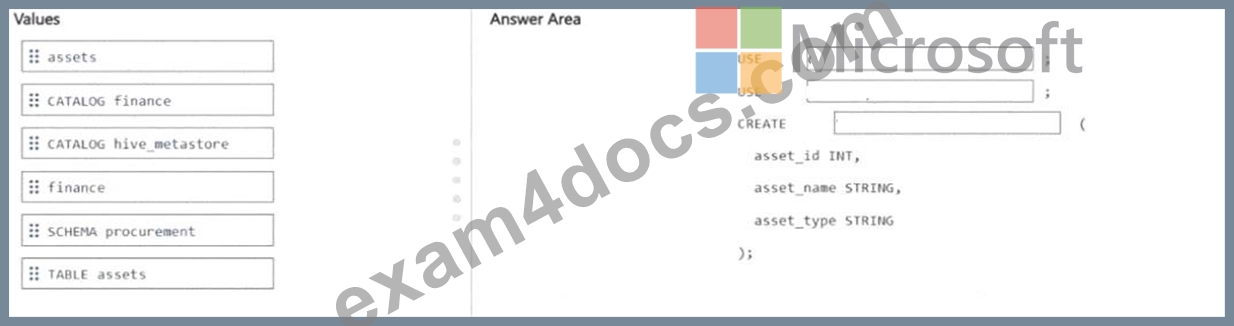
Answer:
Explanation: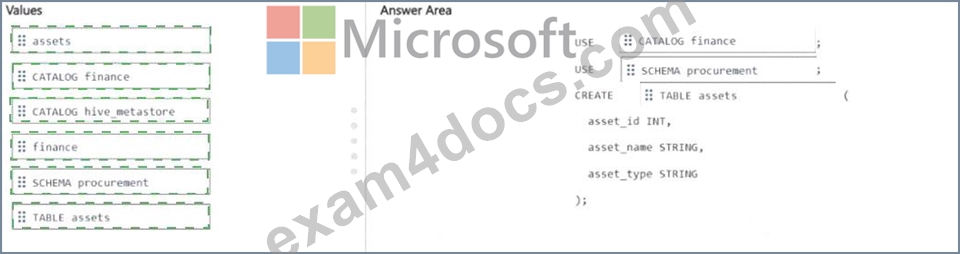
Explanation:
The correct SQL statement uses the full three-part namespace finance.procurement.assets with the three specified columns.
In Unity Catalog, every object lives in a three-tier hierarchy: catalog # schema # table. Using the full path finance.procurement.assets guarantees the table lands in the right schema regardless of the session's current catalog or schema context. Omitting the catalog or schema name relies on the session default, which may not be finance.procurement - a silent mistake that's hard to catch.
The column names asset_id, asset_type, and asset_name must match the spec exactly. Unity Catalog applies access controls, lineage tracking, and tagging at the column level, so the names are meaningful beyond just the schema. Once created, any GRANT statements can target specific columns for fine-grained access control.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- table-using
NEW QUESTION # 29
You need to configure resiliency for a job in Lakeflow Jobs named Job1 to meet the pipeline deployment and operation requirements.
What should you do?
Answer: C
Explanation:
Task-level retries allow the ingestion task to recover automatically from transient failures without rerunning unrelated tasks or restarting the complete workflow. Downstream tasks remain governed by their dependencies and start only after ingestion succeeds. This provides focused failure recovery and reduces unnecessary compute consumption. Disabling retries and relying on manual execution directly contradicts the requirement for resilient, automated pipeline operation. Setting the retry count to zero also prevents automatic retry behavior. Restarting the workflow from the first task whenever any task fails would repeat completed processing, increase costs, and potentially reingest data unnecessarily. Lakeflow Jobs supports individual retry policies for tasks, including the number of retries and delay between attempts, making option D the most controlled and operationally efficient configuration. Microsoft Learn
NEW QUESTION # 30
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
Ensure that amount is always greater than 0.
Prevent an update to Table1 from being committed when data that violates rule1 is detected.
Which statement should you execute?
Answer: D
Explanation:
The correct answer is C - @dlt.expect_or_fail.
Lakeflow Spark Declarative Pipelines (SDP) offers three expectation decorators, each with a different violation response:
@dlt.expect - logs the violation as a metric but writes all records, including bad ones, to the table. Suitable for monitoring only.
@dlt.expect_or_drop - drops violating records and continues the pipeline. The table receives only clean rows, but the pipeline update commits successfully.
@dlt.expect_or_fail - fails the entire pipeline update when a violation is detected. The table update is never committed. This is the correct choice when data integrity is non-negotiable: 'Prevent an update to Table1 from being committed when data that violates rule1 is detected.'
@dlt.expect_all_or_drop takes a dictionary of rules and drops violating rows but still commits - it doesn't halt the pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 31
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! contains three tasks named Task1, Task2. and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.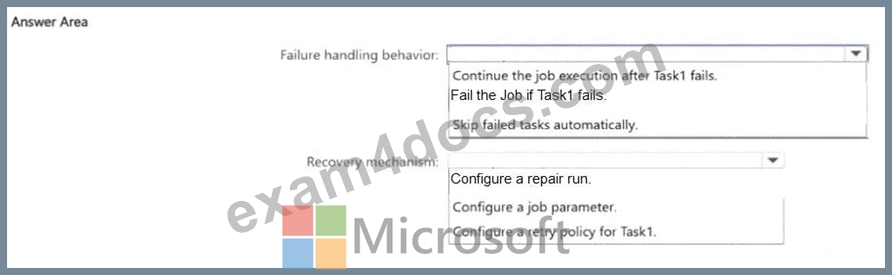
Answer:
Explanation: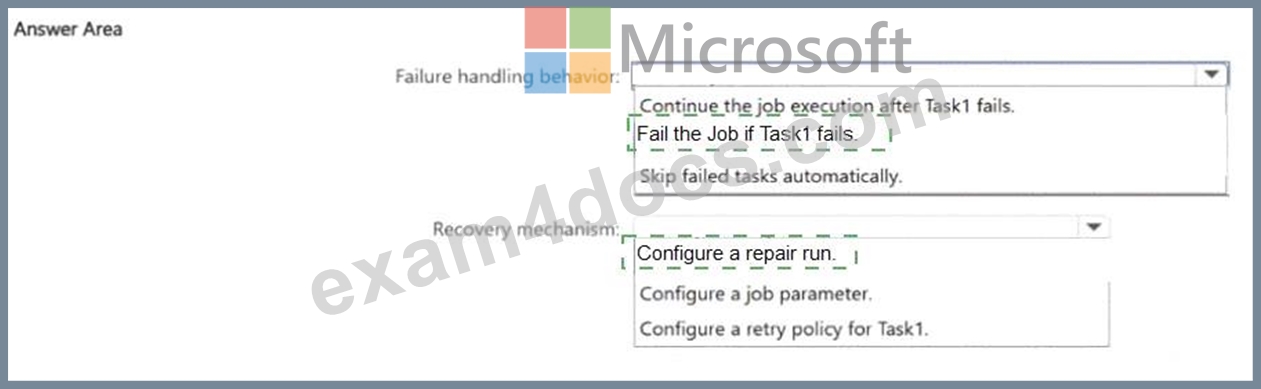
Explanation:
Two configurations are needed:
Task dependency with 'All succeeded' run condition: Set Task2 and Task3 to depend on Task1. Change the run condition on Task2 and Task3 to 'All succeeded' - this means they only execute when all their upstream dependencies (Task1) have succeeded. If Task1 fails, both downstream tasks are skipped automatically, not run with failed inputs.
Repair run for recovery: Lakeflow Jobs' Repair Run feature lets you re-execute only the tasks that failed (Task1 in this case) and their dependents (Task2 and Task3 if they were skipped), while skipping Task1 and any other tasks that already completed successfully. Successfully completed tasks are never re-executed during repair - their results are reused as-is.
Together these provide both controlled failure propagation (nothing runs downstream of a failure) and efficient recovery.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 32
......
Now you can pass Implementing Data Engineering Solutions Using Azure Databricks exam without going through any hassle. You can only focus on DP-750 exam dumps provided by the Exam4Docs, and you will be able to pass the Implementing Data Engineering Solutions Using Azure Databricks test in the first attempt. We provide high quality and easy to understand DP-750 pdf dumps with verified Microsoft DP-750 for all the professionals who are looking to pass the DP-750 exam in the first attempt. The DP-750 training material package includes latest DP-750 PDF questions and practice test software that will help you to pass the DP-750 exam.
Exam DP-750 Objectives: https://www.exam4docs.com/DP-750-study-questions.html