Our AI-200 vce dumps constantly get updated according to the changes of exam requirement from the certification center. Our experts created AI-200 practice exam to help our candidates get used to the formal test and face the challenge with great confidence. One-year free updating of AI-200 Test Answers will be allowed after payment and one or two days' preparation before test will be recommend.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Topic 2: Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Topic 3: Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
| Topic 4: Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
The Microsoft AI-200 Certification is a valuable credential in the modern world. The Microsoft AI-200 certification exam offers a great opportunity for beginners and experienced professionals to validate their skills and knowledge level. With the one certification Developing AI Cloud Solutions on Azure exam you can upgrade your expertise and knowledge.
NEW QUESTION # 117
You are developing a Java application to be deployed in Azure. The application stores sensitive data in Azure Cosmos DB.
You need to configure Always Encrypted to encrypt the sensitive data inside the application.
What should you do first?
Answer: C
Explanation:
To configure Always Encrypted (client-side encryption) for your Java application using Azure Cosmos DB, you must first create a customer-managed key (CMK) and store it in a new Azure Key Vault instance Reference:
https://lennilobel.wordpress.com/2022/08/20/configuring-client-side-encryption-aka-always-encrypted-in-azure-cosmos-db/
NEW QUESTION # 118
An AI application retrieves configuration values from App Configuration. The application uses static configuration.
You need to implement a solution that supports dynamic configuration updates and minimizes latency for application requests.
What should you do?
Answer: A
Explanation:
You should cache configuration values with a refresh interval.
Enables Dynamic Configuration: Azure App Configuration providers natively support a cache- polling mechanism. Once the refresh interval expires, the application checks for updates and reloads configuration values automatically without requiring an application restart.
Minimizes Latency: By pulling configuration values from a local, in-memory cache for all intermediary requests, you completely bypass the network latency of making a remote API call to Azure on every single application request.
Prevents Throttling: Relying on cached values prevents your application from exhausting your App Configuration resource's request quota.
Reference:
https://learn.microsoft.com/en-us/azure/azure-app-configuration/howto-best-practices
NEW QUESTION # 119
Your application stores conversation history so a multi-turn chatbot can reference earlier turns, but the context window is limited. You need to keep the most relevant history within token limits.
What should you implement?
Answer: C
Explanation:
Progressive summarization of older conversation turns, combined with keeping recent turns verbatim, is a standard technique to preserve conversational context within a limited token budget without abruptly losing history.
NEW QUESTION # 120
You are configuring sampling for a distributed application that sends traces to Azure Monitor. The solution must:
* Preserve upstream sampling decisions across distributed traces
* Capture all spans during local testing.
* Sample 10 percent of traces in production.
You need to apply the appropriate sampling configuration for each requirement.
What should you do? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once or not at all. You may need to move the split bar Between panes or scroll to view content.
NOTE: Each correct selection is worth one point.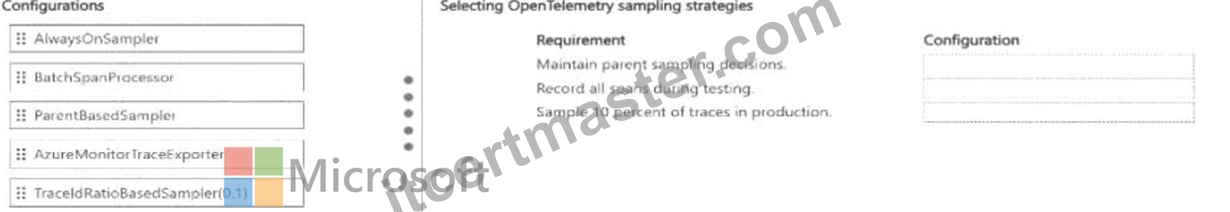
Answer:
Explanation: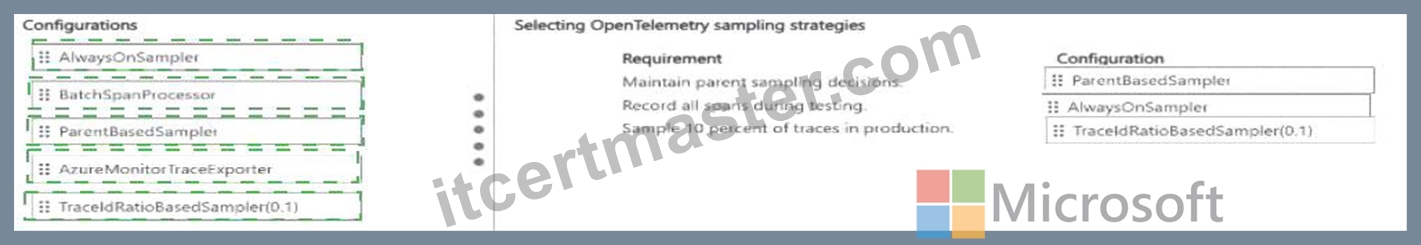
Explanation: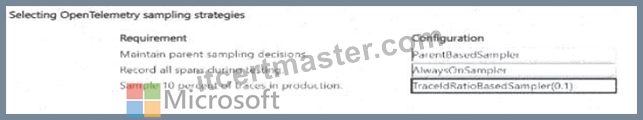
Verified answer: Preserve parent sampling decisions: ParentBasedSampler. Capture all spans locally:
AlwaysOnSampler. Sample 10% in production: TraceIdRatioBasedSampler(0.1).
Detailed Explanation: Parent-based sampling propagates the sampling decision from the upstream parent, preventing broken sampling decisions across a distributed trace. AlwaysOnSampler records every span, which is suitable for local test environments where complete trace visibility is more important than telemetry volume. TraceIdRatioBasedSampler with 0.1 selects approximately ten percent of traces based on trace identifiers, providing deterministic fixed-ratio sampling for production. A batch span processor and an exporter control processing/export, not the sampling decision itself.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | OpenTelemetry sampling in Azure Monitor | Enable Azure Monitor OpenTelemetry
NEW QUESTION # 121
Drag and Drop Question
A semantic search application queries Azure Database for PostgreSQL and stores document embeddings and metadata in a table with the following columns:
- embedding (pgvector)
- department
- created_at
The application must return the top five most similar documents for a given query embedding only from the finance department.
You need to implement semantic retrieval with metadata filtering.
Which query components should you select? To answer, move the appropriate query components to the correct requirements. You may use each query component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.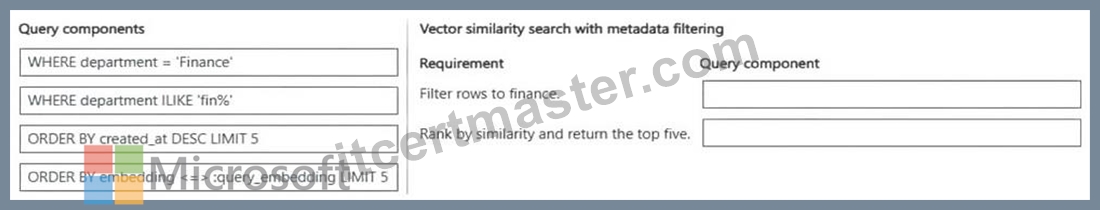
Answer:
Explanation: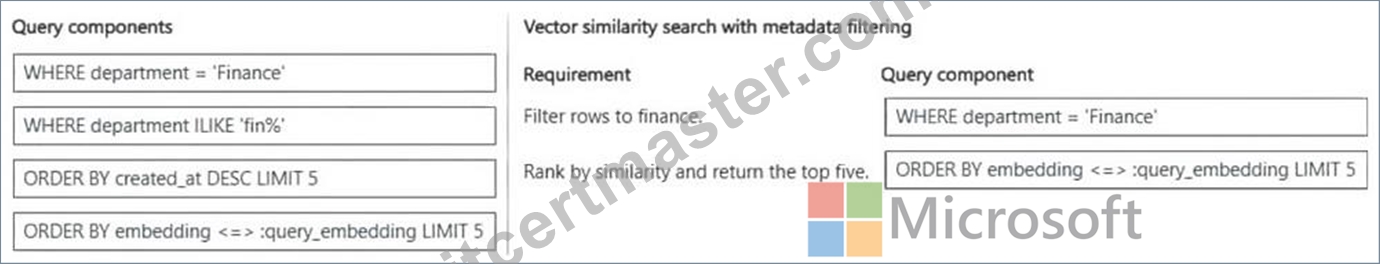
Explanation:
Box 1: WHERE department = 'Finance'
Box 2: ORDER BY embedding <=> :query_vector LIMIT 5
To rank and return the top five most similar documents by similarity in Microsoft Learn, use the ORDER BY embedding <=> [query_vector] expression combined with LIMIT 5, where <=> computes the cosine distance.
Reference:
https://learn.microsoft.com/en-us/azure/postgresql/extensions/how-to-use-pgvector
NEW QUESTION # 122
......
There are many merits of our product on many aspects and we can guarantee the quality of our AI-200 practice engine. Firstly, our experienced expert team compile them elaborately based on the real exam. Secondly, both the language and the content of our AI-200 study materials are simple. The content emphasizes the focus and seizes the key to use refined AI-200 Questions and answers to let the learners master the most important information by using the least practic. Three, we provide varied functions to help the learners learn our study materials and prepare for the exam.
Pass AI-200 Guide: https://www.itcertmaster.com/AI-200.html