DOWNLOAD the newest Exams4Collection MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1HPNwAW2pccd7dAZ0zUqECS17NMnHVIVX
Exams4Collection Amazon Certification Exam comes in three different formats so that the users can choose their desired design and prepare Amazon MLA-C01 exam according to their needs. The first we will discuss here is the PDF file of real Amazon MLA-C01 Exam Questions. It can be taken to any place via laptops, tablets, and smartphones.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Valid Braindumps MLA-C01 Files <<
The top Amazon MLA-C01 certification benefits are proven skills, more career opportunities, an increase in salary, instant promotion, and membership in professional community groups. Surely all these MLA-C01 certification benefits are immediately available after passing the Amazon MLA-C01 Certification Exam. To do this you just need to pass the MLA-C01 certification exam which is not easy to pass.
NEW QUESTION # 167
A company needs to combine data from multiple sources. The company must use Amazon Redshift Serverless to query an AWS Glue Data Catalog database and underlying data that is stored in an Amazon S3 bucket.
Select and order the correct steps from the following list to meet these requirements. Select each step one time or not at all. (Select and order three.)
* Attach the IAM role to the Redshift cluster.
* Attach the IAM role to the Redshift namespace.
* Create an external database in Amazon Redshift to point to the Data Catalog schema.
* Create an external schema in Amazon Redshift to point to the Data Catalog database.
* Create an IAM role for Amazon Redshift to use to access only the S3 bucket that contains underlying data.
* Create an IAM role for Amazon Redshift to use to access the Data Catalog and the S3 bucket that contains underlying data.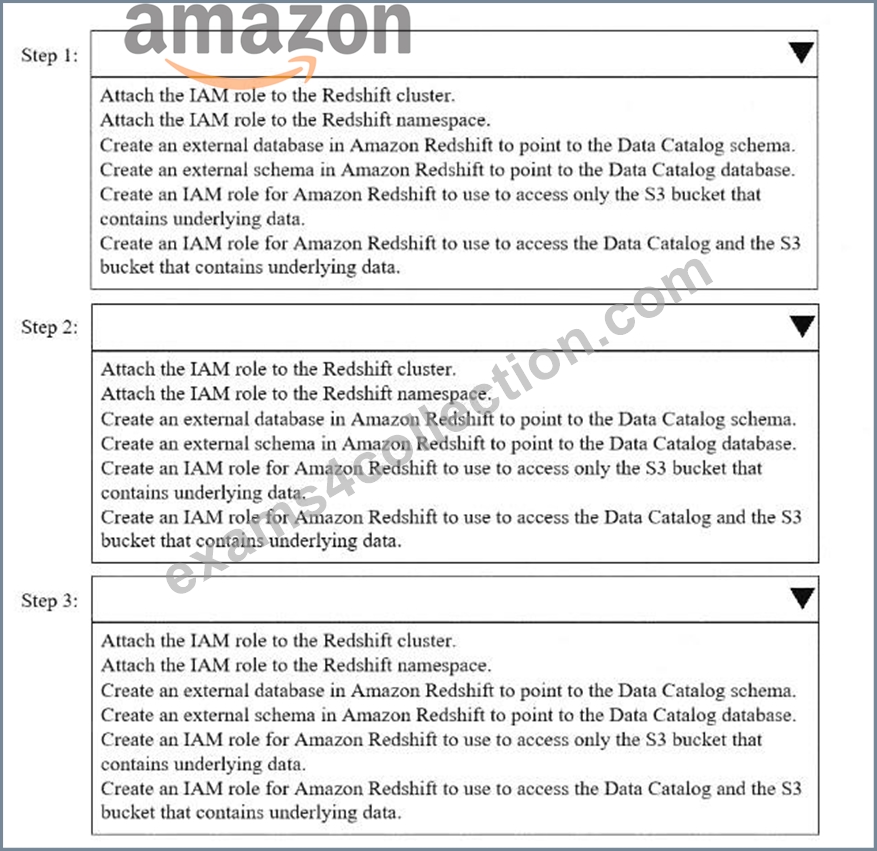
Answer:
Explanation: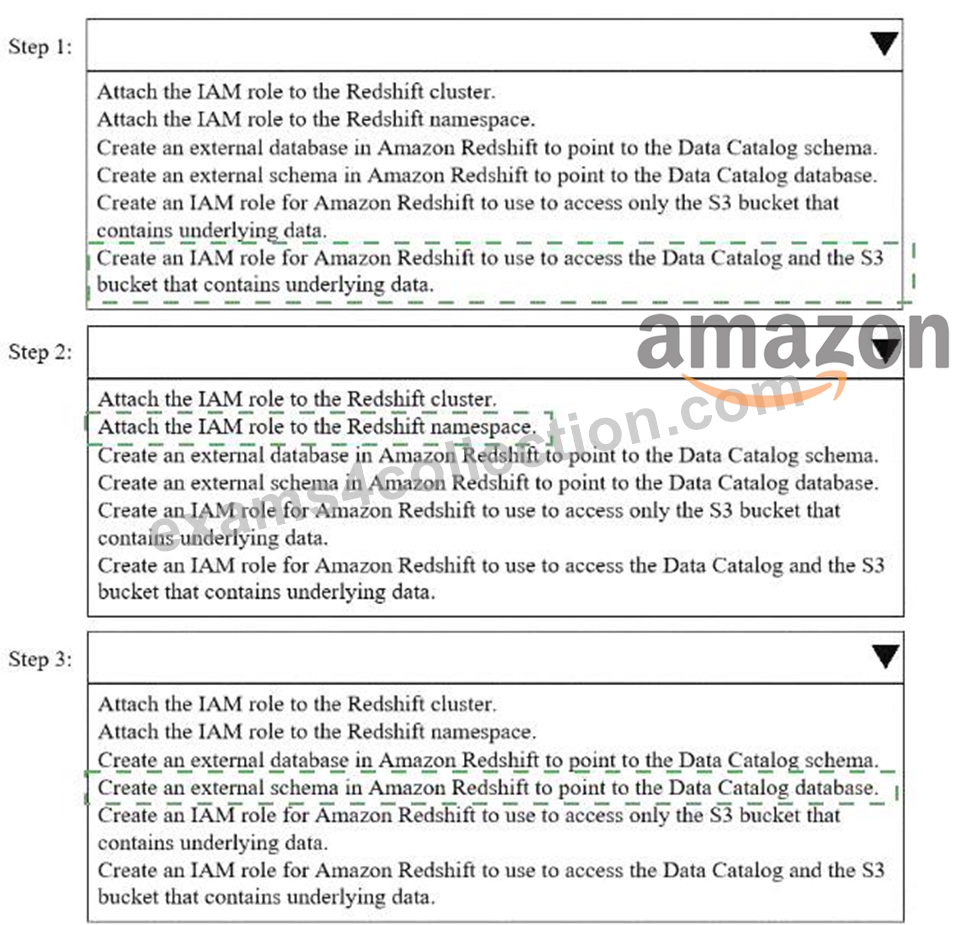
Explanation:
Step 1
Create an IAM role for Amazon Redshift to use to access the Data Catalog and the S3 bucket that contains underlying data.
This role must include:
Permissions for AWS Glue Data Catalog (e.g., glue:GetDatabase, glue:GetTables) Permissions for the Amazon S3 bucket that stores the underlying data Step 2 Attach the IAM role to the Redshift namespace.
Redshift Serverless uses a namespace, not a cluster, so the role must be associated with the namespace to allow Redshift to assume it when querying external data.
Step 3
Create an external schema in Amazon Redshift to point to the Data Catalog database.
The external schema maps Redshift to the Glue Data Catalog database so Redshift can query the tables stored in S3.
NEW QUESTION # 168
A company uses the Amazon SageMaker AI Object2Vec algorithm to train an ML model. The model performs well on training data but underperforms after deployment. The company wants to avoid overfitting the model and maintain the model's ability to generalize.
Which solution will meet these requirements?
Answer: D
Explanation:
The described behavior-strong performance on training data but poor performance in production-is a classic sign of overfitting. AWS documentation for Amazon SageMaker Object2Vec highlights early stopping as a key regularization technique to prevent models from learning noise in the training data.
The early_stopping_patience hyperparameter controls how many additional epochs the training job will run after the validation loss stops improving. Decreasing this value causes training to stop earlier, reducing the chance that the model overfits to the training dataset.
Option B increases batch size, which may improve training efficiency but does not directly address overfitting. Option C decreases the dropout rate, which actually increases overfitting risk, since dropout is a regularization mechanism. Option D increases epochs, which further worsens overfitting.
AWS best practices emphasize early stopping combined with validation metrics as one of the most effective ways to maintain generalization performance in neural embedding models such as Object2Vec.
Therefore, Option A is the correct and AWS-aligned solution.
NEW QUESTION # 169
A company is planning to use Amazon SageMaker to make classification ratings that are based on images. The company has 6 GB of training data that is stored on an Amazon FSx for NetApp ONTAP system virtual machine (SVM). The SVM is in the same VPC as SageMaker.
An ML engineer must make the training data accessible for ML models that are in the SageMaker environment.
Which solution will meet these requirements?
Answer: C
NEW QUESTION # 170
Case study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
Before the ML engineer trains the model, the ML engineer must resolve the issue of the imbalanced data.
Which solution will meet this requirement with the LEAST operational effort?
Answer: C
Explanation:
Problem Description:
* The training dataset has a class imbalance, meaning one class (e.g., fraudulent transactions) has fewer samples compared to the majority class (e.g., non-fraudulent transactions). This imbalance affects the model's ability to learn patterns from the minority class.
Why SageMaker Data Wrangler?
* SageMaker Data Wrangler provides a built-in operation called "Balance Data," which includes oversampling and undersampling techniques to address class imbalances.
* Oversampling the minority class replicates samples of the minority class, ensuring the algorithm receives balanced inputs without significant additional operational overhead.
Steps to Implement:
* Import the dataset into SageMaker Data Wrangler.
* Apply the "Balance Data" operation and configure it to oversample the minority class.
* Export the balanced dataset for training.
Advantages:
* Ease of Use: Minimal configuration is required.
* Integrated Workflow: Works seamlessly with the SageMaker ecosystem for preprocessing and model training.
* Time Efficiency: Reduces manual effort compared to external tools or scripts.
NEW QUESTION # 171
A term frequency-inverse document frequency (tf-idf) matrix using both unigrams and bigrams is built from a text corpus consisting of the following two sentences:
1. Please call the number below.
2. Please do not call us.
What are the dimensions of the tf-idf matrix?
Answer: A
Explanation:
There are 2 sentences, 8 unique unigrams, and 8 unique bigrams, so the result would be (2,16).
The phrases are "Please call the number below" and "Please do not call us." Each word individually (unigram) is "Please," "call," "the," "number," "below," "do," "not," and "us." The unique bigrams are "Please call," "call the," "the number," "number below," "Please do," "do not,"
"not call," and "call us."
NEW QUESTION # 172
......
No matter you are exam candidates of high caliber or newbies, our Amazon MLA-C01 exam quiz will be your propulsion to gain the best results with least time and reasonable money. Not only because the outstanding content of Amazon MLA-C01 Real Dumps that produced by our professional expert but also for the reason that we have excellent vocational moral to improve our Amazon MLA-C01 learning materials quality.
Latest MLA-C01 Exam Bootcamp: https://www.exams4collection.com/MLA-C01-latest-braindumps.html
BONUS!!! Download part of Exams4Collection MLA-C01 dumps for free: https://drive.google.com/open?id=1HPNwAW2pccd7dAZ0zUqECS17NMnHVIVX