P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by Actual4Cert: https://drive.google.com/open?id=1ePqRKxIIHwjZ-T6li69PT_o6Cjg_1ljF
They work closely and check all Snowflake SPS-C01 exam practice test questions step by step and ensure the top standard of SPS-C01 exam questions all the time. So rest assured that with the SPS-C01 exam dumps you will get everything that you need to prepare and pass the Snowflake SPS-C01 Certification Exam with good scores. Countless Snowflake Certified SnowPro Specialty - Snowpark exam candidates have passed their SPS-C01 exam and they all got help from real and updated Snowflake SPS-C01 exam questions. You can also be the next successful candidate for the SPS-C01 certification exam.
| Section | Weight | Objectives |
|---|---|---|
| Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
| Data Transformations and Operations | 35% | - DataFrame manipulation
|
| Snowpark API and Development | 30% | - Multi-language support
|
| Performance and Best Practices | 10% | - Security and governance
|
>> Latest SPS-C01 Test Voucher <<
There are three versions of SPS-C01 training materials for the candidate of you, and different versions have different advantages, you can use it in accordance with your own habit. Free update for each version for one year, namely, you don’t need to buy the same version for many times, and the update version will send to you automatically. You will get the latest version of SPS-C01 Training Materials.
NEW QUESTION # 216
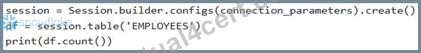
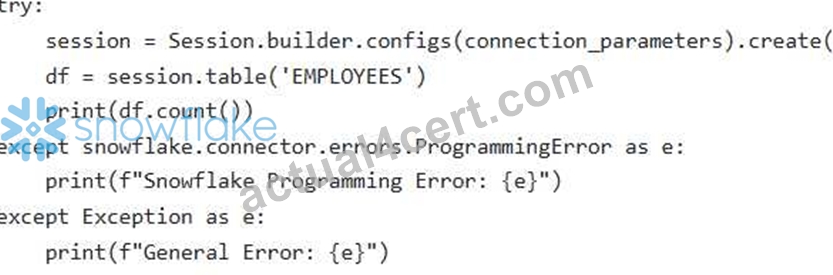
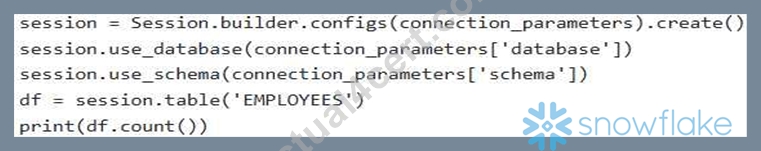
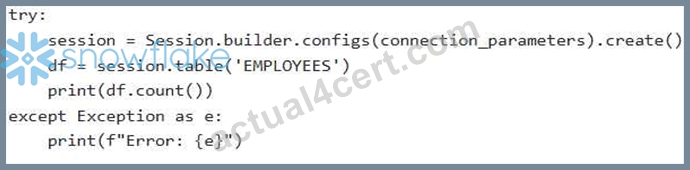
You are developing a Snowpark application that needs to access data from a Snowflake table called 'EMPLOYEES. You want to create a Snowpark DataFrame representing this table. However, you are facing issues with the connection and believe that the database, schema, or warehouse attributes may not be set up correctly for the session. Which of the following code snippets, used in conjunction, BEST demonstrates how to create a Snowpark session with robust error handling to identify and address potential connection issues before attempting to create the DataFrame?
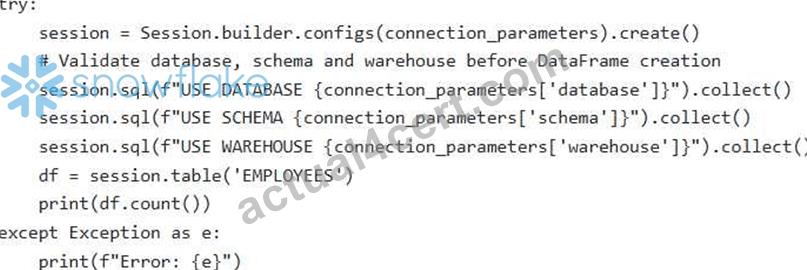
Answer: B,E
Explanation:
The combination of option C and E provides the most robust solution. Option C validates the critical database, schema, and warehouse parameters before attempting to create the DataFrame. If any of these parameters are incorrect, the 'USE statements will fail, and the 'try...except' block will catch the exception. Then Option E specifically catches 'snowflake.connector.errors.ProgrammingError' which would be raised if database/schema/warehouse is not set up correctly. This allows targeted debugging. A and B only catch general errors after the fact, and D is uses deprecated use_database and use_schema calls.
NEW QUESTION # 217
You have a Snowpark DataFrame named containing daily sales transactions. The DataFrame includes columns like 'transaction_id' , 'product id', 'sale_date', and 'sale_amount'. You need to perform the following transformations and persist the results: (1) Calculate the total sales amount for each product on a daily basis. (2) Store the aggregated results into a new table named , partitioned by 'sale_date'. (3) Ensure that if the table already exists, the new data is appended to the existing table. Which of the following code blocks achieve these requirements in the most efficient and correct manner?





Answer: A
Explanation:
Option A is the most efficient and correct. It first aggregates the data as required, then uses 'mode('append')' to add new data without overwriting existing data, and for partitioning. Option B will overwrite existing data. Option C is equivalent to option A, but is a less common coding style. Option D renames the default aggregate column name which is less readable but also works correctly. Option E, 'mergeSchema' isn't a valid option to be passed.
NEW QUESTION # 218
You are developing a Snowpark application that uses a Python UDF to perform geocoding operations. This UDF relies on a third-party geocoding library and a large dataset of geographical data stored in a file named 'geodata.db'. The UDF needs to be operationalized with minimal latency. Which of the following strategies will result in the FASTEST execution of the UDF and optimal resource utilization?
Answer: A
Explanation:
Option E is the most efficient strategy. Packaging the library and data file in a ZIP, referencing it with 'imports' , and using a global variable with caching within the UDF minimizes latency by loading the data only once per worker. It also benefits from utilizing the parallel processing capabilities of Snowpark. Using Java UDF's (C) is less efficient, unless it is highly optimized since java conversion can happen and adds overhead . Relying on external geocoding services (D) introduces network latency and is not ideal for performance. While a custom Anaconda channel (B) can simplify dependency management, it does not address the issue of loading the large 'geodata.db' file efficiently. Option A addresses the dependency managment but performance is not addressed.
NEW QUESTION # 219
You have created a Snowpark stored procedure in Python that accesses a Snowflake stage to read configuration files. To enhance security, you want to grant the stored procedure specific permissions to only read files from that stage, without granting broader account- level access. Which of the following approaches is the MOST secure and granular way to achieve this?
Answer: A
Explanation:
Using 'EXECUTE AS CALLER ensures the stored procedure executes with the privileges of the user calling it. This is the most secure and granular approach because you don't need to grant any specific privileges to the stored procedure itself. The user calling it must already have the necessary permissions to access the stage.
NEW QUESTION # 220
You are developing a Snowpark application that needs to connect to Snowflake using programmatic access. You want to use a secure method of authentication. Which of the following methods, when passed as parameters to the 'snowpark.Session.builder.configS method, would be MOST secure and appropriate for production environments?
Answer: C,E
Explanation:
Using 'oauth_access_token' and 'private_key' (especially when stored securely) are more secure than directly passing username and password. OAuth and Key Pair authentication are recommended for production environments because they avoid storing or transmitting passwords directly. Options A & B are vulnerable because they expose credentials directly in the code or configuration. Option E is incorrect because simply setting the authenticator does not ensure the user authentication will happen with secure methods. User must use Oauth or Key pair authentication for Production use case.
NEW QUESTION # 221
......
Most people now like to practice SPS-C01 study braindumps on computer or phone, but I believe there are nostalgic people like me who love paper books. The PDF version of our SPS-C01 actual exam supports printing. This PDF version also supports mobile phone scanning, so that you can make full use of fragmented time whenever and wherever possible. And the PDF version of our SPS-C01 learning guide can let you free from the constraints of the network, so that you can do exercises whenever you want.
Reliable SPS-C01 Exam Bootcamp: https://www.actual4cert.com/SPS-C01-real-questions.html
What's more, part of that Actual4Cert SPS-C01 dumps now are free: https://drive.google.com/open?id=1ePqRKxIIHwjZ-T6li69PT_o6Cjg_1ljF