2026 Latest TrainingDump Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1-Cs4rDpM_lNnvxwi8MsSgjw7E2px_dAo
The Databricks-Generative-AI-Engineer-Associate quiz torrent we provide is compiled by experts with profound experiences according to the latest development in the theory and the practice so they are of great value. Please firstly try out our product before you decide to buy our product. It is worthy for you to buy our Databricks-Generative-AI-Engineer-Associate exam preparation not only because it can help you pass the exam successfully but also because it saves your time and energy. If you buy our Databricks-Generative-AI-Engineer-Associate Test Prep you will pass the exam easily and successfully,and you will realize you dream to find an ideal job and earn a high income.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design Applications | 14% | - Define functional requirements - Design and architect applications - Select appropriate models |
| Topic 2: Assembling and Deploying Apps | 22% | - Build and deploy RAG pipelines - Package and deploy models - Use Vector Search |
| Topic 3: Data Preparation | 14% | - Prepare data for RAG applications - Manage data quality and chunking |
| Topic 4: Application Development | 30% | - Integrate Databricks tools (LangChain, etc.) - Develop LLM chains - Implement prompt engineering |
| Topic 5: Evaluation and Monitoring | 12% | - Monitor deployed applications - Evaluate model quality and performance |
| Topic 6: Governance | 8% | - Manage permissions and logging - Apply safety filters and guidelines |
>> New Databricks-Generative-AI-Engineer-Associate Exam Bootcamp <<
The experts in our company have been focusing on the Databricks-Generative-AI-Engineer-Associate examination for a long time and they never overlook any new knowledge. The content of our Databricks-Generative-AI-Engineer-Associate study materials has always been kept up to date. We will inform you by E-mail when we have a new version. With our great efforts, our Databricks-Generative-AI-Engineer-Associatepractice dumps have been narrowed down and targeted to the Databricks-Generative-AI-Engineer-Associate examination. We can ensure you a pass rate as high as 99%!
NEW QUESTION # 37
A Generative AI Engineer is creating an LLM-powered application that will need access to up-to-date news articles and stock prices.
The design requires the use of stock prices which are stored in Delta tables and finding the latest relevant news articles by searching the internet.
How should the Generative AI Engineer architect their LLM system?
Answer: D
Explanation:
To build an LLM-powered system that accesses up-to-date news articles and stock prices, the best approach is to create an agent that has access to specific tools (option D).
Agent with SQL and Web Search Capabilities:
By using an agent-based architecture, the LLM can interact with external tools. The agent can query Delta tables (for up-to-date stock prices) via SQL and perform web searches to retrieve the latest news articles. This modular approach ensures the system can access both structured (stock prices) and unstructured (news) data sources dynamically.
Why This Approach Works:
SQL Queries for Stock Prices: Delta tables store stock prices, which the agent can query directly for the latest data.
Web Search for News: For news articles, the agent can generate search queries and retrieve the most relevant and recent articles, then pass them to the LLM for processing.
Why Other Options Are Less Suitable:
A (Summarizing News for Stock Prices): This convoluted approach would not ensure accuracy when retrieving stock prices, which are already structured and stored in Delta tables.
B (Stock Price Volatility Queries): While this could retrieve relevant information, it doesn't address how to obtain the most up-to-date news articles.
C (Vector Store): Storing news articles and stock prices in a vector store might not capture the real-time nature of stock data and news updates, as it relies on pre-existing data rather than dynamic querying.
Thus, using an agent with access to both SQL for querying stock prices and web search for retrieving news articles is the best approach for ensuring up-to-date and accurate responses.
NEW QUESTION # 38
What is an effective method to preprocess prompts using custom code before sending them to an LLM?
Answer: C
Explanation:
The most effective way to preprocess prompts using custom code is to write a custom model, such as an MLflow PyFunc model. Here's a breakdown of why this is the correct approach:
MLflow PyFunc Models:
MLflow is a widely used platform for managing the machine learning lifecycle, including experimentation, reproducibility, and deployment. A PyFunc model is a generic Python function model that can implement custom logic, which includes preprocessing prompts.
Preprocessing Prompts:
Preprocessing could include various tasks like cleaning up the user input, formatting it according to specific rules, or augmenting it with additional context before passing it to the LLM. Writing this preprocessing as part of a PyFunc model allows the custom code to be managed, tested, and deployed easily.
Modular and Reusable:
By separating the preprocessing logic into a PyFunc model, the system becomes modular, making it easier to maintain and update without needing to modify the core LLM or retrain it.
Why Other Options Are Less Suitable:
A (Modify LLM's Internal Architecture): Directly modifying the LLM's architecture is highly impractical and can disrupt the model's performance. LLMs are typically treated as black-box models for tasks like prompt processing.
B (Avoid Custom Code): While it's true that LLMs haven't been explicitly trained with preprocessed prompts, preprocessing can still improve clarity and alignment with desired input formats without confusing the model.
C (Postprocessing Outputs): While postprocessing the output can be useful, it doesn't address the need for clean and well-formatted inputs, which directly affect the quality of the model's responses.
Thus, using an MLflow PyFunc model allows for flexible and controlled preprocessing of prompts in a scalable way, making it the most effective method.
NEW QUESTION # 39
A Generative AI Engineer I using the code below to test setting up a vector store: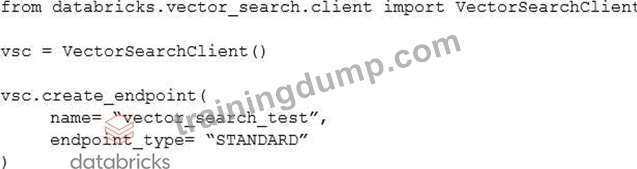
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: A
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 40
A Generative Al Engineer interfaces with an LLM with prompt/response behavior that has been trained on customer calls inquiring about product availability. The LLM is designed to output "In Stock" if the product is available or only the term "Out of Stock" if not.
Which prompt will work to allow the engineer to respond to call classification labels correctly?
Answer: B
Explanation:
* Problem Context: The Generative AI Engineer needs a prompt that will enable an LLM trained on customer call transcripts to classify and respond correctly regarding product availability. The desired response should clearly indicate whether a product is "In Stock" or "Out of Stock," and it should be formatted in a way that is structured and easy to parse programmatically, such as JSON.
* Explanation of Options:
* Option A: Respond with "In Stock" if the customer asks for a product. This prompt is too generic and does not specify how to handle the case when a product is not available, nor does it provide a structured output format.
* Option B: This option is correctly formatted and explicit. It instructs the LLM to respond based on the availability mentioned in the customer call transcript and to format the response in JSON.
This structure allows for easy integration into systems that may need to process this information automatically, such as customer service dashboards or databases.
* Option C: Respond with "Out of Stock" if the customer asks for a product. Like option A, this prompt is also insufficient as it only covers the scenario where a product is unavailable and does not provide a structured output.
* Option D: While this prompt correctly specifies how to respond based on product availability, it lacks the structured output format, making it less suitable for systems that require formatted data for further processing.
Given the requirements for clear, programmatically usable outputs,Option Bis the optimal choice because it provides precise instructions on how to respond and includes a JSON format example for structuring the output, which is ideal for automated systems or further data handling.
NEW QUESTION # 41
A Generative Al Engineer is developing a RAG application and would like to experiment with different embedding models to improve the application performance.
Which strategy for picking an embedding model should they choose?
Answer: C
Explanation:
The task involves improving a Retrieval-Augmented Generation (RAG) application's performance by experimenting with embedding models. The choice of embedding model impacts retrieval accuracy, which is critical for RAG systems. Let's evaluate the options based on Databricks Generative AI Engineer best practices.
Option A: Pick an embedding model trained on related domain knowledge
Embedding models trained on domain-specific data (e.g., industry-specific corpora) produce vectors that better capture the semantics of the application's context, improving retrieval relevance. For RAG, this is a key strategy to enhance performance.
Databricks Reference: "For optimal retrieval in RAG systems, select embedding models aligned with the domain of your data" ("Building LLM Applications with Databricks," 2023).
Option B: Pick the most recent and most performant open LLM released at the time LLMs are not embedding models; they generate text, not embeddings for retrieval. While recent LLMs may be performant for generation, this doesn't address the embedding step in RAG. This option misunderstands the component being selected.
Databricks Reference: Embedding models and LLMs are distinct in RAG workflows: "Embedding models convert text to vectors, while LLMs generate responses" ("Generative AI Cookbook").
Option C: Pick the embedding model ranked highest on the Massive Text Embedding Benchmark (MTEB) leaderboard hosted by HuggingFace The MTEB leaderboard ranks models across general tasks, but high overall performance doesn't guarantee suitability for a specific domain. A top-ranked model might excel in generic contexts but underperform on the engineer's unique data.
Databricks Reference: General performance is less critical than domain fit: "Benchmark rankings provide a starting point, but domain-specific evaluation is recommended" ("Databricks Generative AI Engineer Guide").
Option D: Pick an embedding model with multilingual support to support potential multilingual user questions Multilingual support is useful only if the application explicitly requires it. Without evidence of multilingual needs, this adds complexity without guaranteed performance gains for the current use case.
Databricks Reference: "Choose features like multilingual support based on application requirements" ("Building LLM-Powered Applications").
Conclusion: Option A is the best strategy because it prioritizes domain relevance, directly improving retrieval accuracy in a RAG system-aligning with Databricks' emphasis on tailoring models to specific use cases.
NEW QUESTION # 42
......
After your payment is successful, you will receive an e-mail from our system within 5-10 minutes, and then, you can use high-quality Databricks-Generative-AI-Engineer-Associate exam guide to learn immediately. Everyone knows that time is very important and hopes to learn efficiently to pass the Databricks-Generative-AI-Engineer-Associate exam. Once they discover Databricks-Generative-AI-Engineer-Associate practice materials, they will definitely want to seize the time to learn. So after payment, downloading into the exam database is the advantage of our products. The sooner you download and use Databricks-Generative-AI-Engineer-Associate guide torrent, the sooner you get the Databricks-Generative-AI-Engineer-Associate certificate.
Exam Databricks-Generative-AI-Engineer-Associate Vce Format: https://www.trainingdump.com/Databricks/Databricks-Generative-AI-Engineer-Associate-practice-exam-dumps.html
What's more, part of that TrainingDump Databricks-Generative-AI-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1-Cs4rDpM_lNnvxwi8MsSgjw7E2px_dAo