さらに、ShikenPASS CCDAKダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1e43IN8D9HV8E1CcL288dGjoZcDCC0Jz4
ご存知のように、当社ShikenPASSのCCDAK模擬試験には広大な市場があり、Confluentお客様から高く評価されています。 CCDAK練習教材に少額の料金を支払うだけで、99%の確率でCCDAK試験に合格し、良い生活を送ることができます。 あなたの将来の目標はこの成功した試験から始まると確信しています。 したがって、CCDAKトレーニング資料を選択することは賢明な選択です。 私たちの練習資料は、あなたの夢を達成するのにConfluent Certified Developer for Apache Kafka Certification Examination役立つ知識のプラットフォームを提供します。 CCDAK実践教材を選択して購入してください。
| Section | Objectives |
|---|---|
| Topic 1: Kafka Fundamentals | - Data flow in Kafka
|
| Topic 2: Kafka Ecosystem and Confluent Platform | - Schema Registry
|
| Topic 3: Kafka Streams and Processing | - Kafka Streams API
|
| Topic 4: Kafka Producers and Consumers | - Producer API
|
CCDAK試験はあなたのキャリアのマイルストーンで、競争が激しいこの時代で、これまで以上に重要になりました。あなたは一回で気楽にCCDAK試験に合格することを保証します。将来で新しいチャンスを作って、仕事が楽しげにやらせます。ShikenPASSの値段よりそれが創造する価値ははるかに大きいです。我々は弊社の商品とあなたの努力を通してあなたはCCDAK試験に合格することができると信じています。
質問 # 10
(You want to enrich the content of a topic by joining it with key records from a second topic.
The two topics have a different number of partitions.
Which two solutions can you use?
Select two.)
正解:A、B
解説:
The Apache Kafka Streams documentation defines a co-partitioning requirement for KStream-KTable and KStream-KStream joins. Both input topics must have the same number of partitions and the same key partitioning strategy.
One valid solution is to use a GlobalKTable (Option A). A GlobalKTable is fully replicated to every Kafka Streams instance, removing the co-partitioning requirement. This approach is recommended when the reference data is relatively small and changes infrequently.
Another valid solution is to repartition one topic so that both topics have the same number of partitions (Option B). Kafka Streams provides repartition topics specifically for this purpose, allowing proper KStream- KTable joins.
Option C does not resolve the partition mismatch, as increasing instances does not change partitioning. Option D is incorrect because Kafka Streams does not automatically repartition both topics for joins; repartitioning must be explicitly configured.
Therefore, the correct and officially supported solutions are using a GlobalKTable and explicitly repartitioning one topic.
質問 # 11
Refer to the producer code below. It features a 'Callback' class with a method called 'onCompletion()'. When will the 'onCompletion()' method be Invoked?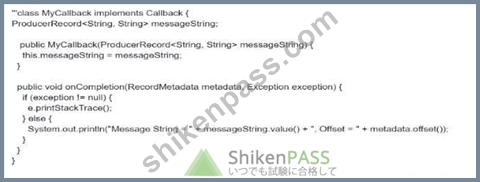
producer.send(record, new MyCallback(record));
正解:B
質問 # 12
A stream processing application is tracking user activity in online shopping carts.
You want to identify periods of user inactivity.
Which type of Kafka Streams window should you use?
正解:A
解説:
Session windowsare ideal for trackingperiods of activity separated by inactivity, such as user sessions.
FromKafka Streams Documentation > Windowing:
"A session window captures streams of events that areintermittentand separated by agap of inactivity."
* Tumbling/Hopping/Sliding windows are fixed in size
* Session windows are dynamic and close after inactivity timeout
This makes them perfect for identifyinggaps in user interaction.
Reference:Kafka Streams Developer Guide > Session Windows
質問 # 13
You are creating a Kafka Streams application to process retail data.
Match the input data streams with the appropriate Kafka Streams object.
正解:
解説:
Explanation:
Table # Product, Customers
Stream # Orders_Placed, Shipment_Of_Orders
Tables represent slowly changing, reference data - e.g., customer profiles, product info.
Streams represent real-time event data - e.g., orders placed, shipments processed.
From Kafka Streams Documentation:
"Use KTable for reference datasets, and KStream for event-based processing such as orders or logs." Reference: Kafka Streams API Concepts
質問 # 14
(You are implementing a Kafka Streams application to process financial transactions.
Each transaction must be processed exactly once to ensure accuracy.
The application reads from an input topic, performs computations, and writes results to an output topic.
During testing, you notice duplicate entries in the output topic, which violates the exactly-once processing requirement.
You need to ensure exactly-once semantics (EOS) for this Kafka Streams application.
Which step should you take?)
正解:A
解説:
According to the official Apache Kafka documentation for Kafka Streams, exactly-once semantics (EOS) are controlled using the processing.guarantee configuration. To ensure that each input record is processed once and only once, and that the results are written atomically to the output topic, Kafka Streams provides built-in EOS support.
The correct and recommended configuration is processing.guarantee=exactly_once_v2, which is the default EOS implementation starting from Kafka 3.0. This mode uses Kafka's transactional APIs to atomically commit consumer offsets and produce output records within a single transaction. As documented, this prevents duplicates even in the presence of failures, retries, or application restarts.
Option A is incorrect because log compaction does not guarantee exactly-once processing; it only retains the latest record per key. Option B is insufficient because enable.idempotence alone does not handle consumer offset commits or state store consistency in Kafka Streams. Option C is invalid because no such configuration exists in Kafka Streams.
Therefore, setting processing.guarantee=exactly_once_v2 is the only fully correct and officially supported solution for achieving EOS in Kafka Streams applications.
質問 # 15
......
献身と熱意を持ってCCDAKガイド資料を段階的に学習する場合、必死に試験に合格することを保証します。学習資料の権威あるプロバイダーとして、潜在顧客からより多くの注目を集めるために、常に同等のテストと比較してCCDAK模擬テストの高い合格率を追求しています。将来的には、CCDAK試験トレントは、高い合格率でより魅力的で素晴らしいものになると信じています。
CCDAK技術問題: https://www.shikenpass.com/CCDAK-shiken.html
ちなみに、ShikenPASS CCDAKの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1e43IN8D9HV8E1CcL288dGjoZcDCC0Jz4