P.S. MogiExamがGoogle Driveで共有している無料かつ新しいDatabricks-Certified-Professional-Data-Engineerダンプ:https://drive.google.com/open?id=1dGEzPUlJHcVkD9viGk-4s0Mru5cduX1E
MogiExamがDatabricksのDatabricks-Certified-Professional-Data-Engineerのサンプルの問題のダウンロードを提供して、あなはリスクフリーの購入のプロセスを体験することができます。これは試用の練習問題で、あなたにインタフェースの友好、問題の質と購入する前の価値を見せます。弊社はMogiExamのDatabricksのDatabricks-Certified-Professional-Data-Engineerのサンプルは製品の性質を確かめるに足りて、あなたに満足させると信じております。あなたの権利と利益を保障するために、MogiExamは一回で合格しなかったら、全額で返金することを約束します。弊社の目的はあなたが試験に合格することに助けを差し上げるだけでなく、あなたが本物のIT認証の専門家になることを願っています。あなたが仕事を求める競争力を高めて、自分の技術レベルに合わせている技術職を取って、気楽にホワイトカラー労働者になって高い給料を取ることをお祈りします。
| Section | Weight | Objectives |
|---|---|---|
| Cost & Performance Optimisation | 13% | - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) - Query optimization and caching |
| Debugging and Deploying | 10% | - Troubleshooting pipelines and errors - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices |
| Monitoring and Alerting | 10% | - Performance and health monitoring - Setting up alerts and notifications - Pipeline observability and logging |
| Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation - Integration with Databricks APIs and tools - Batch and incremental processing logic |
| Data Governance | 7% | - Policy enforcement - Data lineage and metadata tracking - Unity Catalog management |
| Ensuring Data Security and Compliance | 10% | - Access control and permissions - Data encryption and masking - Compliance standards implementation |
| Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization - Handling missing or inconsistent data - Data validation and quality checks |
| Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion - Connecting to diverse data sources - Schema inference and evolution |
| Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Data Modelling | 6% | - Delta Lake table design - Medallion Architecture implementation - Schema design and management |
>> Databricks-Certified-Professional-Data-Engineer日本語版受験参考書 <<
DatabricksのDatabricks-Certified-Professional-Data-Engineer試験に趣味があると、躊躇わなく、我々MogiExamで問題集のデーモをダウンロードして試すことができます。デーモ版によって、このDatabricks-Certified-Professional-Data-Engineer問題集はあなたに適合するかと判断します。適合すると、あなたは安心で購買できます。弊社MogiExamのDatabricks-Certified-Professional-Data-Engineer問題集は必ずあなたの成功へ道の秘訣です。
質問 # 123
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFramedf. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFramedfhas the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: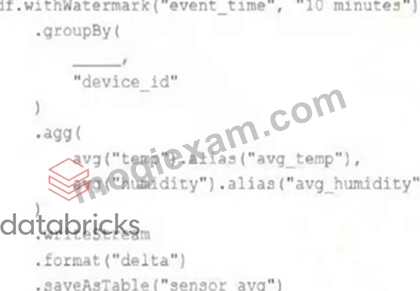
Choose the response that correctly fills in the blank within the code block to complete this task.
正解:A
解説:
Explanation
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five-minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window.
The alias function is used to rename the struct column as "time". Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under
"WINDOW" section.
質問 # 124
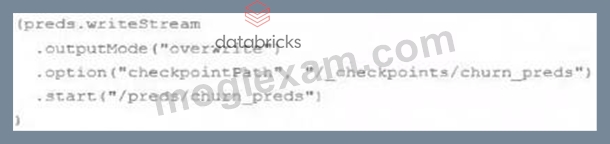
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame namedpredswith the schema "customer_id LONG, predictions DOUBLE, date DATE".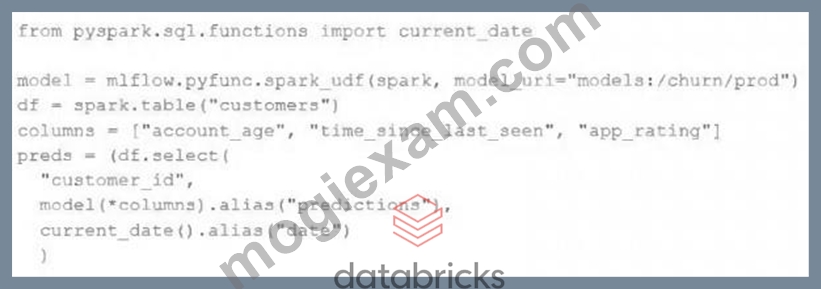
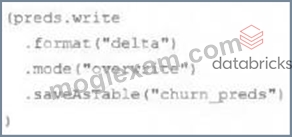
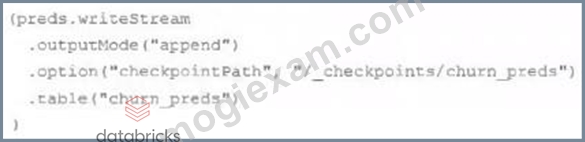
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
正解:E
解説:
Explanation
This is the correct answer because it will save the predictions to a Delta Lake table with the ability to compare all predictions across time. The code uses the mergeInto method to perform an upsert operation, which means it will insert new records or update existing records based on the customer_id and date columns. This way, the table will always contain the latest predictions for each customer and date, and also keep the history of previous predictions. The code also uses a new job cluster to run the job, which will minimize the compute costs as it will be created and terminated for each run. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Upsert into a table using merge" section.
質問 # 125
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.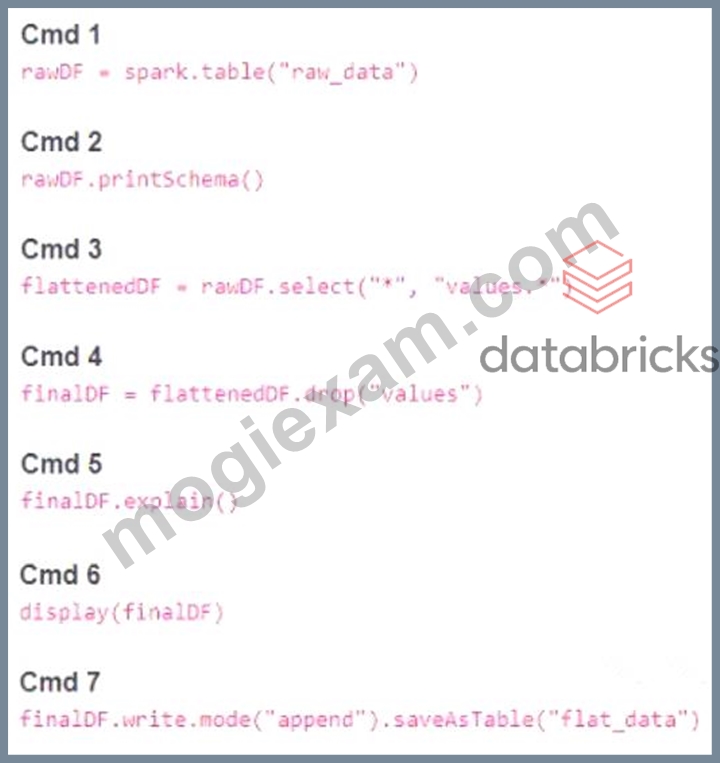
Which command should be removed from the notebook before scheduling it as a job?
正解:B
解説:
Cmd 6 is the command that should be removed from the notebook before scheduling it as a job. This command is selecting all the columns from the finalDF dataframe and displaying them in the notebook. This is not necessary for the job, as the finalDF dataframe is already written to a table in Cmd 7. Displaying the dataframe in the notebook will only consume resources and time, and it will not affect the output of the job.
Therefore, Cmd 6 is redundant and should be removed.
The other commands are essential for the job, as they perform the following tasks:
* Cmd 1: Reads the raw_data table into a Spark dataframe called rawDF.
* Cmd 2: Prints the schema of the rawDF dataframe, which is useful for debugging and understanding the data structure.
* Cmd 3: Selects all the columns from the rawDF dataframe, as well as the nested columns from the values struct column, and creates a new dataframe called flattenedDF.
* Cmd 4: Drops the values column from the flattenedDF dataframe, as it is no longer needed after flattening, and creates a new dataframe called finalDF.
* Cmd 5: Explains the physical plan of the finalDF dataframe, which is useful for optimizing and tuning the performance of the job.
* Cmd 7: Writes the finalDF dataframe to a table called flat_data, using the append mode to add new data to the existing table.
質問 # 126
You are trying to create an object by joining two tables that and it is accessible to data scientist's team, so it does not get dropped if the cluster restarts or if the notebook is detached. What type of object are you trying to create?
正解:D
解説:
Explanation
Answer is View, A view can be used to join multiple tables but also persist into meta stores so others can accesses it
質問 # 127
A data engineer has configured their Databricks Asset Bundle with multiple targets in databricks.yml and deployed it to the production workspace. Now, to validate the deployment, they need to invoke a job named my_project_job specifically within the prod target context. Assuming the job is already deployed, they need to trigger its execution while ensuring the target-specific configuration is respected.
Which command will trigger the job execution?
正解:B
解説:
Databricks Asset Bundles (DABs) enable declarative configuration and deployment of Databricks resources such as jobs, pipelines, and dashboards across multiple environments.
Once deployed, jobs can be executed in a specific target context using the databricks bundle run command, which ensures all environment-specific configurations from the bundle definition (such as parameters, cluster settings, and workspace URLs) are respected.
The -t flag specifies the target environment (e.g., dev, staging, or prod). This ensures that the execution runs with the correct configuration defined under that target in databricks.yml.
Other options (A, B, and C) are invalid because they reference deprecated or incorrect command syntax that doesn't integrate with bundle targets. Therefore, D is the correct and verified answer.
質問 # 128
......
クライアントがトレントのDatabricks-Certified-Professional-Data-Engineer質問を購入する前に、ダウンロードして自由に試してみることができます。製品のページはデモを提供します。目的は、購入前にクライアントにタイトルの一部を知らせ、Databricks-Certified-Professional-Data-Engineerガイドトレントがどのようなものであるかを知らせることです。このページでは、Databricks-Certified-Professional-Data-Engineerガイドトレントの質問と回答の量を紹介しています。無料デモを試してみると、Databricks-Certified-Professional-Data-Engineer試験トレントが購入する価値があるかどうかを判断できます。MogiExamしたがって、お金を無駄にする心配はありません。また、Databricks-Certified-Professional-Data-Engineer試験の急流は役に立たず、価値を高めません。
Databricks-Certified-Professional-Data-Engineer問題集: https://www.mogiexam.com/Databricks-Certified-Professional-Data-Engineer-exam.html
2026年MogiExamの最新Databricks-Certified-Professional-Data-Engineer PDFダンプおよびDatabricks-Certified-Professional-Data-Engineer試験エンジンの無料共有:https://drive.google.com/open?id=1dGEzPUlJHcVkD9viGk-4s0Mru5cduX1E