完璧-一番優秀なDatabricks-Certified-Data-Engineer-Professional最新受験攻略試験-試験の準備方法Databricks-Certified-Data-Engineer-Professional必殺問題集

BONUS!!! Fast2test Databricks-Certified-Data-Engineer-Professionalダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1bptuUuNr4DoTFp9Q9AuNpX7xDTVYNNhR
DatabricksのDatabricks-Certified-Data-Engineer-Professional認定試験がIT業界には極めて重要な地位があるがよく分かりましょう。試験に合格するのは簡単ではないもよくわかりましょう。“簡単に合格できる方法がありますか?”答えはもちろんですよ。Fast2testはこの問題を着々解決できますよ。IT専門家がDatabricksのDatabricks-Certified-Data-Engineer-Professional認定試験に関する特別な問題集を開発しています。それをもって、試験は問題になりませんよ。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Databricks Lakehouse Platform | 24% | - Unity Catalog
- Lakehouse Architecture
- Delta Lake
- Data Management
|
| Data Processing | 28% | - ETL Pipelines
- Data Transformation
- Spark SQL
- Structured Streaming
|
| Data Quality and Governance | 12% | - Data Lineage
- Data Quality
- Governance
|
| Data Modeling and Storage | 20% | - Storage Optimization
- Data Modeling
- File Formats
|
| Monitoring and Troubleshooting | 16% | - Performance Optimization
- Monitoring
- Troubleshooting
|
>> Databricks-Certified-Data-Engineer-Professional最新受験攻略 <<
Databricks-Certified-Data-Engineer-Professional必殺問題集 & Databricks-Certified-Data-Engineer-Professional日本語pdf問題
我々のソフトを利用してDatabricksのDatabricks-Certified-Data-Engineer-Professional試験失敗したら全額で返金するという承諾は不自信ではなく、我々のお客様への誠な態度を表わしたいです。我々はあなたに試験に安心させます。それだけでなく、あなたに我々のアフターサービスに安心させます。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q210-Q215):
質問 # 210
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is named store_saies_summary and the schema is as follows:

The table daily_store_sales contains all the information needed to update store_sales_summary.
The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
If daily_store_sales is implemented as a Type 1 table and the total_sales column might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in the store_sales_summary table?
- A. Implement the appropriate aggregate logic as a Structured Streaming read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- B. Use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update.
- C. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and overwrite the store_sales_summary table with each Update.
- D. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- E. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and append new rows nightly to the store_sales_summary table.
正解:C
質問 # 211
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.
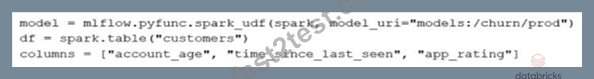
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
- A. df.map(lambda x:model(x[columns])).select("customer_id, predictions")
- B. model.predict(df, columns)
- C. df.select("customer_id", model(*columns).alias("predictions"))
- D. df.select("customer_id", pandas_udf(model, columns).alias("predictions"))
- E. df.apply(model, columns).select("customer_id, predictions")
正解:C
解説:
This code block applies the Spark UDF created from the MLflow model to the DataFrame df by selecting the existing customer_id column and the new column produced by the model, which is aliased to predictions. The model(*columns) part is where the UDF is applied to the columns specified in the columns list, and alias("predictions") is used to name the output column of the model's predictions. This will result in a DataFrame with the desired schema: "customer_id LONG, predictions DOUBLE".
質問 # 212
How are the operational aspects of Lakeflow Declarative Pipelines different from Spark Structured Streaming?
- A. Structured Streaming can process continuous data streams, while Lakeflow Declarative Pipelines cannot.
- B. Lakeflow Declarative Pipelines automatically handle schema evolution, while Structured Streaming always requires manual schema management.
- C. Lakeflow Declarative Pipelines can write to Delta Lake format, while Structured Streaming cannot.
- D. Lakeflow Declarative Pipelines manage the orchestration of multi-stage pipelines automatically, while Structured Streaming requires external orchestration for complex dependencies.
正解:D
解説:
Databricks documentation explains that Lakeflow Declarative Pipelines build upon Structured Streaming but add higher-level orchestration and automation capabilities. They automatically manage dependencies, materialization, and recovery across multi-stage data flows without requiring external orchestration tools such as Airflow or Azure Data Factory. In contrast, Structured Streaming operates at a lower level, where developers must manually handle orchestration, retries, and dependencies between streaming jobs. Both support Delta Lake outputs and schema evolution; however, Lakeflow Declarative Pipelines simplify management by declaratively defining transformations and data quality expectations. Hence, the correct distinction is A -- automated orchestration and management in Lakeflow Declarative Pipelines.
質問 # 213
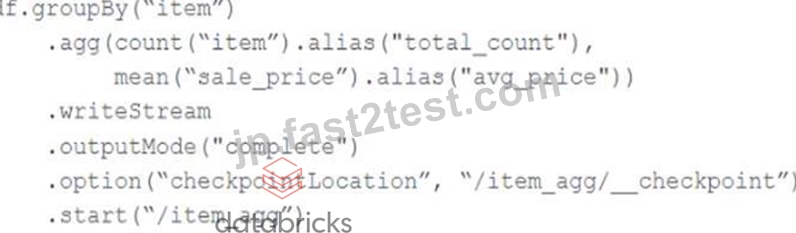
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
Proposed query:
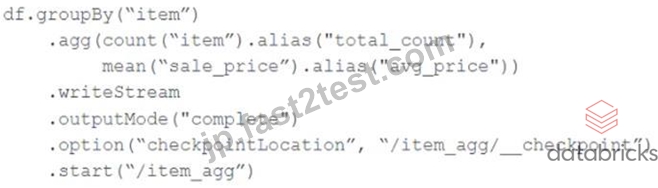
Proposed query:
.start("/item_agg")
Which step must also be completed to put the proposed query into production?
- A. Remove .option (mergeSchema', true') from the streaming write
- B. Run REFRESH TABLE delta, /item_agg'
- C. Specify a new checkpointlocation
- D. Increase the shuffle partitions to account for additional aggregates
- E. Register the data in the "/item_agg" directory to the Hive metastore
正解:C
解説:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
質問 # 214
A data engineer is implementing a job to download multiple PDF files from a third-party provided REST API endpoint by specifying different report types. The REST API is time-consuming and encounters intermittent errors, so the engineer wants to track each download activity to know when it fails and to retry partially, while providing scalable throughput. The engineer needs to download ten report types, and the list can be changed over time. How should the data engineer achieve this?
- A. Define a list variable within a Notebook to loop through the report types to download them, and print the download results. Execute it as a Notebook tasks.
- B. Use a foreach task with a list of report types as its inputs.
- C. Use a Delta Lake table to track each report download status as 10 rows, and use it as a source table to execute the download function as a Pandas UDF.
- D. Define ten Notebook tasks to clearly track which report download failed.
正解:B
解説:
A foreach task allows the job to dynamically iterate over a configurable list of report types, execute downloads in parallel, and track the success or failure of each item independently. This enables scalable throughput, partial retries for failed downloads, and easy updates when the list of report types changes, without hardcoding tasks or introducing unnecessary complexity.
質問 # 215
......
多くの大学生、多くの労働者、さらに多くの主婦など、Databricks-Certified-Data-Engineer-Professional試験に合格するために最善を尽くす人が増えています。 Databricks-Certified-Data-Engineer-Professional試験に合格したいこれらの人々は、試験を自分自身を向上させ、大きな進歩を遂げる唯一の機会と考えています。そのため、彼らはDatabricks-Certified-Data-Engineer-Professional試験の準備に全力を尽くすことを望んでいますが、多くの人が重要なDatabricks-Certified-Data-Engineer-Professional試験の準備に十分な時間がないことは明らかです。 Databricks-Certified-Data-Engineer-Professional試験の質問は、最小限の時間と労力でDatabricks-Certified-Data-Engineer-Professional試験に合格するのに役立ちます。
Databricks-Certified-Data-Engineer-Professional必殺問題集: https://jp.fast2test.com/Databricks-Certified-Data-Engineer-Professional-premium-file.html
- 有難いDatabricks-Certified-Data-Engineer-Professional|信頼的なDatabricks-Certified-Data-Engineer-Professional最新受験攻略試験|試験の準備方法Databricks Certified Data Engineer Professional Exam必殺問題集 💾 サイト☀ www.shikenpass.com ️☀️で➡ Databricks-Certified-Data-Engineer-Professional ️⬅️問題集をダウンロードDatabricks-Certified-Data-Engineer-Professional参考資料
- Databricks-Certified-Data-Engineer-Professional試験過去問 🥄 Databricks-Certified-Data-Engineer-Professional試験問題解説集 🔁 Databricks-Certified-Data-Engineer-Professional専門知識 🍿 最新➽ Databricks-Certified-Data-Engineer-Professional 🢪問題集ファイルは「 www.goshiken.com 」にて検索Databricks-Certified-Data-Engineer-Professional学習資料
- 素晴らしいDatabricks-Certified-Data-Engineer-Professional最新受験攻略一回合格-効率的なDatabricks-Certified-Data-Engineer-Professional必殺問題集 🍢 今すぐ▛ www.it-passports.com ▟で{ Databricks-Certified-Data-Engineer-Professional }を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional受験内容
- Databricks-Certified-Data-Engineer-Professional日本語版復習資料 💹 Databricks-Certified-Data-Engineer-Professional日本語試験対策 🦍 Databricks-Certified-Data-Engineer-Professional試験内容 🎐 最新➡ Databricks-Certified-Data-Engineer-Professional ️⬅️問題集ファイルは➡ www.goshiken.com ️⬅️にて検索Databricks-Certified-Data-Engineer-Professional模擬問題集
- 試験の準備方法-素敵なDatabricks-Certified-Data-Engineer-Professional最新受験攻略試験-効率的なDatabricks-Certified-Data-Engineer-Professional必殺問題集 🦽 「 www.jpshiken.com 」の無料ダウンロード▶ Databricks-Certified-Data-Engineer-Professional ◀ページが開きますDatabricks-Certified-Data-Engineer-Professional関連合格問題
- Databricks-Certified-Data-Engineer-Professional関連日本語内容 🦽 Databricks-Certified-Data-Engineer-Professional関連日本語内容 🐍 Databricks-Certified-Data-Engineer-Professional日本語対策 😈 今すぐ➡ www.goshiken.com ️⬅️で➥ Databricks-Certified-Data-Engineer-Professional 🡄を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional受験料
- Databricks-Certified-Data-Engineer-Professional復習対策書 🅾 Databricks-Certified-Data-Engineer-Professional日本語対策 🎺 Databricks-Certified-Data-Engineer-Professional問題集 🍽 ⏩ www.japancert.com ⏪で⏩ Databricks-Certified-Data-Engineer-Professional ⏪を検索して、無料で簡単にダウンロードできますDatabricks-Certified-Data-Engineer-Professional試験過去問
- 有難いDatabricks-Certified-Data-Engineer-Professional|信頼的なDatabricks-Certified-Data-Engineer-Professional最新受験攻略試験|試験の準備方法Databricks Certified Data Engineer Professional Exam必殺問題集 🥣 ⏩ www.goshiken.com ⏪にて限定無料の( Databricks-Certified-Data-Engineer-Professional )問題集をダウンロードせよDatabricks-Certified-Data-Engineer-Professional日本語講座
- 試験の準備方法-素敵なDatabricks-Certified-Data-Engineer-Professional最新受験攻略試験-効率的なDatabricks-Certified-Data-Engineer-Professional必殺問題集 💺 ➠ www.passtest.jp 🠰は、➽ Databricks-Certified-Data-Engineer-Professional 🢪を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Data-Engineer-Professional無料問題
- Databricks-Certified-Data-Engineer-Professional模擬問題集 🦈 Databricks-Certified-Data-Engineer-Professional日本語試験対策 🍎 Databricks-Certified-Data-Engineer-Professional専門知識 🖍 ➠ www.goshiken.com 🠰を入力して▛ Databricks-Certified-Data-Engineer-Professional ▟を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional試験過去問
- 完璧-一番優秀なDatabricks-Certified-Data-Engineer-Professional最新受験攻略試験-試験の準備方法Databricks-Certified-Data-Engineer-Professional必殺問題集 🍧 “ www.jpshiken.com ”で使える無料オンライン版( Databricks-Certified-Data-Engineer-Professional ) の試験問題Databricks-Certified-Data-Engineer-Professional日本語試験対策
- www.stes.tyc.edu.tw, vrcmods.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, connect.garmin.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, buyerseller.xyz, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! Fast2test Databricks-Certified-Data-Engineer-Professionalダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1bptuUuNr4DoTFp9Q9AuNpX7xDTVYNNhR