BONUS!!! 免費下載Fast2test Databricks-Certified-Professional-Data-Engineer考試題庫的完整版:https://drive.google.com/open?id=1WVv-qho3zDoHgLwqBPxSbd8WMoU1ja6I
Fast2test就是一個能成就很多IT專業人士夢想的網站。如果你有IT夢,就趕緊來Fast2test吧,它有超級好培訓資料即Fast2test Databricks的Databricks-Certified-Professional-Data-Engineer考試培訓資料, 這個培訓資料是每個IT人士都非常渴望的,因為它會讓你通過考試獲得認證,從此以後在職業道路上步步高升。
| Section | Weight | Objectives |
|---|---|---|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Delta Lake | 20-25% | - Delta Lake operations
|
| Data Ingestion | 15-20% | - Batch ingestion methods
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
|
>> Databricks-Certified-Professional-Data-Engineer套裝 <<
言與行的距離到底有多遠?關鍵看人心,倘使心神明淨,意志堅強,則近在咫尺,垂手可及 。我想你應該就是這樣的人吧。既然選擇了要通過Databricks的Databricks-Certified-Professional-Data-Engineer認證考試,當然就得必須通過,Fast2test Databricks的Databricks-Certified-Professional-Data-Engineer考試培訓資料是幫助通過考試的最佳選擇,也是表現你意志堅強的一種方式,Fast2test網站提供的培訓資料在互聯網上那是獨一無二的品質好,如果你想要通過Databricks的Databricks-Certified-Professional-Data-Engineer考試認證,就購買Fast2test Databricks的Databricks-Certified-Professional-Data-Engineer考試培訓資料。
問題 #13
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by thedatevariable: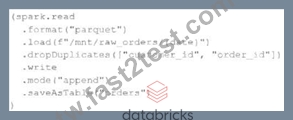
Assume that the fieldscustomer_idandorder_idserve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
答案:C
解題說明:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "DROP DUPLICATES" section.
問題 #14
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic: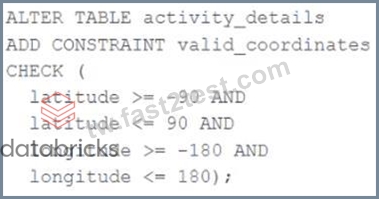
A batch job is attempting to insert new records to the table, including a record where latitude = 45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
答案:B
解題說明:
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the constraint, and the target table will not be updated. References:
* Constraints : https://docs.delta.io/latest/delta-constraints.html
* ACID Transactions : https://docs.delta.io/latest/delta-intro.html#acid-transactions
問題 #15
A table named user_ltv is being used to create a view that will be used by data analysis on various teams.
Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema: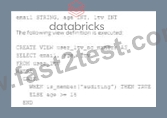
An analyze who is not a member of the auditing group executing the following query: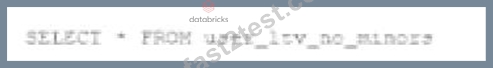
Which result will be returned by this query?
答案:C
解題說明:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
問題 #16
Which approach demonstrates a modular and testable way to use DataFrame.transform for ETL code in PySpark?
答案:D
解題說明:
Comprehensive and Detailed
Databricks and Apache Spark recommend building modular and reusable ETL transformations by leveraging the DataFrame.transform() API. This method allows you to chain multiple transformation functions in a clean and testable way.
Option A: Encapsulating the logic in a class (Pipeline) works, but it reduces modularity and flexibility. It does not show the true intended use of DataFrame.transform() which is chaining functional transformations.
Option B: This is the correct approach. It defines small, reusable functions (upper_value, filter_positive) that each take a DataFrame and return a transformed DataFrame. By chaining them with df.transform(func), you can compose ETL pipelines in a clear and declarative manner. This enables unit testing of individual functions and makes the ETL pipeline modular, testable, and production-ready.
Option C: This shows a single transformation wrapped in a function and tested, but it lacks pipeline composition - it is not demonstrating modular chaining across multiple transformations.
Option D: This simply defines a transformation function with hardcoded logic. It does not leverage DataFrame.transform() nor demonstrate modularity through composition.
Therefore, Option B is the best demonstration of how to use DataFrame.transform() in PySpark ETL pipelines.
Databricks documentation explicitly highlights that DataFrame.transform() allows developers to "chain together reusable functions in a readable and modular way, improving testability and maintainability of ETL code." This makes B the correct and officially supported pattern.
問題 #17
Which of the following is true of Delta Lake and the Lakehouse?
答案:E
解題說明:
https://docs.delta.io/2.0.0/table-properties.html
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters 1 . Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer 1 . By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan 1 . This can significantly improve the query performance and reduce the I/O cost.
The other options are false because:
* Parquet compresses data column by column, not row by row 2 . This allows for better compression ratios, especially for repeated or similar values within a column 2 .
* Views in the Lakehouse do not maintain a valid cache of the most recent versions of source tables at all times 3 . Views are logical constructs that are defined by a SQL query on one or more base tables 3
. Views are not materialized by default, which means they do not store any data, but only the query definition 3 . Therefore, views always reflect the latest state of the source tables when queried 3 .
However, views can be cached manually using the CACHE TABLE or CREATE TABLE AS SELECT commands.
* Primary and foreign key constraints can not be leveraged to ensure duplicate values are never entered into a dimension table. Delta Lake does not support enforcing primary and foreign key constraints on tables. Constraints are logical rules that define the integrity and validity of the data in a table. Delta Lake relies on the application logic or the user to ensure the data quality and consistency.
* Z-order can be applied to any values stored in Delta Lake tables, not only numeric values. Z-order is a technique to optimize the layout of the data files by sorting them on one or more columns. Z-order can improve the query performance by clustering related values together and enabling more efficient data skipping. Z-order can be applied to any column that has a defined ordering, such as numeric, string, date, or boolean values.
References: Data Skipping , Parquet Format , Views , [Caching], [Constraints] , [Z-Ordering]
問題 #18
......
你是一名IT人員嗎?你報名參加當今最流行的IT認證考試了嗎?如果你是,我將告訴你一個好消息,你很幸運,我們Fast2test Databricks的Databricks-Certified-Professional-Data-Engineer考試認證培訓資料可以幫助你100%通過考試,這絕對是個真實的消息。如果你想在IT行業更上一層樓,選擇我們Fast2test那就更對了,我們的培訓資料可以幫助你通過所有有關IT認證的,而且價格很便宜,我們賣的是適合,不要不相信,看到了你就知道。
最新Databricks-Certified-Professional-Data-Engineer考題: https://tw.fast2test.com/Databricks-Certified-Professional-Data-Engineer-premium-file.html
P.S. Fast2test在Google Drive上分享了免費的、最新的Databricks-Certified-Professional-Data-Engineer考試題庫:https://drive.google.com/open?id=1WVv-qho3zDoHgLwqBPxSbd8WMoU1ja6I