DOWNLOAD the newest DumpsTests ACD-301 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1_Yr1dIg5_tvOJ6AIGyBa-fC6pMaJ8PdH
We have free demo of our ACD-301 exam questions offering the latest catalogue and brief contents for your information on the website, if you do not have thorough understanding of our ACD-301 study materials. Many exam candidates build long-term relation with our company on the basis of our high quality ACD-301 Guide engine. And our ACD-301 training braindumps have became their best assistant on the way to pass the exam.
| Section | Weight | Objectives |
|---|---|---|
| Data Management | 25% | - Leverage Data Fabric, data types, and migration strategies - Troubleshoot complex data and database performance issues - Design secure and efficient data models |
| Platform & Solution Architecture | 15% | - Understand enterprise platform architecture - Manage deployments and environment configurations - Make architecture decisions for maintainability and scalability |
| Scalability and Performance Design | 20% | - Plan and execute load testing and monitoring - Design and build high-performance components - Troubleshoot application-level performance bottlenecks |
| Application Design and Development | 25% | - Apply best practices for multi-application development - Evaluate how Appian meets user requirements - Design applications with reusability and consistency |
| Extending Appian & Integrations | 15% | - Troubleshoot integration and API errors - Implement authentication and secure integrations - Design advanced APIs and connected systems |
>> ACD-301 Latest Test Cost <<
Our ACD-301 dumps pdf vce is absolutely the right and valid study material for candidates who desired to pass the ACD-301 actual test. Now, please go and free download our ACD-301 practice demo first. The questions & answers of ACD-301 free demo are parts of the complete exam dumps, which can give you some reference to assess the valuable of the ACD-301 Training Material. In addition, there is one year time for the access of the updated ACD-301 practice dumps after purcahse. You will get ACD-301 latest study pdf all the time for preparation.
NEW QUESTION # 46
For each requirement, match the most appropriate approach to creating or utilizing plug-ins Each approach will be used once.
Note: To change your responses, you may deselect your response by clicking the blank space at the top of the selection list.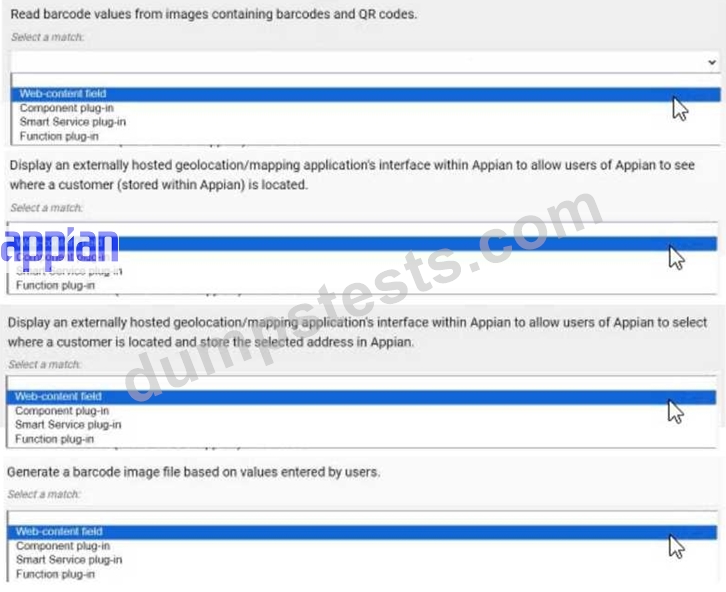
Answer:
Explanation: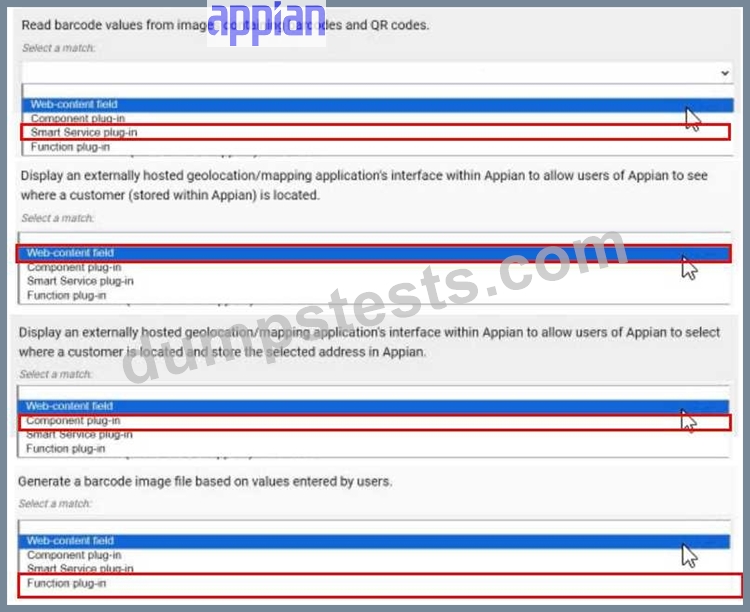
NEW QUESTION # 47
You are developing a case management application to manage support cases for a large set of sites. One of the tabs in this application s site Is a record grid of cases, along with Information about the site corresponding to that case. Users must be able to filter cases by priority level and status.
You decide to create a view as the source of your entity-backed record, which joins the separate case/site tables (as depicted in the following Image).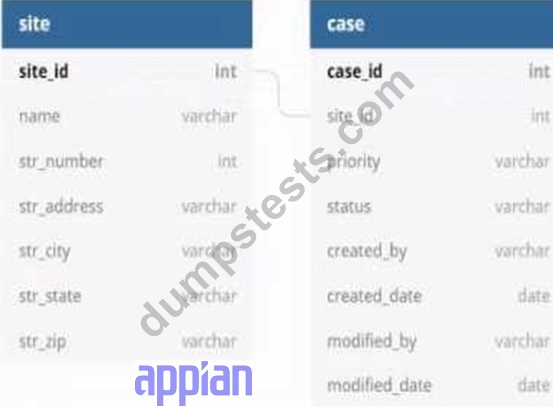
Which three column should be indexed?
Answer: B,C,F
Explanation:
Indexing columns can improve the performance of queries that use those columns in filters, joins, or order by clauses. In this case, the columns that should be indexed are site_id, status, and priority, because they are used for filtering or joining the tables. Site_id is used to join the case and site tables, so indexing it will speed up the join operation. Status and priority are used to filter the cases by the user's input, so indexing them will reduce the number of rows that need to be scanned. Name, modified_date, and case_id do not need to be indexed, because they are not used for filtering or joining. Name and modified_date are only used for displaying information in the record grid, and case_id is only used as a unique identifier for each record. Verified Appian Records Tutorial,Appian Best Practices As an Appian Lead Developer, optimizing a database view for an entity-backed record grid requires indexing columns frequently used in queries, particularly for filtering and joining. The scenario involves a record grid displaying cases with site information, filtered by "priority level" and "status," and joined via the site_id foreign key. The image shows two tables (site and case) with a relationship via site_id. Let's evaluate each column based on Appian's performance best practices and query patterns:
A . site_id:This is a primary key in the site table and a foreign key in the case table, used for joining the tables in the view. Indexing site_id in the case table (and ensuring it's indexed in site as a PK) optimizes JOIN operations, reducing query execution time for the record grid. Appian's documentation recommends indexing foreign keys in large datasets to improve query performance, especially for entity-backed records. This is critical for the join and must be included.
B . status:Users filter cases by "status" (a varchar column in the case table). Indexing status speeds up filtering queries (e.g., WHERE status = 'Open') in the record grid, particularly with large datasets. Appian emphasizes indexing columns used in WHERE clauses or filters to enhance performance, making this a key column for optimization. Since status is a common filter, it's essential.
C . name:This is a varchar column in the site table, likely used for display (e.g., site name in the grid). However, the scenario doesn't mention filtering or sorting by name, and it's not part of the join or required filters. Indexing name could improve searches if used, but it's not a priority given the focus on priority and status filters. Appian advises indexing only frequently queried or filtered columns to avoid unnecessary overhead, so this isn't necessary here.
D . modified_date:This is a date column in the case table, tracking when cases were last updated. While useful for sorting or historical queries, the scenario doesn't specify filtering or sorting by modified_date in the record grid. Indexing it could help if used, but it's not critical for the current requirements. Appian's performance guidelines prioritize indexing columns in active filters, making this lower priority than site_id, status, and priority.
E . priority:Users filter cases by "priority level" (a varchar column in the case table). Indexing priority optimizes filtering queries (e.g., WHERE priority = 'High') in the record grid, similar to status. Appian's documentation highlights indexing columns used in WHERE clauses for entity-backed records, especially with large datasets. Since priority is a specified filter, it's essential to include.
F . case_id:This is the primary key in the case table, already indexed by default (as PKs are automatically indexed in most databases). Indexing it again is redundant and unnecessary, as Appian's Data Store configuration relies on PKs for unique identification but doesn't require additional indexing for performance in this context. The focus is on join and filter columns, not the PK itself.
Conclusion: The three columns to index are A (site_id), B (status), and E (priority). These optimize the JOIN (site_id) and filter performance (status, priority) for the record grid, aligning with Appian's recommendations for entity-backed records and large datasets. Indexing these columns ensures efficient querying for user filters, critical for the application's performance.
Appian Documentation: "Performance Best Practices for Data Stores" (Indexing Strategies).
Appian Lead Developer Certification: Data Management Module (Optimizing Entity-Backed Records).
Appian Best Practices: "Working with Large Data Volumes" (Indexing for Query Performance).
NEW QUESTION # 48
What are two advantages of having High Availability (HA) for Appian Cloud applications?
Answer: B,C
Explanation:
Comprehensive and Detailed In-Depth Explanation:
High Availability (HA) in Appian Cloud is designed to ensure that applications remain operational and data integrity is maintained even in the face of hardware failures, network issues, or other disruptions. Appian's Cloud Architecture and HA documentation outline the benefits, focusing on redundancy, minimal downtime, and data protection. The question asks for two advantages, and the options must align with these core principles.
Option B (Data and transactions are continuously replicated across the active nodes to achieve redundancy and avoid single points of failure):
This is a key advantage of HA. Appian Cloud HA instances use multiple active nodes to replicate data and transactions in real-time across the cluster. This redundancy ensures that if one node fails, others can take over without data loss, eliminating single points of failure. This is a fundamental feature of Appian's HA setup, leveraging distributed architecture to enhance reliability, as detailed in the Appian Cloud High Availability Guide.
Option D (In the event of a system failure, your Appian instance will be restored and available to your users in less than 15 minutes, having lost no more than the last 1 minute worth of data):
This is another significant advantage. Appian Cloud HA is engineered to provide rapid recovery and minimal data loss. The Service Level Agreement (SLA) and HA documentation specify that in the case of a failure, the system failover is designed to complete within a short timeframe (typically under 15 minutes), with data loss limited to the last minute due to synchronous replication. This ensures business continuity and meets stringent uptime and data integrity requirements.
Option A (An Appian Cloud HA instance is composed of multiple active nodes running in different availability zones in different regions):
This is a description of the HA architecture rather than an advantage. While running nodes across different availability zones and regions enhances fault tolerance, the benefit is the resulting redundancy and availability, which are captured in Options B and D. This option is more about implementation than a direct user or operational advantage.
Option C (A typical Appian Cloud HA instance is composed of two active nodes):
This is a factual statement about the architecture but not an advantage. The number of nodes (typically two or more, depending on configuration) is a design detail, not a benefit. The advantage lies in what this setup enables (e.g., redundancy and quick recovery), as covered by B and D.
The two advantages-continuous replication for redundancy (B) and fast recovery with minimal data loss (D)-reflect the primary value propositions of Appian Cloud HA, ensuring both operational resilience and data integrity for users.
The two advantages of having High Availability (HA) for Appian Cloud applications are:
B . Data and transactions are continuously replicated across the active nodes to achieve redundancy and avoid single points of failure. This is an advantage of having HA, as it ensures that there is always a backup copy of data and transactions in case one of the nodes fails or becomes unavailable. This also improves data integrity and consistency across the nodes, as any changes made to one node are automatically propagated to the other node.
D). In the event of a system failure, your Appian instance will be restored and available to your users in less than 15 minutes, having lost no more than the last 1 minute worth of data. This is an advantage of having HA, as it guarantees a high level of service availability and reliability for your Appian instance. If one of the nodes fails or becomes unavailable, the other node will take over and continue to serve requests without any noticeable downtime or data loss for your users.
NEW QUESTION # 49
Your client's customer management application is finally released to Production. After a few weeks of small enhancements and patches, the client is ready to build their next application. The new application will leverage customer information from the first application to allow the client to launch targeted campaigns for select customers in order to increase sales. As part of the first application, your team had built a section to display key customer information such as their name, address, phone number, how long they have been a customer, etc. A similar section will be needed on the campaign record you are building. One of your developers shows you the new object they are working on for the new application and asks you to review it as they are running into a few issues. What feedback should you give?
Answer: B
Explanation:
Comprehensive and Detailed In-Depth Explanation:
The scenario involves reusing a customer information section from an existing application in a new application for campaign management, with the developer encountering issues. Appian's best practices emphasize reusability, efficiency, and maintainability, especially when leveraging existing components across applications.
Option B (Ask the developer to convert the original customer section into a shared object so it can be used by the new application):
This is the recommended approach. Converting the original section into a shared object (e.g., a reusable interface component) allows it to be accessed across applications without duplication. Appian's Design Guide highlights the use of shared components to promote consistency, reduce redundancy, and simplify maintenance. Since the new application requires similar customer data (name, address, etc.), reusing the existing section-after ensuring it is modular and adaptable-addresses the developer's issues while aligning with the client's goal of leveraging prior work. The developer can then adjust the shared object (e.g., via parameters) to fit the campaign context, resolving their issues collaboratively.
Option A (Provide guidance to the developer on how to address the issues so that they can proceed with their work):
While providing guidance is valuable, it doesn't address the root opportunity to reuse existing code. This option focuses on fixing the new object in isolation, potentially leading to duplicated effort if the original section could be reused instead.
Option C (Point the developer to the relevant areas in the documentation or Appian Community where they can find more information on the issues they are running into):
This is a passive approach and delays resolution. As a Lead Developer, offering direct support or a strategic solution (like reusing components) is more effective than redirecting the developer to external resources without context.
Option D (Create a duplicate version of that section designed for the campaign record):
Duplication violates Appian's principle of DRY (Don't Repeat Yourself) and increases maintenance overhead. Any future updates to customer data display logic would need to be applied to multiple objects, risking inconsistencies.
Given the need to leverage existing customer information and the developer's issues, converting the section to a shared object is the most efficient and scalable solution.
NEW QUESTION # 50
You are reviewing log files that can be accessed in Appian to monitor and troubleshoot platform-based issues.
For each type of log file, match the corresponding Information that it provides. Each description will either be used once, or not at all.
Note: To change your responses, you may deselect your response by clicking the blank space at the top of the selection list.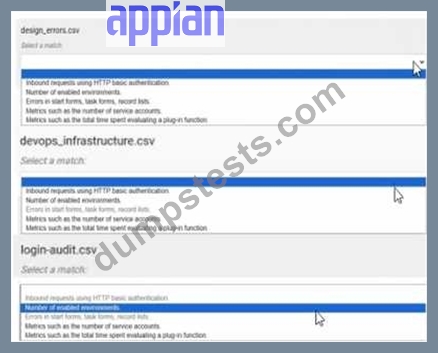
Answer:
Explanation: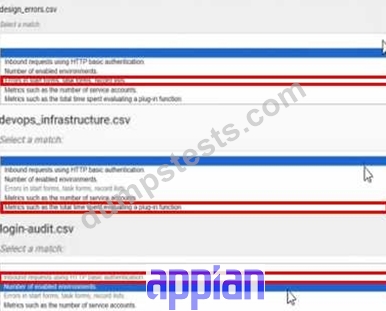
NEW QUESTION # 51
......
Based on high-quality products, our ACD-301 guide torrent has high quality to guarantee your test pass rate, which can achieve 98% to 100%. ACD-301 study tool is updated online by our experienced experts, and then sent to the user. And we provide free updates of ACD-301 training material for one year after your payment. The data of our ACD-301 Exam Torrent is forward-looking and can grasp hot topics to help users master the latest knowledge. And you can also free download the demo of ACD-301 exam questions to have a check.
ACD-301 Book Pdf: https://www.dumpstests.com/ACD-301-latest-test-dumps.html
P.S. Free & New ACD-301 dumps are available on Google Drive shared by DumpsTests: https://drive.google.com/open?id=1_Yr1dIg5_tvOJ6AIGyBa-fC6pMaJ8PdH