Certified-Data-Engineer-Professional Vce Free, Certified-Data-Engineer-Professional Braindumps

After years of hard work, our Certified-Data-Engineer-Professional guide training can take the leading position in the market. Our highly efficient operating system for learning materials has won the praise of many customers. If you are determined to purchase our Certified-Data-Engineer-Professional study tool, we can assure you that you can receive an email from our efficient system within 5 to 10 minutes after your payment, which means that you do not need to wait a long time to experience our learning materials. Then you can start learning our Certified-Data-Engineer-Professional Exam Questions in preparation for the exam.
| Section | Objectives |
|---|
| Topic 1: Cost & Performance Optimisation | - Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Apply data skipping and file pruning techniques
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Topic 2: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure Databricks-to-Databricks Sharing
- 3. Configure sharing with external platforms using the open sharing protocol
|
| Topic 3: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 4: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Design and implement scalable data models using Delta Lake
- 3. Optimize data layout using Liquid Clustering
|
| Topic 5: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Topic 6: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Topic 7: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- Building and Testing ETL Pipelines
- 1. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 2. Compare streaming tables and materialized views
- 3. Configure environments, dependencies, memory, and retry behavior
- 4. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 5. Use APPLY CHANGES APIs for change data capture
- 6. Develop unit and integration tests for data processing code
- 7. Use control flow operators in pipeline components
- 8. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
|
| Topic 8: Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
- Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
|
| Topic 9: Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use row filters and column masks for sensitive data
- 3. Use ACLs to secure workspace objects and enforce least privilege
|
| Topic 10: Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Query Profiler and Spark UI to monitor workloads
|
>> Certified-Data-Engineer-Professional Vce Free <<
100% Pass Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Fantastic Vce Free
All people dream to become social elite. However, less people can take the initiative. If you spend less time on playing computer games and spend more time on improving yourself, you are bound to escape from poverty. Maybe our Certified-Data-Engineer-Professional real dump could give your some help. Our company concentrates on relieving your pressure of preparing the Certified-Data-Engineer-Professional Exam. Getting the certificate equals to embrace a promising future and good career development. Perhaps you have heard about our Certified-Data-Engineer-Professional exam question from your friends or news. Why not has a brave attempt? You will certainly benefit from your wise choice.
Databricks Certified Data Engineer Professional Sample Questions (Q121-Q126):
NEW QUESTION # 121
A data architect is implementing Delta Sharing as part of their data governance strategy to enable secure data collaboration with external partners and internal business units. The architect must establish a permission framework that allows designated data stewards to create shares for their respective domains while maintaining security boundaries and audit compliance. Which specific permissions and roles must be assigned to enable users to create, configure, and manage Delta Shares while maintaining proper security governance and access controls?
- A. Only workspace admins can create and manage shares
- B. Users need the MANAGE SHARES permission on the workspace
- C. Any user with USE_CATALOG privilege can create shares
- D. Users need to be metastore admins or have CREATE SHARE privilege for the metastore
Answer: D
Explanation:
Creating and managing Delta Shares requires elevated governance privileges at the metastore level. Assigning users as metastore admins or granting them the CREATE SHARE privilege allows designated data stewards to create and configure shares within defined security boundaries, while preserving centralized auditability and access control.
NEW QUESTION # 122
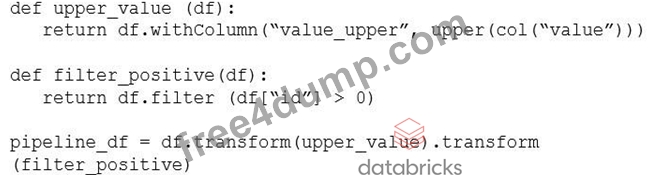
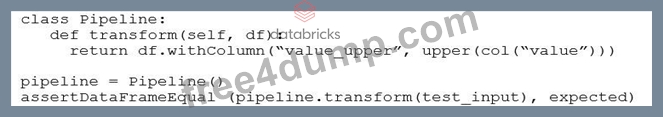
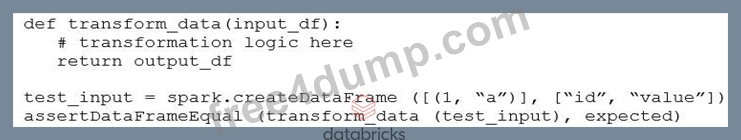
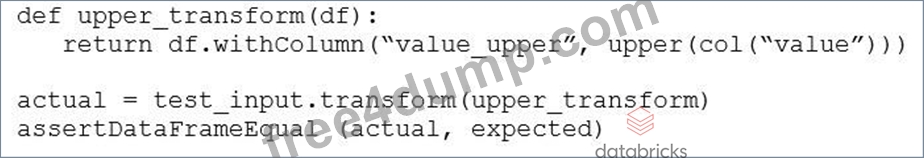
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
Answer: D
Explanation:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
NEW QUESTION # 123
A view is registered with the following code:
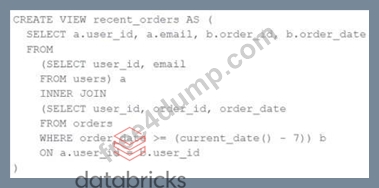
Both users and orders are Delta Lake tables.
Which statement describes the results of querying recent_orders?
- A. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- B. All logic will execute when the view is defined and store the result of joining tables to the DBFS; this stored data will be returned when the view is queried.
- C. Results will be computed and cached when the view is defined; these cached results will incrementally update as new records are inserted into source tables.
- D. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
Answer: A
NEW QUESTION # 124
Which statement describes a key benefit of an end-to-end test?
- A. It makes it easier to automate your test suite
- B. It closely simulates real world usage of your application.
- C. It pinpoint errors in the building blocks of your application.
- D. It provides testing coverage for all code paths and branches.
Answer: B
Explanation:
End-to-end testing is a methodology used to test whether the flow of an application, from start to finish, behaves as expected. The key benefit of an end-to-end test is that it closely simulates real- world, user behavior, ensuring that the system as a whole operates correctly.
NEW QUESTION # 125
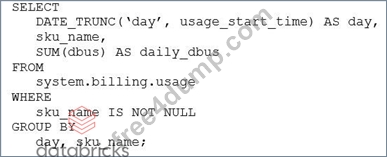
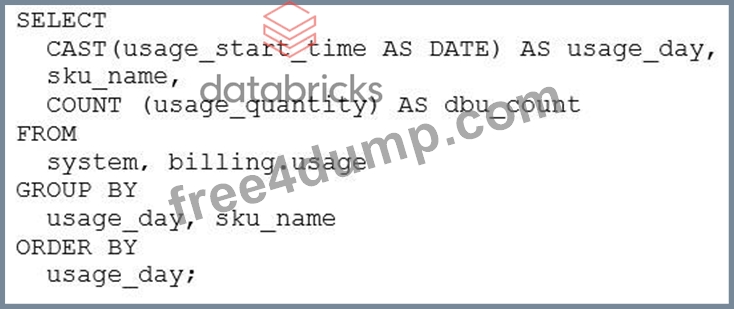
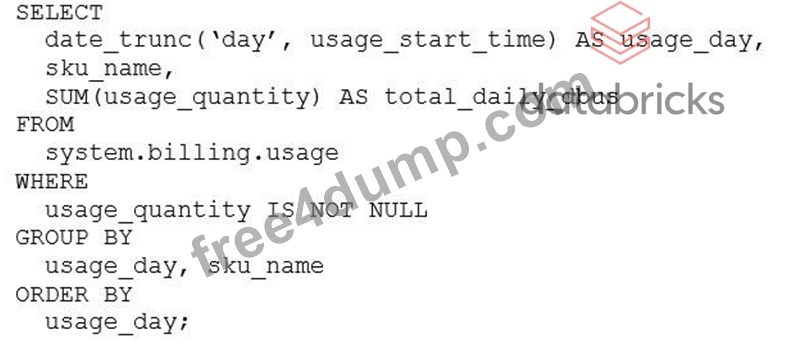
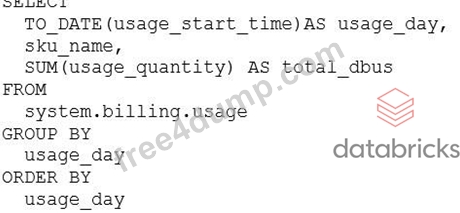
A platform engineer needs to report the resource consumption, categorized by SKU tier, across all workspaces. The engineer decides to use the system.billing.usage system table to create a query. Which SQL query will accurately return the daily usage by product?
Answer: C
Explanation:
This query correctly aggregates usage at a daily granularity by truncating the usage start timestamp to the day and summing the usage quantity, which represents DBUs. Grouping by both the derived daily value and the SKU name ensures usage is accurately categorized by product tier across all workspaces.
NEW QUESTION # 126
......
We will not only ensure you to pass the exam, but also provide for you a year free update service. If you are not careful to fail to pass the Certified-Data-Engineer-Professional examination, we will full refund to you. However, this possibility is almost not going to happen. We can 100% help you pass the Certified-Data-Engineer-Professional Exam, you can download part of practice questions from Free4Dump as a free try.
Certified-Data-Engineer-Professional Braindumps: https://www.free4dump.com/Certified-Data-Engineer-Professional-braindumps-torrent.html
- Latest Certified-Data-Engineer-Professional Vce Free - Easy and Guaranteed Certified-Data-Engineer-Professional Exam Success 🔥 Search for 【 Certified-Data-Engineer-Professional 】 and download exam materials for free through ▶ www.vce4dumps.com ◀ ❎Certified-Data-Engineer-Professional Latest Exam Dumps
- Free PDF Quiz Databricks - Certified-Data-Engineer-Professional - Perfect Databricks Certified Data Engineer Professional Vce Free 💡 Go to website ( www.pdfvce.com ) open and search for ➥ Certified-Data-Engineer-Professional 🡄 to download for free 🧡Valid Certified-Data-Engineer-Professional Exam Sims
- Pass Guaranteed 2026 Databricks - Certified-Data-Engineer-Professional Vce Free 🚡 Simply search for ➽ Certified-Data-Engineer-Professional 🢪 for free download on ➽ www.validtorrent.com 🢪 😱Study Certified-Data-Engineer-Professional Material
- Study Certified-Data-Engineer-Professional Material ☁ Valid Dumps Certified-Data-Engineer-Professional Free 🐴 Download Certified-Data-Engineer-Professional Free Dumps ↔ Easily obtain free download of 《 Certified-Data-Engineer-Professional 》 by searching on ➠ www.pdfvce.com 🠰 😝Reliable Certified-Data-Engineer-Professional Exam Bootcamp
- Certified-Data-Engineer-Professional Certification Sample Questions 🍫 Valid Certified-Data-Engineer-Professional Exam Sims ▶ Latest Certified-Data-Engineer-Professional Exam Papers 🤿 Easily obtain ⏩ Certified-Data-Engineer-Professional ⏪ for free download through ✔ www.pdfdumps.com ️✔️ 💿Study Certified-Data-Engineer-Professional Material
- Download Certified-Data-Engineer-Professional Free Dumps 🤗 Exam Dumps Certified-Data-Engineer-Professional Zip 📇 Dumps Certified-Data-Engineer-Professional Torrent 🥰 Easily obtain { Certified-Data-Engineer-Professional } for free download through ⮆ www.pdfvce.com ⮄ 🦅Study Certified-Data-Engineer-Professional Material
- Original Certified-Data-Engineer-Professional Questions 😫 Original Certified-Data-Engineer-Professional Questions 🕡 Valid Certified-Data-Engineer-Professional Exam Sims 👣 Search on ☀ www.pdfdumps.com ️☀️ for ( Certified-Data-Engineer-Professional ) to obtain exam materials for free download ⏲Test Certified-Data-Engineer-Professional Topics Pdf
- Certified-Data-Engineer-Professional Vce Free - Free PDF Quiz 2026 Databricks First-grade Certified-Data-Engineer-Professional Braindumps 🌿 Go to website 【 www.pdfvce.com 】 open and search for ( Certified-Data-Engineer-Professional ) to download for free 💠Certified-Data-Engineer-Professional Certification Exam Infor
- Quiz 2026 Latest Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Vce Free 🔗 Easily obtain [ Certified-Data-Engineer-Professional ] for free download through ⇛ www.prepawaypdf.com ⇚ 🥞Dumps Certified-Data-Engineer-Professional Torrent
- Dumps Certified-Data-Engineer-Professional Torrent 🧨 Certified-Data-Engineer-Professional Certification Exam Infor ☔ Certified-Data-Engineer-Professional Real Exam Questions 🥓 Copy URL ➡ www.pdfvce.com ️⬅️ open and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download for free 🥵Test Certified-Data-Engineer-Professional Result
- Certified-Data-Engineer-Professional Practice Exam Pdf 🙂 Book Certified-Data-Engineer-Professional Free 🧣 New Certified-Data-Engineer-Professional Test Blueprint 🦊 Download ⮆ Certified-Data-Engineer-Professional ⮄ for free by simply searching on “ www.testkingpass.com ” 🧢Exam Dumps Certified-Data-Engineer-Professional Zip
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, writeablog.net, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, learn.csisafety.com.au, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes